

2026 Best GPU Cloud tools
GPU Cloud services for AI training, inference, rendering, and high-performance computing. Compare flexible access to on-demand GPU resources.
AI Infrastructure
Explore this collectionTools

CoreWeave
AI Inference Platform
CoreWeave is an AI-focused cloud platform that combines GPU infrastructure, storage, networking, orchestration, and operational tooling for training and serving AI workloads. It supports teams moving from model experiments to production systems, including reinforcement-learning and agent-development workflows.
Freemium









Paperspace
AI Model Deployment
Paperspace is a cloud platform for developing, training, and deploying machine learning applications with managed notebooks, GPU machines, and deployment workflows. It serves ML developers, data scientists, researchers, and teams that need on-demand accelerated computing.
Freemium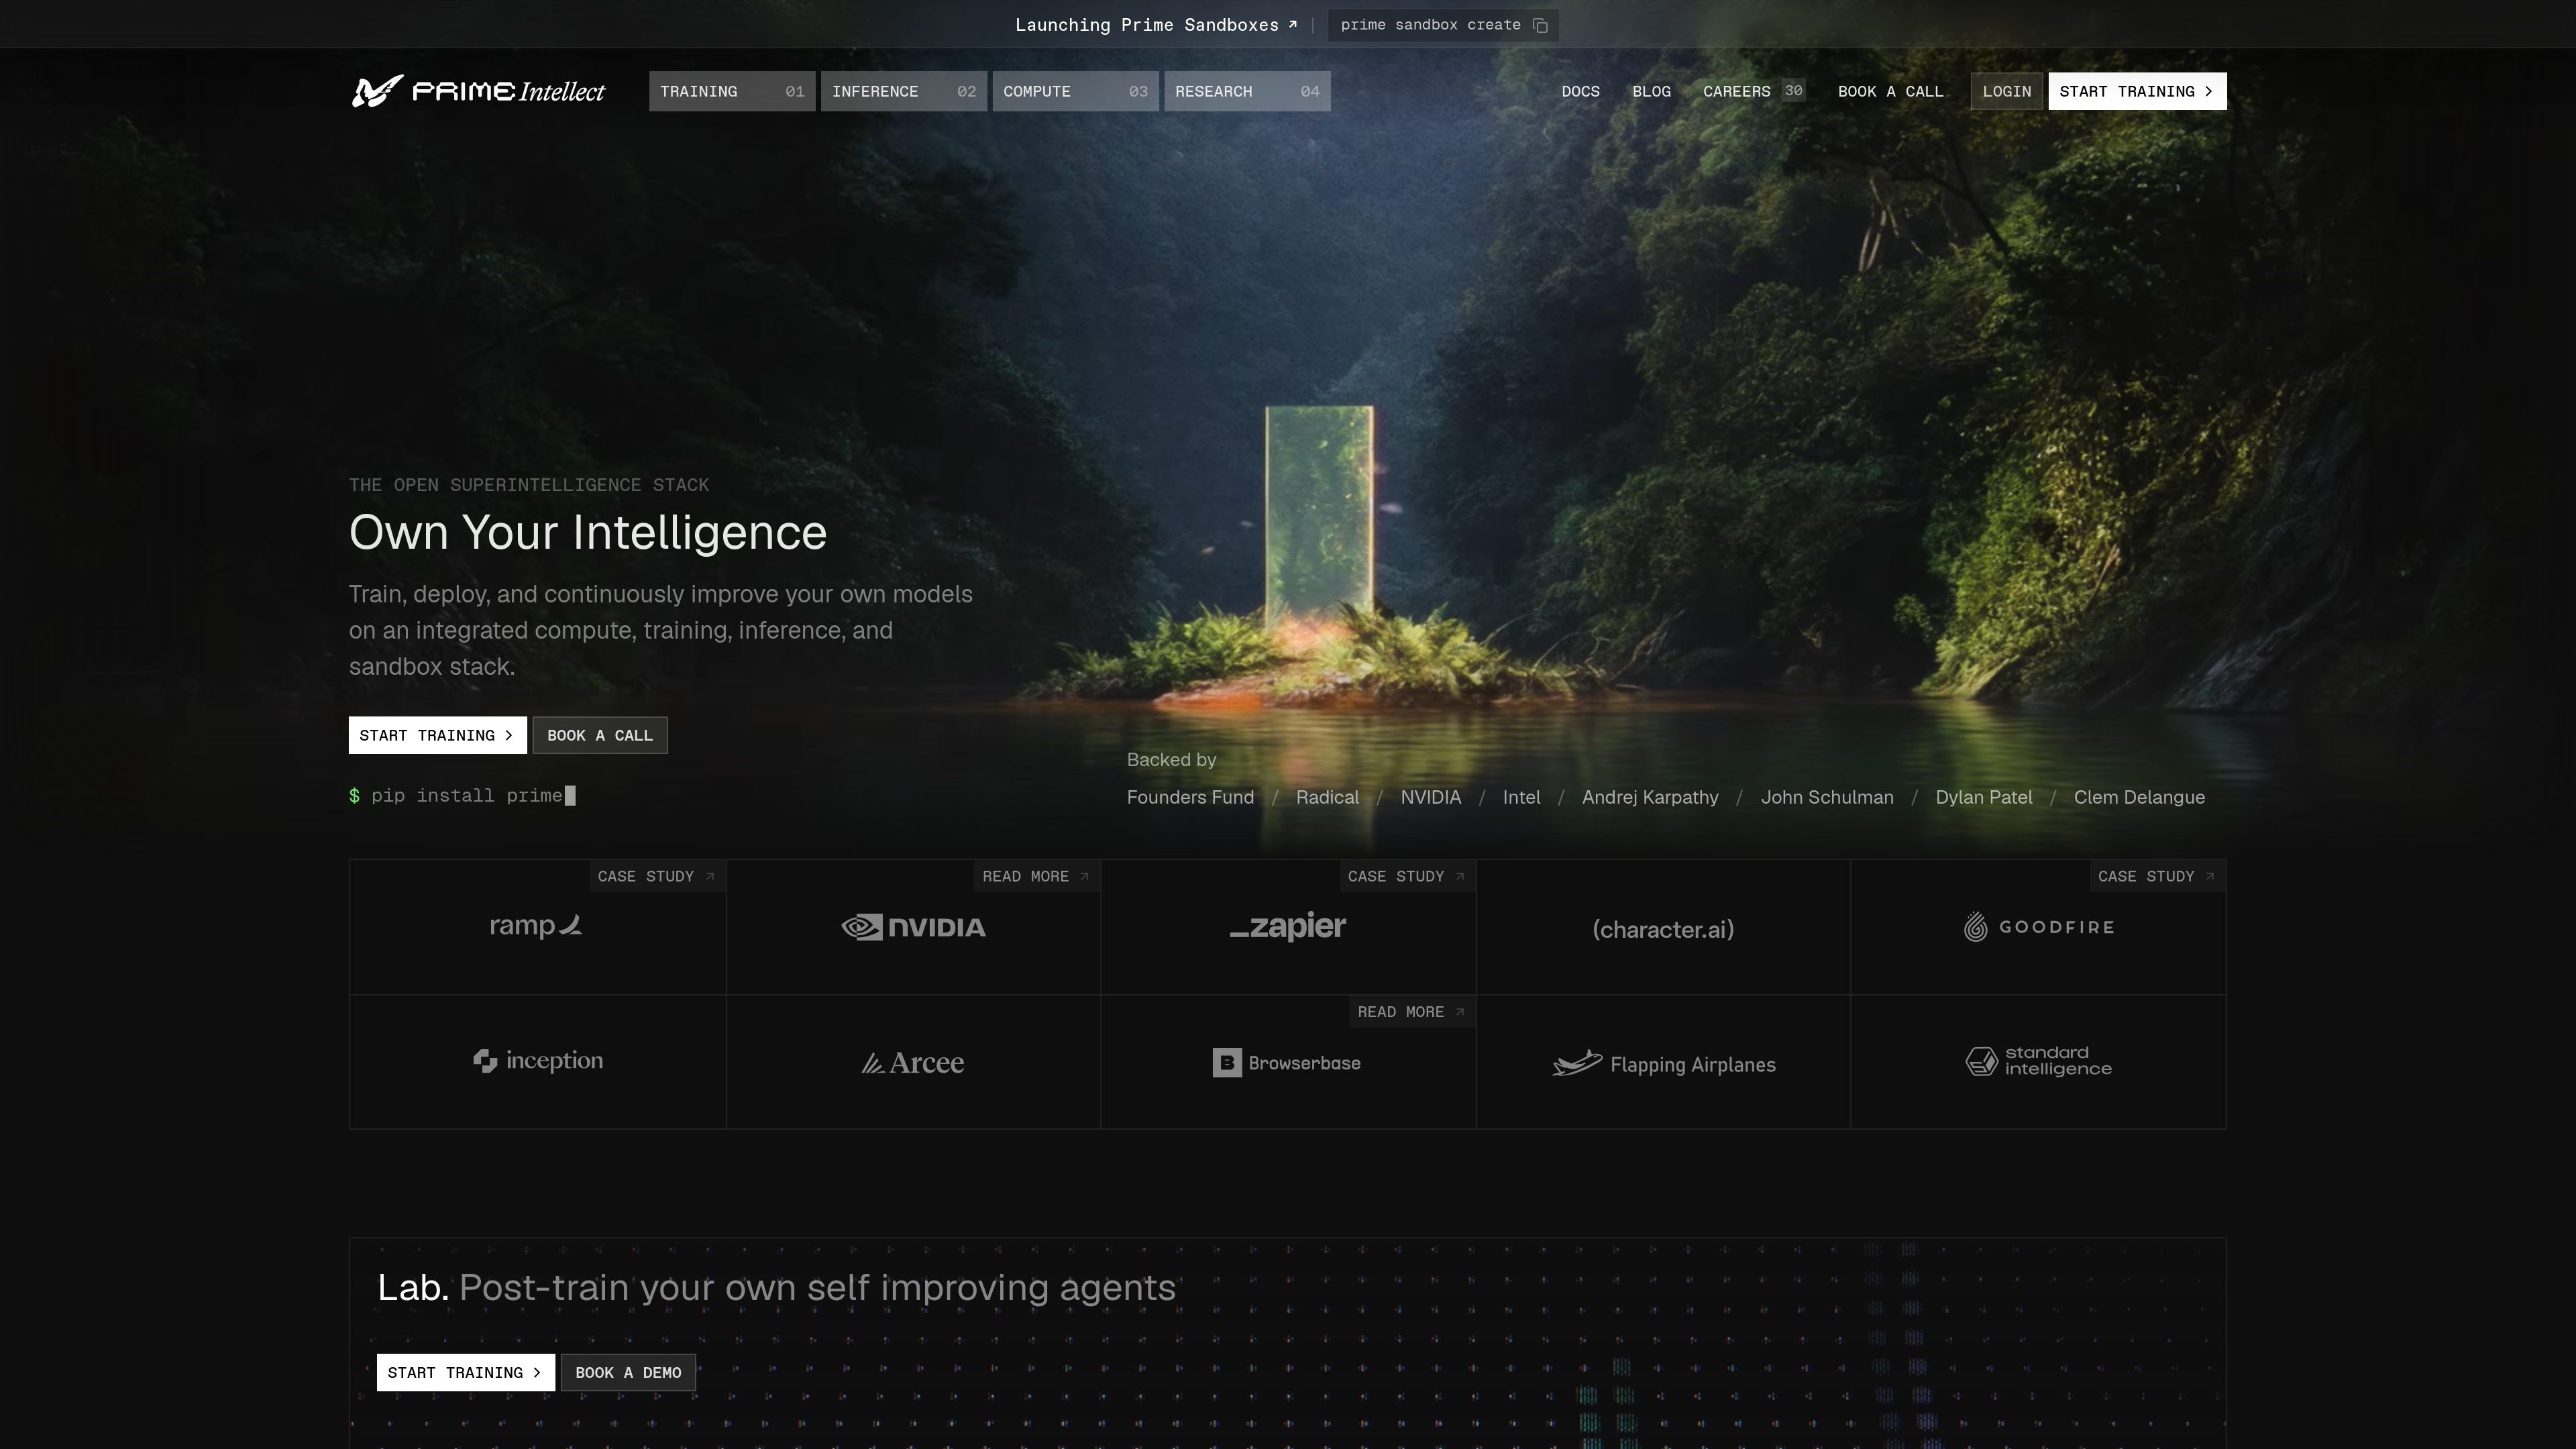

Prime Intellect
AI Agent Infrastructure
Prime Intellect is an open stack for training, evaluating, deploying, and improving AI models and agents. It combines RL environments, hosted evaluations and training, model inference, GPU compute, and isolated sandboxes for research and production workflows.
Freemium

Hyperstack
AI Inference Platform
Hyperstack is a cloud GPU platform for running AI and machine learning workloads, including training, inference, data analytics, and model development. It also provides AI Studio, virtual machines, and managed Kubernetes for deploying and operating GPU-backed workloads.
Freemium



Radiant
AI Model Deployment
Radiant is an integrated AI infrastructure platform that finances, builds, and operates data centers, GPU systems, networking, storage, and managed services. It helps AI teams and infrastructure operators provision and run compute through a unified platform and FlightDeck control plane.
Freemium


Frequently asked questions
What problems do GPU Cloud tools address?
GPU Cloud services for AI training, inference, rendering, and high-performance computing. Compare flexible access to on-demand GPU resources.
Does protocol compatibility make an API a drop-in replacement?
Test tool calls, streaming, errors, context limits and multimodal inputs. Matching model names do not establish identical routing or billing. Replay representative requests and examine differences before moving traffic gradually.
Why can a lower model price still mean a higher total cost?
Caching, response length, retries, concurrency limits and latency affect cost per successful task. Self-hosting adds memory, idle capacity and operations. Estimate costs using your workload rather than list prices alone.
What should I verify before putting AI infrastructure in production?
Test timeouts, throttling, upstream failures and key rotation. Ensure retries do not repeat side effects. Review data location, log redaction and retention, and establish fallback, budget alerts and access auditing.