LLM Evaluation

Explore LLM evaluation tools, benchmarks, and testing platforms to measure model quality, compare outputs, detect risks, and improve AI applications.

AI Infrastructure

Explore this collection

Products

Artificial Analysis preview
Artificial Analysis logo

Artificial Analysis

LLM Evaluation

Artificial Analysis is an AI benchmarking platform for comparing models, providers, and hardware, with Pro and Enterprise plans and a free API.

Weights & Biases preview
Weights & Biases logo

Weights & Biases

LLM Evaluation

Machine learning and AI platform for experiment tracking, artifacts, GenAI tracing, and evaluations.

Arena preview
Arena logo

Arena

AI Chatbot

Arena is a public AI model comparison and ranking platform for chatting with models, voting on outputs, and exploring task-specific leaderboards across text, vision, code, search, video, and agent tasks.

Pydantic preview
Pydantic logo

Pydantic

AI Observability

An AI engineering stack for type-safe apps, observability, evaluation, and model routing

Scale AI preview
Scale AI logo

Scale AI

LLM Evaluation

Data, evaluations, and enterprise AI tools for reliable production systems

Langfuse preview
Langfuse logo

Langfuse

AI Observability

Langfuse is an open-source AI platform for tracing, evaluating, and improving LLM applications and agents with observability, prompts, experiments, and human review.

SuperAnnotate preview
SuperAnnotate logo

SuperAnnotate

LLM Evaluation

AI data platform for annotation and evaluation pipelines across image, video, text, and audio workflows.

Horizon preview
Horizon logo

Horizon

LLM Evaluation

Labelbox’s RL environment product for post-training and evaluating long-horizon AI tasks.

Outlier AI preview
Outlier AI logo

Outlier AI

LLM Evaluation

Remote AI training platform connecting experts with flexible projects and weekly pay

Context logo
Context logo

Context

AI Agent Builder

Context is an enterprise AI agents platform for building, deploying, and improving agents on customer infrastructure, with workspace, runtime, context, evaluation, connectors, and IdP access controls.

Klavis AI logo
Klavis AI logo

Klavis AI

AI Agent Infrastructure

Klavis AI offers live environments to train and evaluate AI agents with coding and tool-use data.

Agnost AI preview
Agnost AI logo

Agnost AI

AI Observability

Agnost AI monitors AI agents in production by analyzing conversations, traces, user corrections, and frustration. It helps teams identify recurring failures, review suggested prompt fixes, and apply approved changes with replay-based regression coverage.

OpenTrain AI preview
OpenTrain AI logo

OpenTrain AI

LLM Evaluation

OpenTrain AI is a marketplace and managed service for hiring pre-vetted AI trainers, data labelers, and domain experts for RLHF, evaluation, red teaming, annotation, and agent workflows.

QAgent preview
QAgent logo

QAgent

AI Testing Assistant

QAgent is an AI agent testing and quality assurance platform for developers and agile teams. It connects to an agent through a webhook or endpoint, runs automated test cases, and evaluates responses for groundedness, policy adherence, prompt compliance, and related quality dimensions.
inferock-bench preview
inferock-bench logo

inferock-bench

AI Gateway And Routing

inferock-bench is a local diagnostic proxy for tracking LLM API usage, provider-reported costs, failures, and billing-integrity signals. It helps developers inspect calls to OpenAI, Anthropic, Gemini Developer API, and pinned OpenRouter endpoints using locally stored receipts.
NovaSynth preview
NovaSynth logo

NovaSynth

AI Testing Assistant

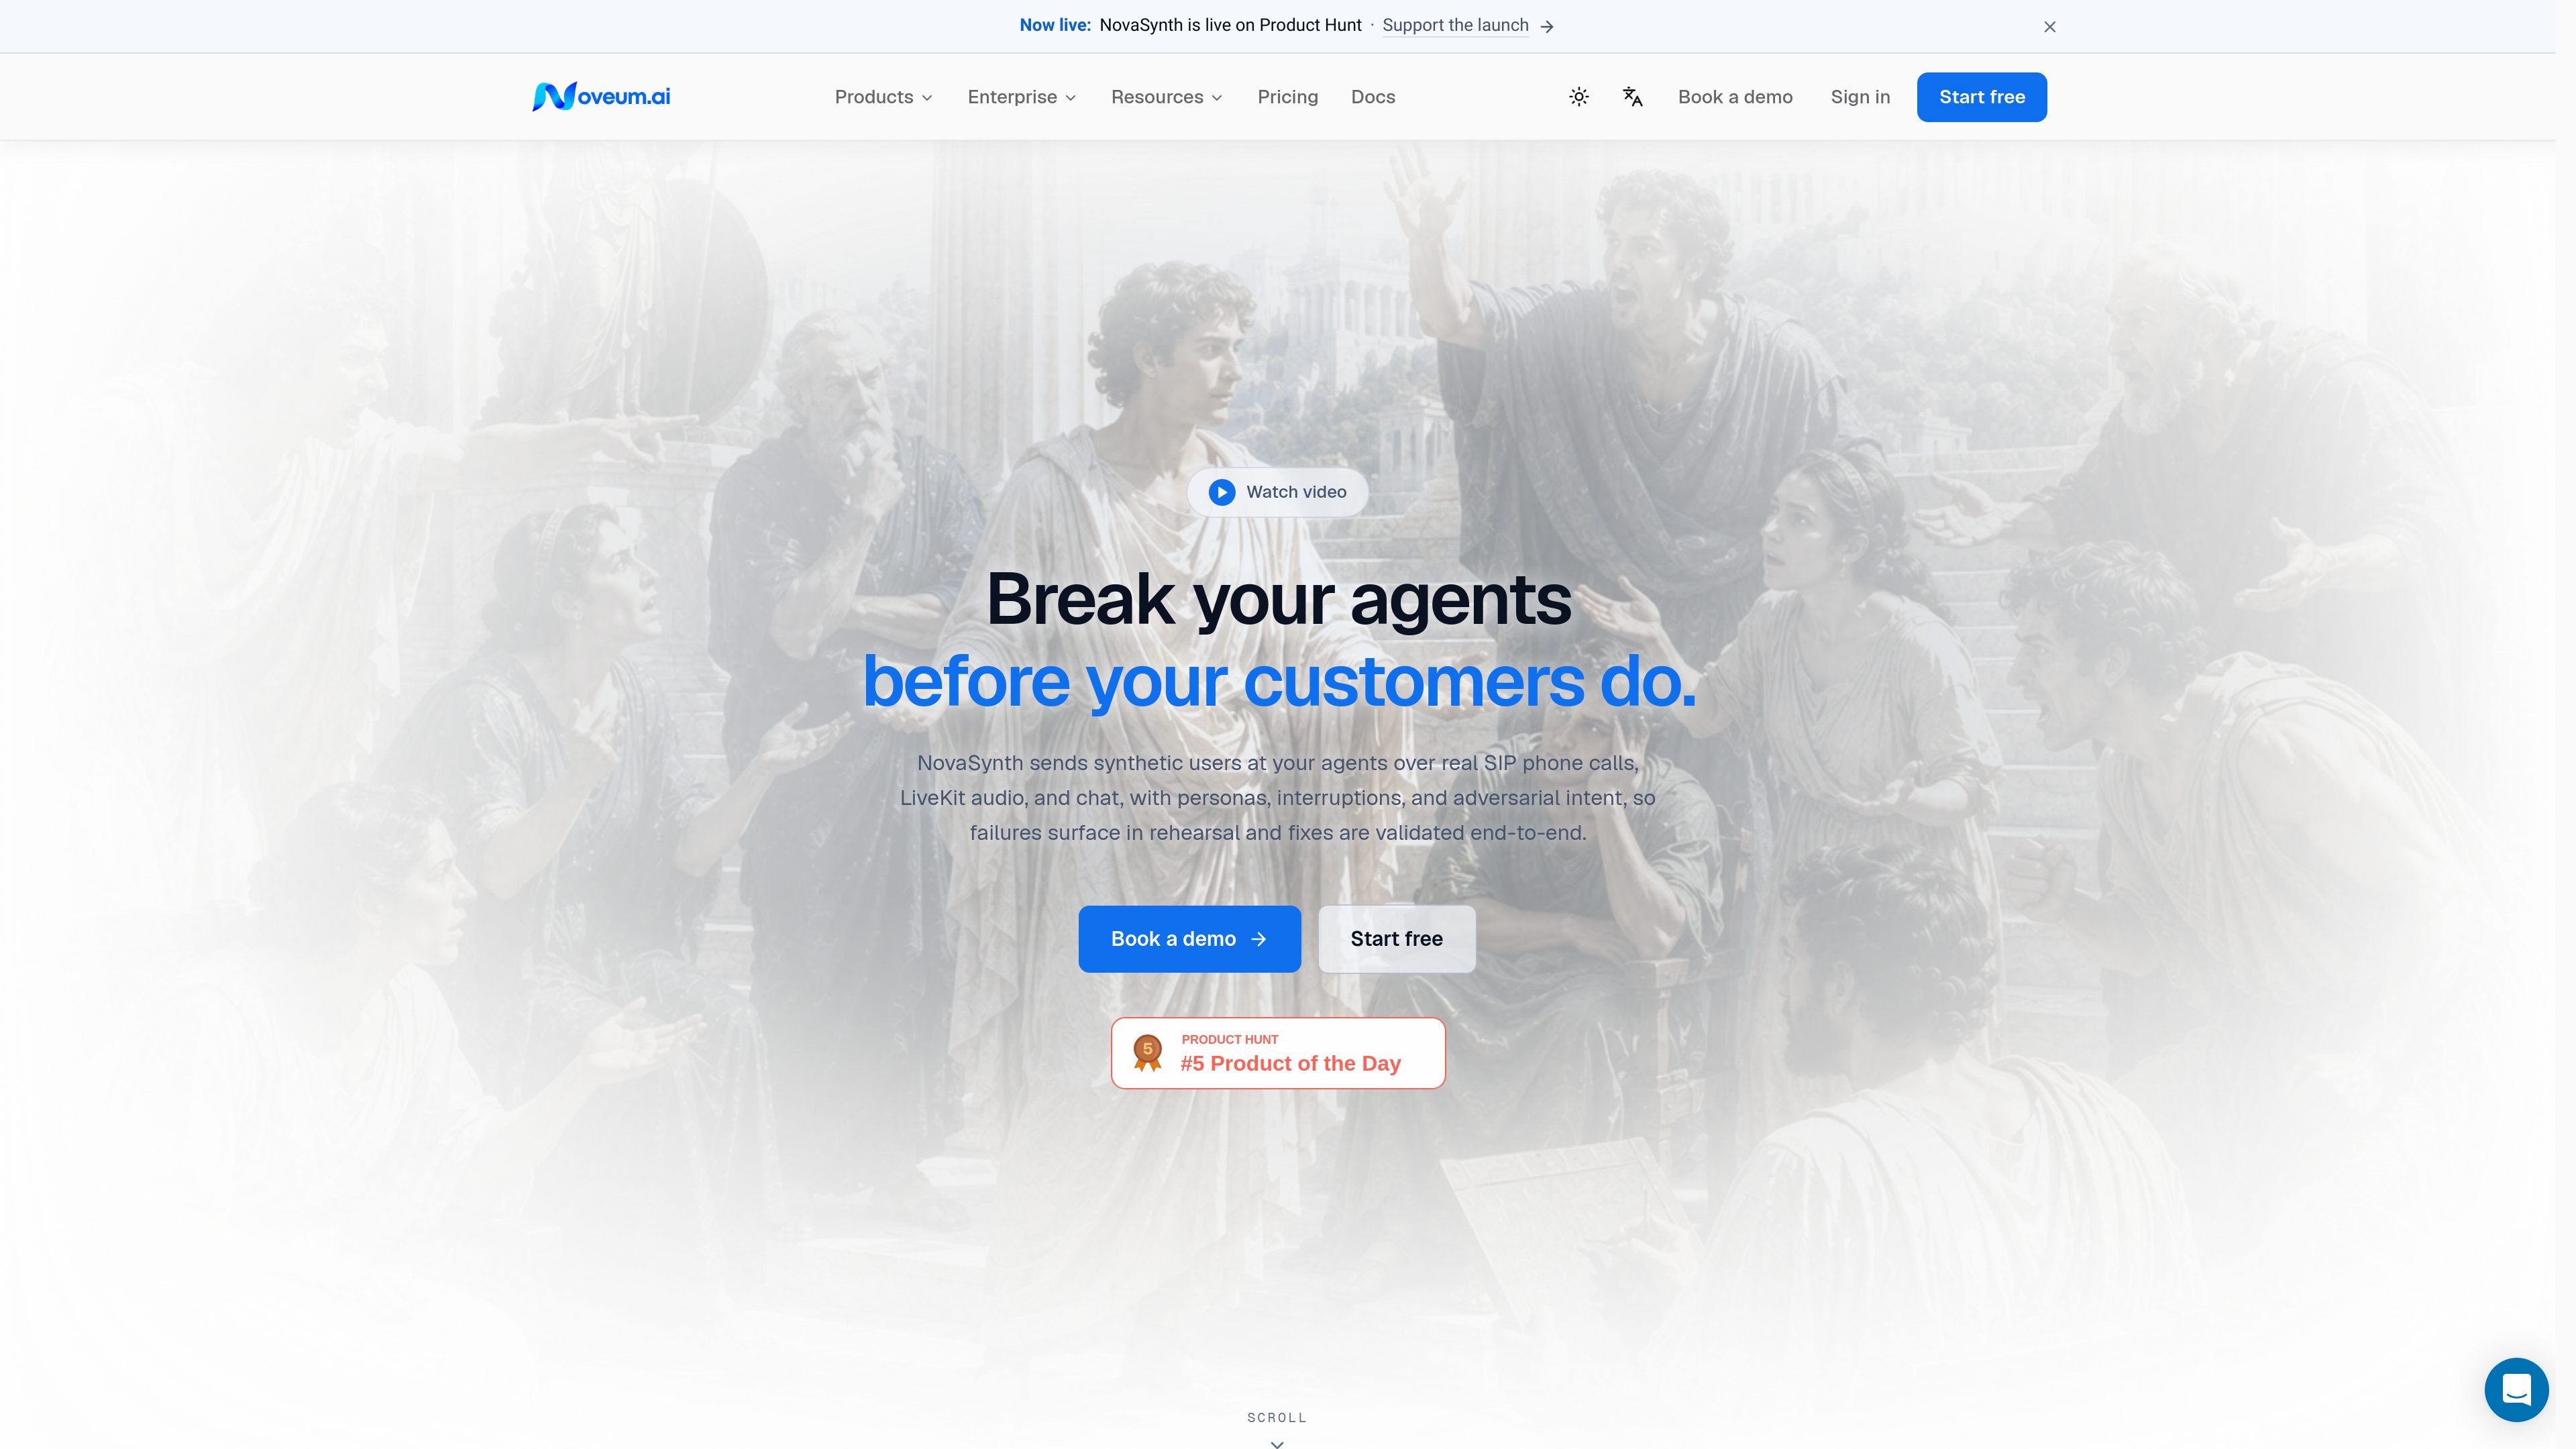
NovaSynth is a pre-production testing platform for AI agents that uses synthetic users across real SIP phone calls, LiveKit audio, and chat. It helps teams rehearse multi-turn interactions, surface failures, and validate fixes before releasing agents to customers.

MCPJam preview
MCPJam logo

MCPJam

AI Testing Assistant

MCPJam is a testing and evaluation platform for MCP servers. It helps developers inspect servers locally, run user and model-based tests, and add behavior checks to CI/CD workflows.

Oqoqo preview
Oqoqo logo

Oqoqo

LLM Evaluation

Oqoqo is an evaluation platform for running repeatable agent experiments in realistic, isolated environments. Teams use it to build private benchmarks, compare agents and models, and investigate why agent workflows succeed or fail.

ComputeArena preview
ComputeArena logo

ComputeArena

LLM Evaluation

ComputeArena is a community benchmark directory for measuring local AI model throughput across chips, quantisations, and runtimes. It helps developers run offline benchmarks, inspect signed reports, and compare decode and prefill performance on compatible workloads.

Jev State preview
Jev State logo

Jev State

AI Agent Builder

Jev State is a workspace for defining, testing, and regression-checking conversational decisions powered by Jev. It helps teams inspect why an agent takes a step and export runnable TypeScript and tests for an application.