
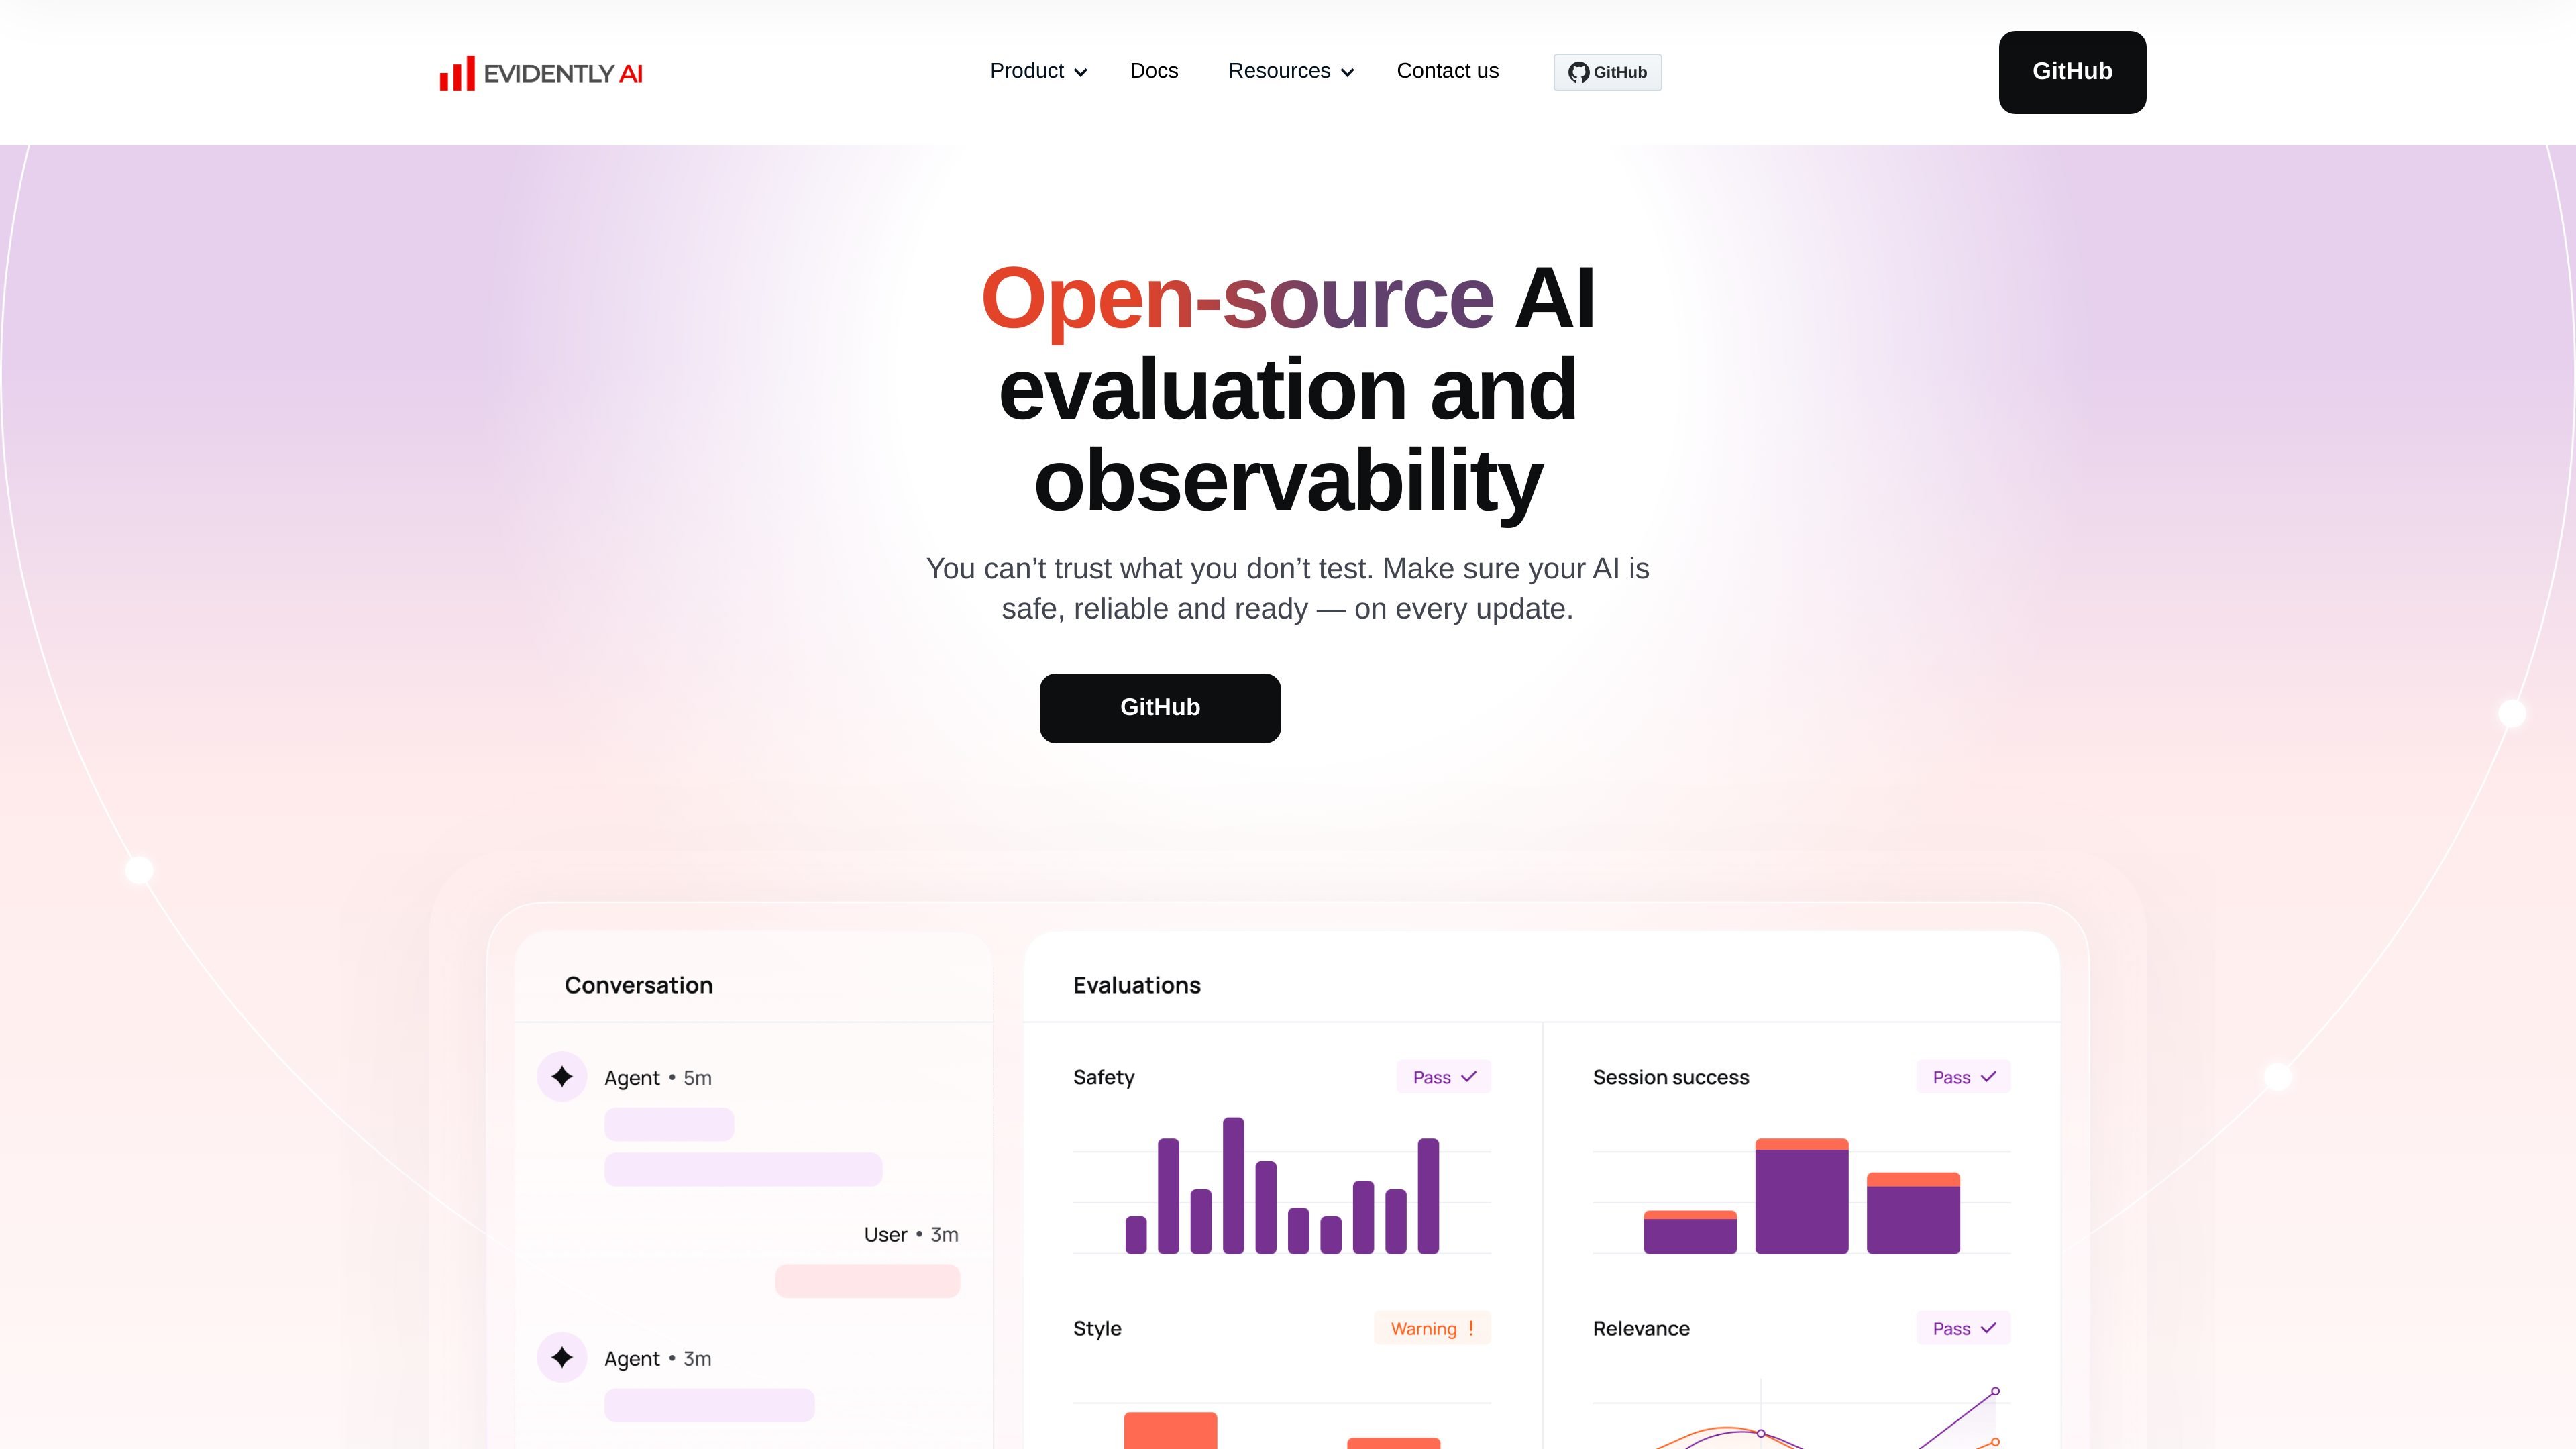
Automated evaluations
Measure AI output quality, safety, and reliability, and run evaluation workflows as part of a pipeline.

Open-source framework for evaluating and monitoring LLM applications, AI agents, and ML models.
Evidently AI is an open-source framework for evaluating, testing, and monitoring LLM applications, RAG systems, AI agents, and predictive machine-learning models. It helps teams assess output quality, safety, and reliability during development and track changes after deployment. Evaluations can combine built-in metrics with custom rules, classifiers, prompts, or models, while reports and monitoring views make results available for review.
Measure AI output quality, safety, and reliability, and run evaluation workflows as part of a pipeline.
Use a library of more than 100 built-in metrics or define evaluations with custom prompts, models, and rules.
Generate realistic, edge-case, or adversarial inputs tailored to an application, including benign and hostile prompts.
Explore evaluation results in visual reports that can be shared with others.
Track evaluation results and quality checks in a live dashboard to identify drift, regressions, and emerging risks.
Evaluate LLM behavior, retrieval quality, and safety alongside predictive performance, data drift, and data quality.
Assess retrieval quality and context relevance, and check generated answers for factuality or hallucinations before release.
Use edge-case and adversarial inputs to evaluate agent responses and expose risks such as unsafe output or prompt-based attacks.
Run quality and safety checks during application updates, then review results in visual reports.
Track model performance, data quality, and data drift as production data changes.
It supports LLM-powered products such as chatbots, RAG applications, AI agents, and copilots, as well as predictive machine-learning systems.
Yes. The framework offers more than 100 built-in metrics and supports custom evaluations using prompts, models, or rules, including combinations of rules, classifiers, and LLM-based evaluations.
Yes. Evidently describes running evaluations in a pipeline and reviewing the results through shareable visual reports.
Examples include guideline and format adherence, hallucinations and factuality, PII detection, retrieval quality and context relevance, sentiment, toxicity, tone, and trigger words.
流量数据仅供参考。

langfuse.com
开源 AI 工程平台,用于追踪、评估和改进 LLM 应用与智能体。
hamming.ai
Hamming AI 为开发语音与聊天智能体的团队提供自动化测试、红队测试和生产环境监控,帮助团队在上线前评估智能体行为,排查真实对话中的故障,并将其转化为后续版本的回归测试。
akto.io
AI security platform for discovering, testing, governing, and protecting LLMs, agents, MCPs, and GenAI applications.

futureagi.com
Future AGI 为开发和运营 AI 智能体的团队提供评测、模拟对话、运行时护栏和生产追踪工具,帮助定位故障并在发布前验证改动。

dynamo.ai
为生成式 AI 和智能体 AI 提供企业级评估、安全防护、监控与治理控制。

opensearch.org
OpenSearch is a community-driven, Apache 2.0-licensed open source search and analytics suite for ingesting, searching, visualizing, and analyzing data. It supports application search, observability, security analytics, and machine learning workflows.