2026 最佳大型語言模型評測工具

探索大型語言模型評測工具、基準測試與平台,衡量模型品質、比較輸出、辨識風險並改善 AI 應用。

維護者:

AI 基礎設施

探索此分類集合

產品

OpenTrain AI preview
OpenTrain AI logo

OpenTrain AI

大型語言模型評測

OpenTrain AI 是一個市場與託管服務平台,可聘用經預先審核的 AI 訓練師、資料標註員與領域專家,用於 RLHF、評估、紅隊測試、標註及代理工作流程。

免費及付費方案
Agnost AI preview
Agnost AI logo

Agnost AI

AI 可觀測性

Agnost AI monitors AI agents in production by analyzing conversations, traces, user corrections, and frustration. It helps teams identify recurring failures, review suggested prompt fixes, and apply approved changes with replay-based regression coverage.

免費及付費方案
FastRouter.ai preview
FastRouter.ai logo

FastRouter.ai

AI 閘道與路由

An OpenAI-compatible gateway for routing, evaluating, and governing access to 200+ AI models.

免費及付費方案
Sourcebae preview
Sourcebae logo

Sourcebae

AI招募助理

Expert matching, annotation workflows, and quality dashboards for AI training and evaluation.

付費
OverallGPT preview
OverallGPT logo

OverallGPT

大型語言模型評測

OverallGPT compares AI answers to one question side by side and combines the responses into an Overall Answer.

免費及付費方案
Oqoqo preview
Oqoqo logo

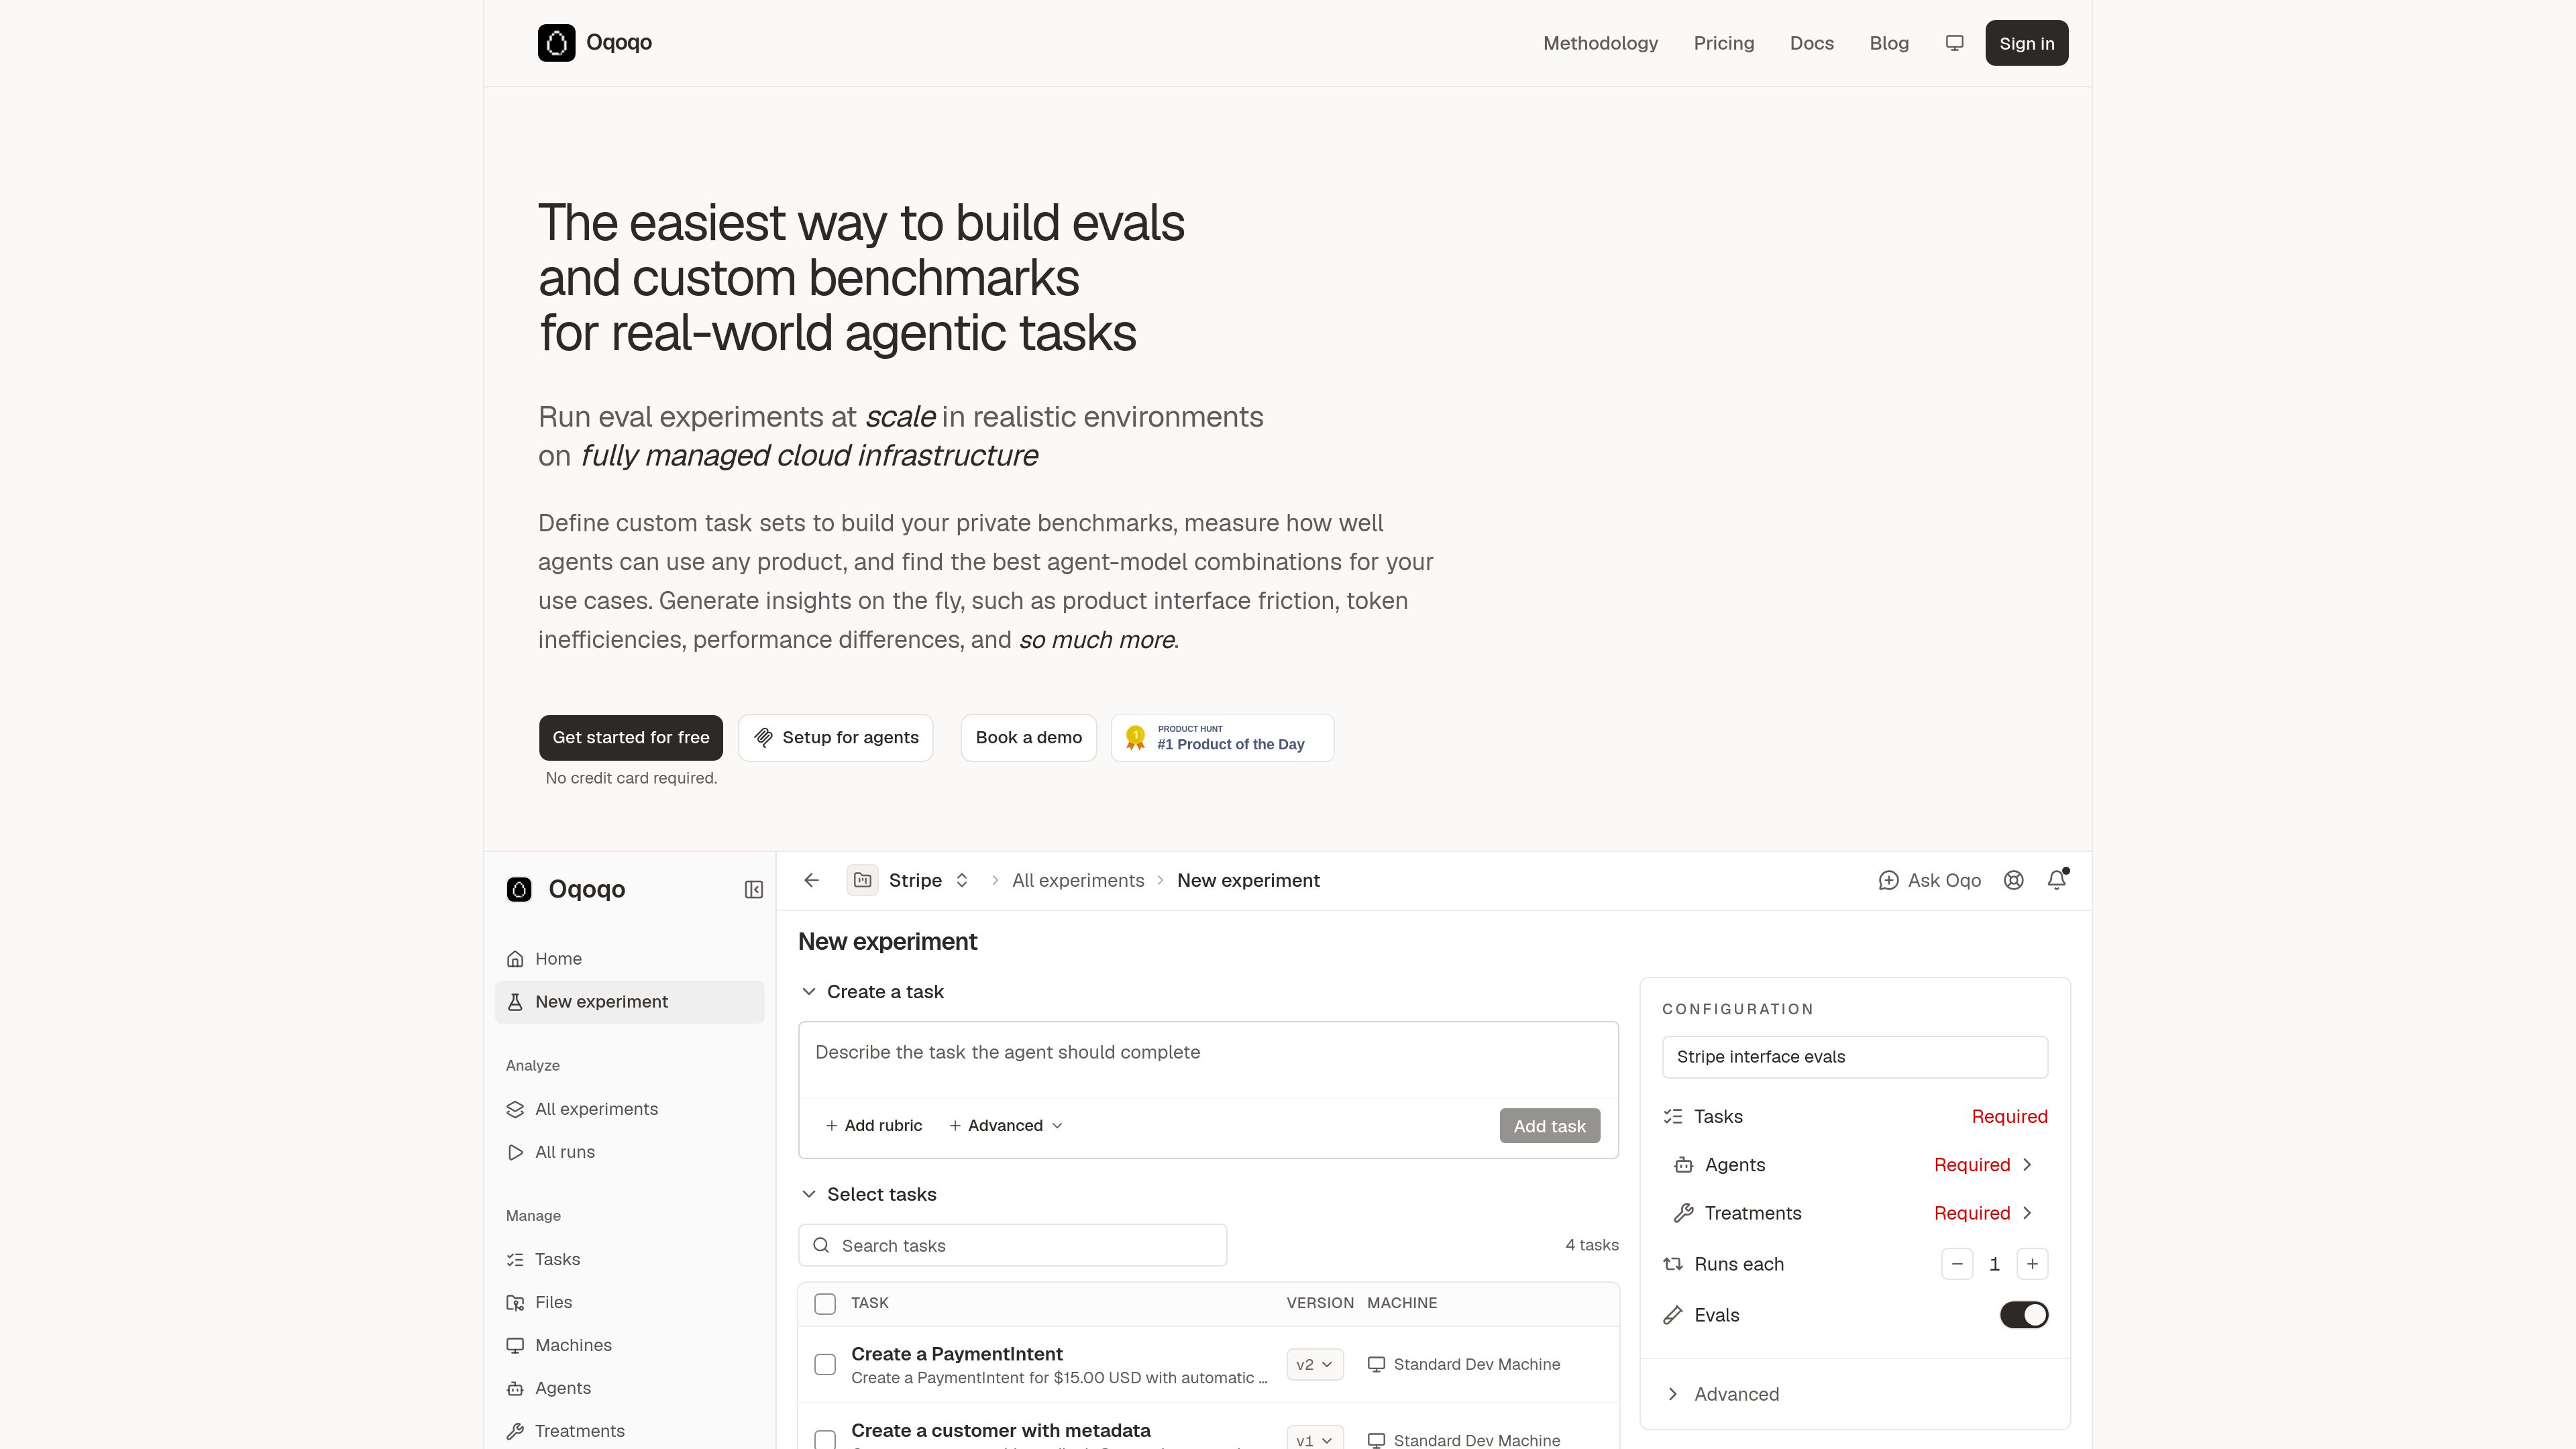
Oqoqo

大型語言模型評測

Oqoqo is an evaluation platform for running repeatable agent experiments in realistic, isolated environments. Teams use it to build private benchmarks, compare agents and models, and investigate why agent workflows succeed or fail.

免費及付費方案
inferock-bench preview
inferock-bench logo

inferock-bench

AI 閘道與路由

inferock-bench is a local diagnostic proxy for tracking LLM API usage, provider-reported costs, failures, and billing-integrity signals. It helps developers inspect calls to OpenAI, Anthropic, Gemini Developer API, and pinned OpenRouter endpoints using locally stored receipts.

免費及付費方案
ComputeArena preview
ComputeArena logo

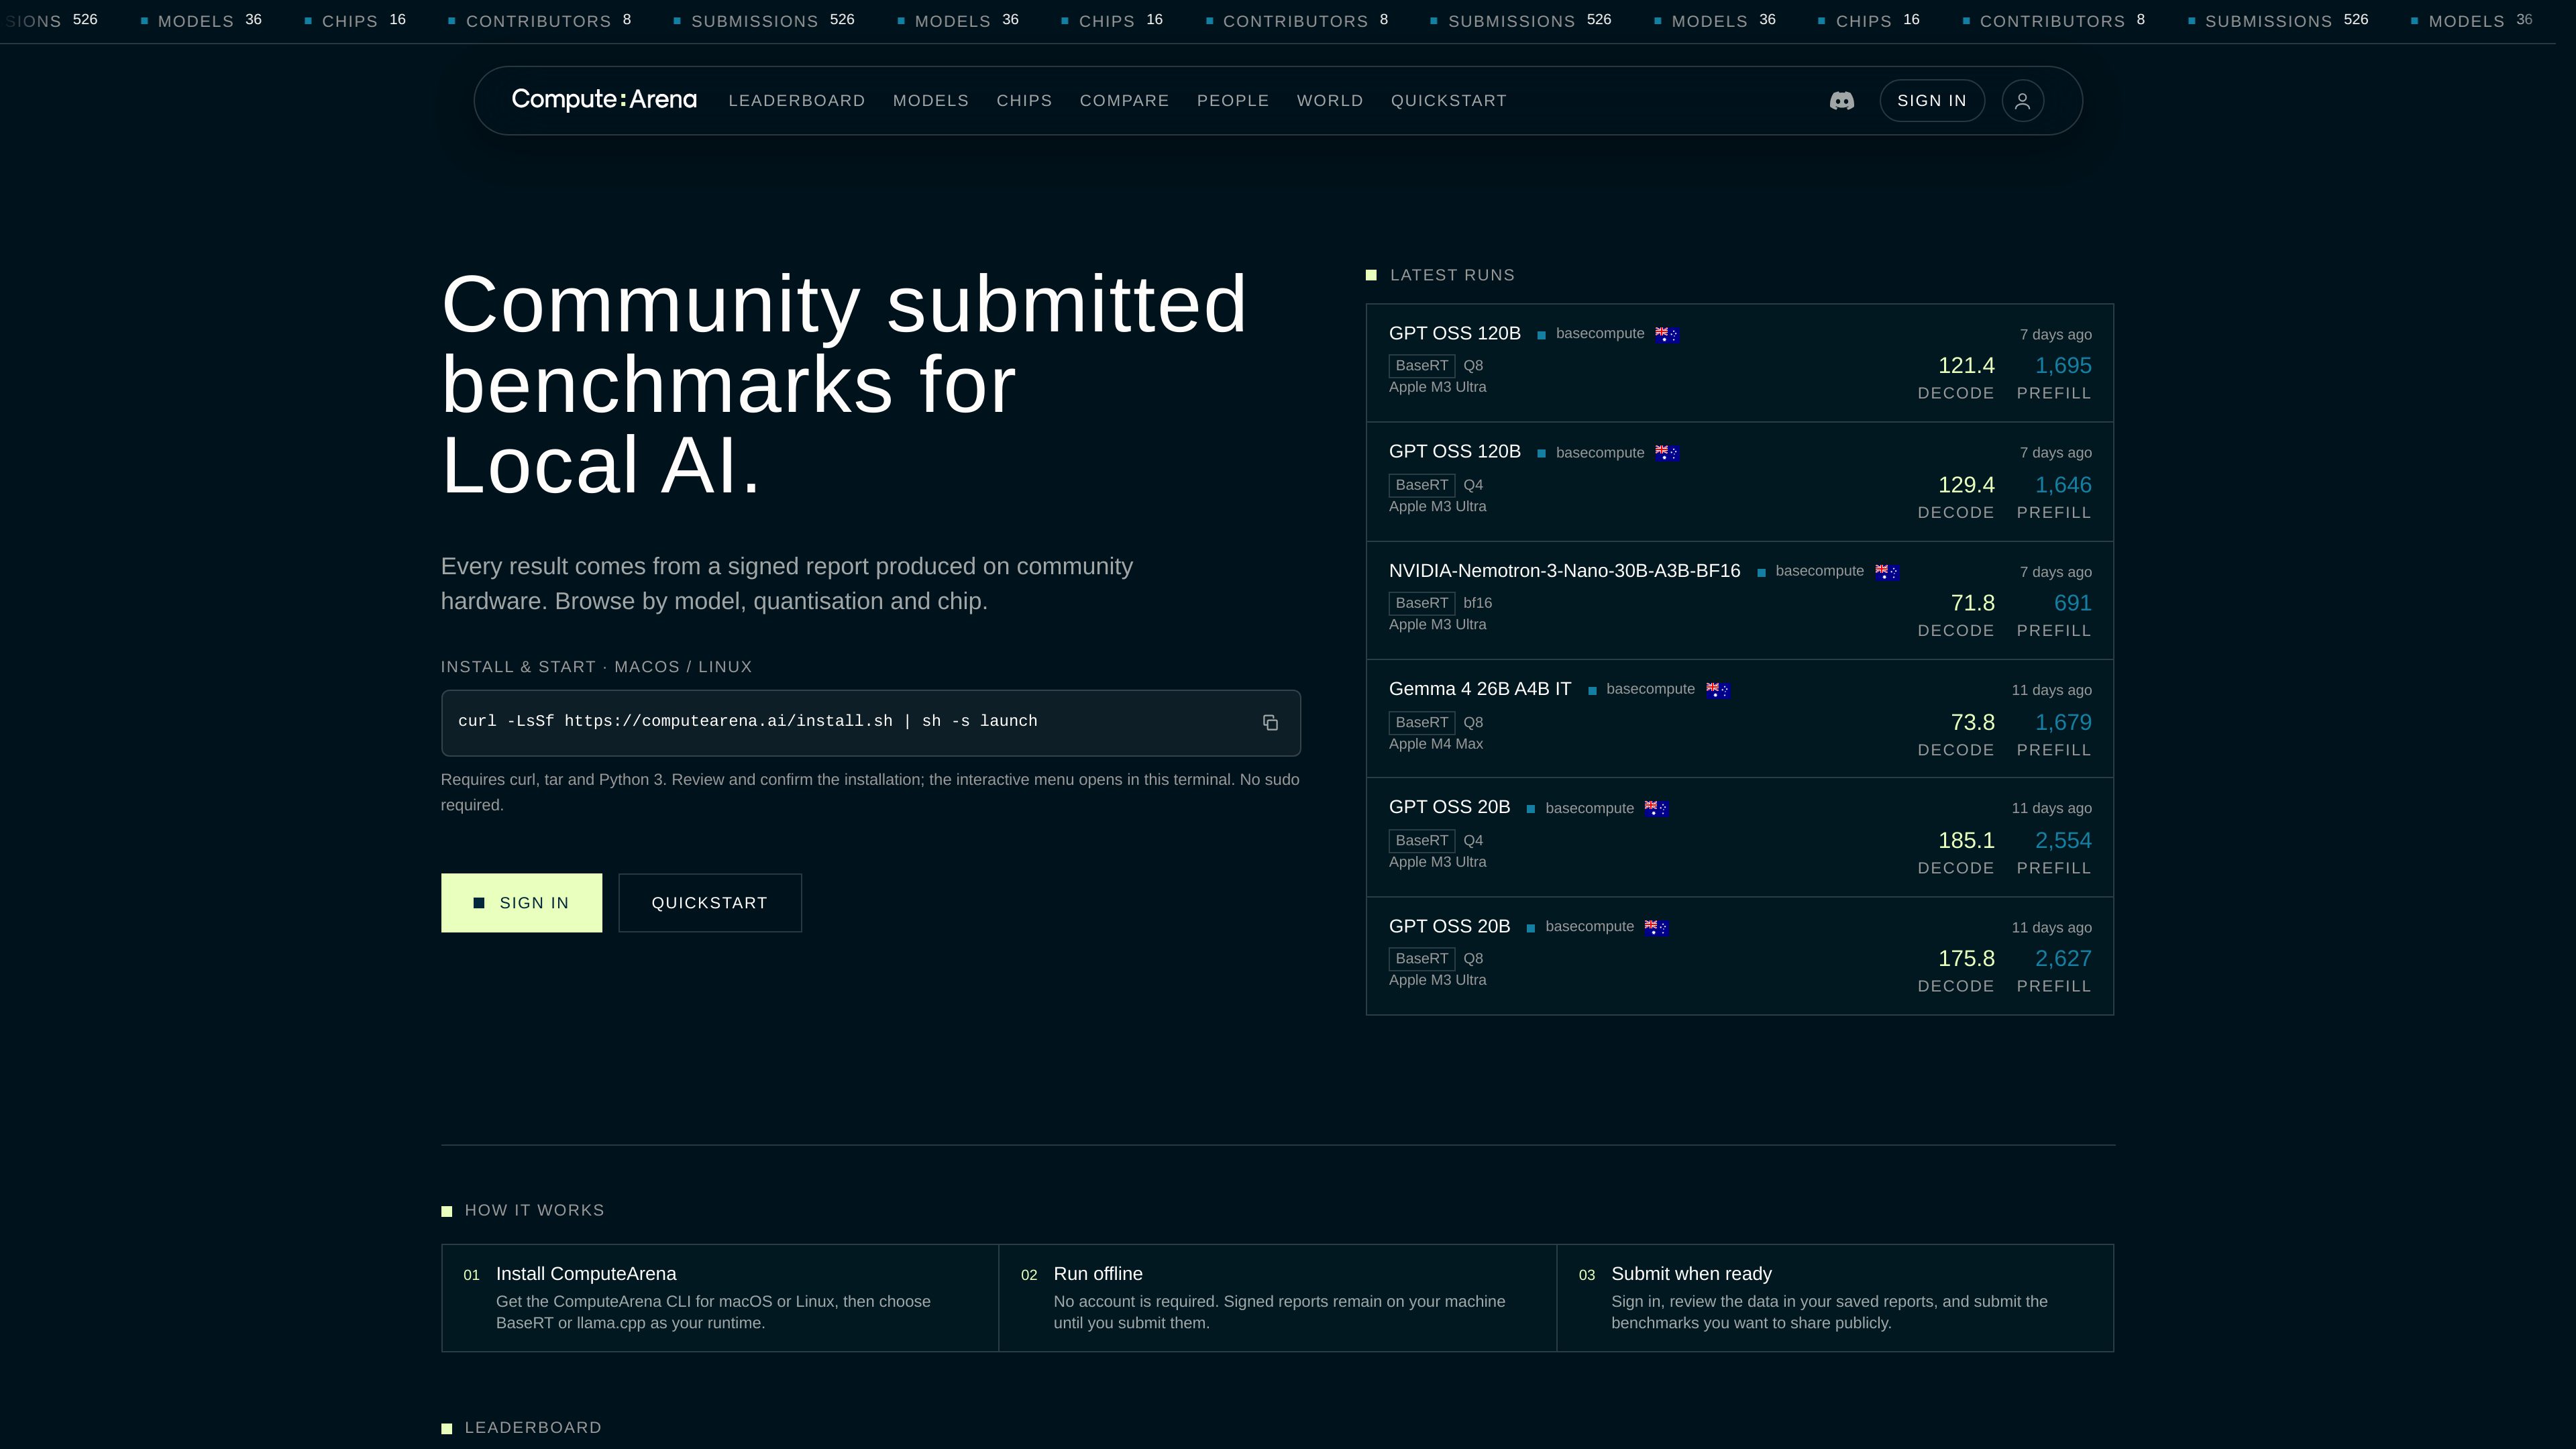
ComputeArena

大型語言模型評測

ComputeArena is a community benchmark directory for measuring local AI model throughput across chips, quantisations, and runtimes. It helps developers run offline benchmarks, inspect signed reports, and compare decode and prefill performance on compatible workloads.

免費及付費方案
QAgent preview
QAgent logo

QAgent

AI 測試助手

QAgent is an AI agent testing and quality assurance platform for developers and agile teams. It connects to an agent through a webhook or endpoint, runs automated test cases, and evaluates responses for groundedness, policy adherence, prompt compliance, and related quality dimensions.

免費及付費方案
NovaSynth preview
NovaSynth logo

NovaSynth

AI 測試助手

NovaSynth is a pre-production testing platform for AI agents that uses synthetic users across real SIP phone calls, LiveKit audio, and chat. It helps teams rehearse multi-turn interactions, surface failures, and validate fixes before releasing agents to customers.

免費及付費方案
Jev State preview
Jev State logo

Jev State

AI 智能體建立工具

Jev State is a workspace for defining, testing, and regression-checking conversational decisions powered by Jev. It helps teams inspect why an agent takes a step and export runnable TypeScript and tests for an application.

免費及付費方案
ALIA preview
ALIA logo

ALIA

AI模型中心

ALIA est une infrastructure de données IA spécialisée dans les langues, cultures et connaissances africaines. Elle permet aux organisations de collecter, annoter, valider et évaluer des données destinées à l’entraînement et à l’évaluation de modèles.

免費及付費方案
fez preview
fez logo

fez

AI 閘道與路由

Fez is an experimental decision-model platform that turns workflow context into probabilities for model routing, tool selection, escalation, and support triage. It helps teams train and evaluate specialized models for repeated decisions in AI systems.

免費及付費方案
iFixAi preview
iFixAi logo

iFixAi

大型語言模型評測

iFixAi independently audits AI agents for whether they perform their assigned work while respecting permissions, approvals, organizational boundaries, and evidence requirements. It is designed for teams that need to examine deployed or developing agents beyond conventional benchmarks and evals.

免費及付費方案
Giskard preview
Giskard logo

Giskard

AI 測試助手

Giskard is an AI security and evaluation platform for testing conversational LLM agents before and after deployment. It combines automated red teaming, quality evaluation, runtime guardrails, and remediation workflows for teams responsible for reliable AI systems.

免費及付費方案
DeepEval preview
DeepEval logo

DeepEval

AI 測試助手

DeepEval is an open-source LLM evaluation framework for testing and benchmarking AI applications. It helps developers run pytest-native evaluations, score outputs and agent traces, and iterate on systems across text, image, audio, and voice workflows.

免費及付費方案
TensorZero preview
TensorZero logo

TensorZero

AI 閘道與路由

TensorZero is an open-source LLMOps platform for building and operating production-grade LLM applications. Its stated scope combines an LLM gateway with observability, evaluation, optimization, and experimentation tools.

免費及付費方案
Galileo preview
Galileo logo

Galileo

AI 可觀測性

Galileo is an AI observability and evaluation platform for testing, debugging, and governing LLM and agent systems across development and production. It helps teams turn evaluation results into production guardrails and monitor AI behavior at scale.

免費及付費方案
Promptfoo preview
Promptfoo logo

Promptfoo

AI 測試助手

Promptfoo is an AI security and testing platform for evaluating LLM applications, agents, models, and workflows. It helps developers and security teams find vulnerabilities, validate guardrails, map findings to security frameworks, and track remediation through development and deployment.

免費及付費方案
TruLens preview
TruLens logo

TruLens

AI 智能體基礎設施

TruLens is an open-source library for tracing and evaluating AI agents and other LLM applications. It helps development teams inspect agent steps, score quality with configurable metrics, and compare application versions using OpenTelemetry-based instrumentation.

免費及付費方案