Inworld AI logo

Inworld AI

Paid
Visit

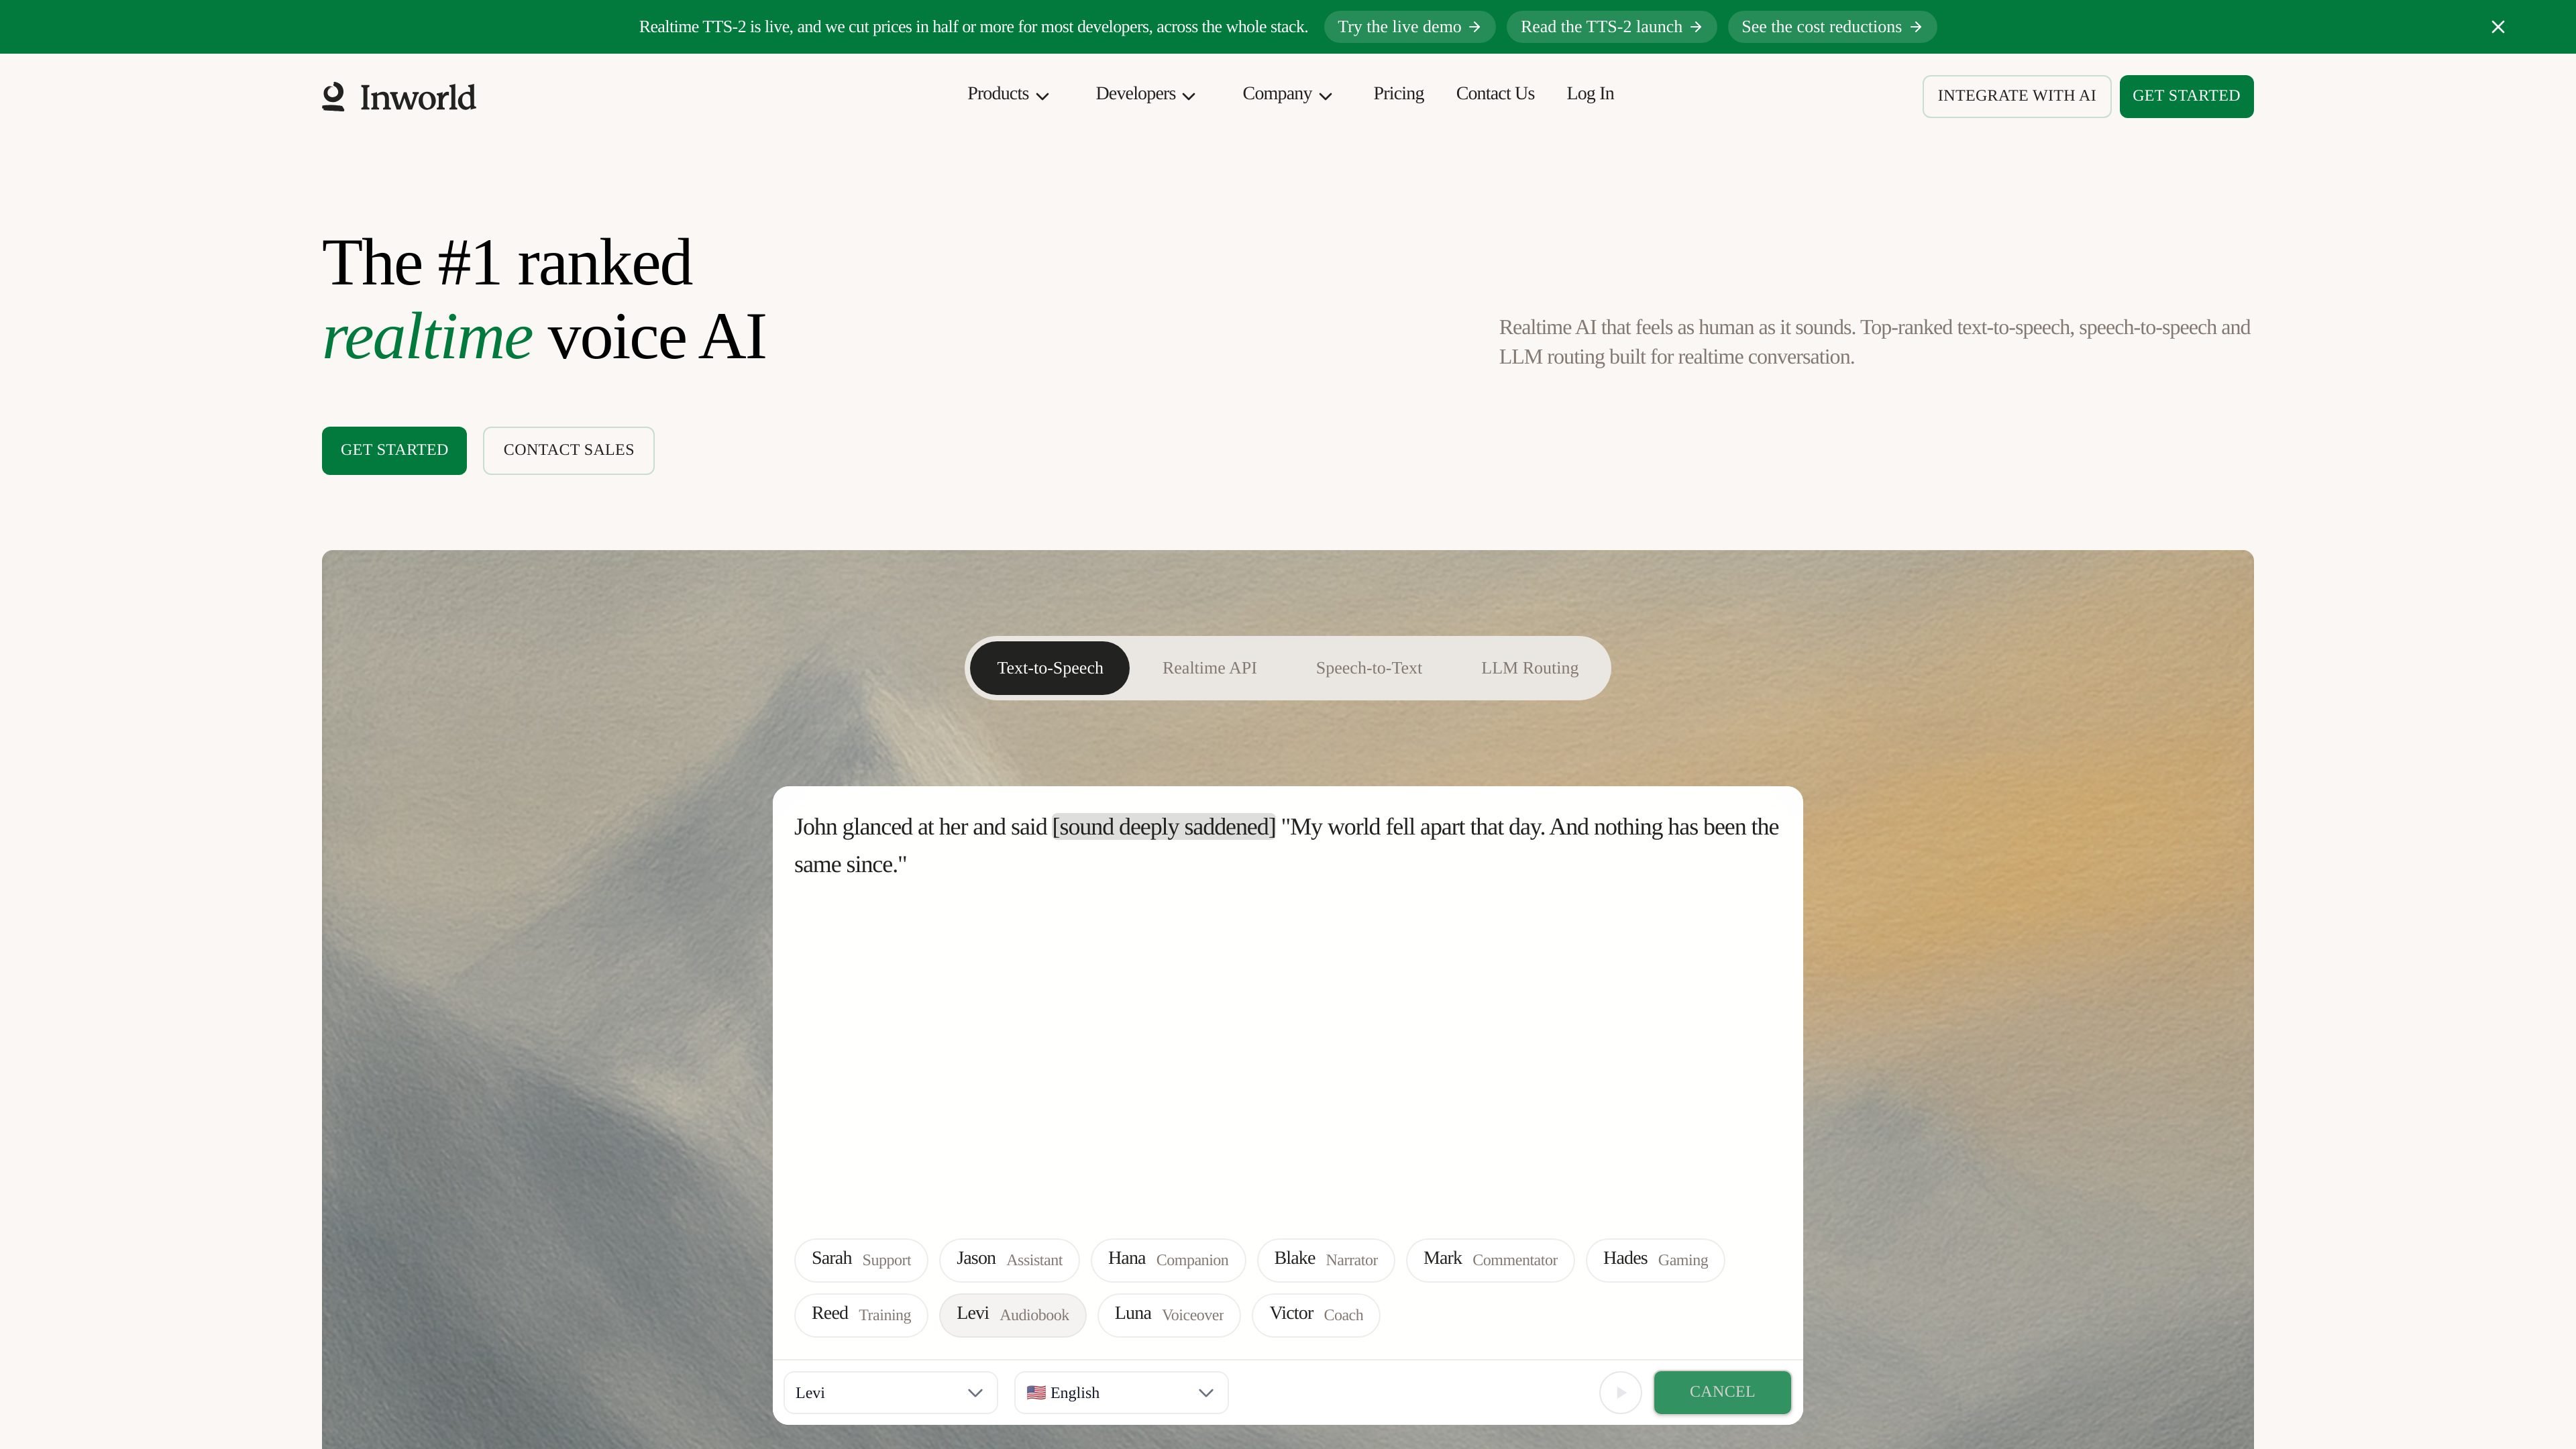
Realtime voice, speech, and language-model infrastructure for consumer applications.

What is Inworld AI?

Inworld AI provides developer APIs for speech generation, transcription, realtime voice conversations, and language-model routing. Use the services individually or combine speech input, a chosen language model, and synthesized output in a live conversation. The platform serves applications such as language practice, interactive characters, companions, and voice support.

Start with an Inworld account and the relevant Voice or Inference quickstart, then configure credentials, models, and application behavior. Production use needs attention to usage costs, request and connection limits, permitted data handling, and the quality of generated responses. Voice synthesis and inferred speech-profile signals do not establish that an answer or a personal characteristic is correct.

What can Inworld AI do?

Realtime text-to-speech

Stream generated speech with pronunciation, timing, and voice controls. TTS-2 supports inline voice-direction instructions, while available controls depend on the chosen model; advertised latency is not an end-to-end application guarantee.

Speech recognition with voice profiling

Transcribe live audio through bidirectional WebSocket streaming or use synchronous transcription for files. Voice-profile outputs include inferred signals such as pitch, style, emotion, age, and accent; treat those estimates as model outputs rather than verified personal facts.

Persistent realtime voice sessions

Combine speech input, a language model, and speech output in a live session. Realtime controls include turn taking, tool calling, provider selection, and context management; configure and test them for the intended client and workflow.

LLM routing and hosted inference

Access multiple language models through a routing interface, with controls for model selection and fallback behavior. Choose models around the application’s requirements and provider terms; a shared interface does not make model results uniformly accurate.

Voice cloning and design

Create a voice from reference audio or describe a voice in text. Use voices and recordings for which you have appropriate permission, and check the selected model and plan’s cloning and language support.

Use Cases

“Spoken language learning”

Add spoken practice and character voices to language-learning applications. Test pronunciation, supported languages, and the underlying teaching responses rather than assuming speech quality proves educational correctness.

“Conversational companions and social apps”

Consumer applications can build voice-led interactions by pairing a persistent speech session with a selected language model and synthesized voice.

“Game and interactive-media characters”

Generate character dialogue and spoken media with suitable voice controls and timing outputs. Check the chosen model’s available timestamp format and the project’s voice permissions before integrating playback.

“Voice support and phone agents”

Combine realtime transcription, a selected LLM, and synthesized responses for a support or phone-agent workflow. Configure permitted tool actions, escalation behavior, and response checks before allowing an agent to act for a user.

“Model selection for live applications”

Application teams can route requests among external and hosted LLMs to match model choice to a particular user interaction or deployment requirement.

Frequently Asked Questions

Can Inworld support a complete voice conversation?

Yes. The Realtime API combines speech input and output with a selected language model in a live session. It offers turn-taking, tool-calling, provider, and context controls. Client connections and available behaviors need configuration and testing.

Where should a developer start?

Create an Inworld platform account and follow the Voice or Inference quickstart in the developer documentation. Create credentials with the required permissions. Keep API keys out of browser or mobile client code; use a backend or the appropriate short-lived client token.

Do all speech models have the same controls?

No. Check the selected model’s language, cloning, timing, and steering support. For example, the pricing table limits voice steering to Realtime TTS-2. Do not assume every model or plan provides an identical voice workflow.

Are voice-profile outputs verified facts about a speaker?

No. Emotion, age, accent, pitch, and style signals are inferred model outputs. Review their suitability and the relevant data permissions before using them, especially where a mistaken inference could affect a person.

How is usage billed?

Paid plans provide a credit balance that is deducted at the plan’s metered rates; LLM usage is billed at provider cost. Limits and entitlements vary. On-Demand includes a finite free evaluation allowance, not unlimited ongoing speech. Check top-up or auto-reload settings and billing-period conditions.

Can every account assume zero data retention?

No. Zero data retention and regulated-workload options are listed as plan-specific add-ons, while enterprise terms can include additional data-region and access arrangements. Confirm the selected agreement and relevant provider requirements before sending sensitive data.

Quick Facts

Product
Developer voice and inference platform
Core inputs
Text, audio, conversation context, and model requests
Outputs
Synthesized speech, transcripts, model responses, and inferred voice signals
Integration
APIs, realtime connections, and authenticated platform access
Billing
Metered credits and plan-specific limits
Data handling
Retention and regional options depend on the selected terms

Inworld AI Traffic Analysis

Traffic data is for reference only.

Domain Rating
74

Inworld AI Alternatives

Daily logo

Daily

daily.co

Daily provides SDKs and infrastructure for realtime voice and video calls, recording, and AI agent workflows across web, mobile, desktop, native, and server applications, with Pipecat Cloud for voice AI deployment.

SpeechifyAI logo

SpeechifyAI

speechify.ai

SpeechifyAI is a developer API for expressive text-to-speech and voice cloning. It provides streaming Simba models, catalog and cloned voices, SSML support, and a free starting tier for building speech into applications.

Speechmatics logo

Speechmatics

www.speechmatics.com

Speechmatics provides speech-to-text APIs for pre-recorded and real-time audio, with support for multilingual speech, multiple speakers, and voice-agent workflows. It is designed for teams building transcription and Voice AI applications.

Deepgram logo

Deepgram

deepgram.com

Speech-to-text, text-to-speech, and voice agent APIs for developers and enterprises.

Voicemaker logo

Voicemaker

voicemaker.in

Voicemaker is a browser-based text-to-speech platform for creating and fine-tuning AI voice output in multiple languages and formats.