
Dense, sparse, and hybrid indexes
Choose dense indexes for semantic search, sparse indexes for full-text or keyword search, or hybrid indexes when both search approaches are needed.

Upstash Vector is a serverless vector database for storing and querying embeddings and metadata in AI and machine-learning applications. It supports dense, sparse, and hybrid indexes through a REST API and SDKs for Python, TypeScript, Go, and PHP.
Upstash Vector is a serverless vector database for similarity search over embeddings and metadata. It lets developers create an index, insert vectors, and query for similar results through a REST API or SDKs.
Indexes can be dense, sparse, or hybrid: dense is suited to semantic search, sparse to full-text or keyword search, and hybrid to a combination of both. The service also provides metadata filtering, namespaces, live index updates, console-based usage charts, and a query interface. It is designed for AI and machine-learning applications that need retrieval from application data.
Choose dense indexes for semantic search, sparse indexes for full-text or keyword search, or hybrid indexes when both search approaches are needed.
Insert vectors with an ID and metadata, then query by vector similarity. Query responses can include stored metadata, and queries support metadata filtering.
Access indexes through REST or the documented Python, TypeScript/JavaScript, Go, and PHP clients. Connection details and sample code are available from the console.
The Vector service includes namespaces and live index updates, allowing applications to organize vector data and update indexes as application data changes.
The Upstash console reports daily requests, throughput, mean and P99 latency, vector count, and data size, and provides a simple interface for querying an index.
Available plans include Free, Pay as You Go, Fixed, Pro, and Enterprise. The documented free plan is intended for small projects, while other plans address variable traffic, predictable loads, or larger deployments.
Store embedding vectors for application content and query them with a vector to retrieve the most similar records for an AI or machine-learning workflow.
Use a sparse index for full-text or keyword search when exact terms and lexical matching are more important than embedding similarity.
Use a hybrid index when an application needs to combine semantic similarity with full-text search in the same retrieval workflow.
Use namespaces to organize vectors within an index when an application needs separate logical data groups, such as different collections or application partitions.
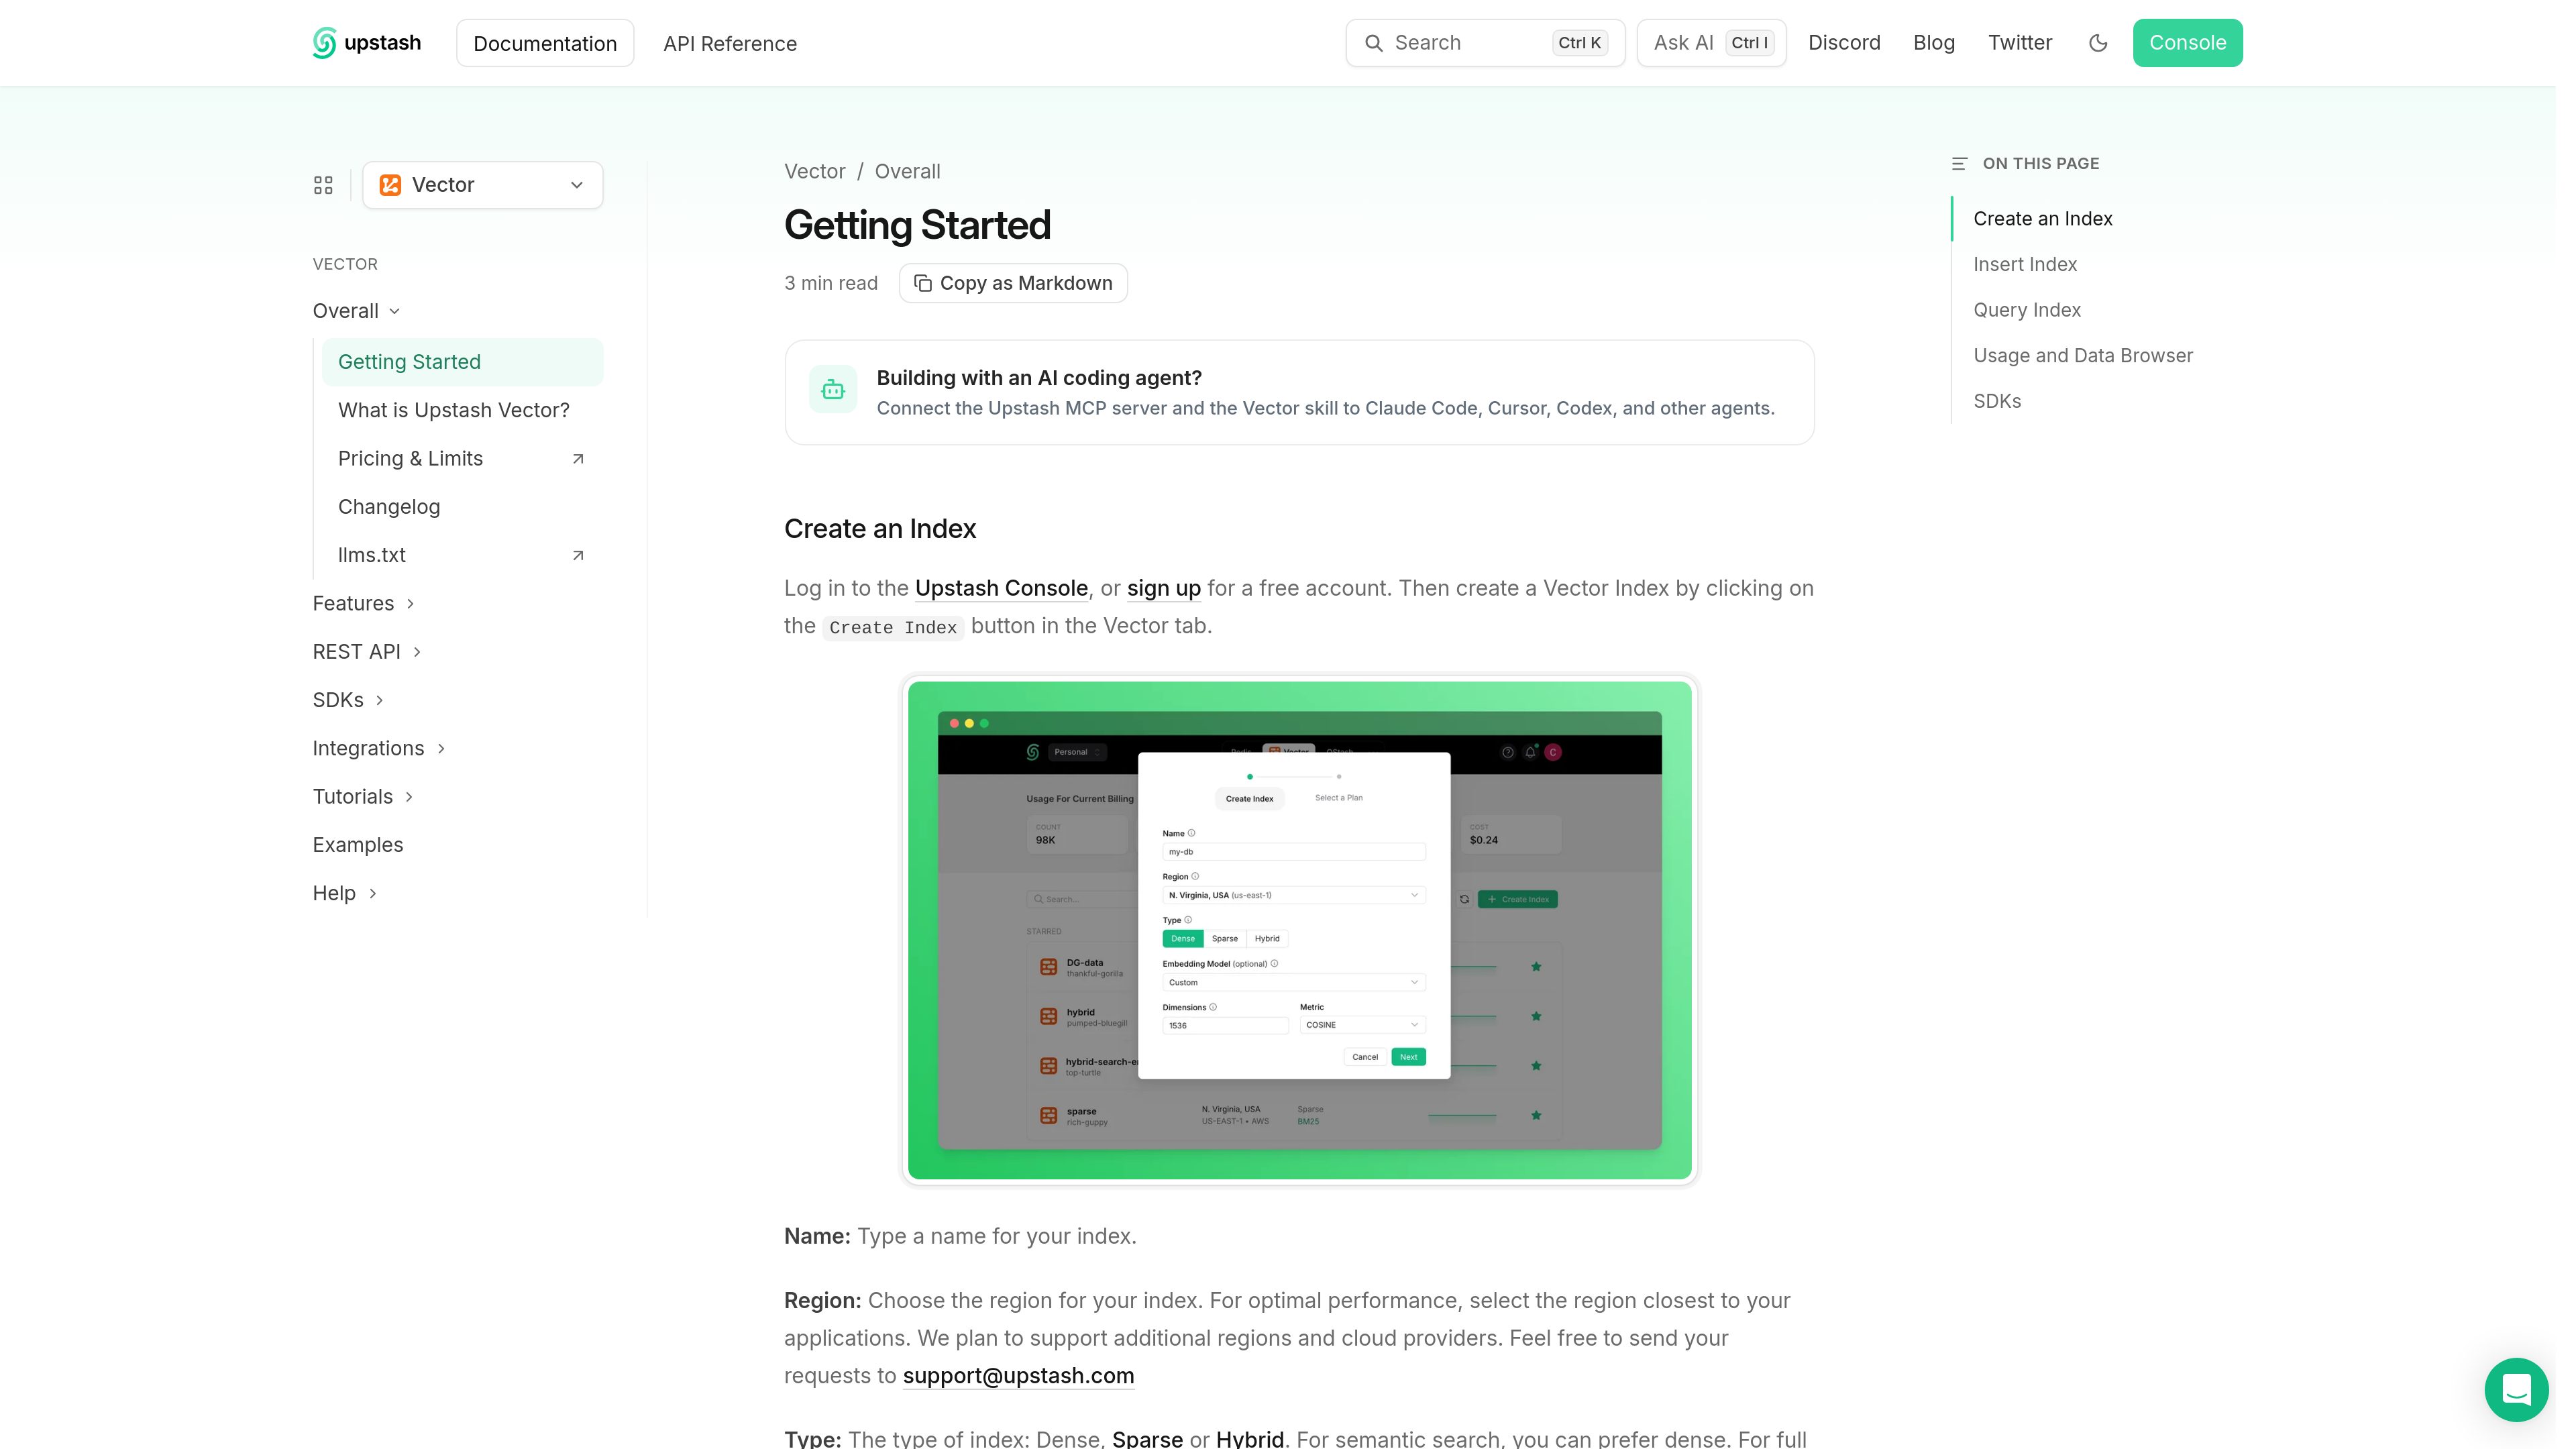
Log in to the Upstash Console or create a free account, open the Vector tab, and select Create Index. Choose a name, region, index type, and— for dense or hybrid indexes—dimensions and a distance metric.
Use the REST API or an SDK/client for Python, TypeScript/JavaScript, Go, or PHP. The console provides connection details and sample code.
Dense indexes are intended for semantic search, sparse indexes for full-text or keyword search, and hybrid indexes for combining the two.
Not necessarily. Upstash documents Vector as eventually consistent, so there may be a delay before newly inserted or updated vectors are ready for querying.
The Vector pricing FAQ states that 1,000 is the default limit for top-k.

supabase.com
Supabase is a Postgres development platform for building applications with a database, authentication, APIs, realtime features, serverless functions, storage, and vector support. It helps developers move from application code to a managed backend through a dashboard, client libraries, CLI, and generated APIs.
pgvector.org
pgvector is an open-source PostgreSQL extension for storing vectors and running exact or approximate nearest-neighbor searches alongside relational data. It supports multiple vector formats, distance functions, and standard PostgreSQL operations for applications that need similarity search.

redis.io
Redis is a real-time data platform and database for applications, with Redis Cloud providing a fully managed deployment on major public cloud services. It supports application data, caching, search, and AI-oriented workflows through Redis and Redis Stack.

myscale.com
MyScale queries vector and structured data with SQL. Build similarity and filtered retrieval over embeddings and metadata on a managed cloud cluster.
serenedb.com
SereneDB is a search-OLAP database for real-time full-text, vector, hybrid search, and analytical queries over the same data. It uses SQL and the PostgreSQL wire protocol, helping developers connect with familiar clients while keeping search and analytics in one engine.

weaviate.io
Weaviate is a vector database for building AI-native applications, including retrieval-augmented generation systems. It helps developers store and retrieve vector data, connect applications to language models, and deploy the database in a managed, self-hosted, or private-cloud environment.