
Vectors and structured columns together
Keep embedding vectors alongside metadata in the same database. Use SQL to query those fields and join vector search results with another table.

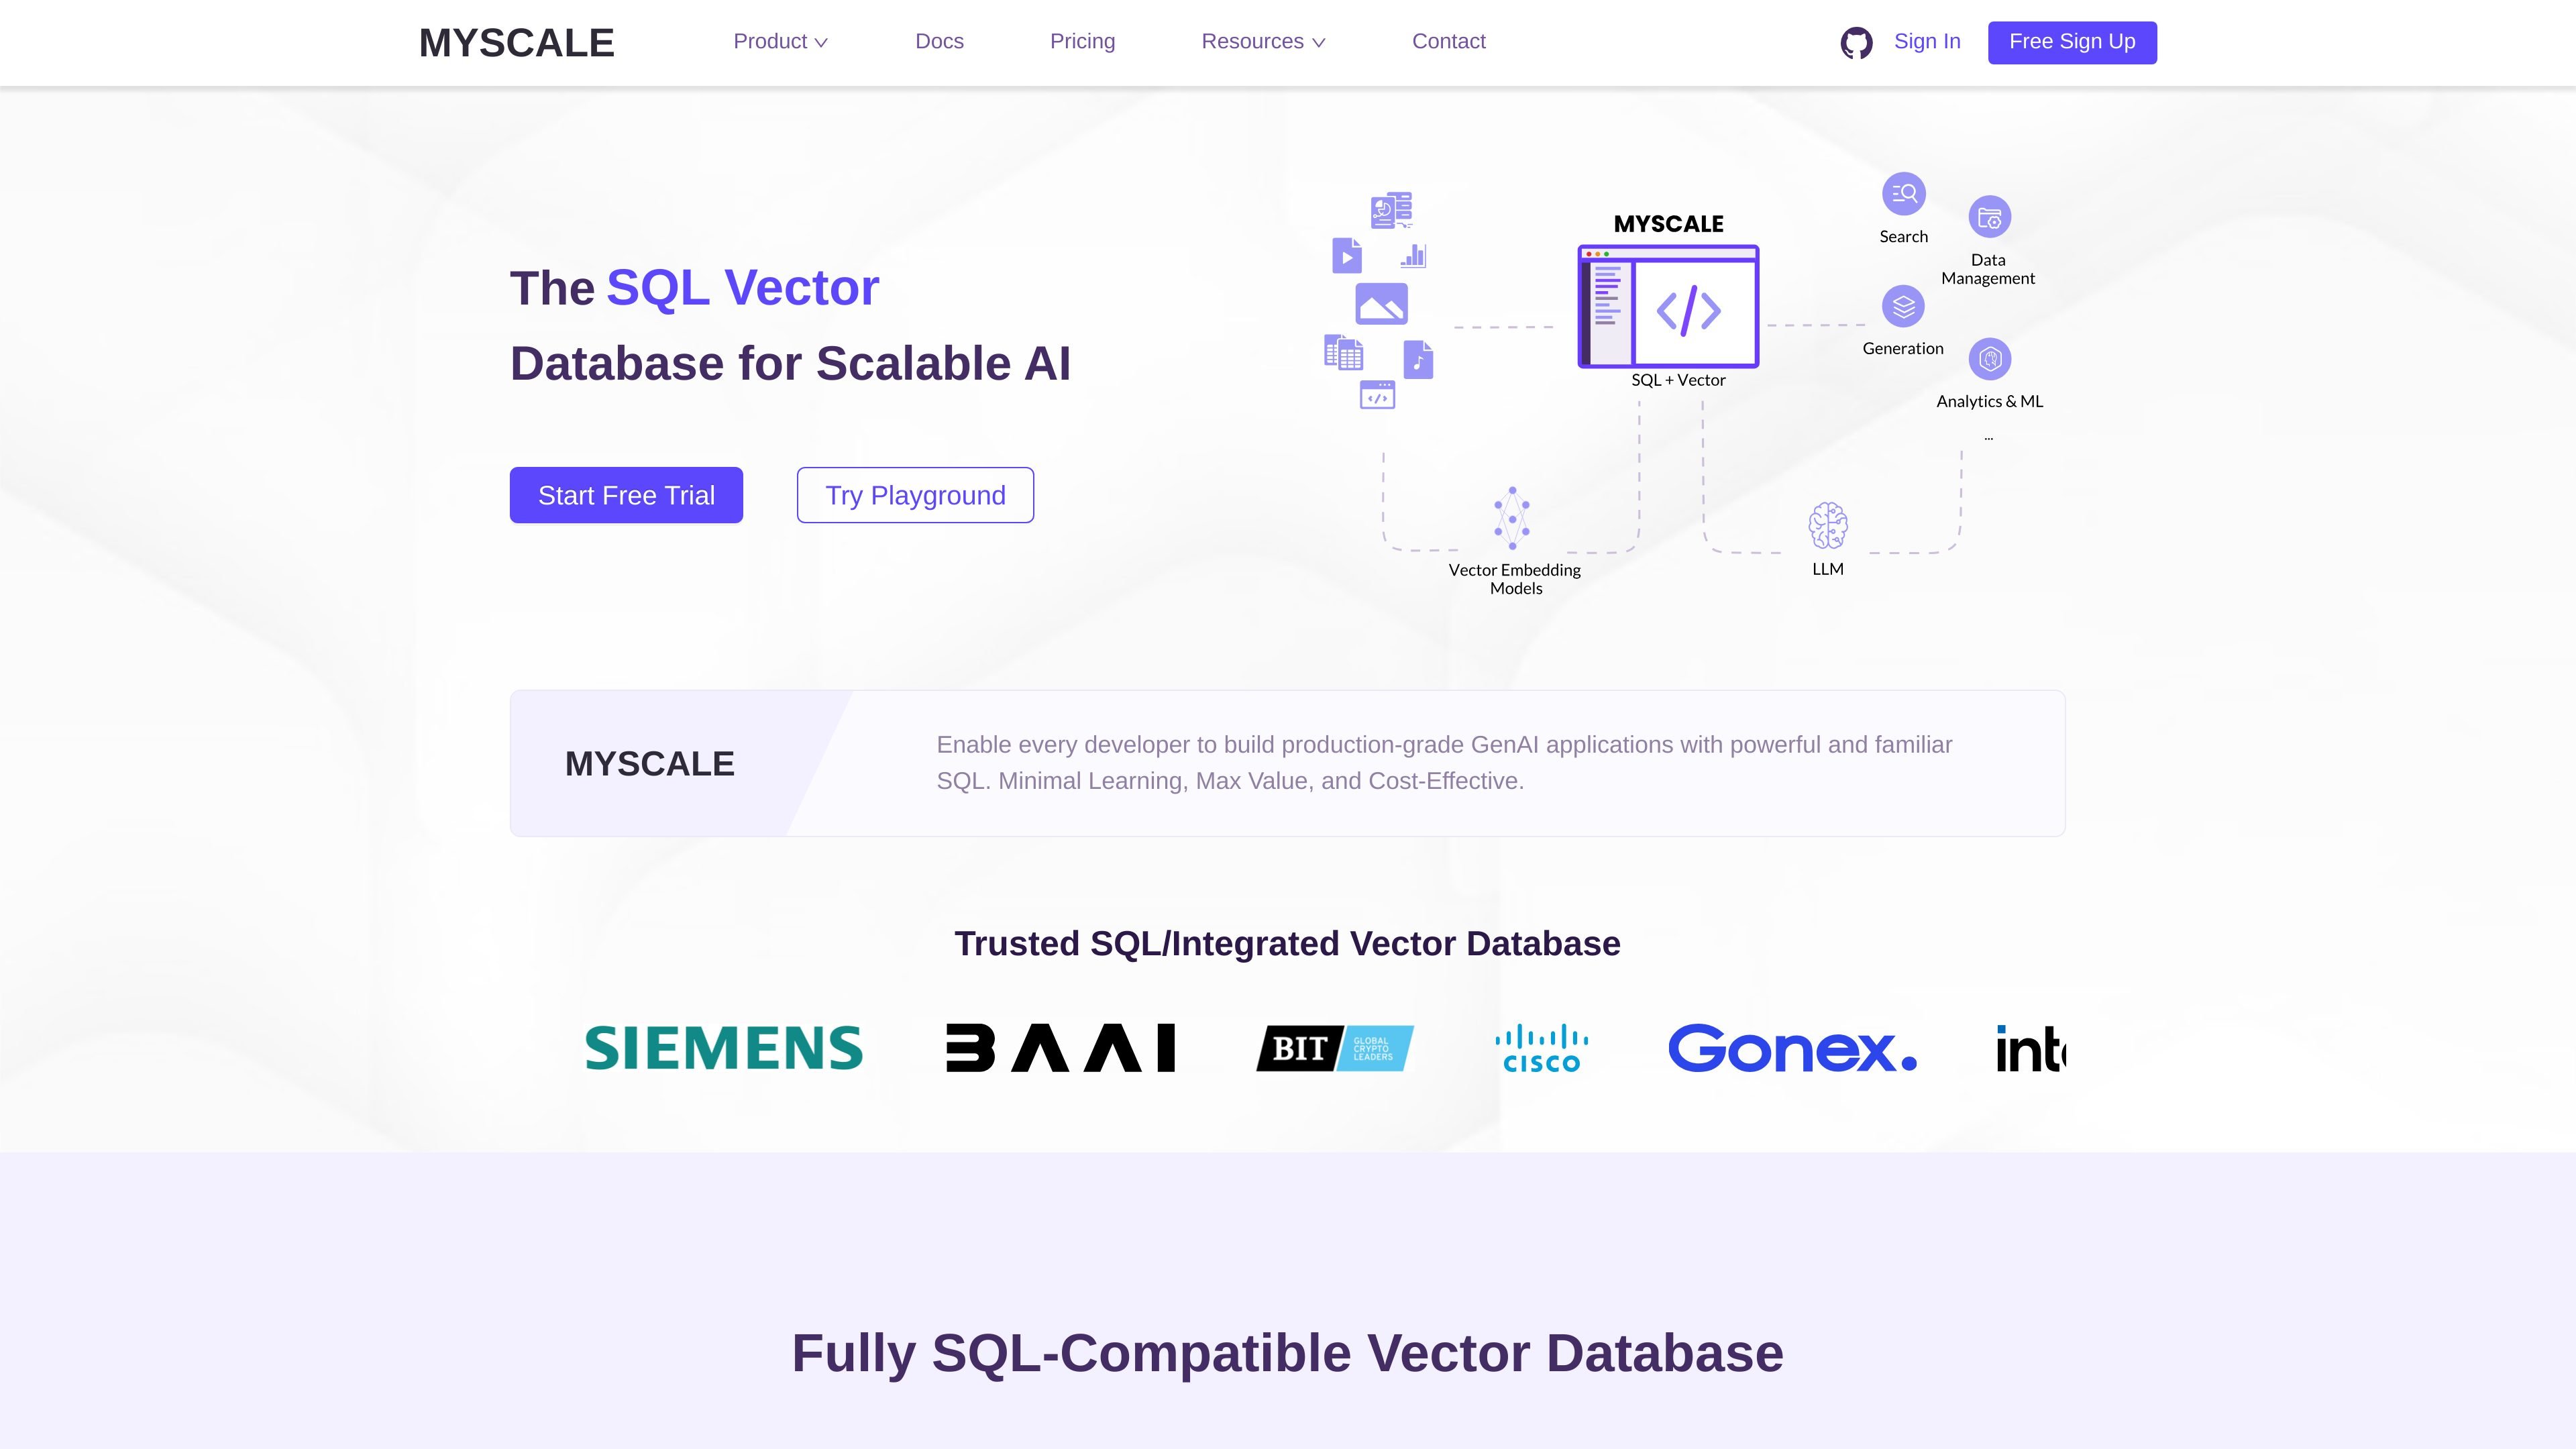
MyScale queries vector and structured data with SQL. Build similarity and filtered retrieval over embeddings and metadata on a managed cloud cluster.
MyScale is a cloud database for applications that need vector similarity search alongside structured data queries. Built on ClickHouse, it stores embeddings and ordinary table columns together so developers can combine a query vector with SQL filters, analytics and joins.
Start by launching a cluster, creating a table and importing your data. Build an MSTG vector index and check that it is ready, then run queries in SQL Workspace or connect an application through a supported client. Search returns matching rows ranked by vector distance; SQL conditions can narrow them by fields such as labels or dates.
Keep embedding vectors alongside metadata in the same database. Use SQL to query those fields and join vector search results with another table.
Build MyScale's MSTG vector index and submit a query vector for nearest-neighbor retrieval. Rank matching records by their vector distance and combine the results with metadata.
Combine vector distance ordering with SQL WHERE conditions. Full-text indexing provides a text search option alongside the database's vector and structured query capabilities.
Import formats such as CSV, JSONEachRow and Parquet, then inspect results in the web SQL Workspace. Connect applications with Python, Node.js, Go, JDBC or HTTPS using the cluster's connection details.
Search stored embeddings for relevant records that an application can use as context. The returned records are a retrieval step; answer generation remains part of the application workflow.
Find similar entries while restricting results to selected labels, dates or other structured fields, keeping similarity ranking and filtering in one SQL query.
Use numerical representations of text, images or other data for similarity queries, then combine matches with structured columns and SQL analysis.
Store vectors in a table and supply a query vector to a distance query. After building an index, MyScale returns similar records and their distances. Choose embeddings and a similarity metric appropriate to the data your application searches.
Development supports one cluster with a default configuration and no multiple replicas. Seven days without activity terminate the cluster and delete all of its data.
Billing depends on the usage time of pods and their type, size and replica configuration. The console's Admin > Billing area lets you switch plans, update a payment card and view invoices. Plan choice and resource configuration therefore matter when comparing operating costs.
Standard supports size and replica changes; cluster size can only increase. During a size change, a single-replica cluster cannot execute statements, while a multi-replica cluster permits reads but not writes. Replica changes permit only SELECT statements while scaling.
Use SQL Workspace in the console or a Python, Node.js, Go, JDBC or HTTPS client. The cluster list's Connection Details action supplies the endpoint and authentication information. The cluster must be started before importing data or executing queries.
Os dados de tráfego são apenas para referência.

weaviate.io
Weaviate is a vector database for building AI-native applications, including retrieval-augmented generation systems. It helps developers store and retrieve vector data, connect applications to language models, and deploy the database in a managed, self-hosted, or private-cloud environment.
serenedb.com
SereneDB is a search-OLAP database for real-time full-text, vector, hybrid search, and analytical queries over the same data. It uses SQL and the PostgreSQL wire protocol, helping developers connect with familiar clients while keeping search and analytics in one engine.
pgvector.org
pgvector is an open-source PostgreSQL extension for storing vectors and running exact or approximate nearest-neighbor searches alongside relational data. It supports multiple vector formats, distance functions, and standard PostgreSQL operations for applications that need similarity search.

redis.io
Redis is a real-time data platform and database for applications, with Redis Cloud providing a fully managed deployment on major public cloud services. It supports application data, caching, search, and AI-oriented workflows through Redis and Redis Stack.

upstash.com
Upstash Vector is a serverless vector database for storing and querying embeddings and metadata in AI and machine-learning applications. It supports dense, sparse, and hybrid indexes through a REST API and SDKs for Python, TypeScript, Go, and PHP.

supabase.com
Supabase is a Postgres development platform for building applications with a database, authentication, APIs, realtime features, serverless functions, storage, and vector support. It helps developers move from application code to a managed backend through a dashboard, client libraries, CLI, and generated APIs.