
Automated AI red teaming
Runs adversarial tests across security and quality threats, including prompt injection, hallucination, legal and financial risks, harmful content, personal-information disclosure, and other vulnerability classes.
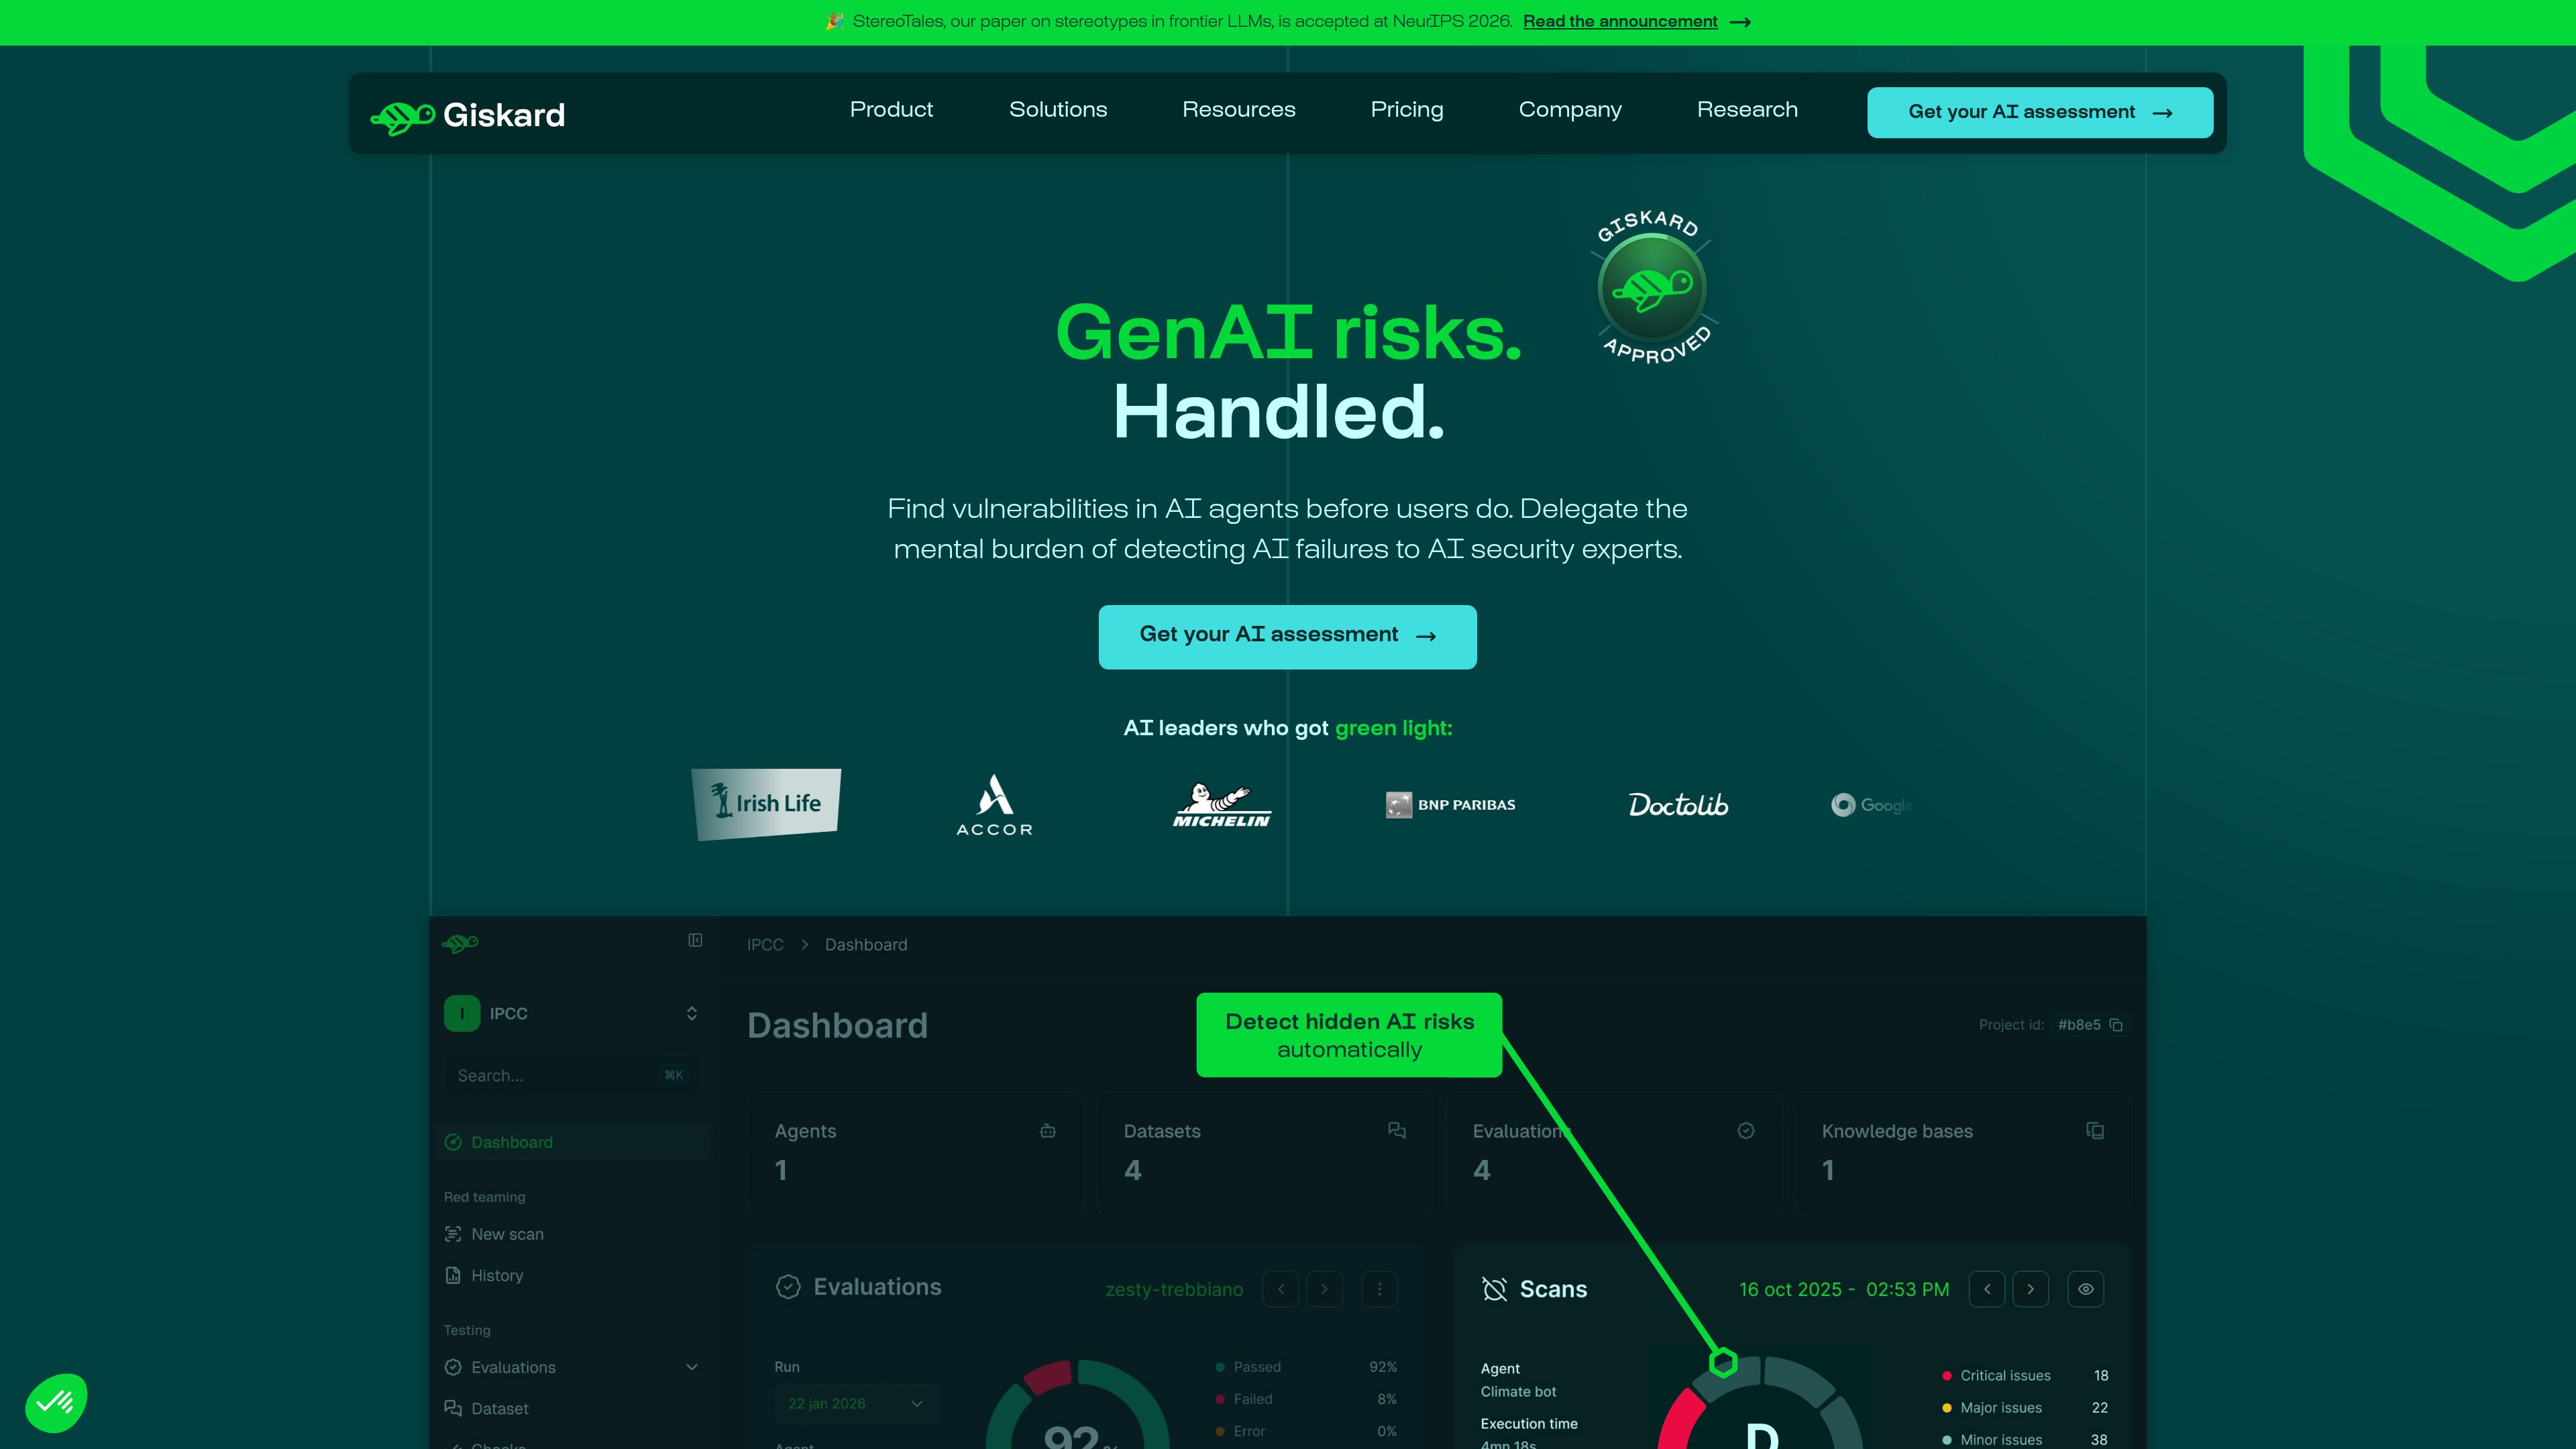
Giskard is an AI security and evaluation platform for testing conversational LLM agents before and after deployment. It combines automated red teaming, quality evaluation, runtime guardrails, and remediation workflows for teams responsible for reliable AI systems.
Giskard is an AI security and evaluation platform for conversational LLM agents. It tests agents as black boxes through an API endpoint, without requiring access to their foundation model, vector database, or other internal components. The platform is designed for both pre-deployment assessment and continuous testing after release, covering security risks and response-quality problems.
Its security capabilities include automated adversarial testing, multi-turn attacks, prompt-injection testing, data-disclosure checks, harmful-content and stereotype detection, and tool-calling validation. The platform also supports scenario-based tests that model specific personas and business logic. Giskard Guards adds a runtime control layer that evaluates prompts, tool calls, parameters, permissions, and responses against context-aware, policy-driven rules.
For quality evaluation, Giskard can generate domain-specific question-and-expectation pairs from a knowledge base, apply RAG quality metrics, and support custom evaluation metrics defined around business requirements. Human reviewers can inspect, debug, annotate, and prioritize results. Dataset import, tags, task assignment, audit trails, scheduled alerts, and CI/CD support connect testing with ongoing engineering and review processes.
After an assessment, the platform provides a structured report with a deployment verdict, ranked security findings, and functional scenarios tested against the team’s requirements. Giskard describes a remediation workflow that includes qualifying findings, discussing severity, prioritizing actions, opening tickets, and rerunning tests to confirm fixes. Deployment options described on the site include SaaS, private cloud, on-premises, and air-gapped environments, with enterprise controls for access, data residency, and support.
Runs adversarial tests across security and quality threats, including prompt injection, hallucination, legal and financial risks, harmful content, personal-information disclosure, and other vulnerability classes.
Tests conversational flows and agent behavior across multiple turns, including tool calls, parameters, user permissions, and complex scenarios rather than evaluating isolated text alone.
Giskard Guards applies natural-language or policy-as-code rules to prompts, tools, and responses, with custom policies and coverage for OWASP LLM risks and selected EU AI Act topics.
Generates domain-specific evaluation data, checks retrieval-augmented responses with fine-grained quality metrics, and supports custom metrics tailored to business logic.
Provides interfaces for reviewing, debugging, and annotating results, along with tags, task assignment, versioning, audit trails, and scheduled email alerts for critical failures or newly detected vulnerabilities.
Offers SaaS, private-cloud, on-premises, and air-gapped deployment options described for enterprise use, with data-residency choices, role-based access controls, audit trails, encryption, and a stated zero-training policy.
Product and AI teams can test a conversational agent against security vulnerabilities and functional requirements before deployment, then use the structured report and deployment verdict to decide whether to release or remediate.
Teams can rerun evaluations and adversarial tests as agents, prompts, policies, or connected tools change, helping identify new vulnerabilities and regressions after deployment.
Teams building assistants over internal knowledge bases can generate representative question-and-expectation pairs and assess correctness, grounding, omissions, contradictions, and hallucinations.
Security, compliance, and platform teams can use Giskard Guards to turn organizational or regulatory requirements into enforceable policies that inspect agent interactions and tool activity in production environments.
Engineering, security, and review teams can qualify findings, assign actions, annotate test cases, track versions, maintain audit logs, and rerun tests to verify that fixes address the original issue.
Both. The site describes pre-deployment testing for production-readiness KPIs and post-deployment continuous testing to detect vulnerabilities that emerge as the application operates or changes.
The Giskard Hub is described as supporting conversational AI agents in text-to-text mode. It uses black-box testing, so the agent’s internal foundation model and vector database do not need to be exposed; the complete agent must be accessible through an API endpoint.
Giskard describes a structured report with a clear deploy-or-fix verdict, security vulnerabilities ranked by criticality, and functional scenarios tested against the team’s requirements. It may also provide a Giskard Label when an agent passes.
Yes. The platform supports custom evaluation metrics and scenario-based tests. Giskard Guards supports custom guidelines in natural language and policy-as-code rules, including OPA/Rego as listed on the Guards page.
The pricing and product pages describe SaaS, private-cloud, on-premises, and air-gapped deployment options for enterprise use. The site also describes regional data residency and isolation choices, including EU or US processing options on the home page.

deepeval.com
DeepEval is an open-source LLM evaluation framework for testing and benchmarking AI applications. It helps developers run pytest-native evaluations, score outputs and agent traces, and iterate on systems across text, image, audio, and voice workflows.
www.galileo.ai
Galileo is an AI observability and evaluation platform for testing, debugging, and governing LLM and agent systems across development and production. It helps teams turn evaluation results into production guardrails and monitor AI behavior at scale.

jev-state.vercel.app
Jev State is a workspace for defining, testing, and regression-checking conversational decisions powered by Jev. It helps teams inspect why an agent takes a step and export runnable TypeScript and tests for an application.

www.promptfoo.dev
Promptfoo is an AI security and testing platform for evaluating LLM applications, agents, models, and workflows. It helps developers and security teams find vulnerabilities, validate guardrails, map findings to security frameworks, and track remediation through development and deployment.
www.mcpjam.com
MCPJam is a testing and evaluation platform for MCP servers. It helps developers inspect servers locally, run user and model-based tests, and add behavior checks to CI/CD workflows.

qagent.in
QAgent is an AI agent testing and quality assurance platform for developers and agile teams. It connects to an agent through a webhook or endpoint, runs automated test cases, and evaluates responses for groundedness, policy adherence, prompt compliance, and related quality dimensions.