
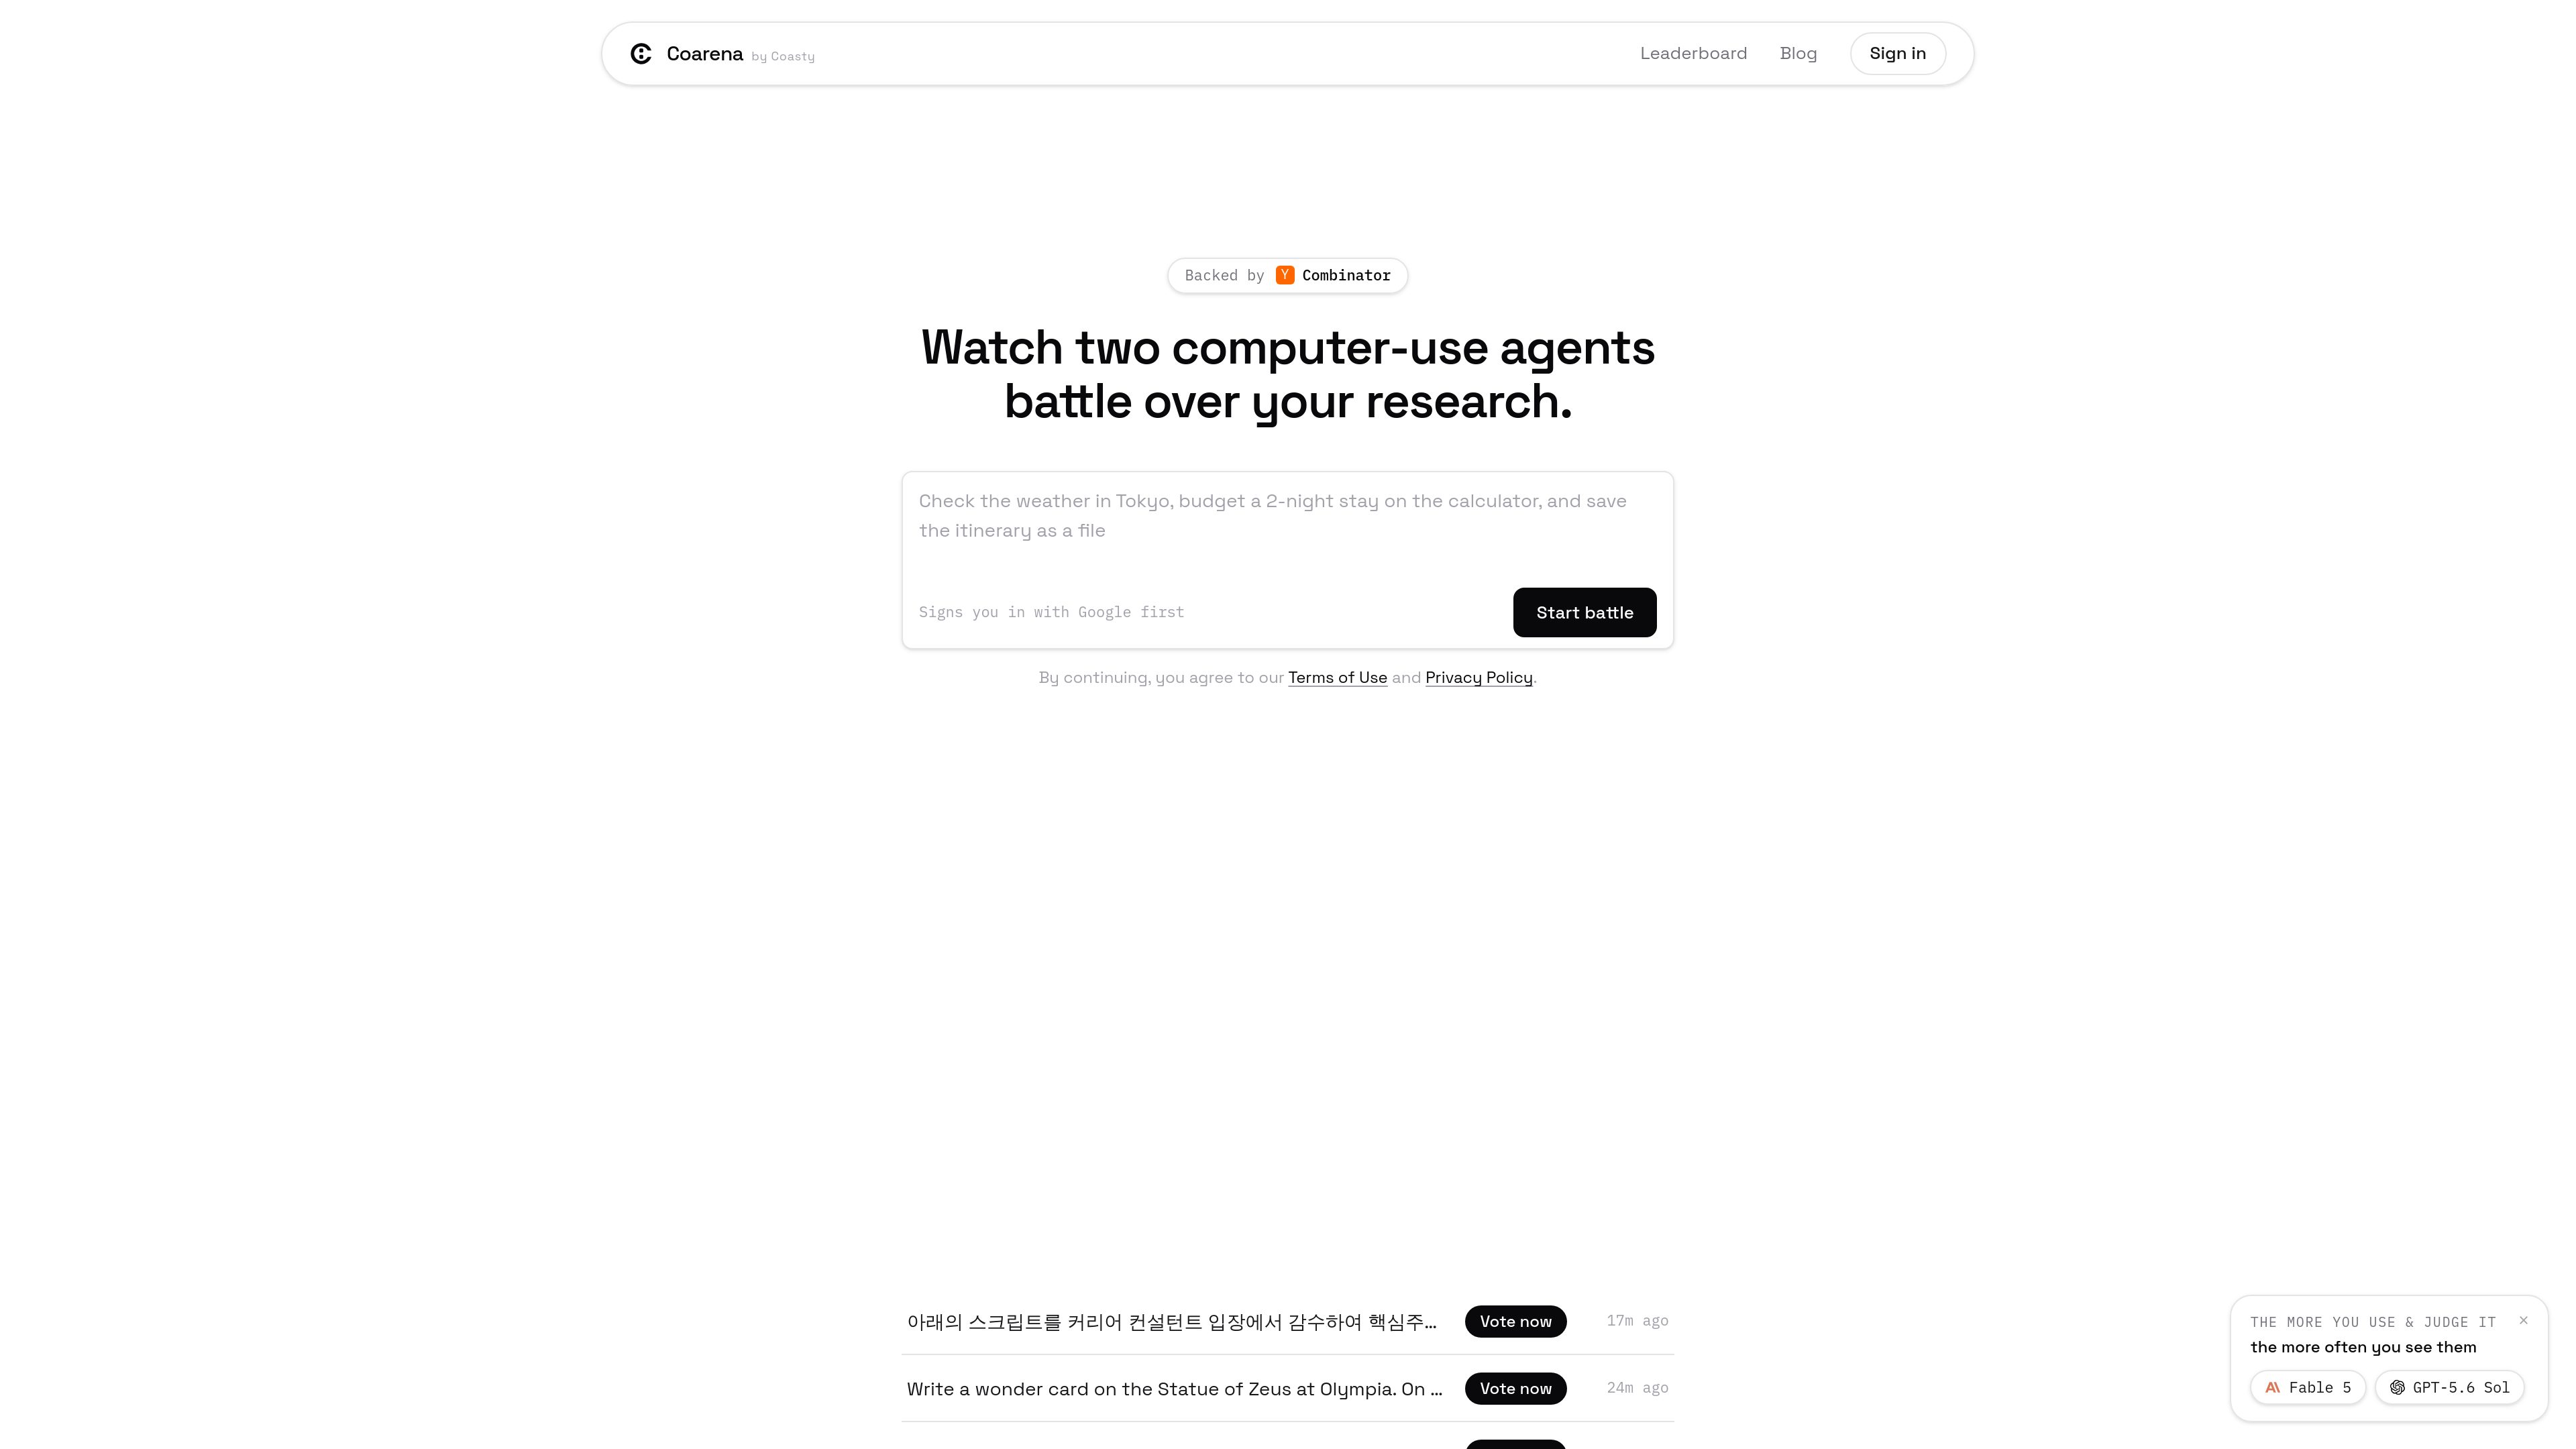
Live head-to-head browser tasks
Users can start a battle on a real computer-use task and compare two agents on the same objective.

Coarena es un arena de uso informático donde puedes publicar tareas reales de navegador, ver en directo cómo dos agentes de IA de vanguardia intentan resolverlas y juzgar a ciegas quién gana. También ofrece métricas de referencia, etiquetas de preferencias y acceso a conjuntos de datos para evaluar el uso informático.
Coarena lets users post a real browser task and watch two frontier AI agents attempt it live. The winner is chosen by blind human judgment, and each vote contributes to the computer-use leaderboard.
The product also extends beyond the arena format. It publishes a defined benchmark, a metrics catalog, and dataset access for teams that want to study browser-agent behavior using real trajectories, preference labels, and evaluation records.
Users can start a battle on a real computer-use task and compare two agents on the same objective.
Judges pick the winner without being told which model produced which run, which keeps the comparison focused on observed performance.
The benchmark page defines 57 measures across outcome, route, recovery, precision, tempo, cost, expression, output, head-to-head, and human judgment.
Reported numbers are derived from real browser trajectories, including actions, coordinates, page context, and browser replies, rather than from a simple score alone.
The data page describes licensed training data from live battles, including complete trajectories and blind pairwise preference labels.
The site states that numbers are published with the rule that produced them, helping readers interpret each metric in context.
Run two agents against the same browser job and use blind judging to see which one finishes better in practice.
Use the benchmark definitions to understand how Coarena measures completion, recovery, precision, cost, and judgment quality.
Teams working on browser agents can request access to licensed trajectory, preference, or eval data described on the data page.
Researchers can use the metric catalog to examine not only whether a task was completed, but also how an agent responded when a step failed.
Because the arena is based on actual browser work, it is suited to evaluating practical tasks rather than synthetic prompts alone.
The arena uses blind human judgment. Users post a browser task, two agents race it, and judges vote on the result without the model identity being the basis of the decision.
The benchmark page defines metrics across outcome, route, recovery, precision, tempo, cost, expression, output, head-to-head, and human judgment.
Yes. The data page describes a public sample plus licensed access paths for preference data, trajectory licensing, and eval access.
No. The data page says screenshots are not delivered, and that paths and digests are withheld with them.
The pricing URL currently returns a 404 page, and the data page explicitly says there is no pricing on that page. Public pricing details were not evidenced in the supplied sources.
Los datos de tráfico son solo como referencia.
| may | 0 |
|---|---|
| jun | 0 |
| jul | 0 |
Las analíticas de tráfico aún no están disponibles.
Las analíticas de tráfico aún no están disponibles.

developers.cloudflare.com
Kitesurf es el navegador sin estado de Cloudflare para agentes de IA y flujos de trabajo automatizados. Diseñado para ejecutarse en Workers, renderiza páginas, captura pantallas y extrae HTML con menos CPU y memoria que Chromium en tareas habituales de agentes.

nunu.ai
Plataforma de agentes de IA para automatizar pruebas de juegos y flujos de control de calidad mediante tareas de extremo a extremo en dispositivos reales, con paneles e informes para revisar los resultados.

ragas.io
Marco de código abierto para probar y evaluar aplicaciones de LLM, generar datos sintéticos de evaluación, medir su calidad y supervisar su comportamiento en producción.

fetchsandbox.com
FetchSandbox es una herramienta para probar integraciones de API, webhooks y flujos de trabajo con estado desde entornos de programación con IA. Permite a desarrolladores y agentes validar integraciones sin usar claves API reales ni consumir la cuota de producción.

plurai.ai
Plurai es una plataforma de confianza para agentes de IA que permite simular, evaluar y aplicar medidas de protección, para probar agentes en producción, supervisar su comportamiento y protegerlos en tiempo real antes y después del despliegue.
noveum.ai
Plataforma de pruebas de preproducción para agentes de IA que simula usuarios en llamadas SIP reales, audio de LiveKit y chat para ensayar conversaciones, detectar fallos y validar correcciones antes del lanzamiento.