
Structured page extraction
Extract meaningful entities and content from individual web pages without writing site-specific rules. Results can be returned as Markdown or full JSON.

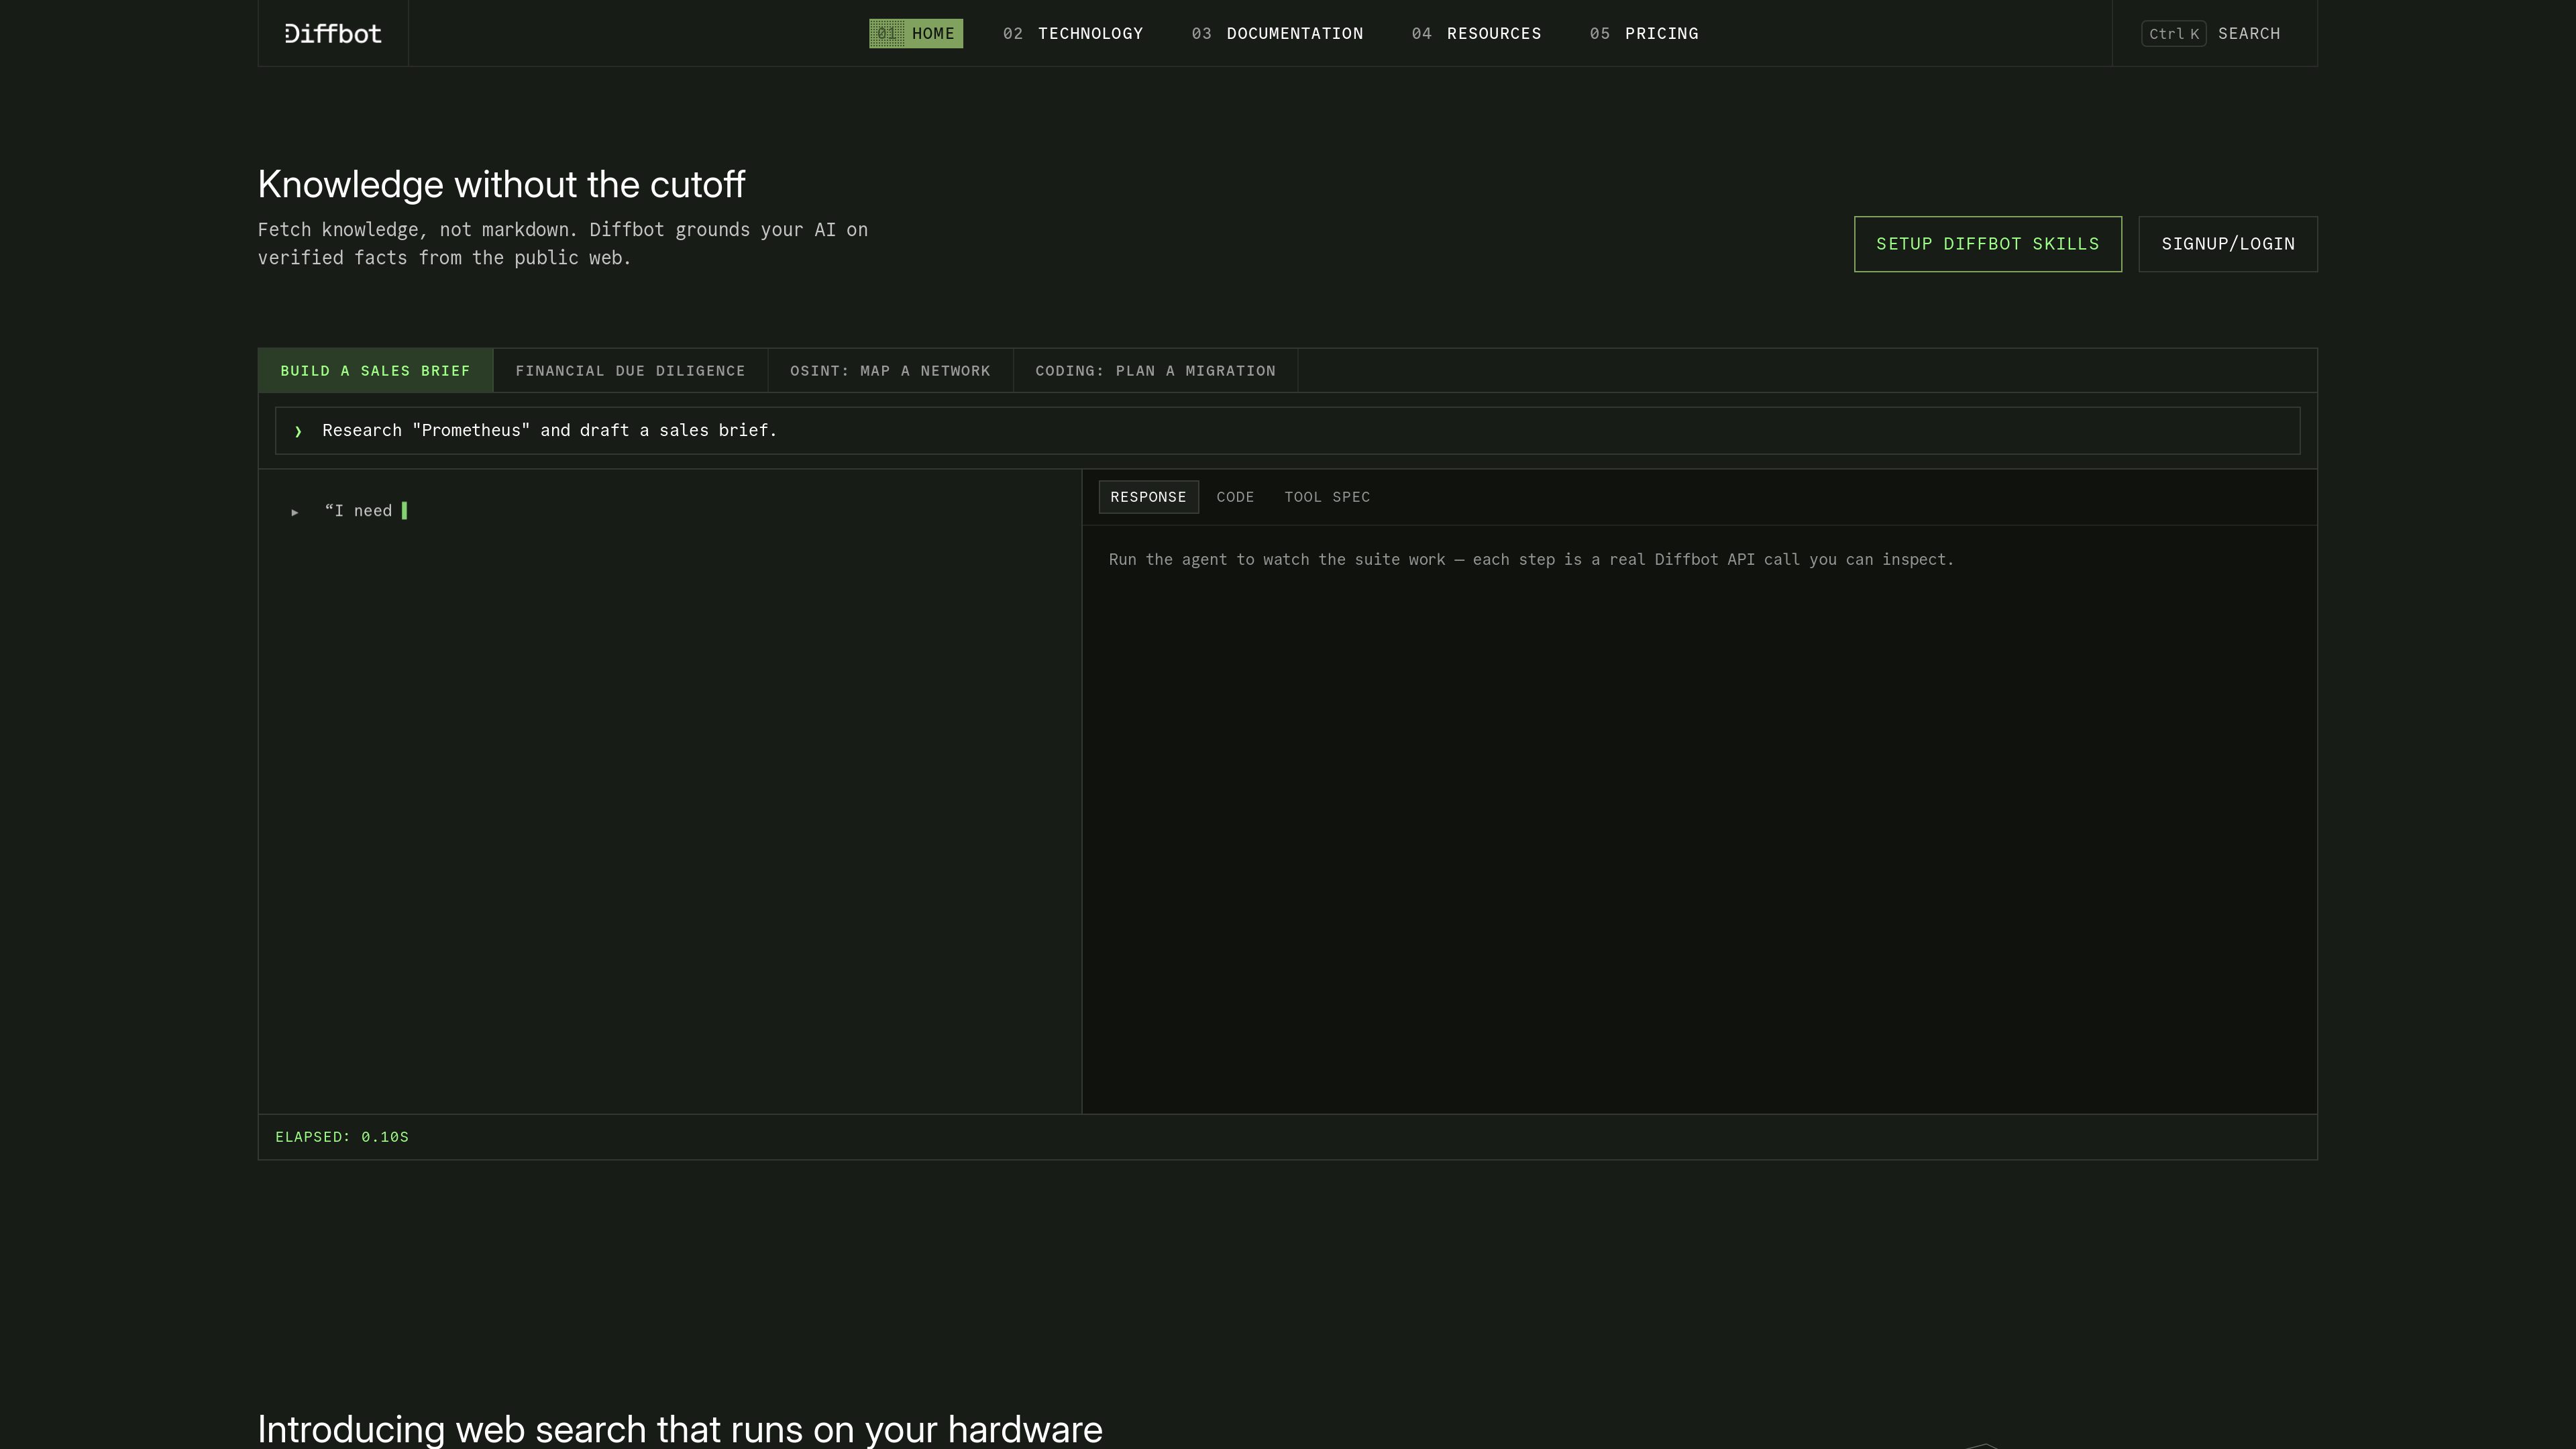
Diffbot transforms unstructured public web content into structured data for AI applications. Its APIs and agent skills support web search, page extraction, crawling, entity resolution, natural-language processing, and Knowledge Graph research.
Diffbot is a web data and knowledge platform that reads unstructured public web content and converts it into structured, linked information. Its core APIs cover page extraction, site crawling, Knowledge Graph querying and export, data enhancement, natural-language processing, and web search. The resulting data is intended for AI applications, research workflows, and systems that need facts from the public web rather than raw pages or flat scraped records.
Developers can call Diffbot APIs directly or install Diffbot Skills in a supported agent harness. The skills expose agent-facing workflows for web search, structured extraction, crawling, entity resolution, and Knowledge Graph research.
Extract meaningful entities and content from individual web pages without writing site-specific rules. Results can be returned as Markdown or full JSON.
Query linked records covering organizations, people, news, places, deals, and other entity types. Knowledge Graph data can be explored through agent skills or raw DQL queries and exported as typed JSON or CSV.
Web Search combines an indexed web corpus with retrieval, ranking, and content chunking. Results include ranked URLs, relevance scores, dates, and snippets, and the API is available through GET and POST requests.
Crawl websites for links and structured pages, manage crawler jobs, and apply options such as URL-processing patterns and maximum pages to process.
Identify entities in raw text and link them to Diffbot Knowledge Graph records. Entity results can include confidence, salience, sentiment, and Diffbot IDs.
Connect Diffbot capabilities to agent harnesses including Claude Code, GitHub Copilot, Snowflake Cortex, Factory.ai Droid, ForgeCode, and pi.dev, with a universal npx-based option also documented.
Use Knowledge Graph searches for organizations, people, news, funding, acquisitions, and industry criteria when assembling company or market research.
Give an agent live web results or extracted page content so research tasks can use structured public-web evidence rather than relying only on model knowledge.
Use Web Search through an API or investigate self-hosting when a team wants search infrastructure on its own network; the site describes the product as self-host-ready.
Crawl sites and extract structured pages to build datasets or knowledge graphs from documentation, product pages, and other public web sources.
Process text such as reports or announcements to identify people, organizations, and other entities, then connect those mentions to records usable in downstream analysis.
Developers can authenticate with a Diffbot token and call the documented APIs, or install Diffbot Skills in a supported agent harness. Web Search is available through GET and POST API endpoints.
Skills expose agent workflows for Knowledge Graph searches, live web search, page extraction, entity resolution, and site crawling. They include commands for news, organizations, people, places, deals, and raw DQL queries.
The Extract workflow returns structured page content as Markdown by default and can return full JSON. Knowledge Graph data can be exported as typed JSON or CSV, while Web Search returns ranked results with URLs, dates, relevance scores, and snippets.
The Web Search product is described as self-host-ready. The site says to contact Diffbot for more information about self-hosting.
Usage is measured in monthly credits. Page extraction and web searches generally consume one credit per operation, while Knowledge Graph entity records and some other operations have different credit costs. The Free plan is available without a credit card, and paid usage can incur plan-specific overage charges.
microsoft.github.io
GraphRAG is a research project and data pipeline for extracting structured information from unstructured text with language models, then using graph-based context to support question answering over private data.

you.com
为网页、新闻和金融工作流提供搜索、内容提取与带引用研究的开发者 API。

www.valyu.ai
Valyu provides search, content extraction, answer, and DeepResearch APIs for AI agents and knowledge-work applications. It combines open-web results with financial, scientific, biomedical, legal, economic, and other specialist sources, returning cited content and research outputs.

vespa.ai
Vespa is an AI search platform for building search, retrieval-augmented generation, recommendation, personalization, and agent applications over text, vectors, tensors, and structured data. It is designed for developer teams that need configurable ranking and distributed operation at production scale.

quantifind.com
纯 SaaS 金融犯罪自动化平台,支持 AML-KYC 筛查、调查与报告。

www.voyageai.com
Voyage AI provides embedding models and rerankers for improving search and retrieval in AI applications. It is designed for teams building retrieval-augmented generation and other applications that use unstructured data.