
Schema-shaped JSON responses
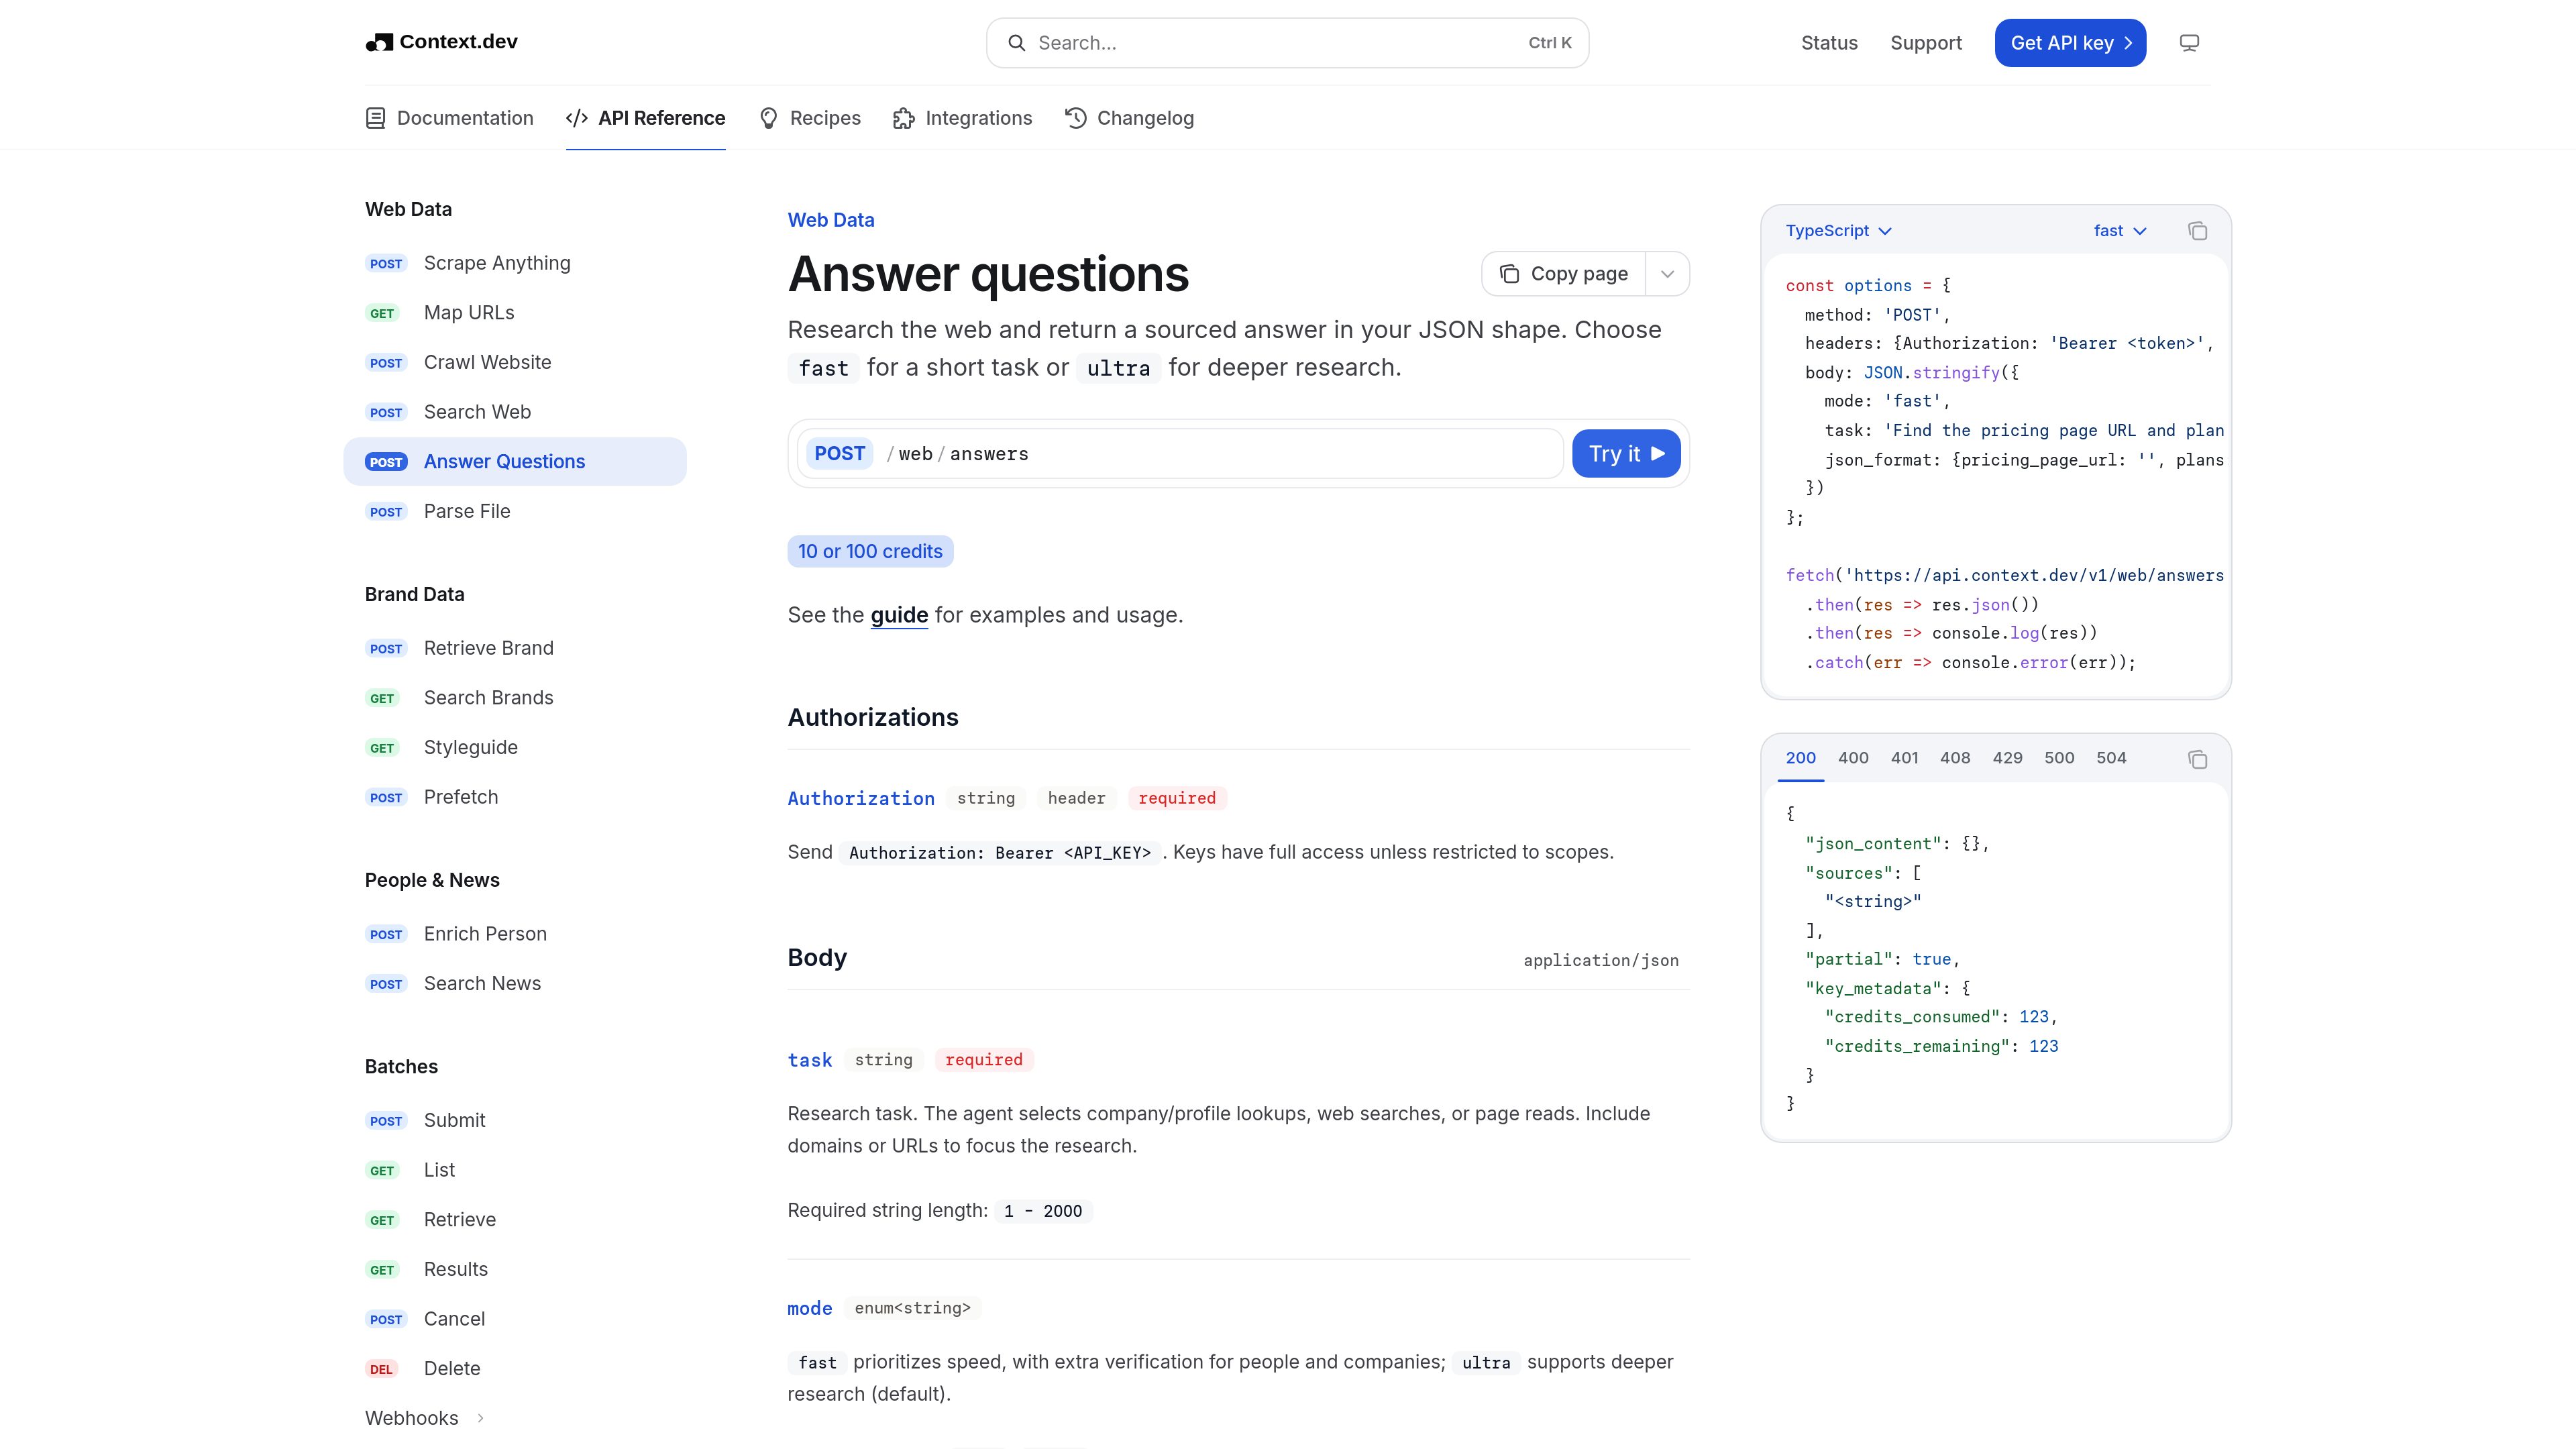
Provide a `json_format` object in the request to describe the fields your application needs. The response places the extracted result in `json_content`.

Context.dev Answers researches the web and returns sourced results in a JSON structure you define. It supports fast responses for shorter tasks and ultra mode for deeper research.
Context.dev Answers is a web research API for applications that need structured, source-backed information. Submit a task and define the desired JSON shape; the endpoint returns JSON content together with the sources used. Requests can use fast mode for shorter tasks or ultra mode for deeper research.
Provide a `json_format` object in the request to describe the fields your application needs. The response places the extracted result in `json_content`.
Each response includes a `sources` array, allowing downstream workflows to retain the web references associated with the returned answer.
Choose `fast` for a short task or `ultra` when the request calls for deeper research, as described in the API documentation.
Call `POST /v1/web/answers` with bearer-token authorization and a JSON request body containing the task, mode, and requested output format.
Responses expose whether the result is partial and include key metadata such as credits consumed and credits remaining.
Ask a defined question about public web content and return the findings in fields that can be stored, displayed, or passed to another service.
Use a schema with fields such as URLs, names, or other attributes to collect comparable information across web research tasks instead of handling unstructured prose.
Pass JSON results and their source list into an internal research, enrichment, or content workflow where traceable web evidence is useful.
A successful response includes `json_content` for the requested result, a `sources` array, a `partial` indicator, and key metadata containing credit usage information.
Include a `json_format` object in the POST request body. The API documentation demonstrates defining fields and arrays with placeholder values to describe the desired JSON shape.
The documentation describes `fast` for short tasks and `ultra` for deeper research.
Context.dev lists Answers from 10 credits per call in its shared API credit table. Plan allowances differ by tier; the pricing page specifically lists Fast-mode quotas for Developer, Pro, Growth, and Scale plans.
Yes. The response contains a `partial` field, and the API documents timeout, rate-limit, authorization, client-error, and server-error responses. Applications should check the response status and partial indicator before using the result.

www.nimbleway.com
Nimble Web Search Agents are self-learning research agents that search and crawl the live web for domain-specific answers, enrichment, and structured datasets. They are designed for teams building repeatable research workflows where the schema, search scope, and output format need to be controlled.

liner.com
提供搜索与问答 API,支持基于网页、学术检索和引用溯源的可信 AI 搜索体验。

www.valyu.ai
Valyu provides search, content extraction, answer, and DeepResearch APIs for AI agents and knowledge-work applications. It combines open-web results with financial, scientific, biomedical, legal, economic, and other specialist sources, returning cited content and research outputs.

vespa.ai
Vespa is an AI search platform for building search, retrieval-augmented generation, recommendation, personalization, and agent applications over text, vectors, tensors, and structured data. It is designed for developer teams that need configurable ranking and distributed operation at production scale.

rayyan.ai
AI 驱动的系统综述与文献综述平台

unriddle.ai
Anara 是一款 AI 研究工作区,可搜索资料库和网页,生成带引用的答案并分析文档。