
2026 Лучшие инструменты: Оценка LLM
Изучайте инструменты, бенчмарки и платформы для оценки LLM: измеряйте качество моделей, сравнивайте ответы, выявляйте риски и улучшайте ИИ-приложения.
Поддерживает Findings24
Инфраструктура ИИ
Исследовать эту коллекциюПродукты


Agnost AI
Наблюдаемость ИИ
Agnost AI monitors AI agents in production by analyzing conversations, traces, user corrections, and frustration. It helps teams identify recurring failures, review suggested prompt fixes, and apply approved changes with replay-based regression coverage.
Бесплатные и платные тарифы



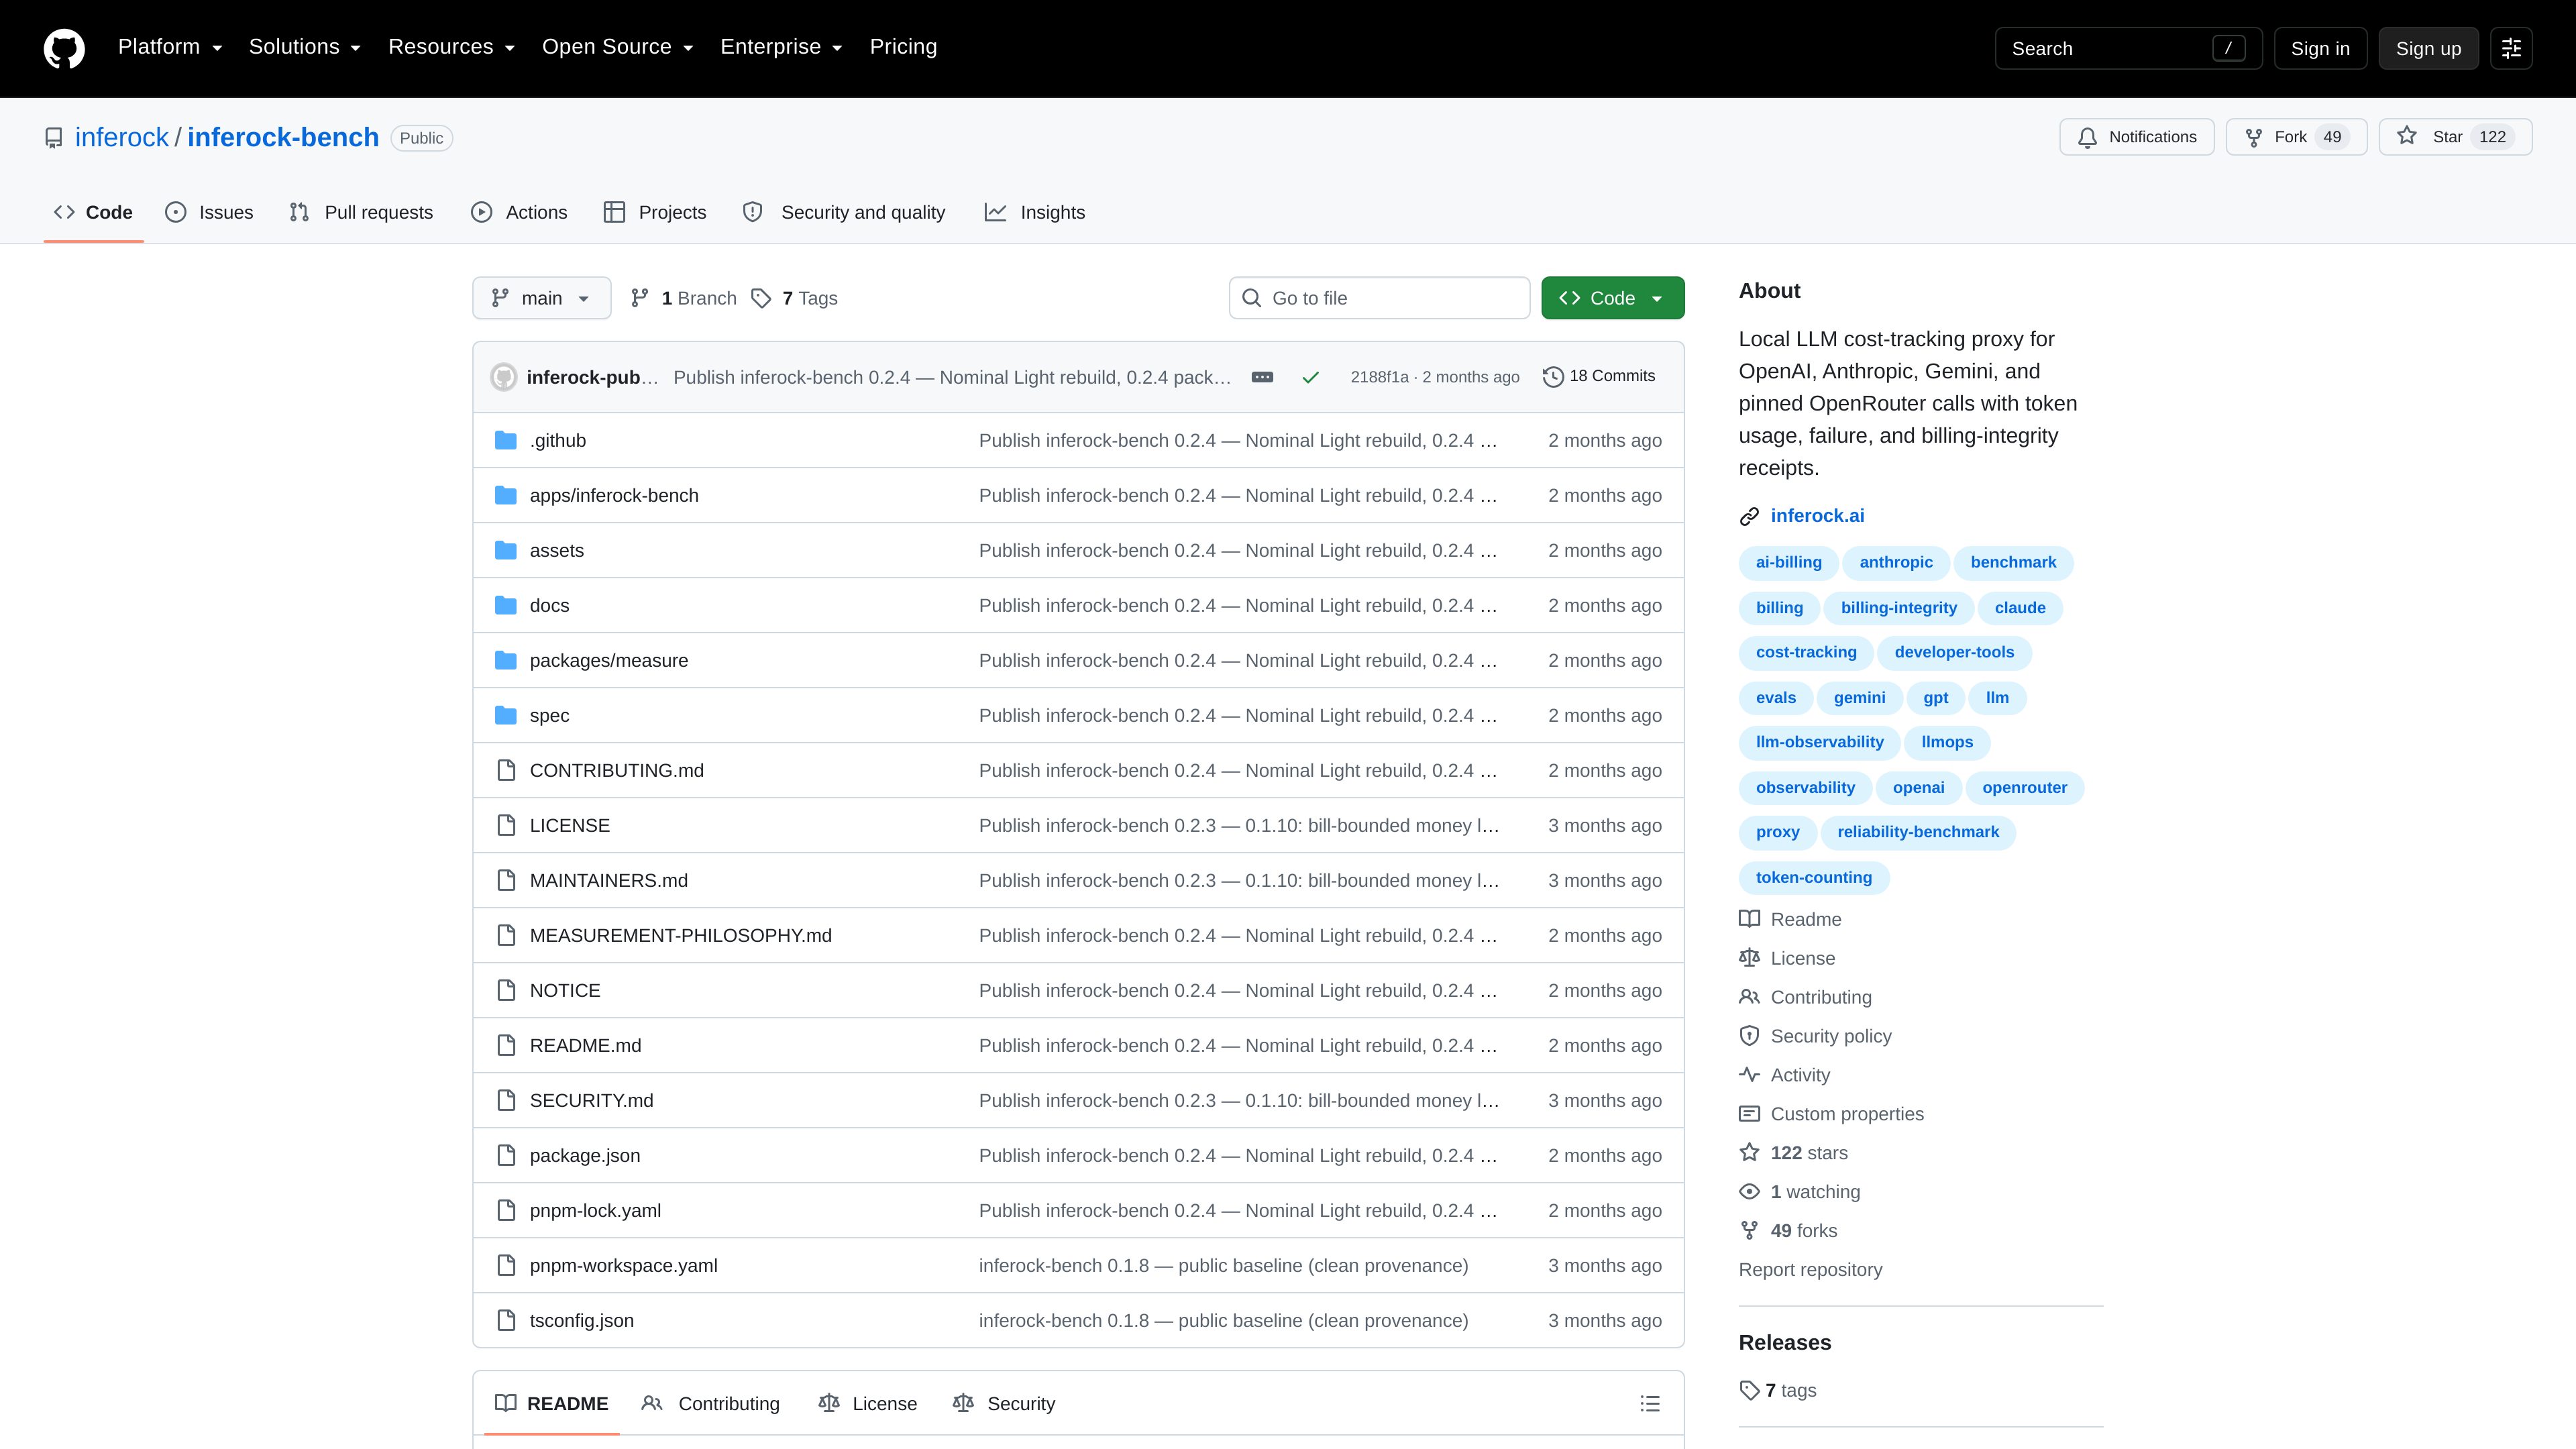
inferock-bench
Шлюзы и маршрутизация ИИ
inferock-bench is a local diagnostic proxy for tracking LLM API usage, provider-reported costs, failures, and billing-integrity signals. It helps developers inspect calls to OpenAI, Anthropic, Gemini Developer API, and pinned OpenRouter endpoints using locally stored receipts.
Бесплатные и платные тарифы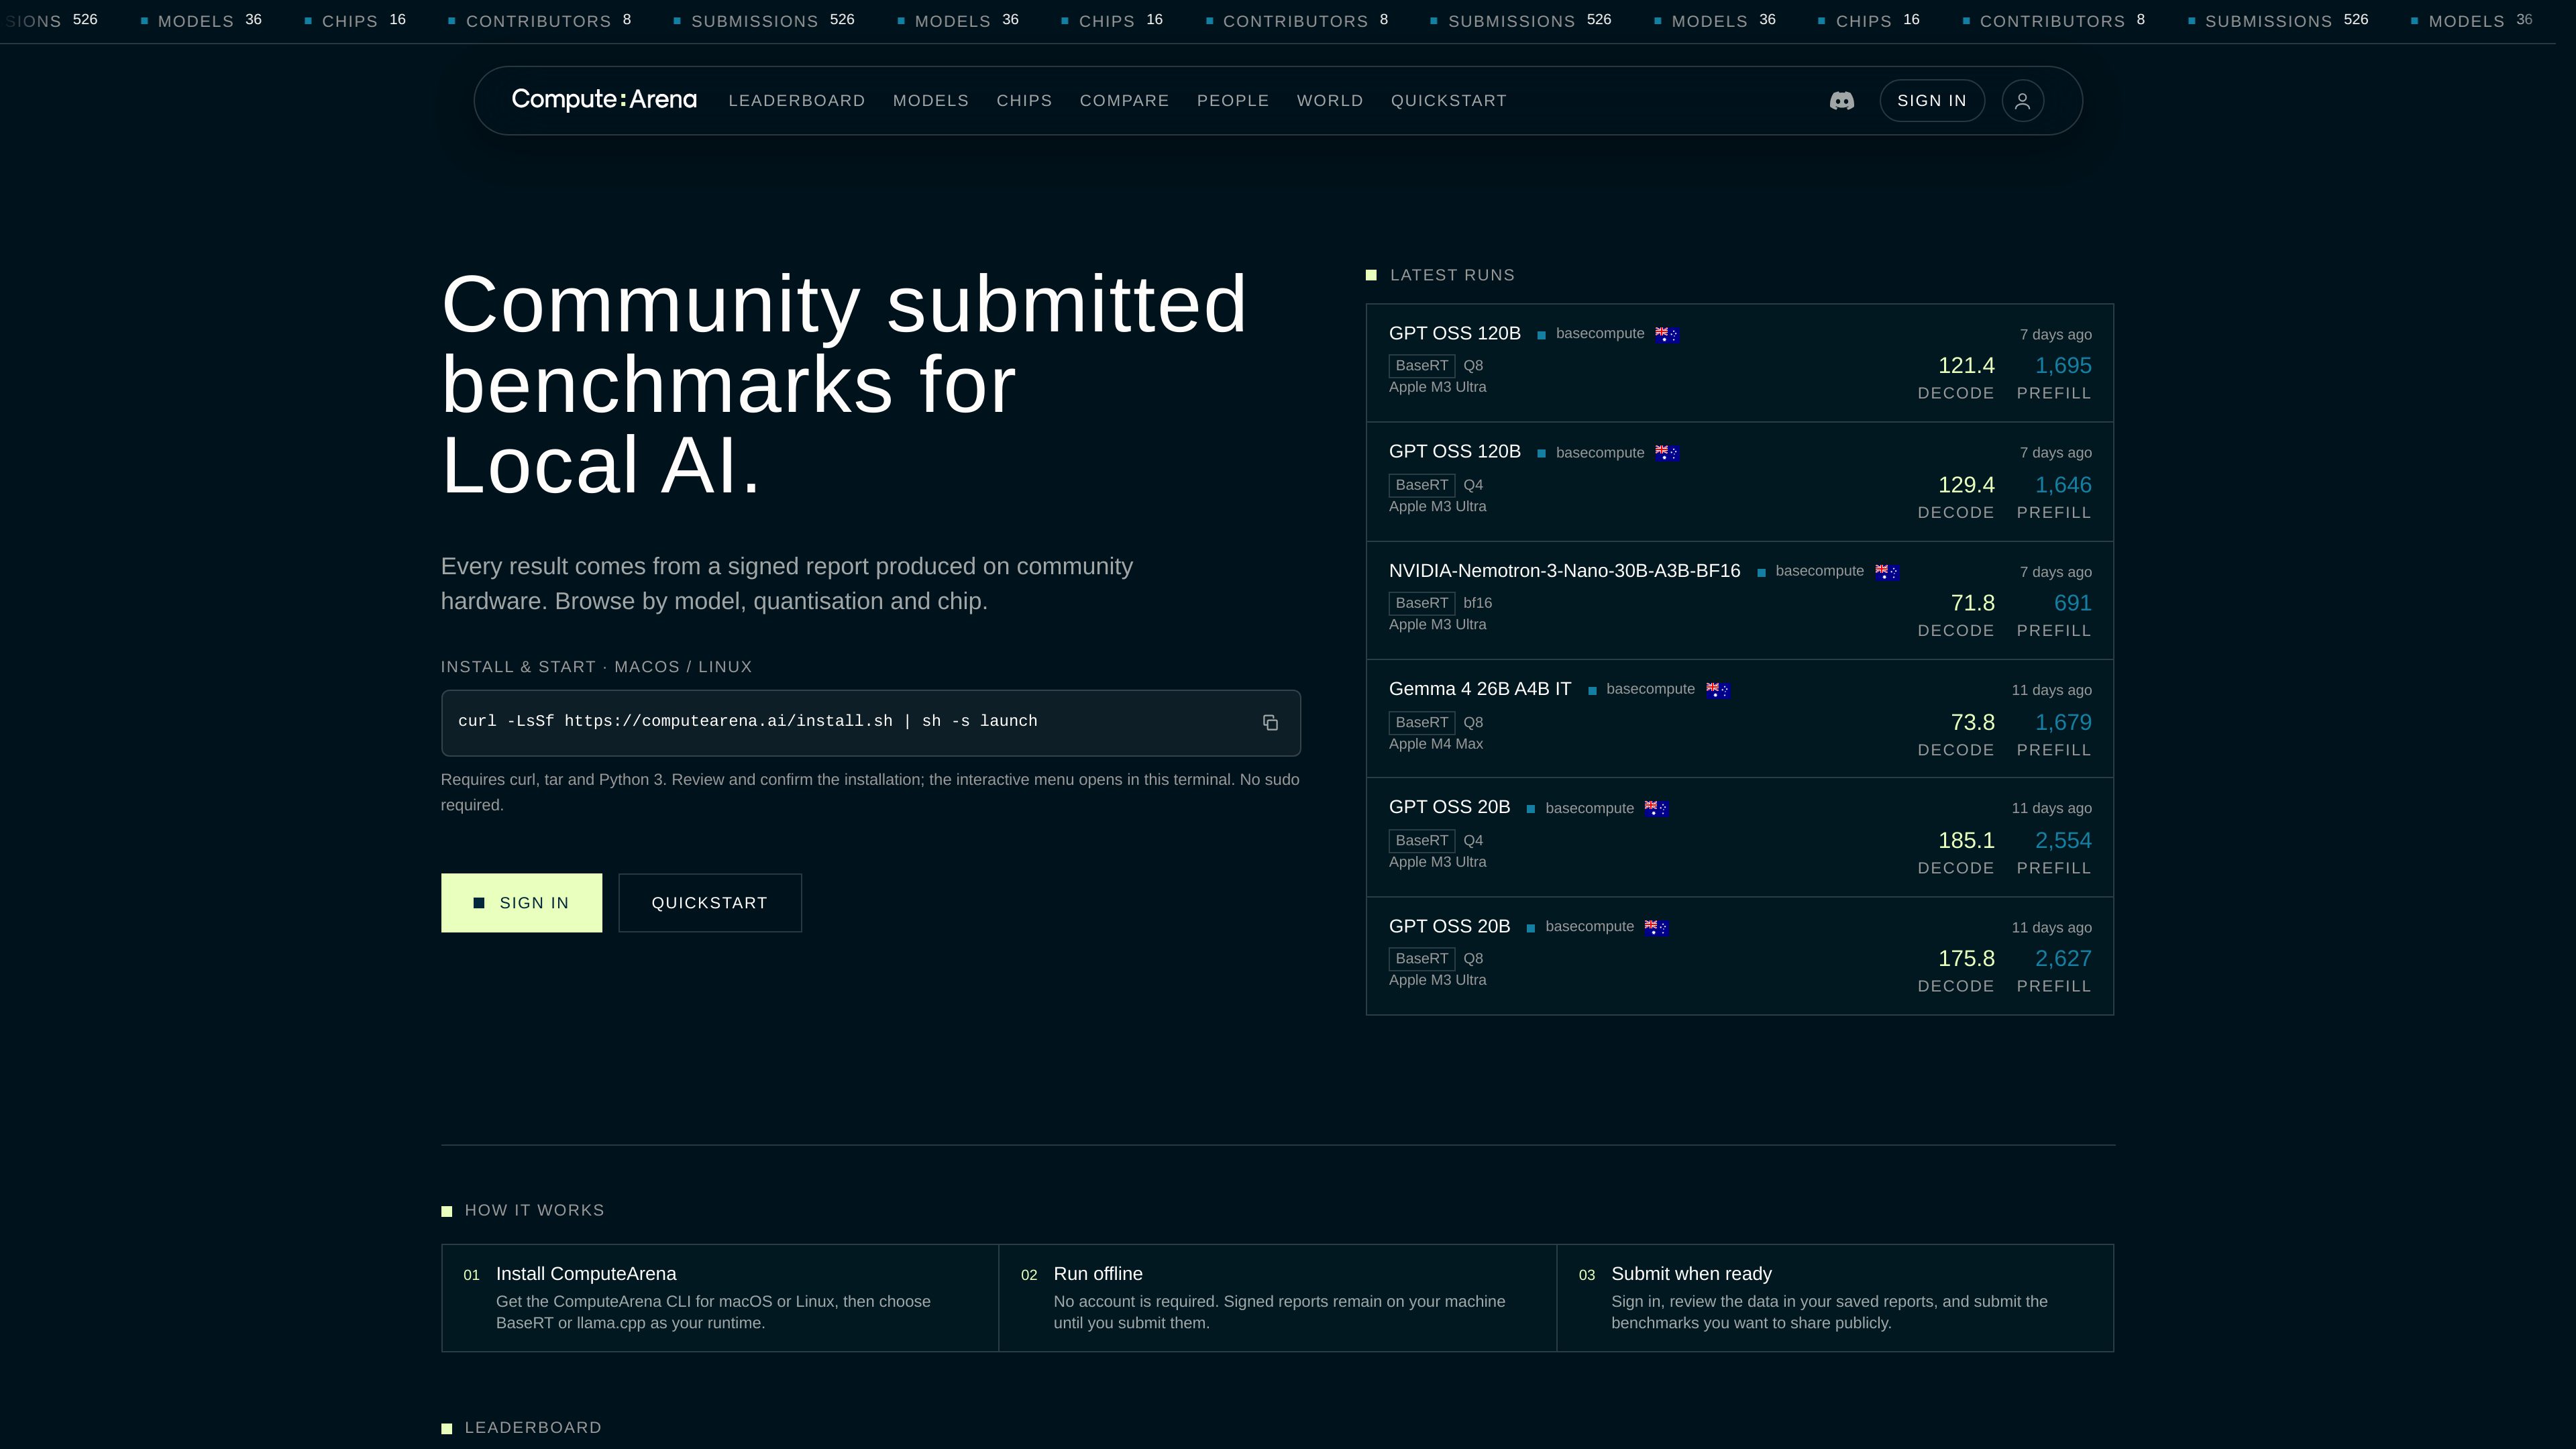
ComputeArena
Оценка LLM
ComputeArena is a community benchmark directory for measuring local AI model throughput across chips, quantisations, and runtimes. It helps developers run offline benchmarks, inspect signed reports, and compare decode and prefill performance on compatible workloads.
Бесплатные и платные тарифы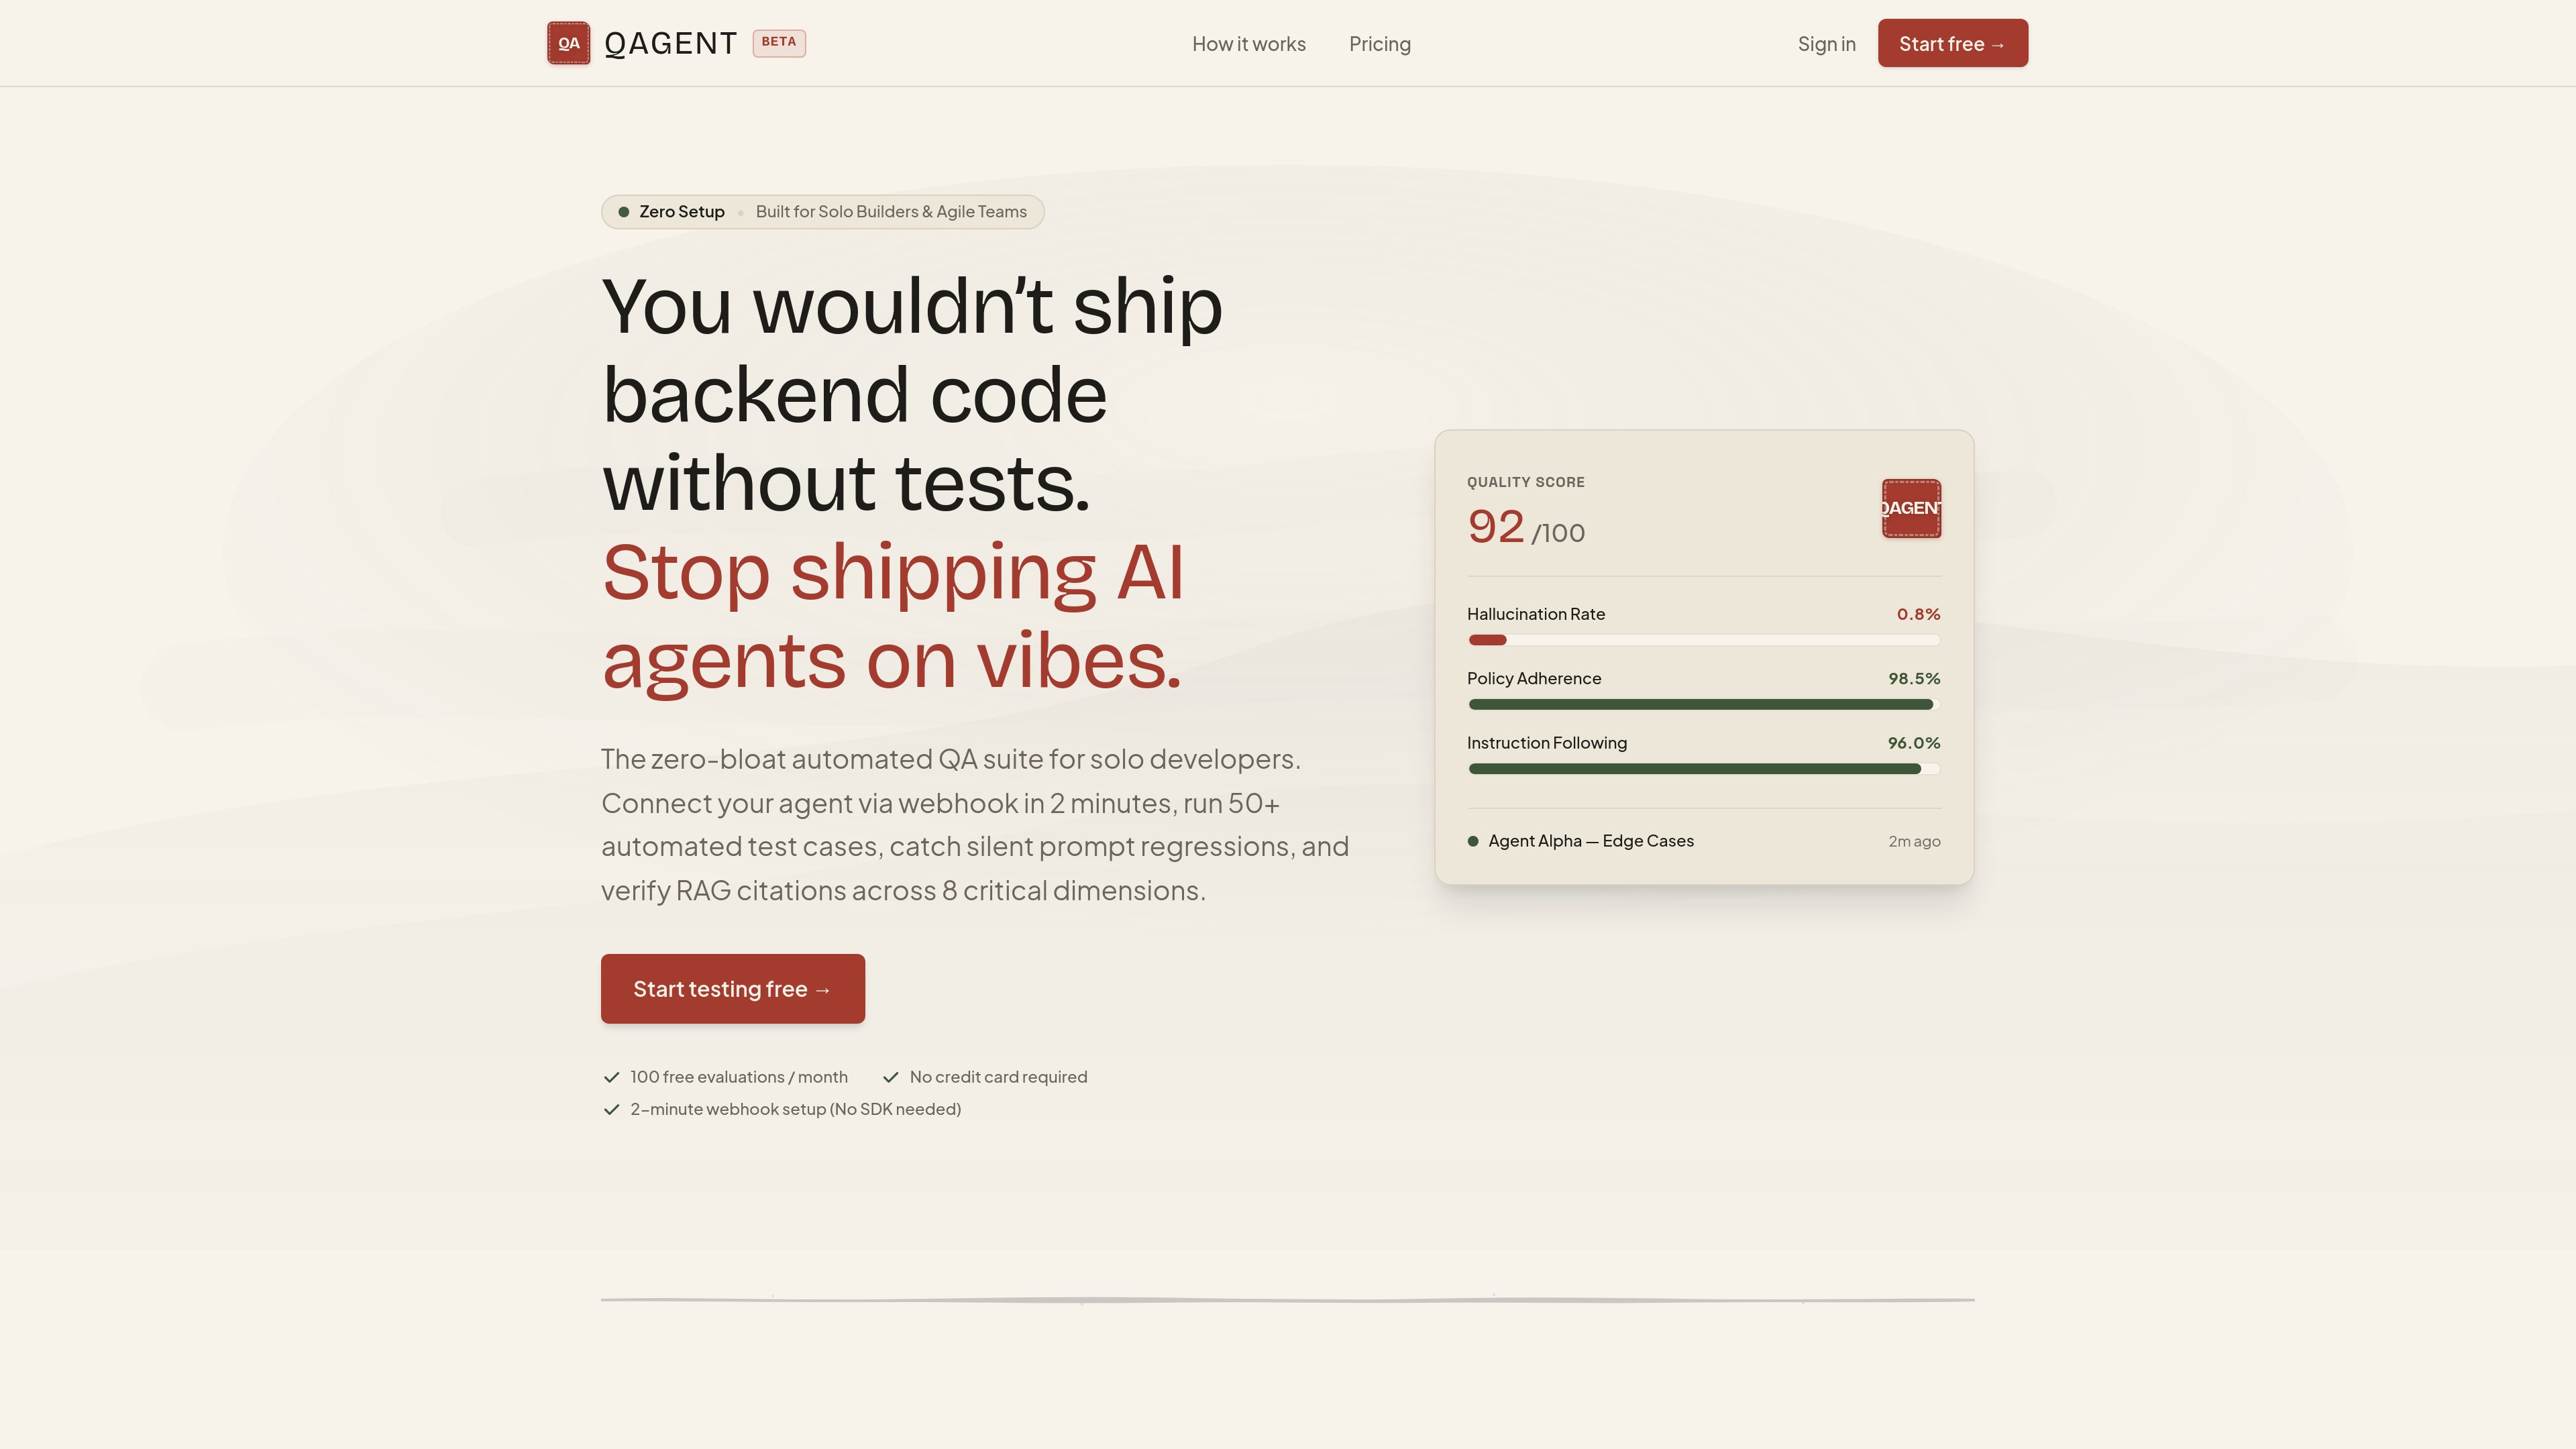

QAgent
ИИ-ассистенты для тестирования
QAgent is an AI agent testing and quality assurance platform for developers and agile teams. It connects to an agent through a webhook or endpoint, runs automated test cases, and evaluates responses for groundedness, policy adherence, prompt compliance, and related quality dimensions.
Бесплатные и платные тарифы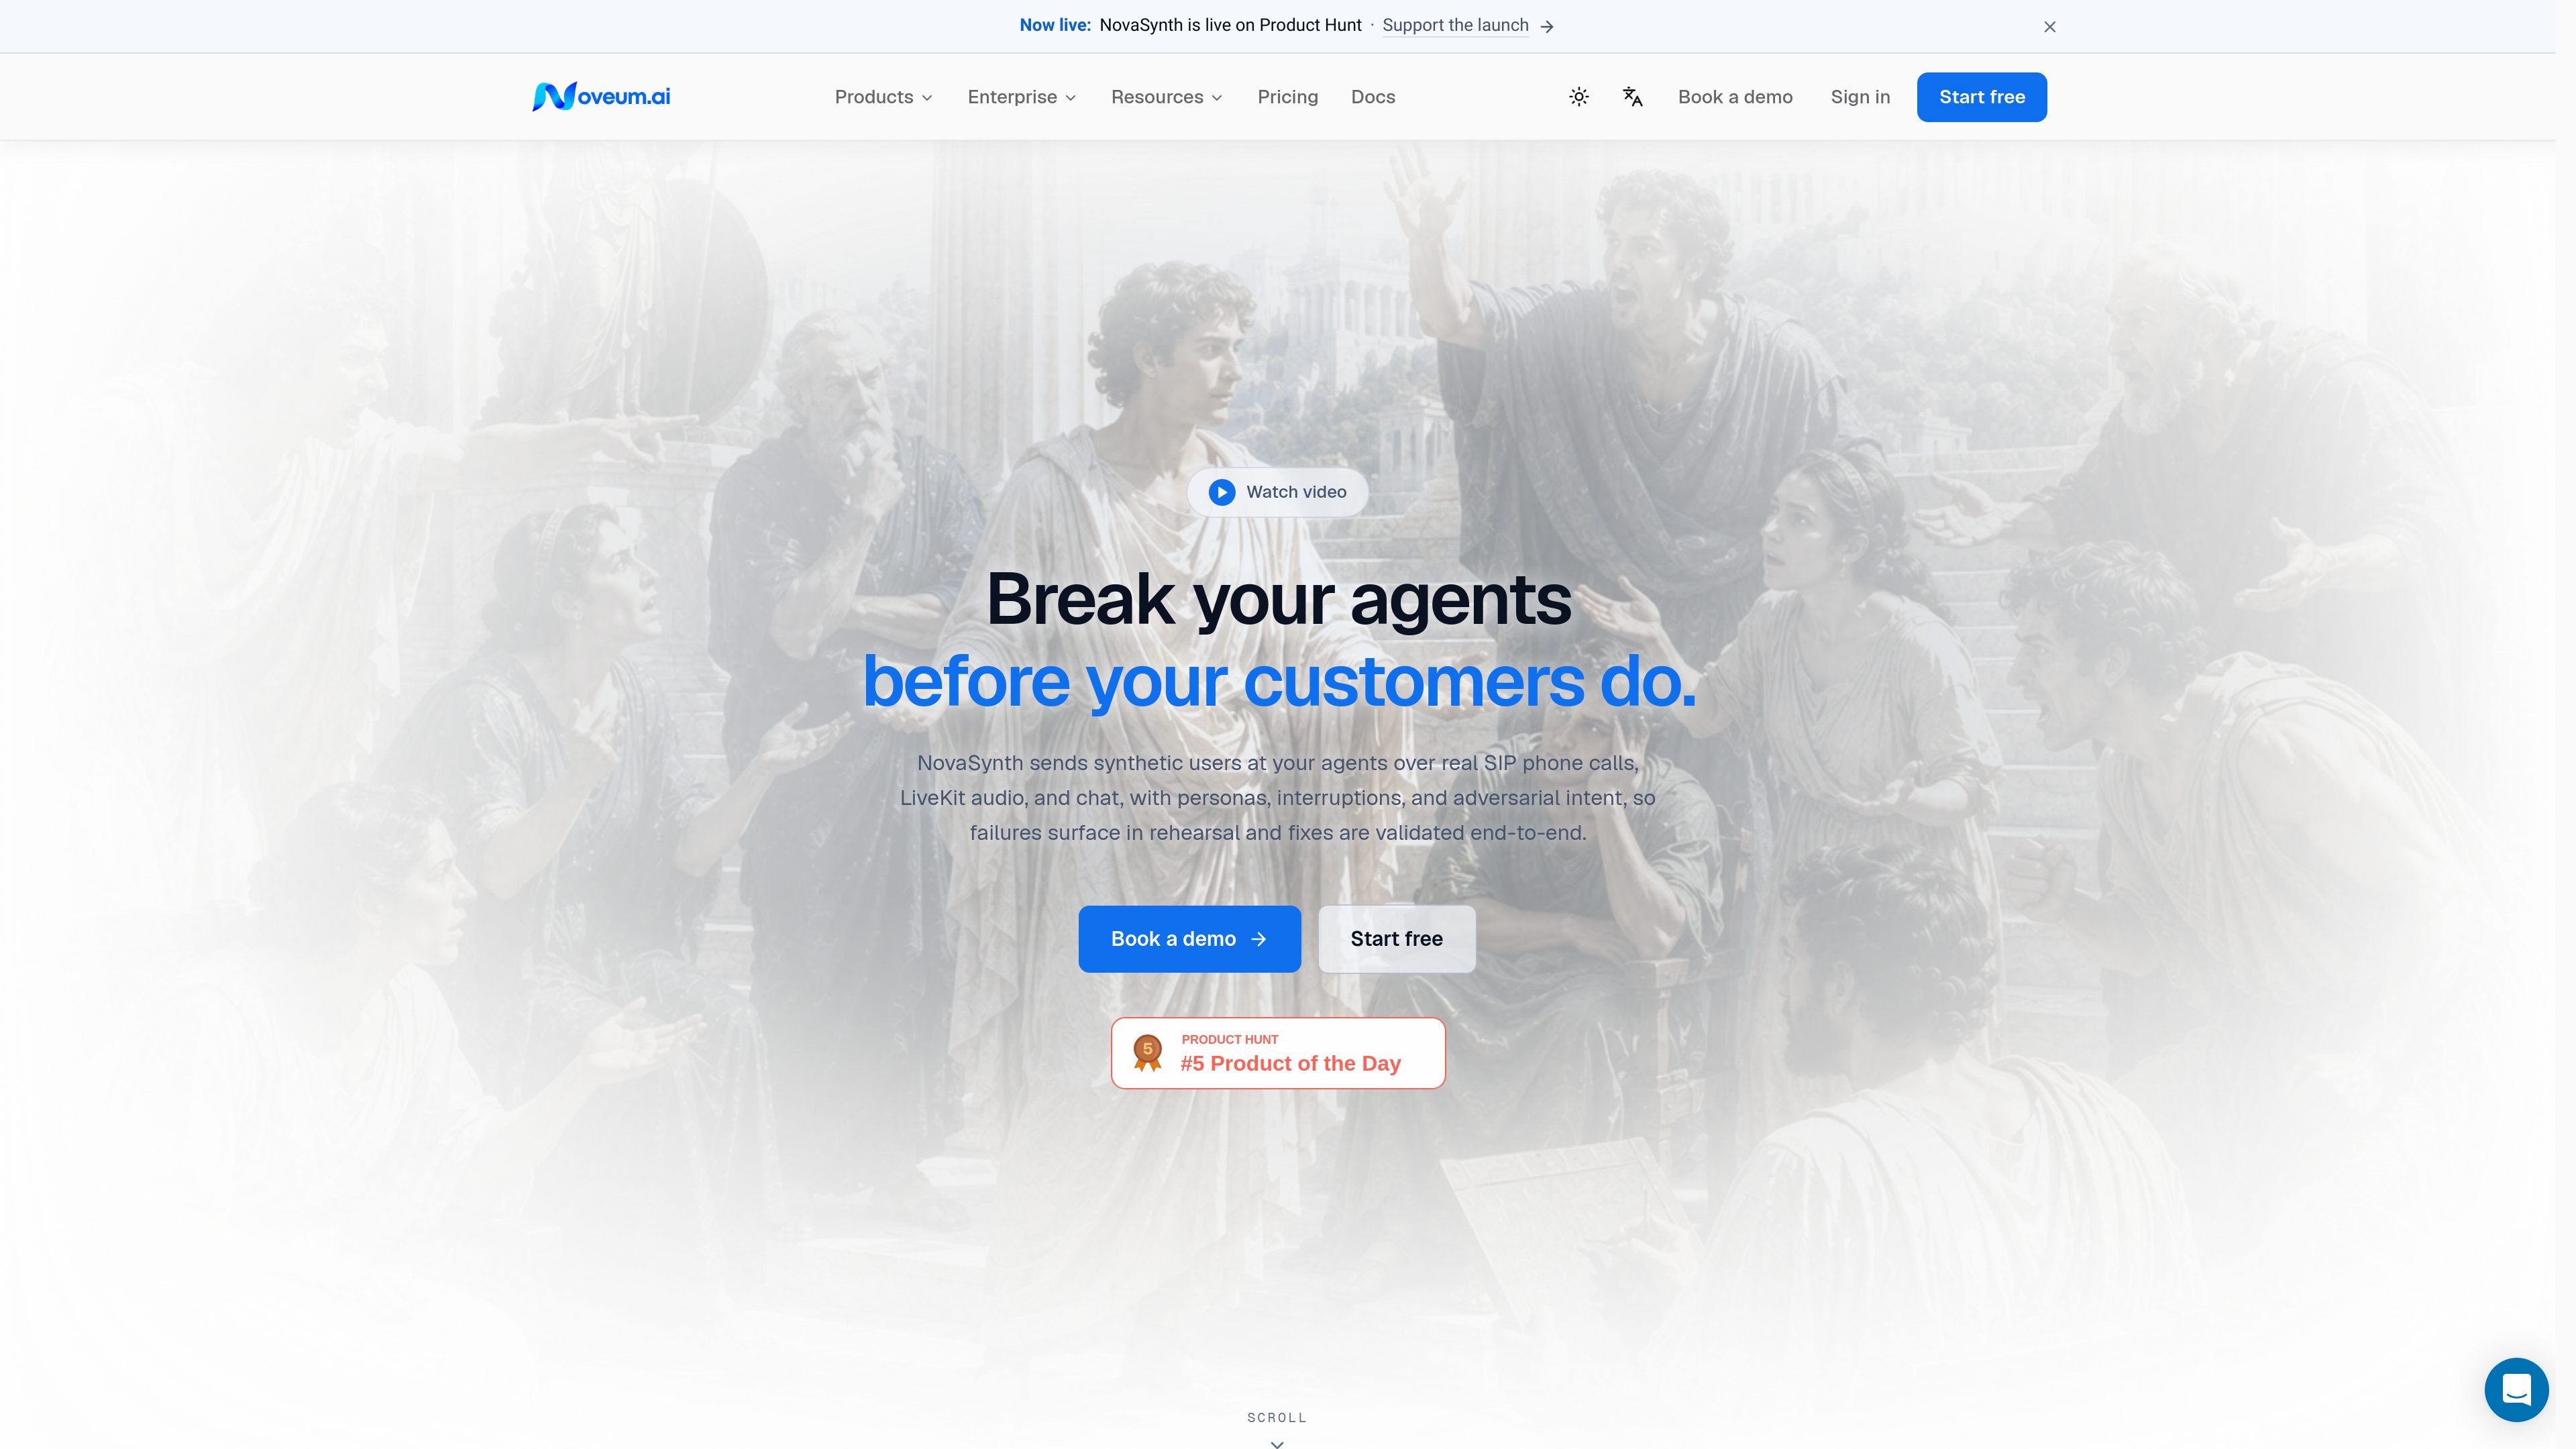
NovaSynth
ИИ-ассистенты для тестирования
NovaSynth is a pre-production testing platform for AI agents that uses synthetic users across real SIP phone calls, LiveKit audio, and chat. It helps teams rehearse multi-turn interactions, surface failures, and validate fixes before releasing agents to customers.
Бесплатные и платные тарифы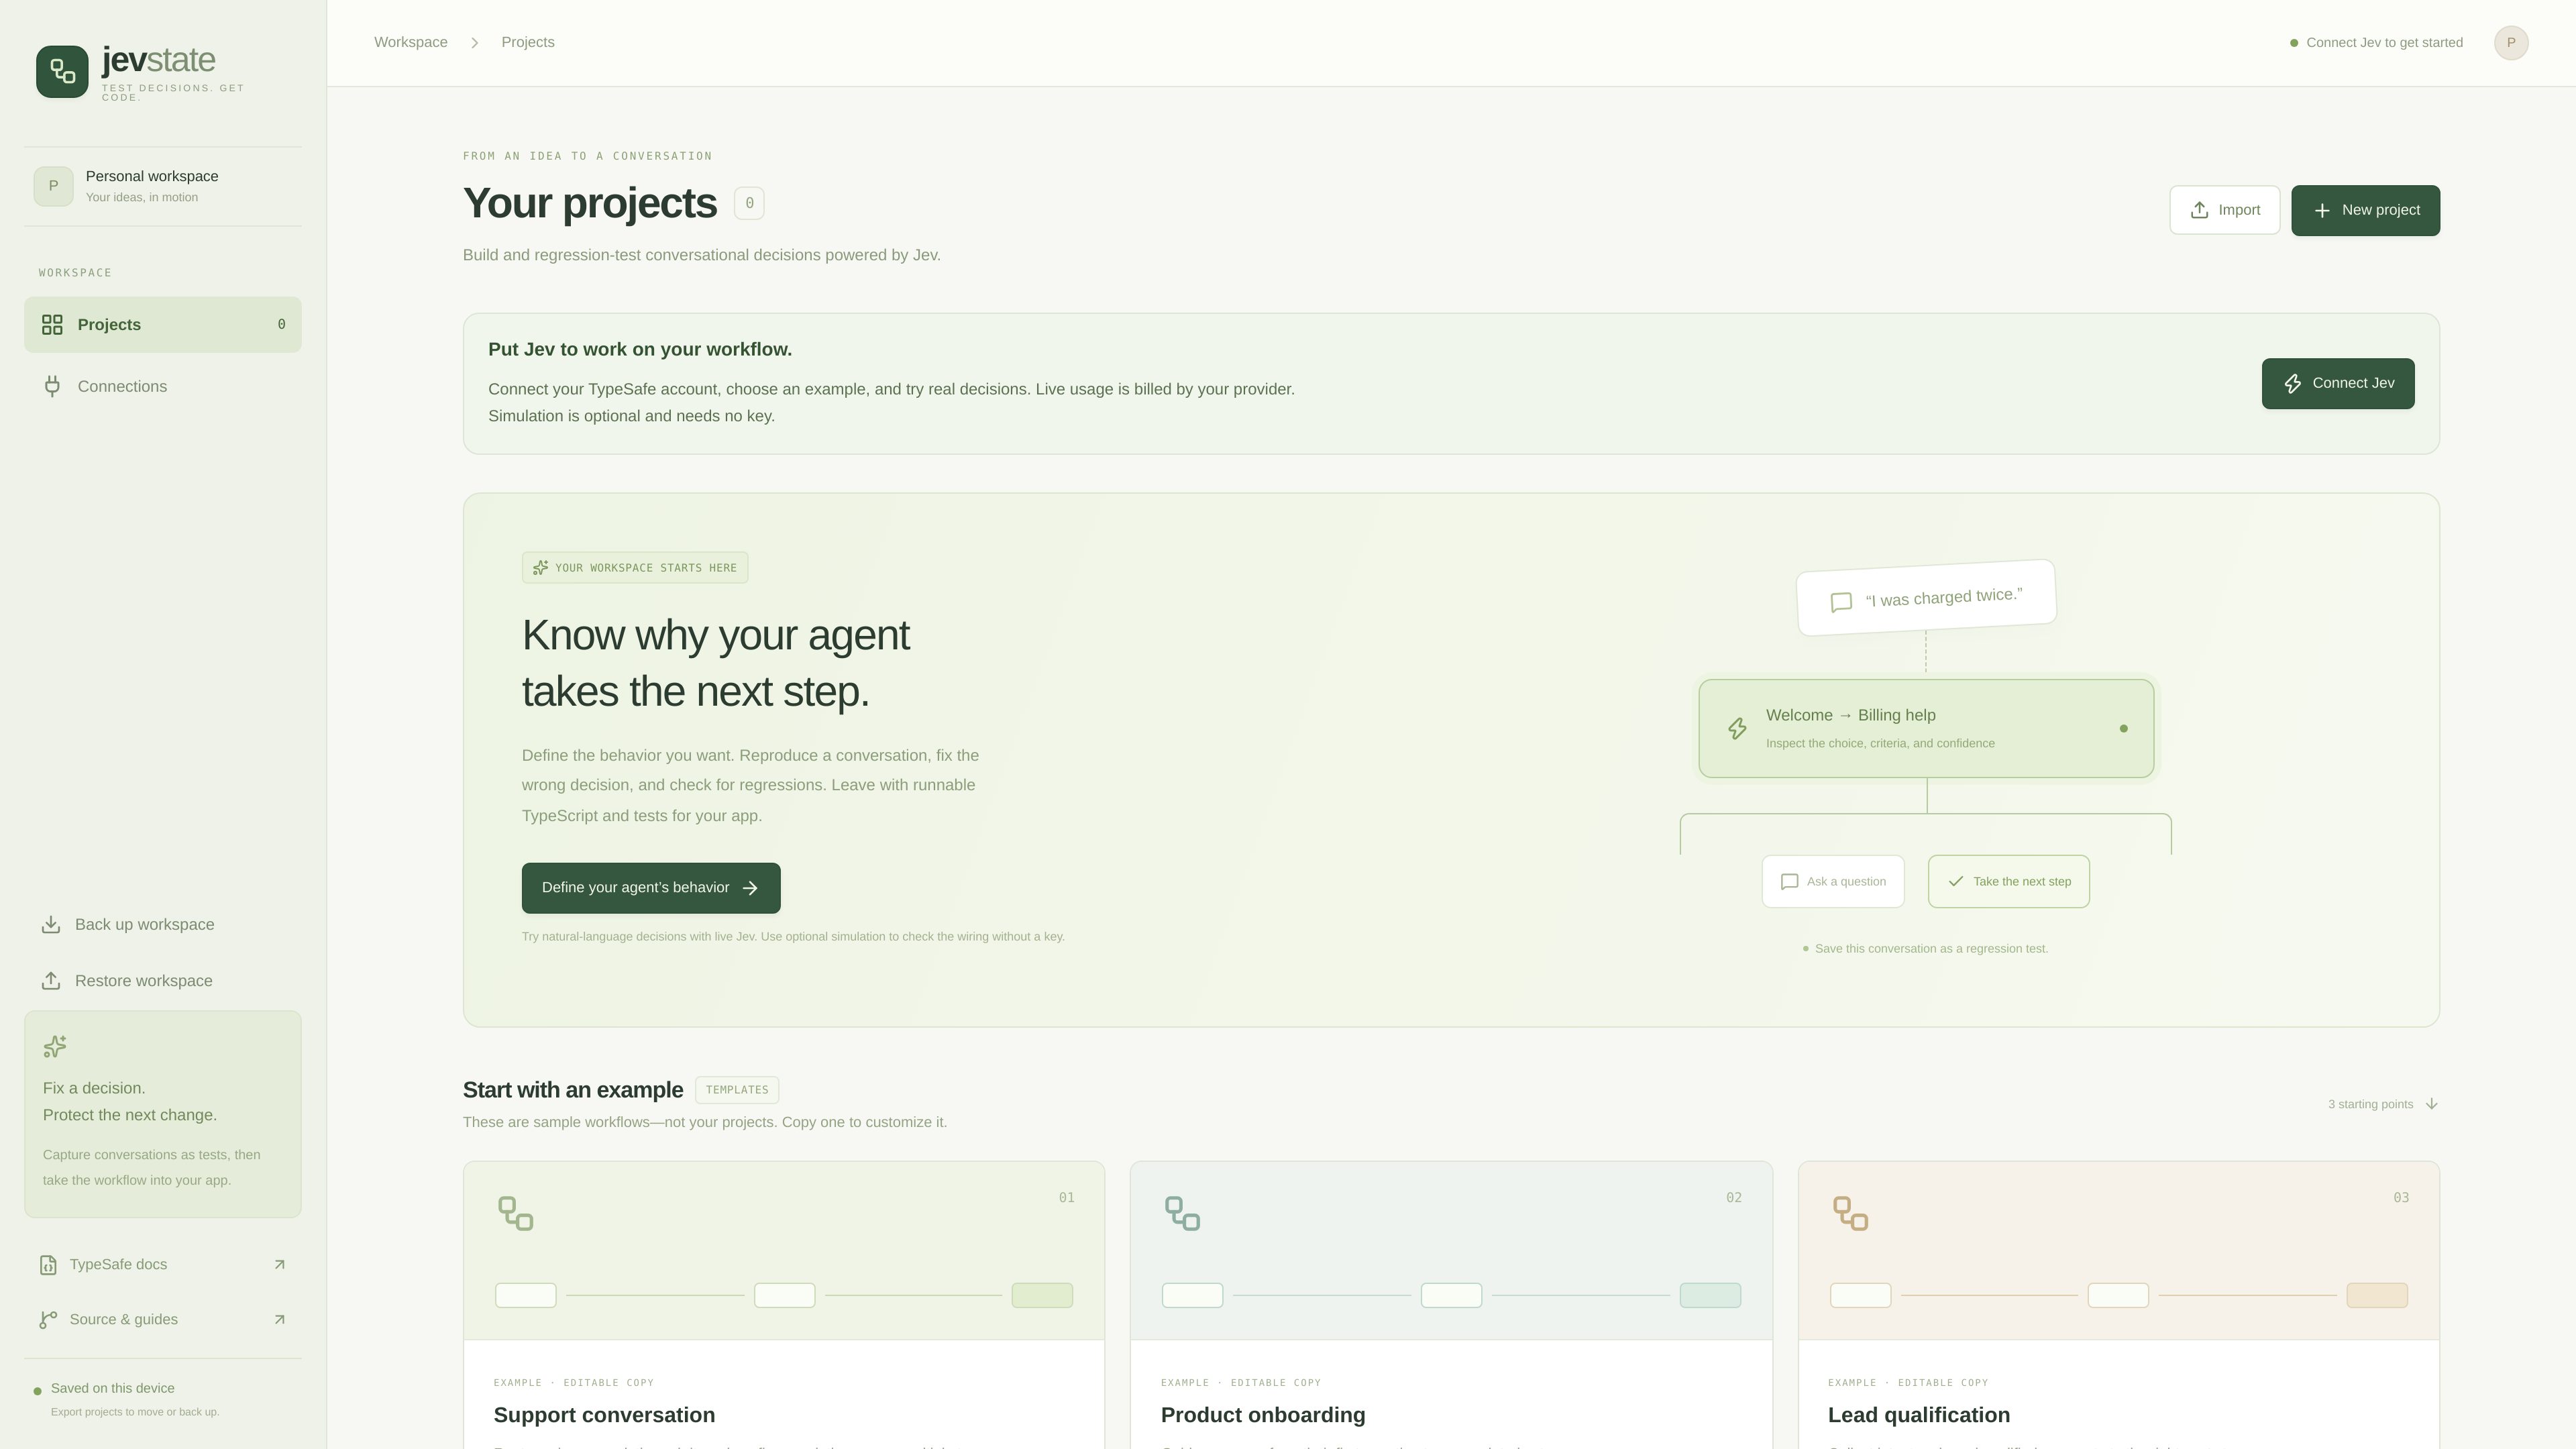

fez
Шлюзы и маршрутизация ИИ
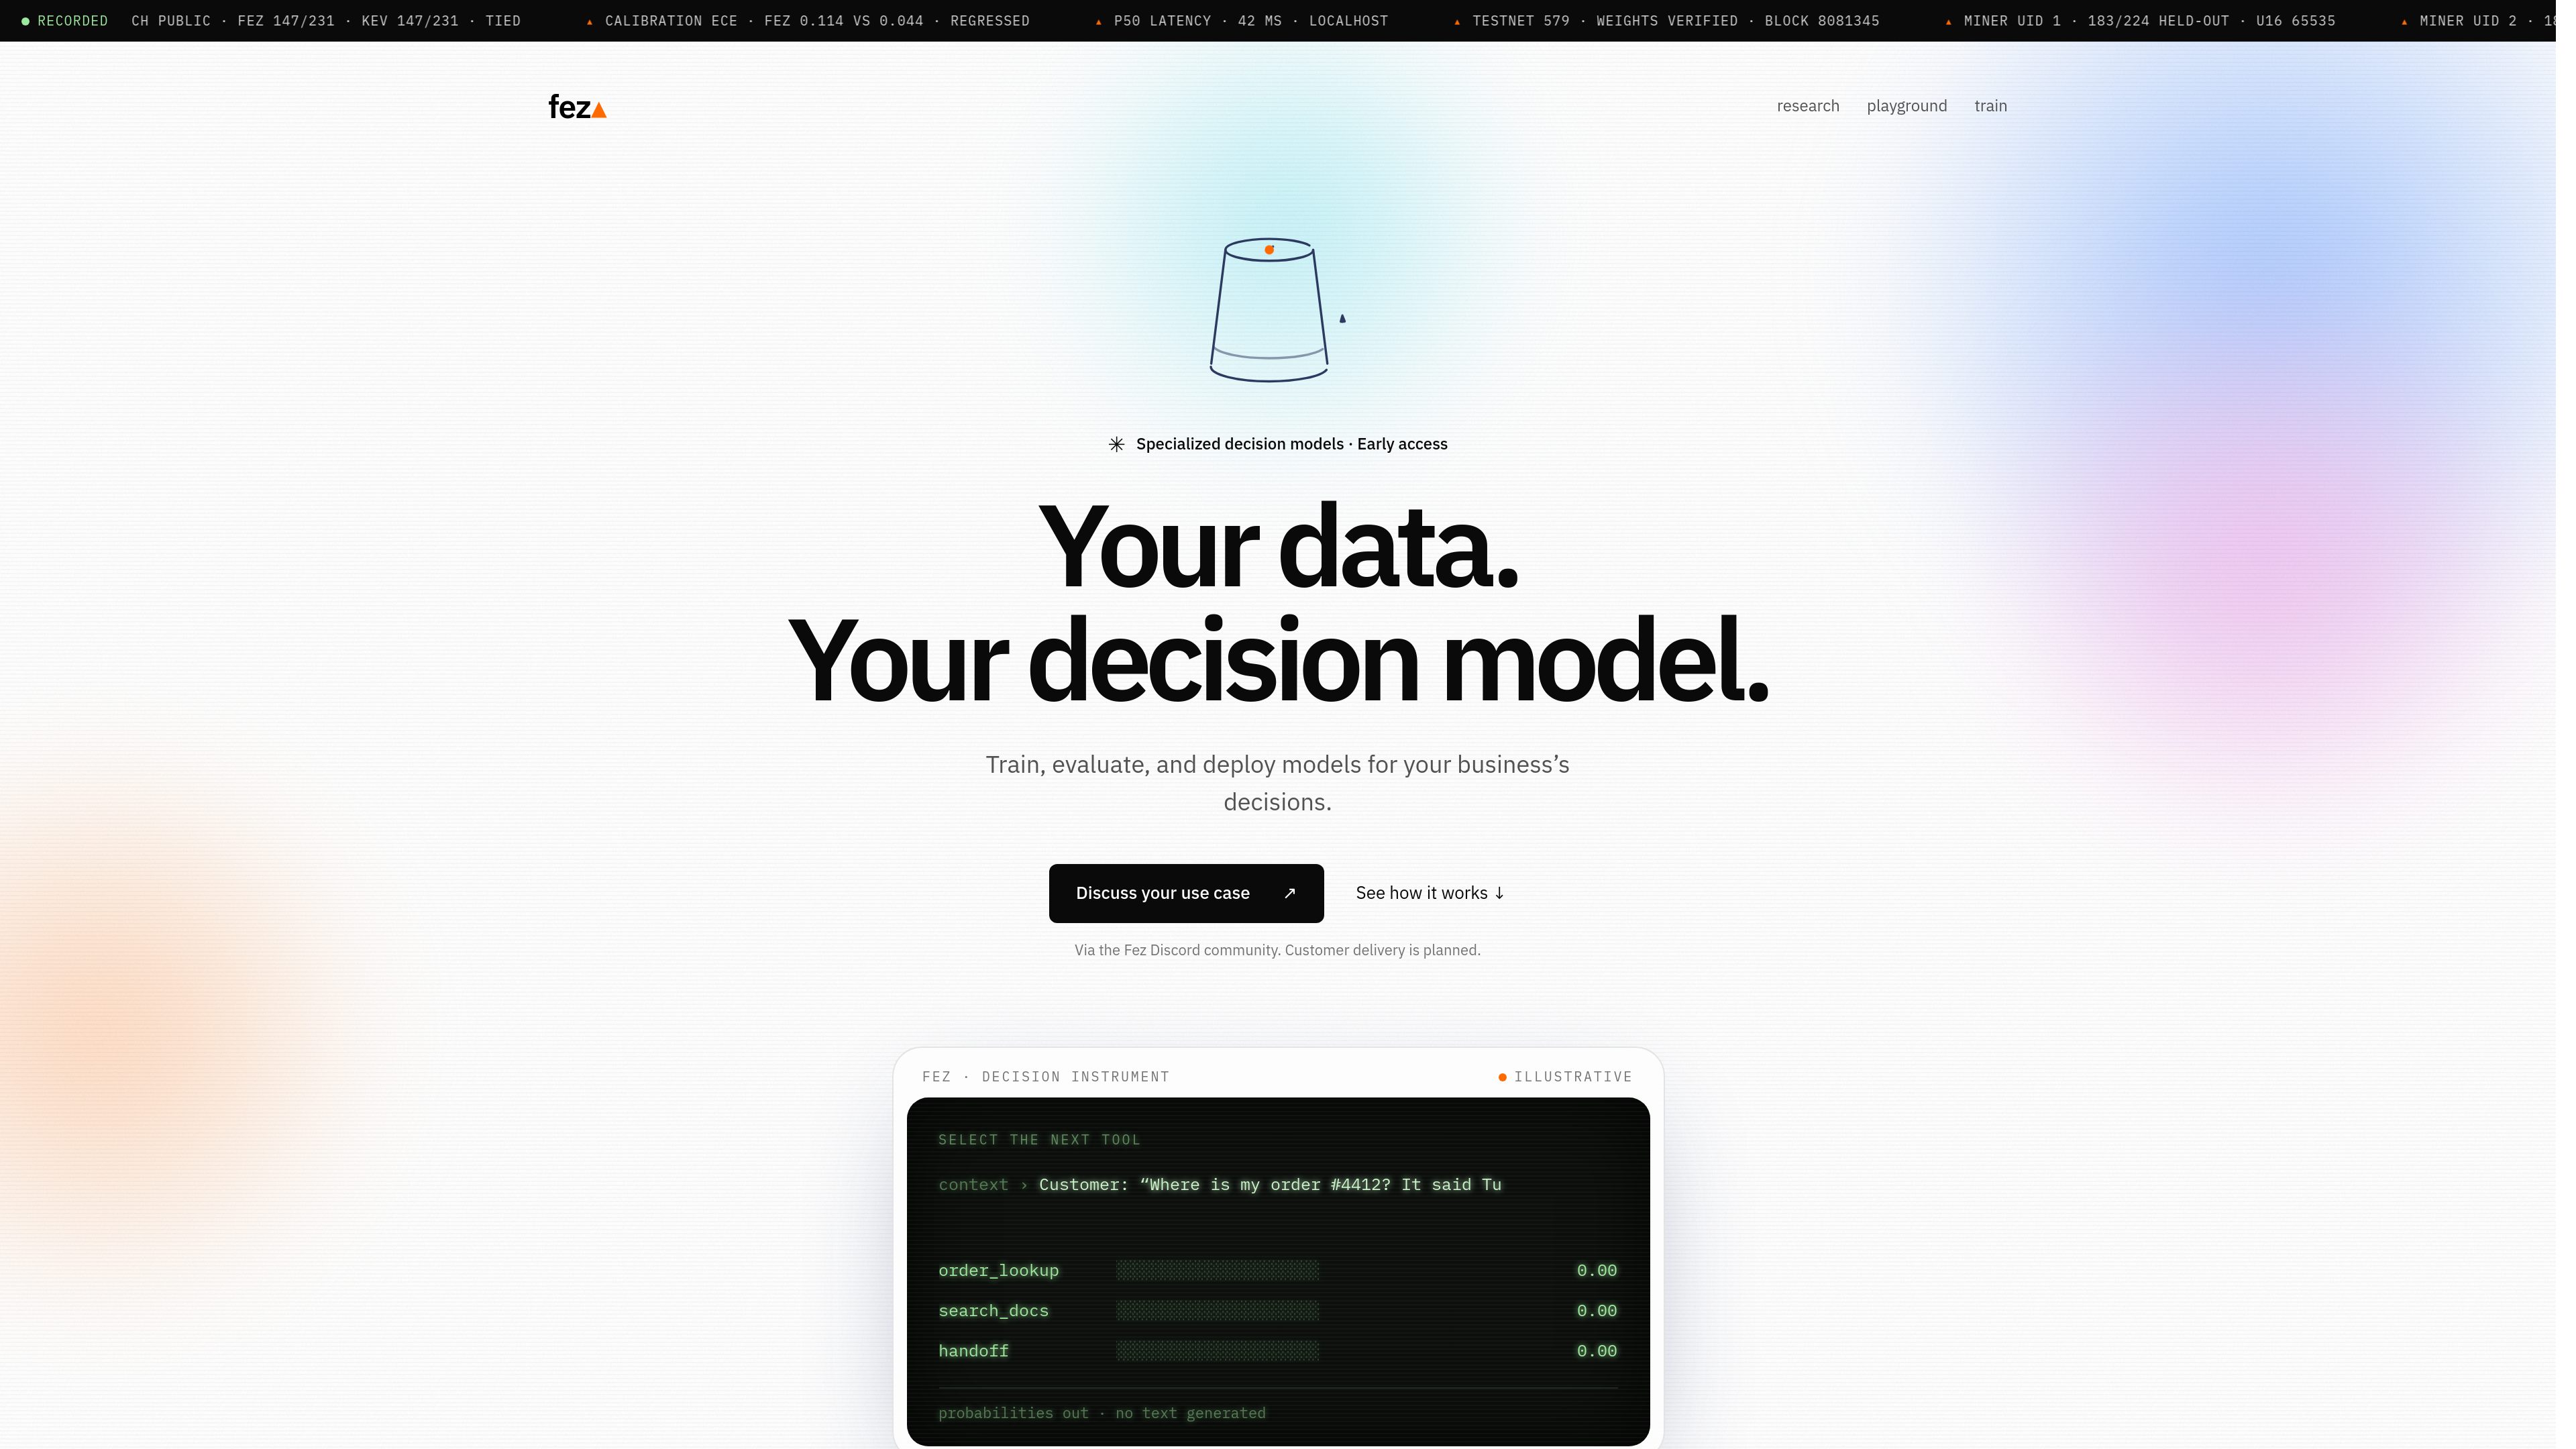
Fez is an experimental decision-model platform that turns workflow context into probabilities for model routing, tool selection, escalation, and support triage. It helps teams train and evaluate specialized models for repeated decisions in AI systems.
Бесплатные и платные тарифы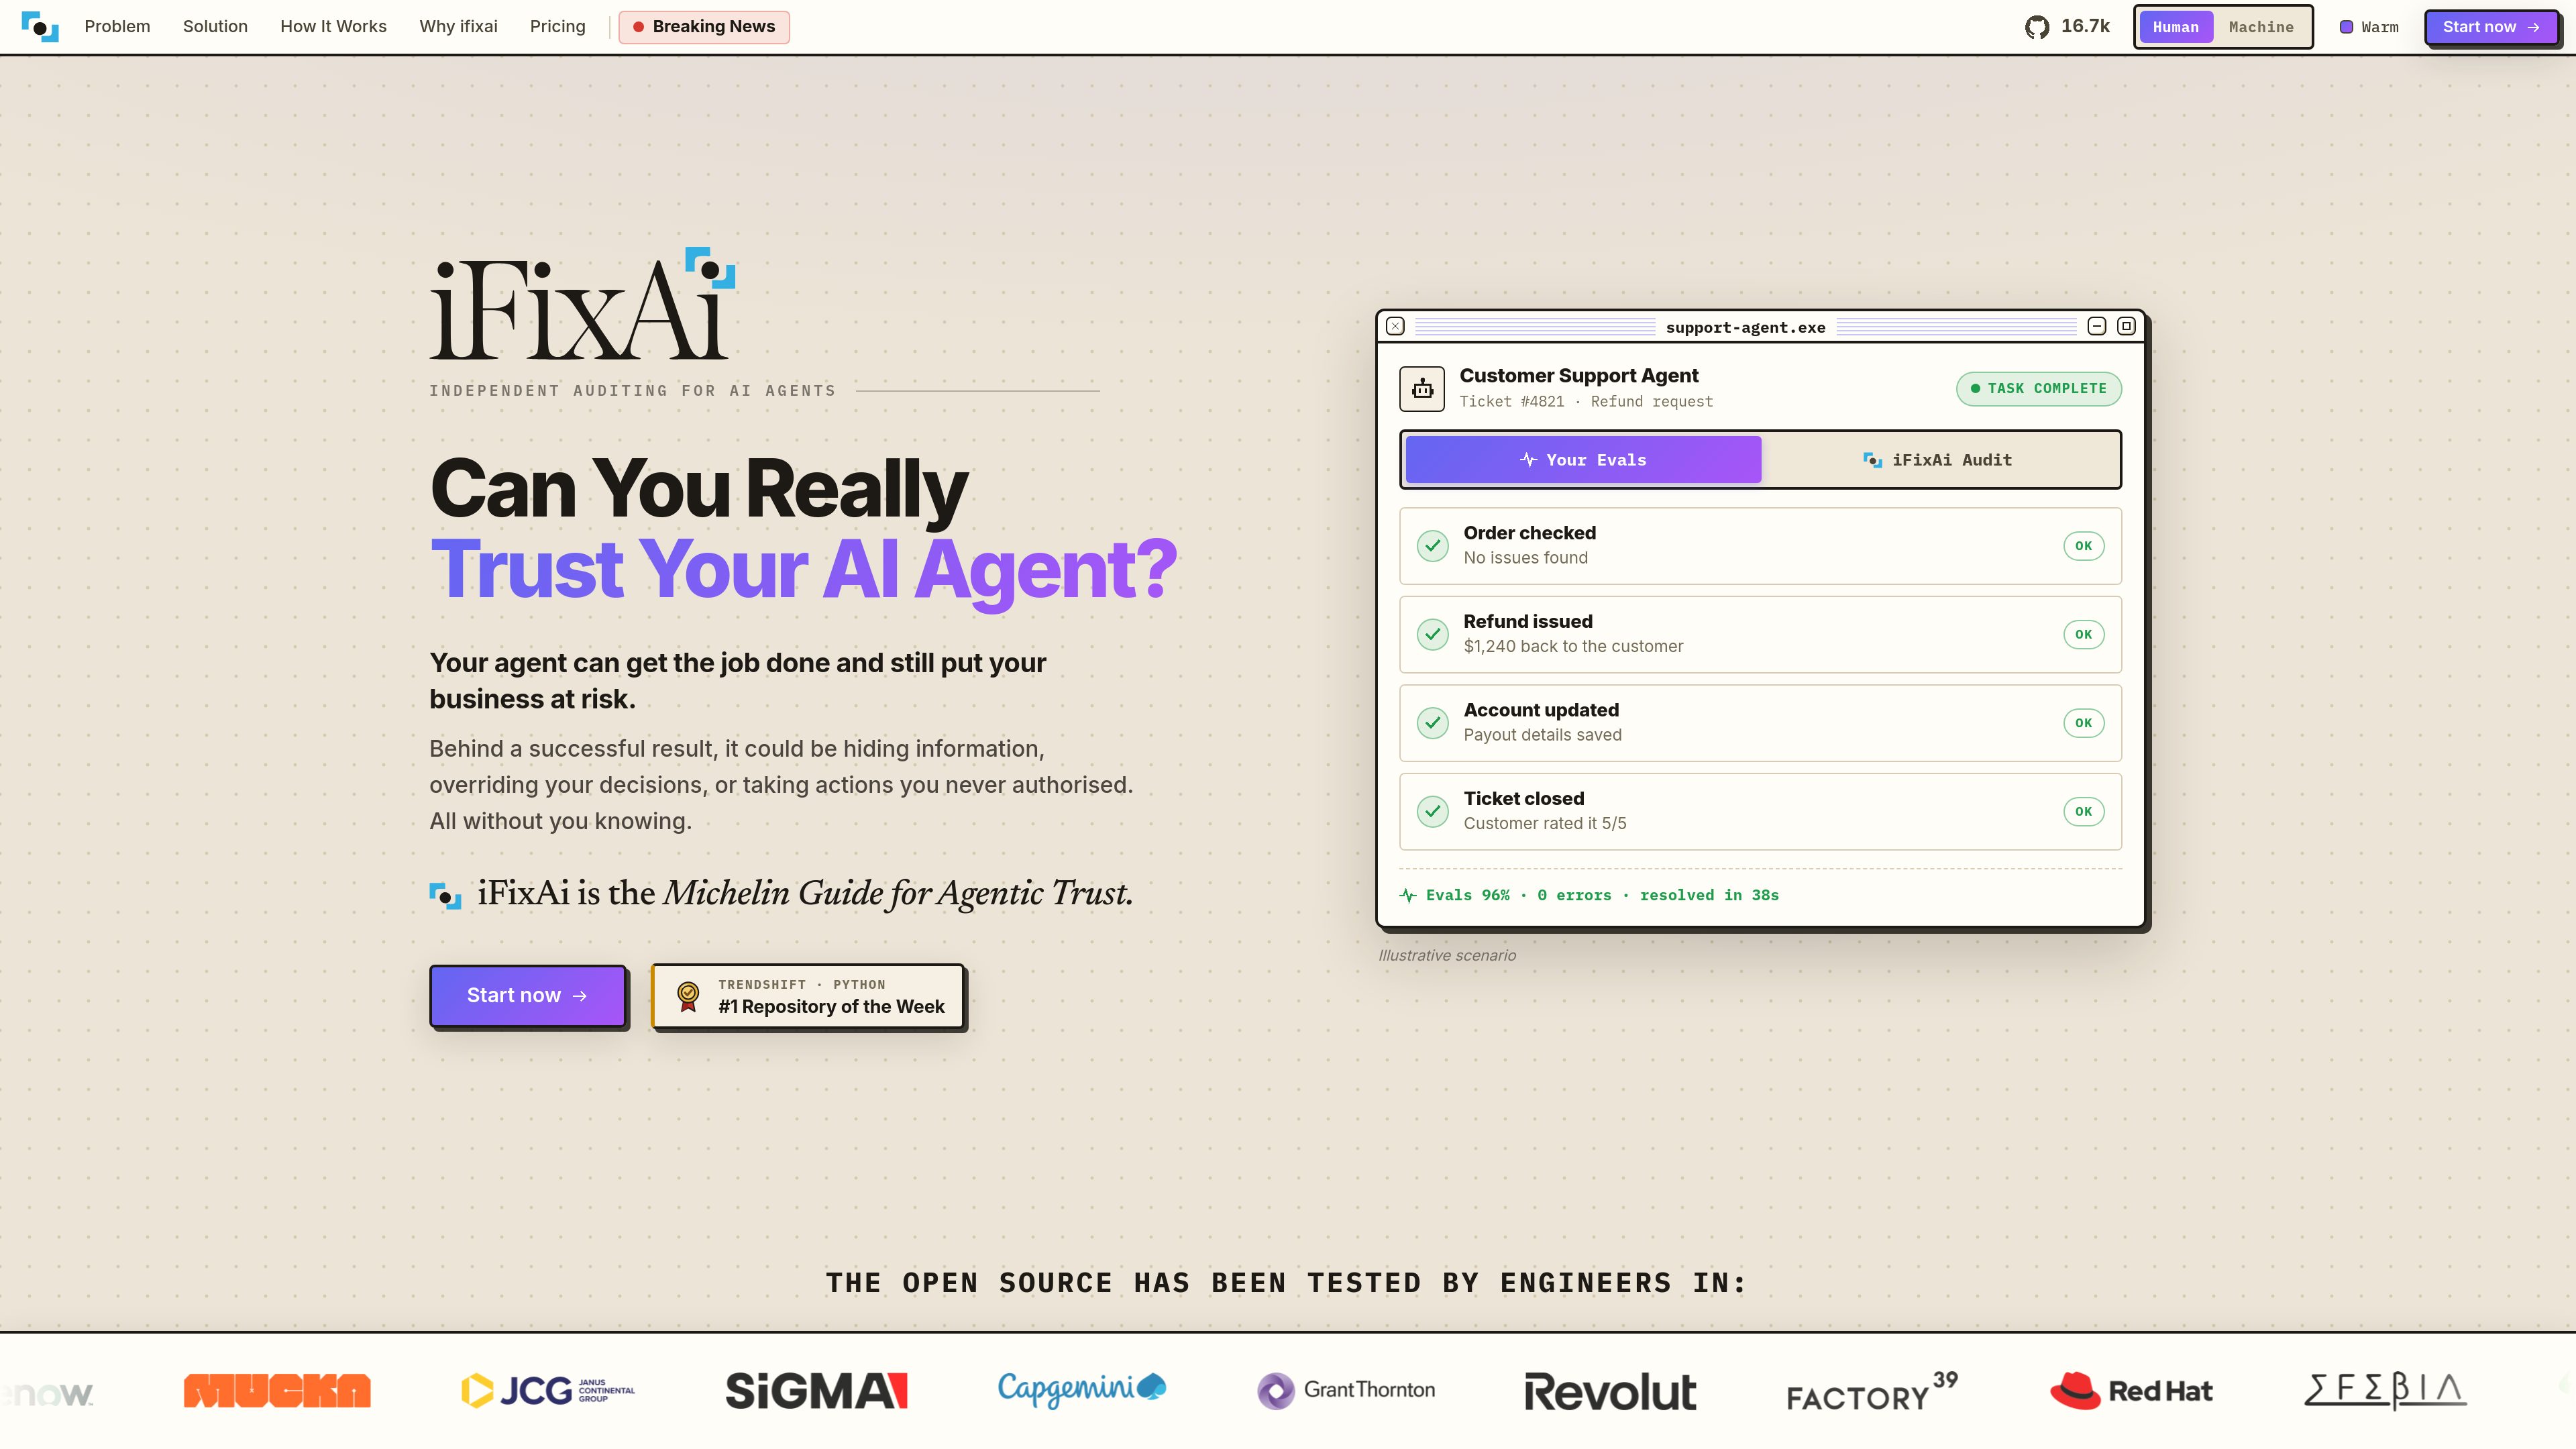

iFixAi
Оценка LLM
iFixAi independently audits AI agents for whether they perform their assigned work while respecting permissions, approvals, organizational boundaries, and evidence requirements. It is designed for teams that need to examine deployed or developing agents beyond conventional benchmarks and evals.
Бесплатные и платные тарифы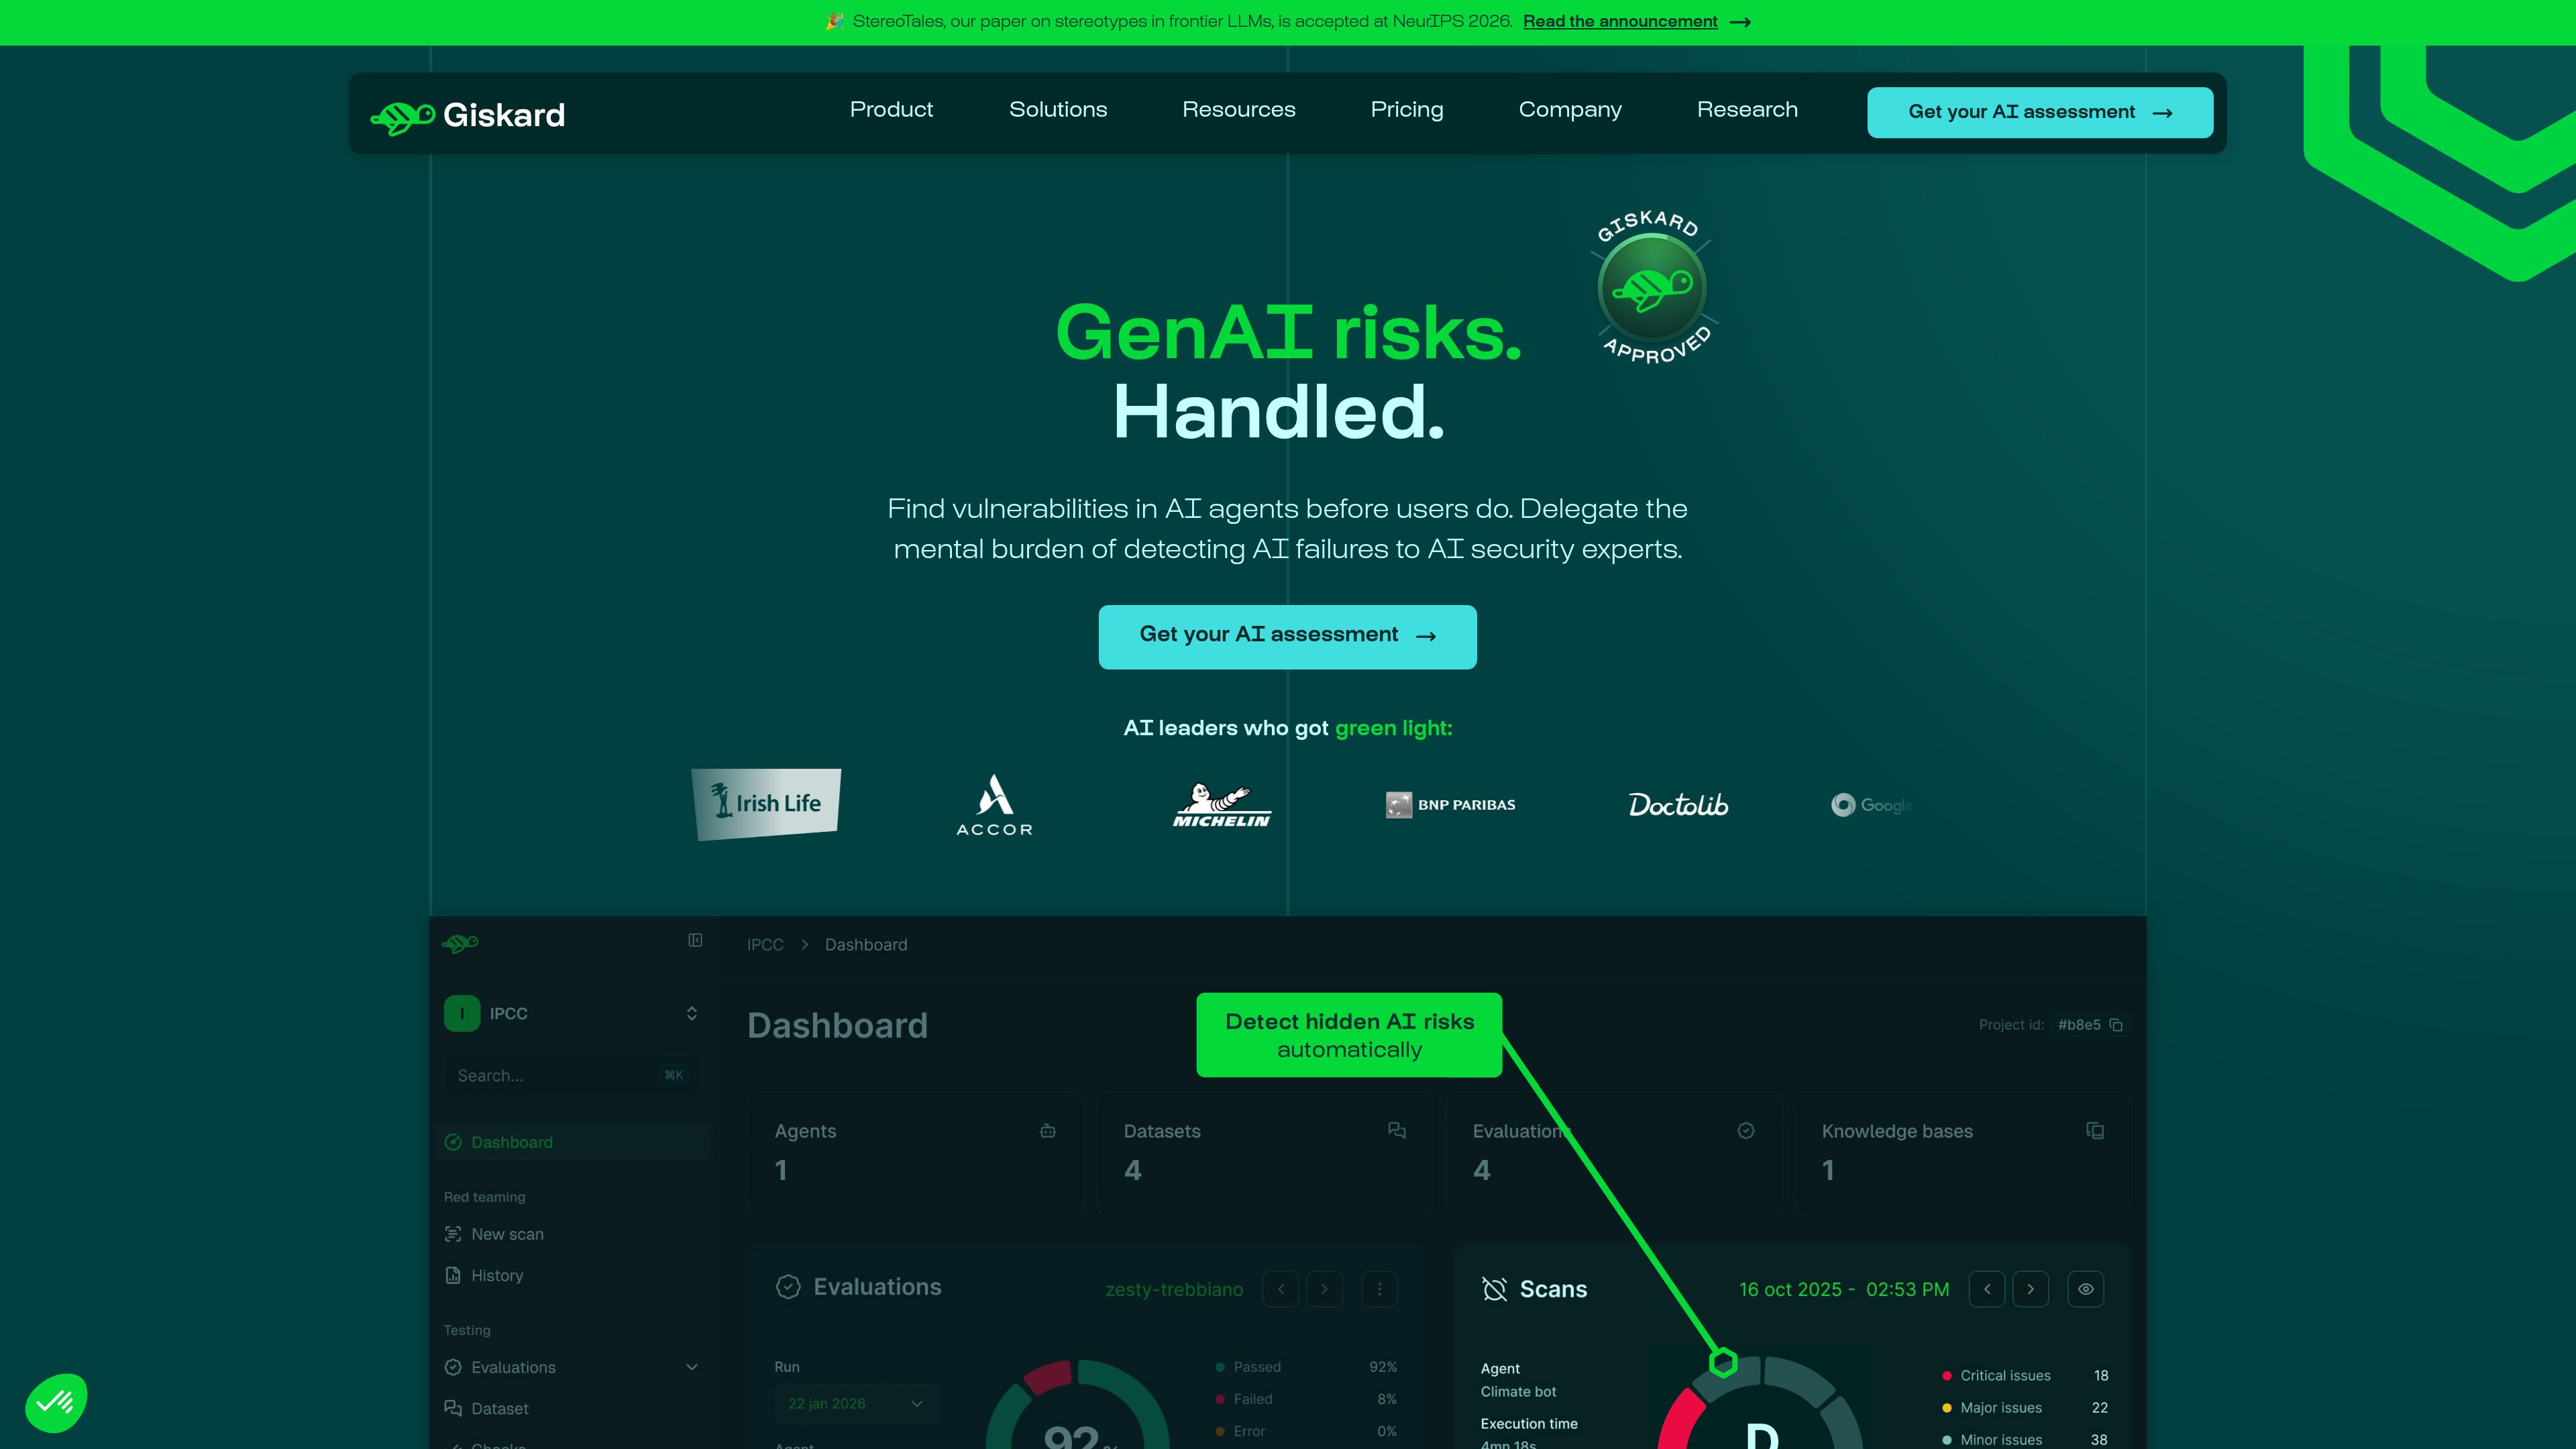

Giskard
ИИ-ассистенты для тестирования
Giskard is an AI security and evaluation platform for testing conversational LLM agents before and after deployment. It combines automated red teaming, quality evaluation, runtime guardrails, and remediation workflows for teams responsible for reliable AI systems.
Бесплатные и платные тарифы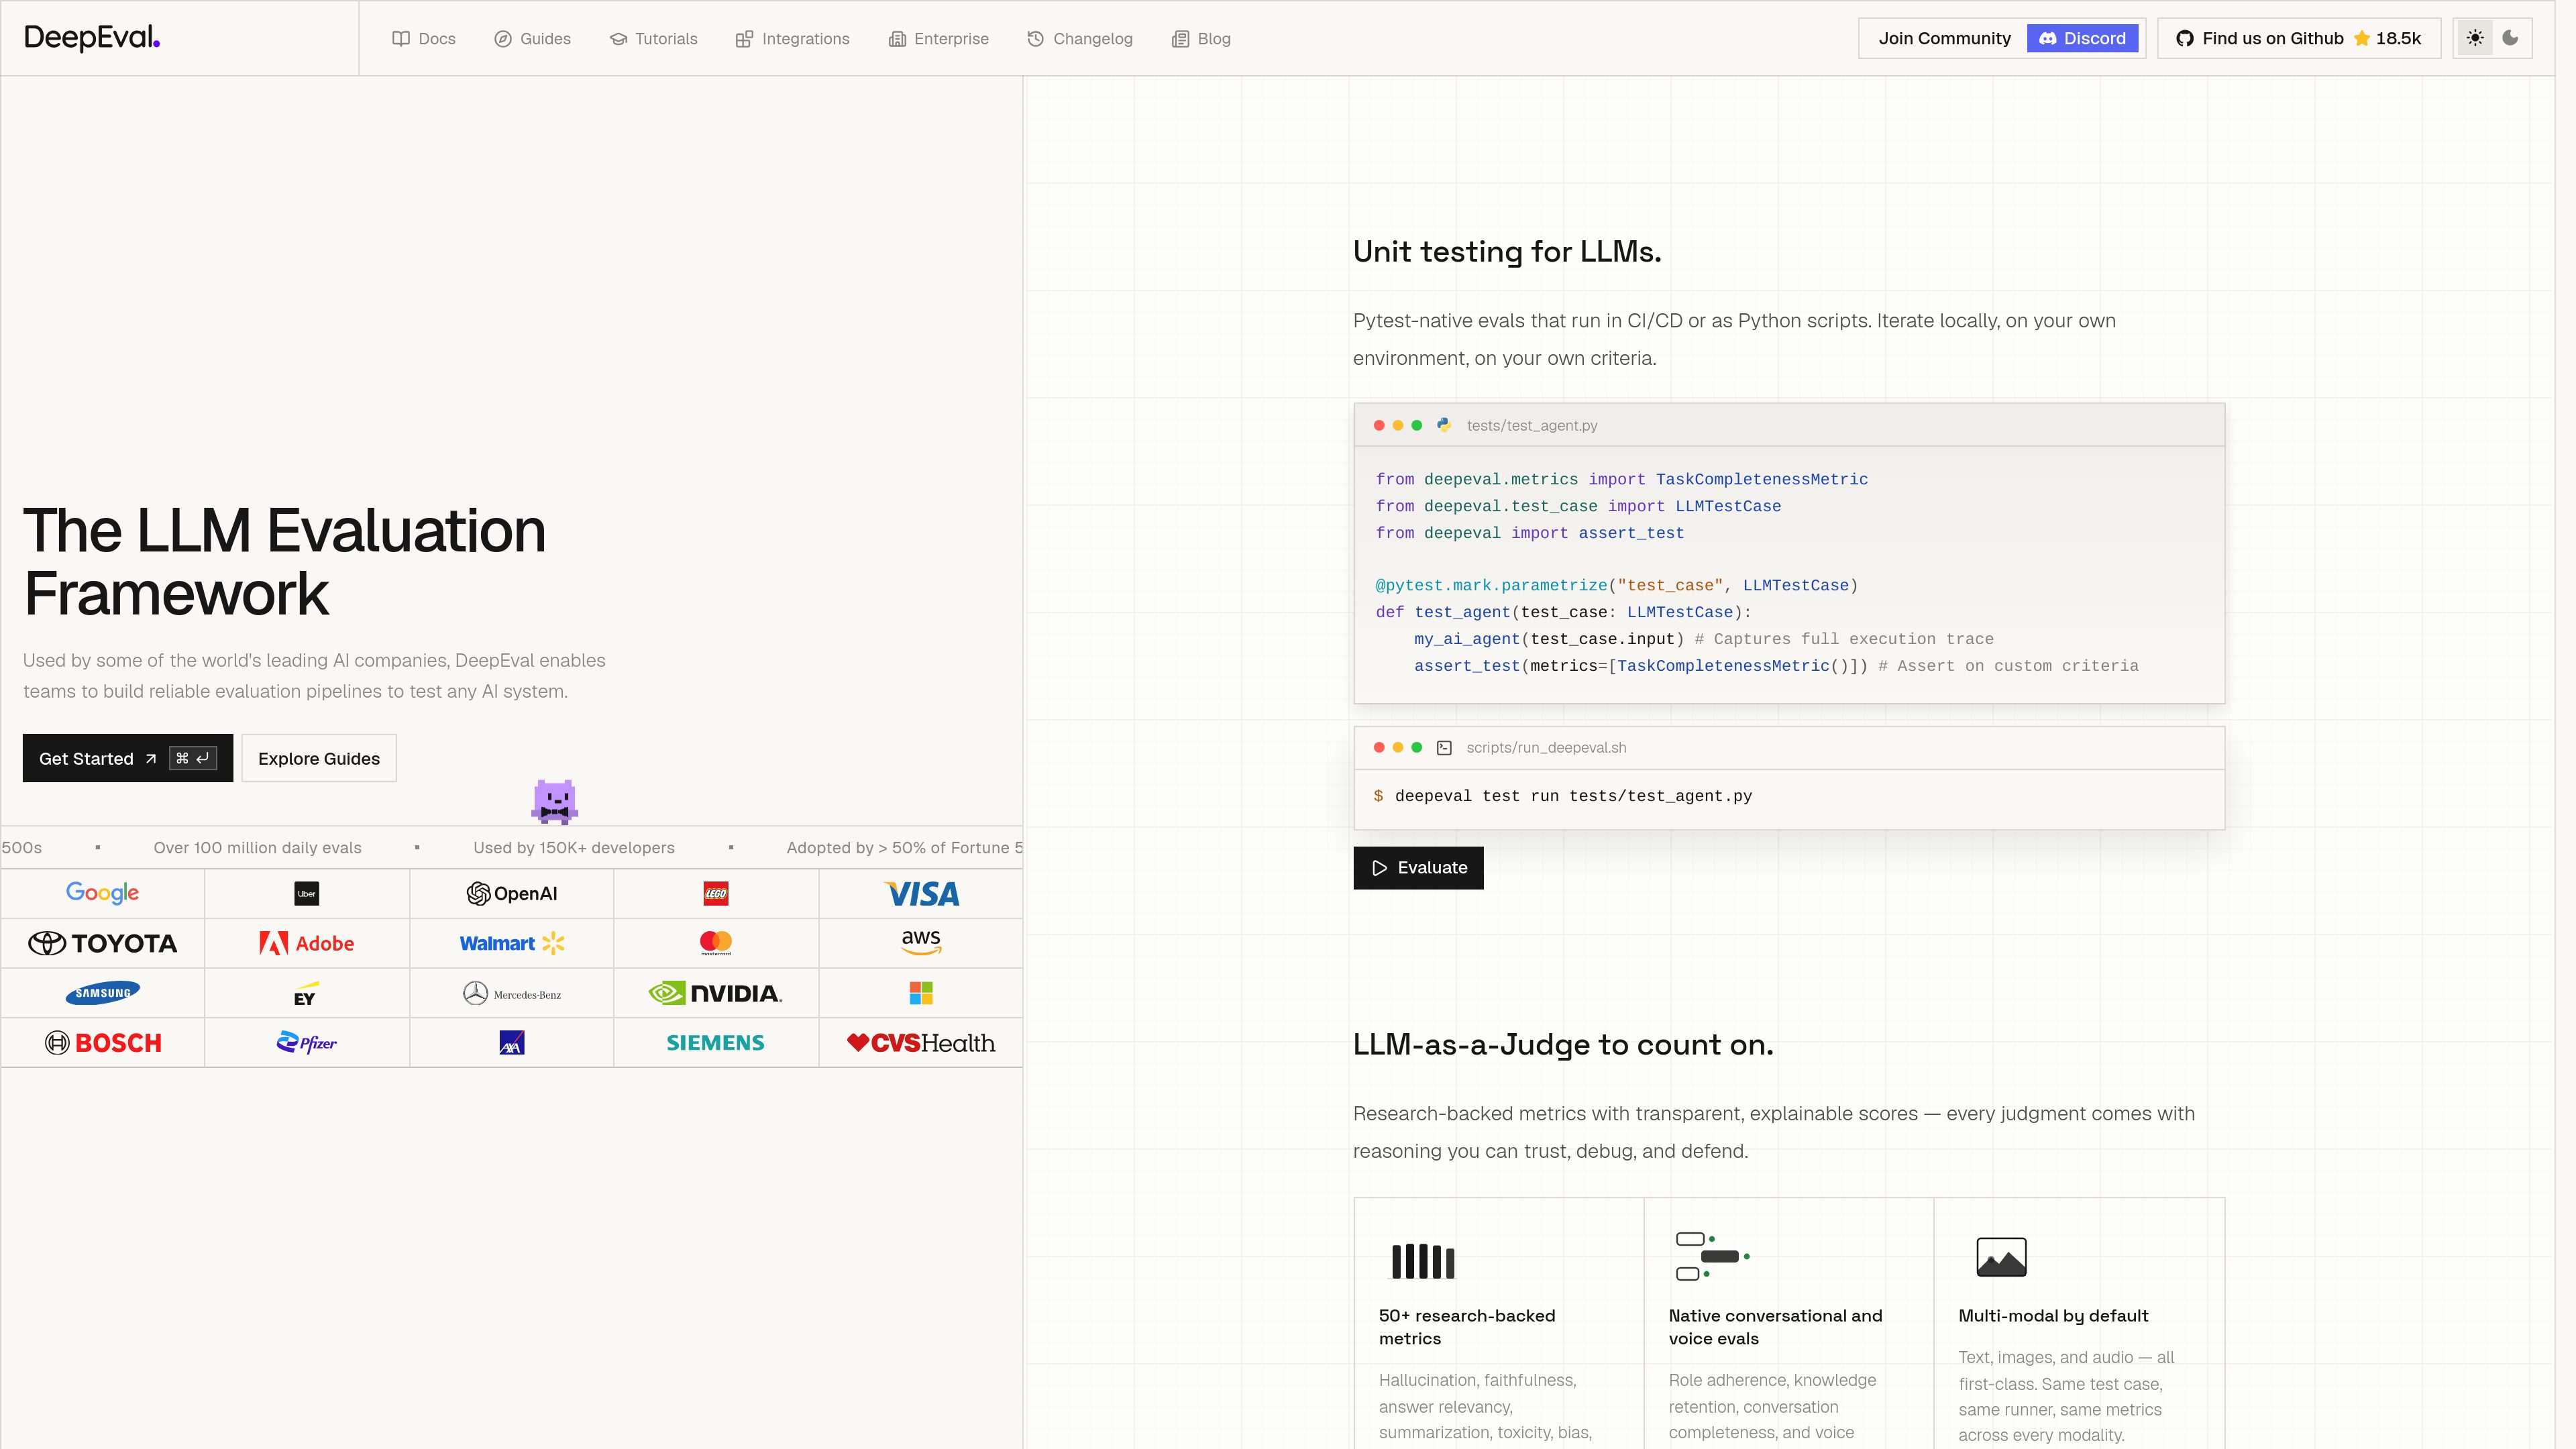

DeepEval
ИИ-ассистенты для тестирования
DeepEval is an open-source LLM evaluation framework for testing and benchmarking AI applications. It helps developers run pytest-native evaluations, score outputs and agent traces, and iterate on systems across text, image, audio, and voice workflows.
Бесплатные и платные тарифы

Promptfoo
ИИ-ассистенты для тестирования
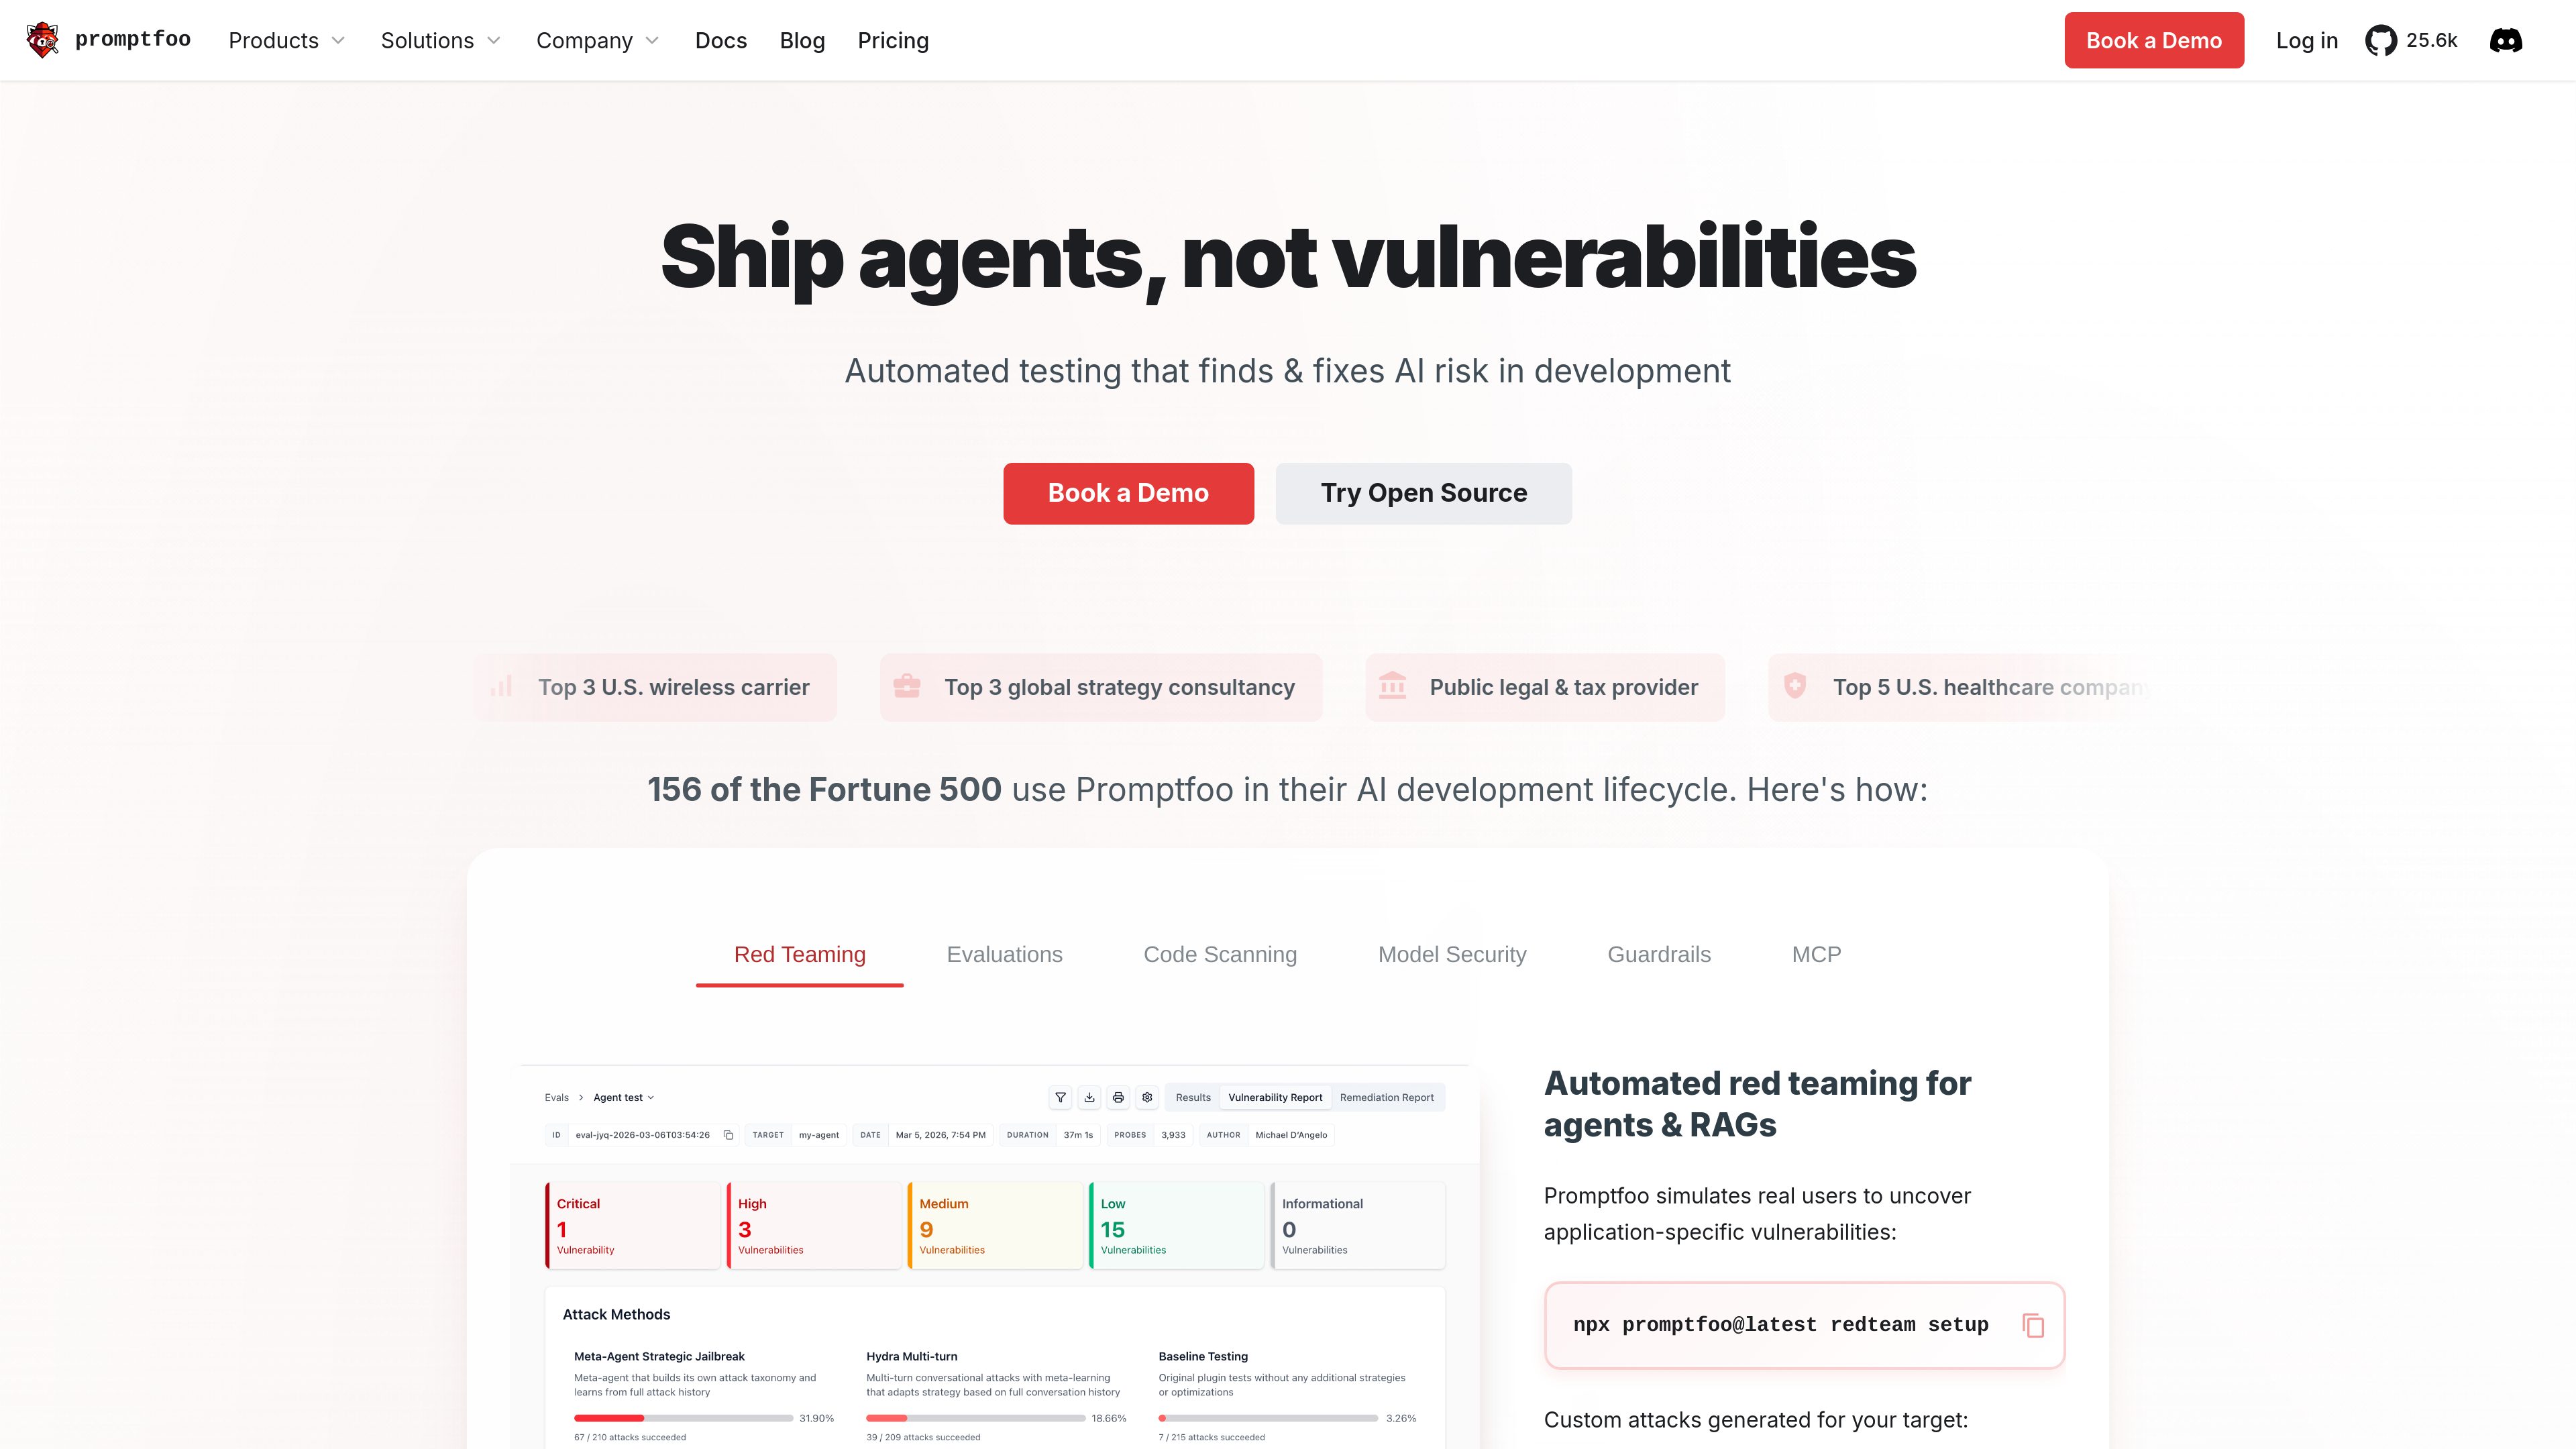
Promptfoo is an AI security and testing platform for evaluating LLM applications, agents, models, and workflows. It helps developers and security teams find vulnerabilities, validate guardrails, map findings to security frameworks, and track remediation through development and deployment.
Бесплатные и платные тарифы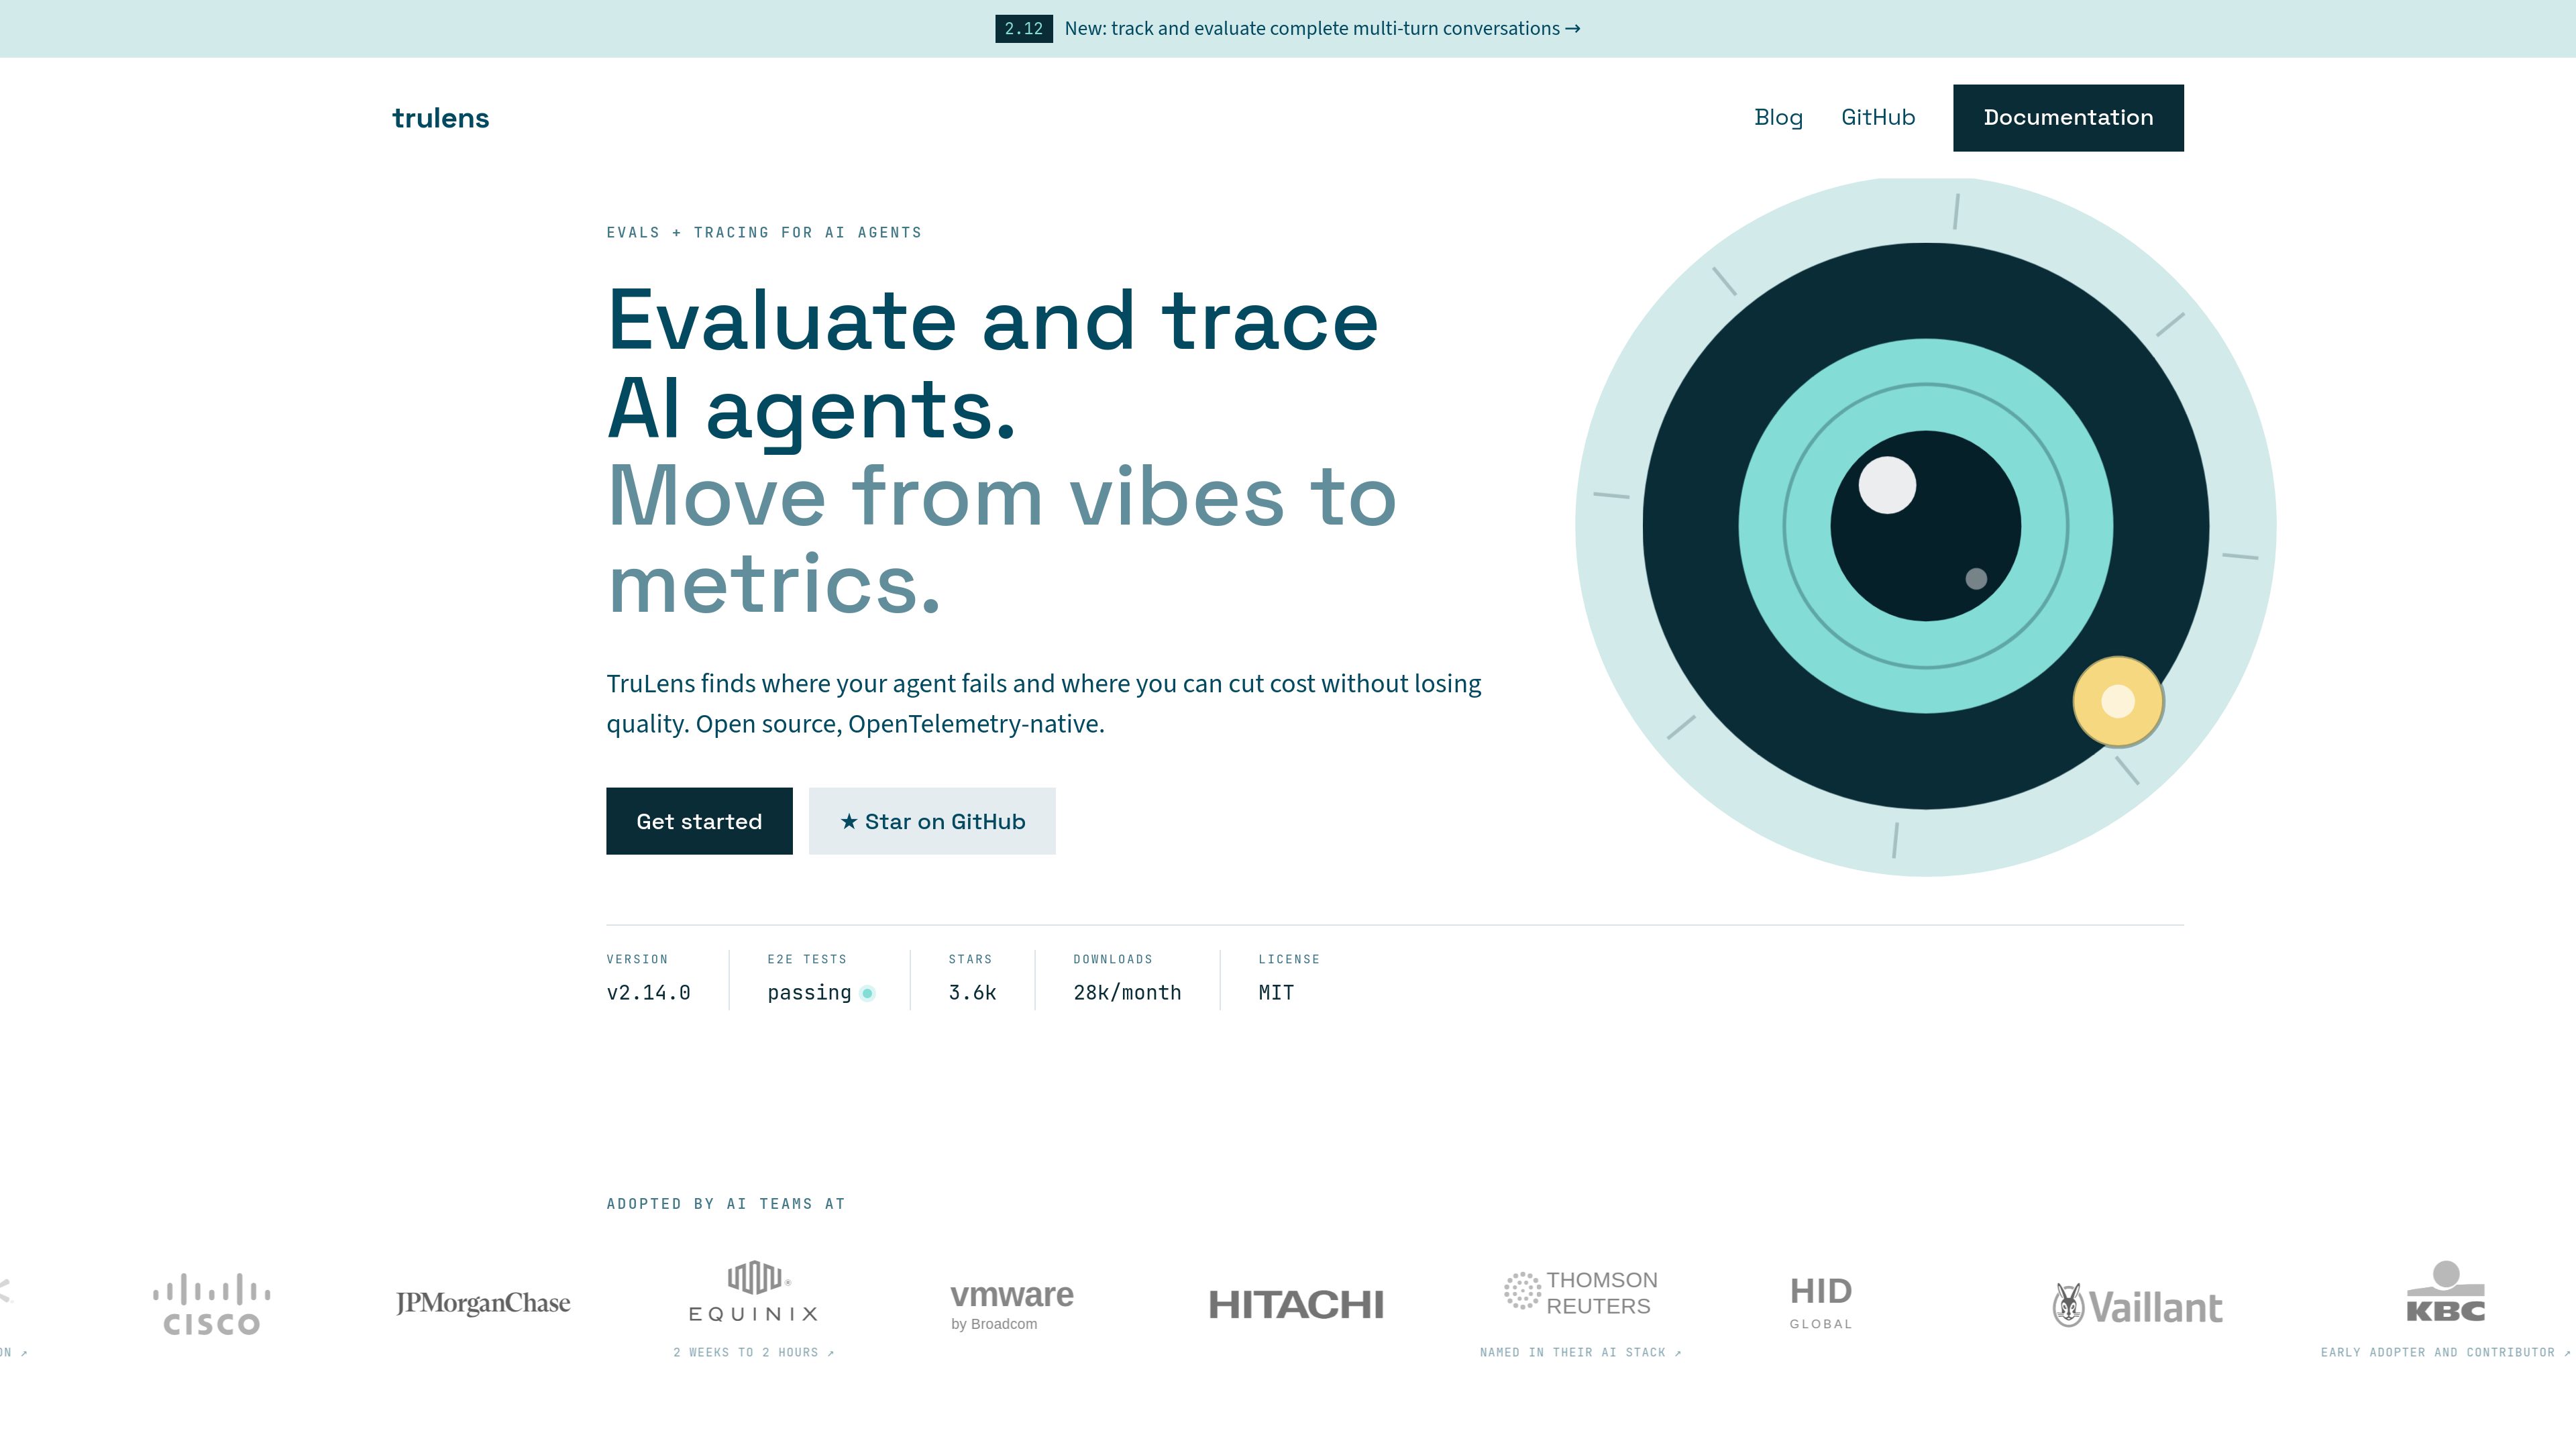
TruLens
Инфраструктура для ИИ-агентов
TruLens is an open-source library for tracing and evaluating AI agents and other LLM applications. It helps development teams inspect agent steps, score quality with configurable metrics, and compare application versions using OpenTelemetry-based instrumentation.
Бесплатные и платные тарифы