
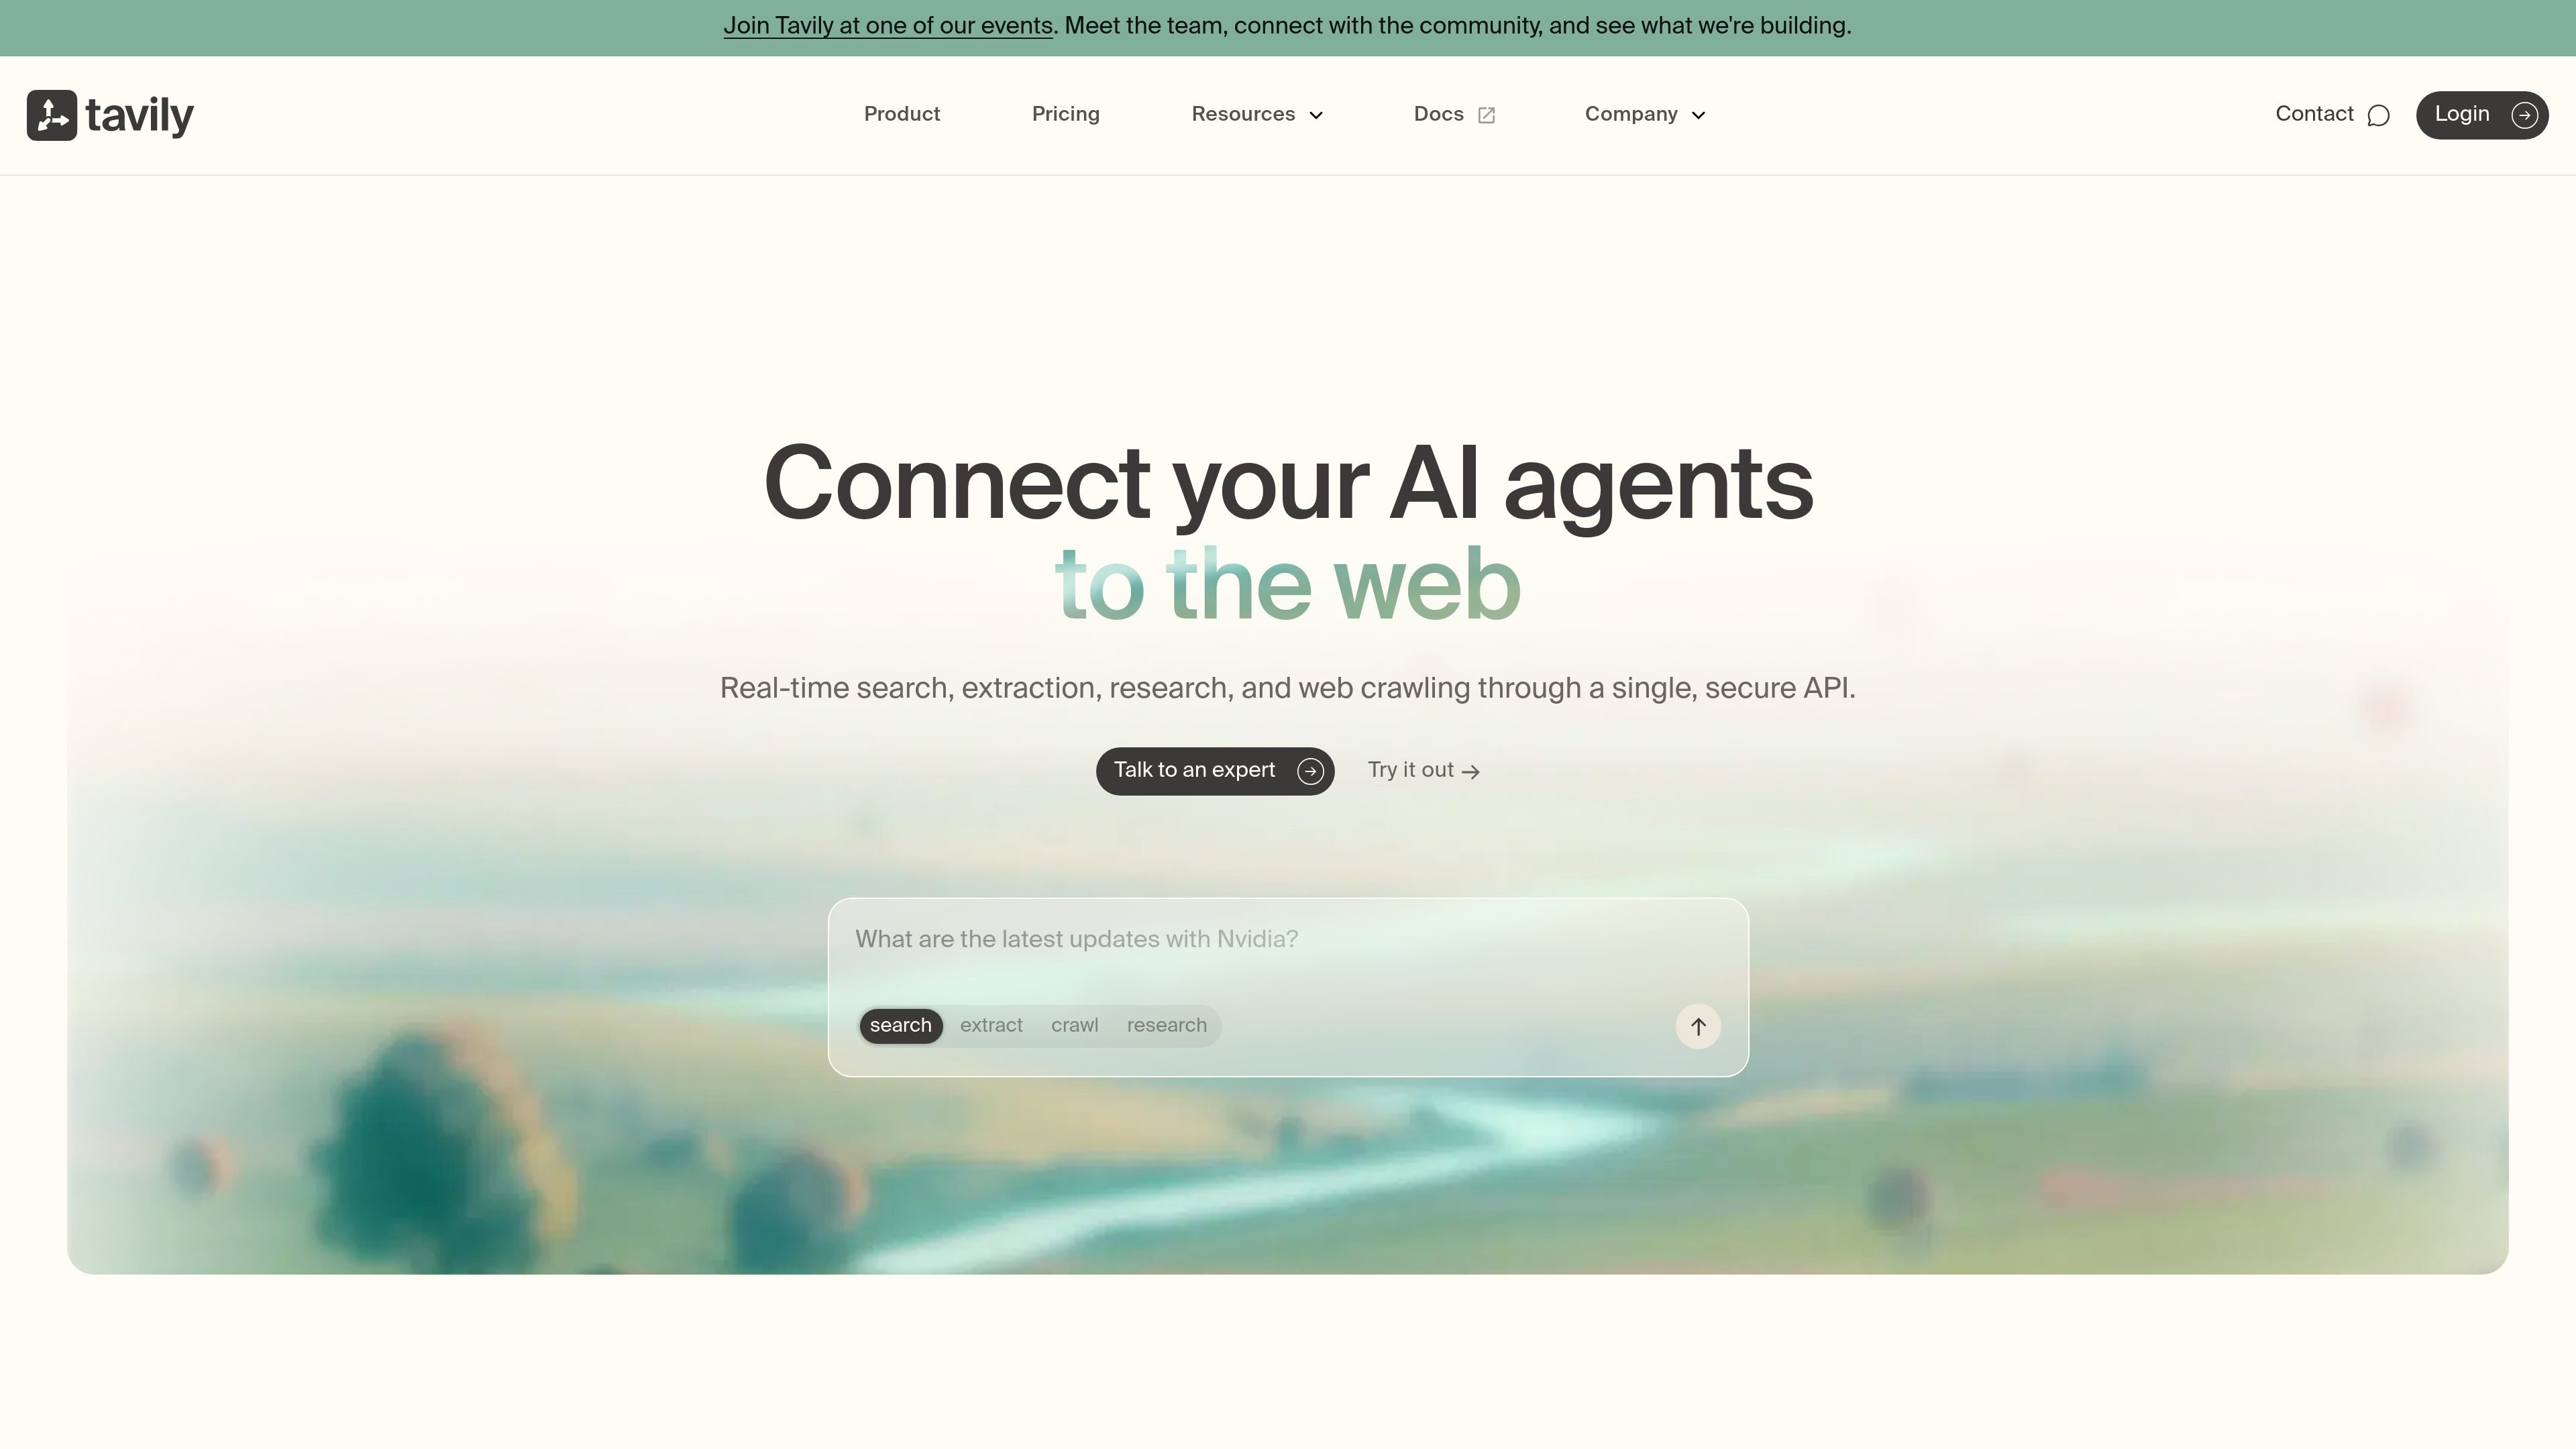
Real-time web search
The /search endpoint retrieves fresh web results and reranks them into information-rich snippets, helping agents work from relevant evidence rather than unfiltered search output.

Real-time web search, extraction, crawling, and research APIs for AI agents.
Tavily is a web access API for AI agents that provides real-time search, content extraction, crawling, mapping, and research capabilities. It retrieves current information from the web, cleans and ranks results, and returns structured, source-cited context that models can use for reasoning. The service is designed for production workloads, including applications that need scalable retrieval, configurable context, and safeguards for privacy, prompt injection, and harmful content.
The /search endpoint retrieves fresh web results and reranks them into information-rich snippets, helping agents work from relevant evidence rather than unfiltered search output.
Tavily can extract content from web pages and crawl sites so applications can retrieve machine-readable information beyond a single search result.
Dedicated /research and /map endpoints support multi-step research workflows and web discovery alongside search, extraction, and crawling.
Teams can adjust search depth, result count, content length, and domain filters to balance evidence quality, latency, and context usage.
Requests pass through security, privacy, and content validation layers designed to address PII leakage, prompt injection, and malicious or harmful sources. The service also lists Zero Data Retention, SOC 2 Type II, and ISO 27001 for regulated workflows.
Tavily reports 99.99% uptime, 180 ms p50 latency on /search, and support for high-throughput workloads, with enterprise rate limits, SLAs, and support available.
Build agents that gather current web evidence across multiple steps, synthesize findings, and retain source URLs for verification.
Retrieve regulatory information, public records, enforcement actions, and adverse media for underwriting, compliance, and risk assessment workflows.
Supply structured web evidence during supervised fine-tuning or reinforcement-learning workflows, while controlling retrieval settings and context use across repeated rollouts.
Connect applications built with different models or orchestration frameworks to a common web retrieval layer through API access and supported partner integrations.
Create a free account, retrieve an API key from the dashboard, install the Python or JavaScript SDK, and use the key to authenticate API requests.
Tavily provides endpoints for search, extraction, research, crawling, and mapping. The /search endpoint returns reranked web context, while the other endpoints support broader retrieval and research workflows.
Usage is measured in API credits, which vary by request type. The service offers a free plan with monthly credits, pay-as-you-go usage, project plans, and custom enterprise plans.
The service is presented for production and regulated workflows, with security and content controls, listed SOC 2 Type II and ISO 27001 certifications, Zero Data Retention, enterprise SLAs, and high-throughput retrieval options.
Os dados de tráfego são apenas para referência.
www.getzep.com
Graphiti is an open-source GitHub project for building real-time knowledge graphs for AI agents. It provides a codebase that developers can inspect, extend, and contribute to through the repository’s development workflow.

www.pipecat.ai
Pipecat is an open-source Python framework and ecosystem for building real-time voice and multimodal AI agents. It helps developers compose pipelines that coordinate speech, language, vision, video, text, tools, and telephony transports.

www.simular.ai
Simular is an autonomous computer platform that uses AI agents to operate real computers and automate digital workflows. It serves individuals, builders, operators, and businesses that need to automate tasks across desktop applications and websites, including workflows that do not expose traditional APIs.

steel.dev
Steel is open-source browser infrastructure for AI agents and web automation. It provides cloud browser sessions through an API, with support for common browser automation tools and workflows such as scraping, research, RPA, and agent-driven web tasks.

tabstack.ai
A managed web API for cited research, structured extraction, and agent web tasks.

zeroclick.ai
ZeroClick helps businesses sell APIs, datasets, and digital services directly to AI agents. It adds a machine-readable storefront, agent payment support, signed request forwarding, and transaction analytics in front of an existing offering.