
Managed ComfyUI cloud environment
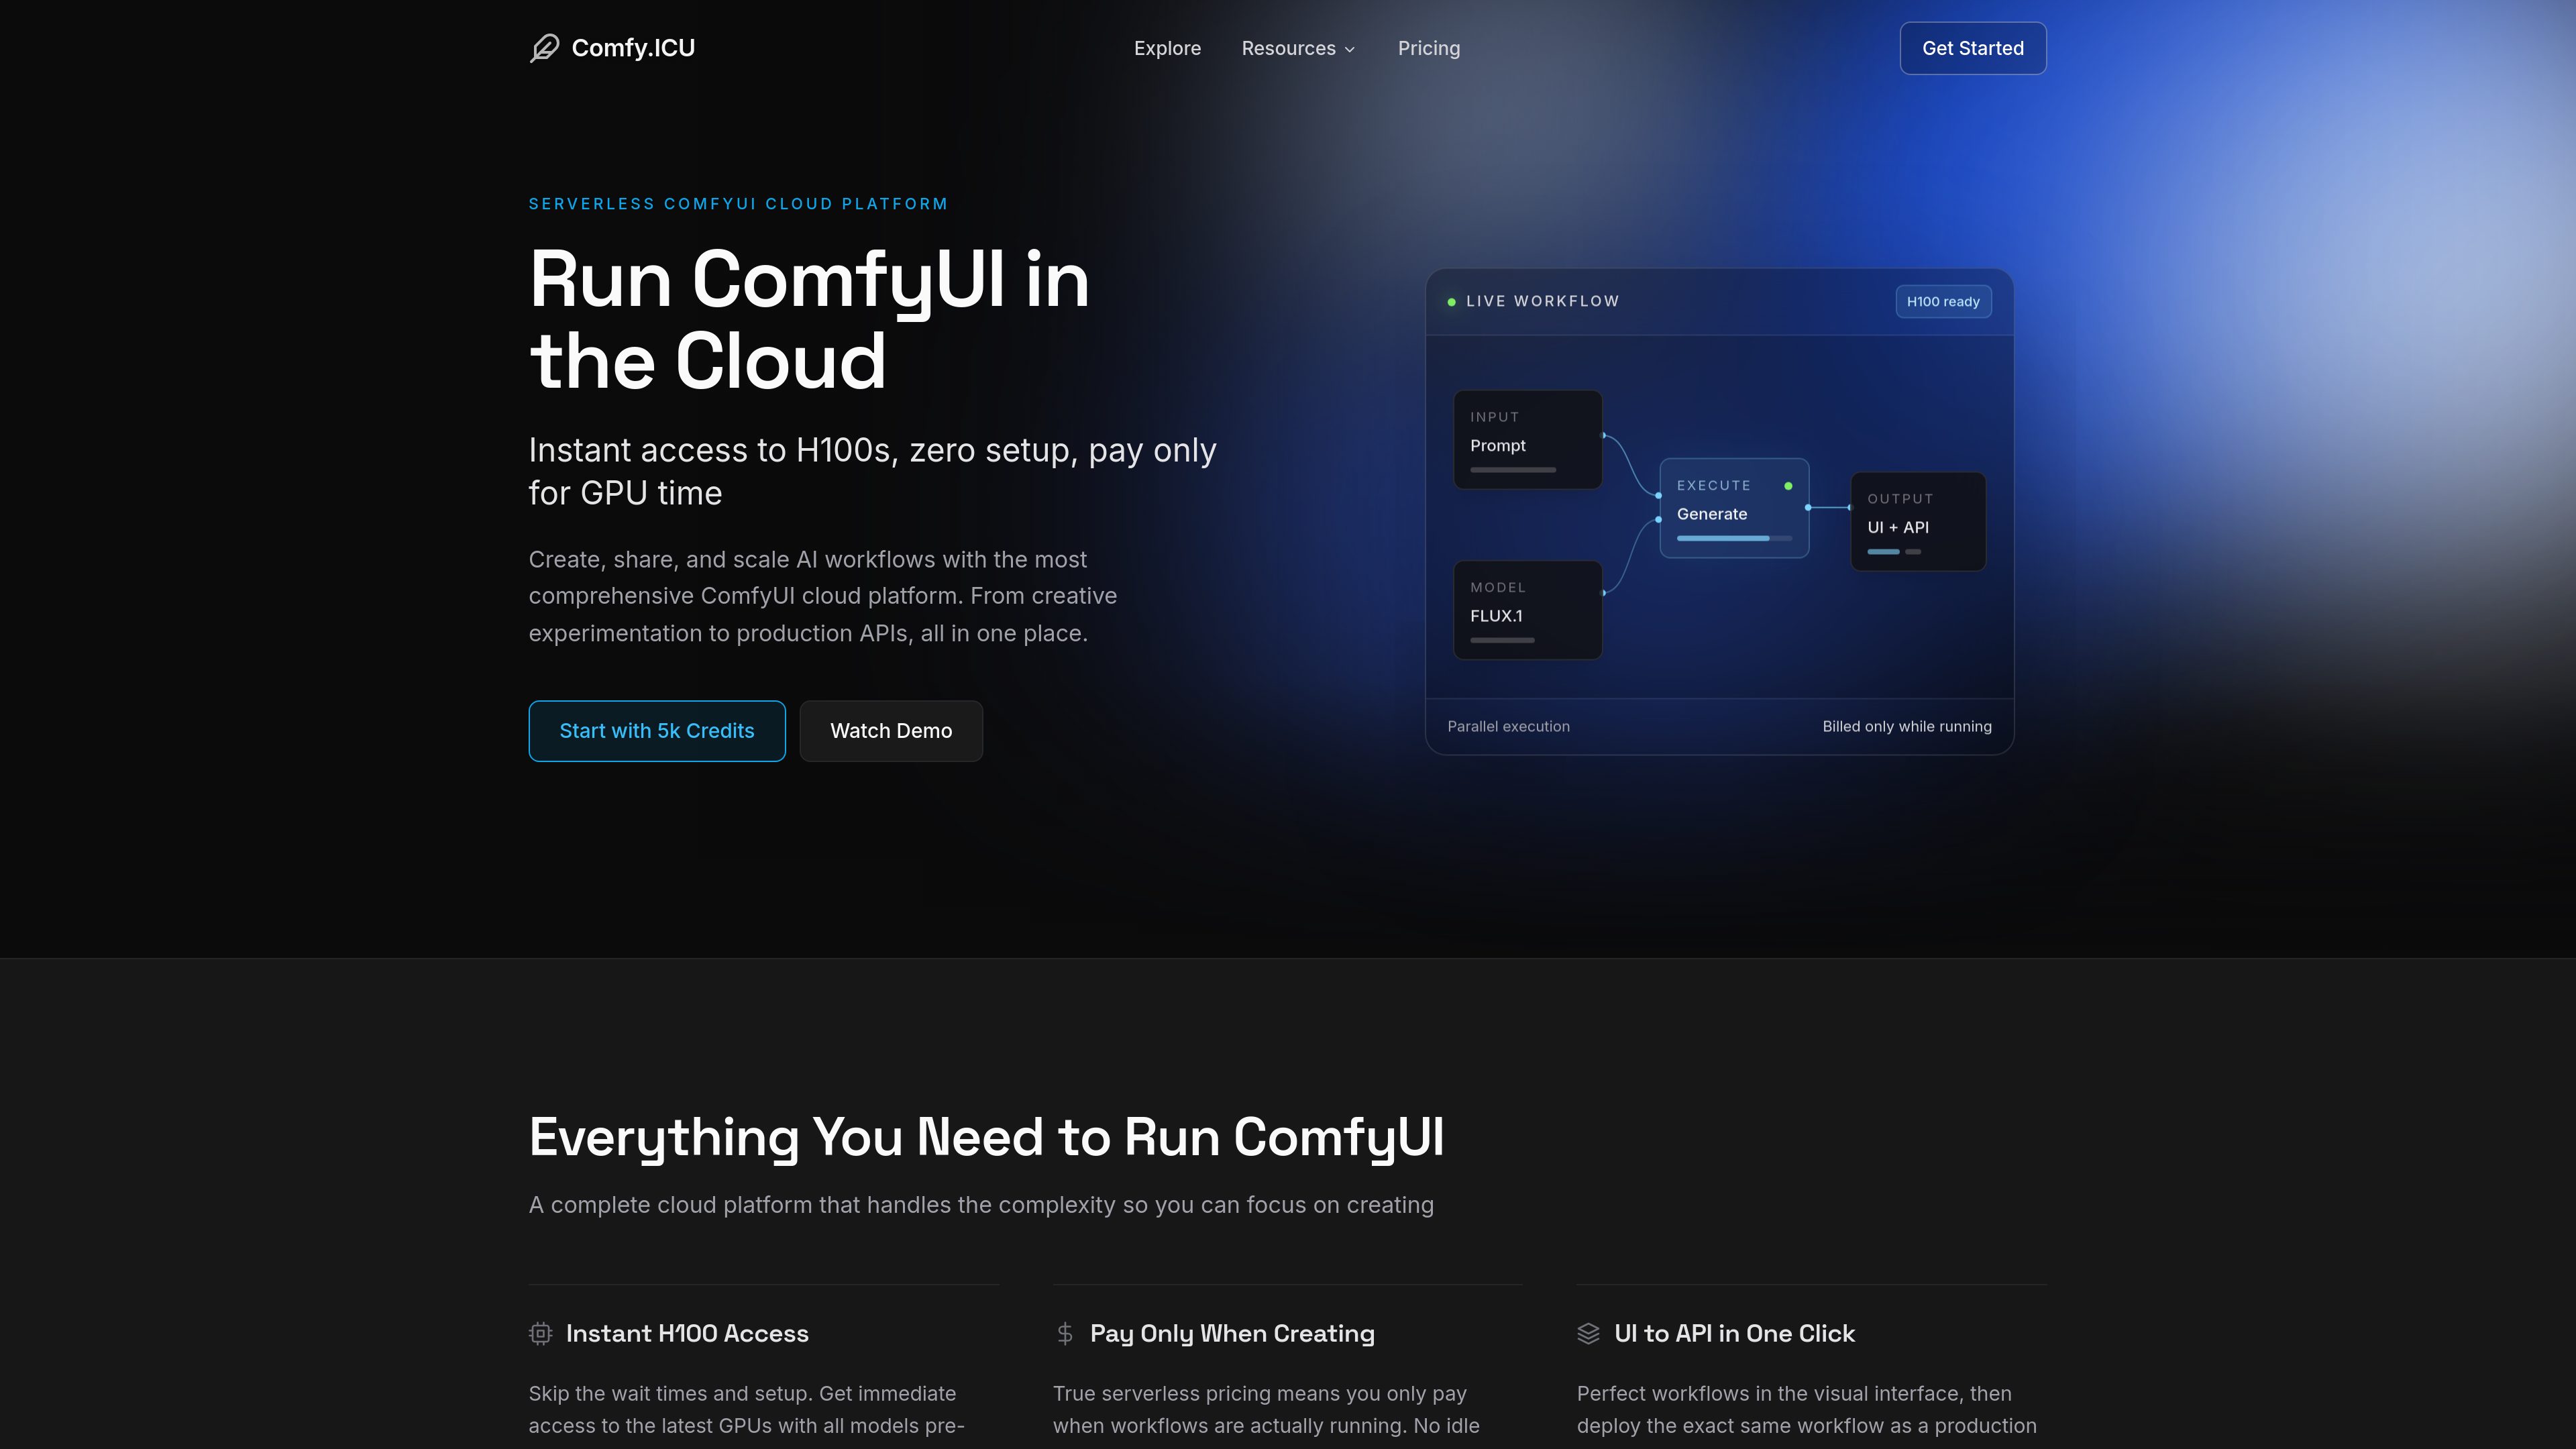
Run ComfyUI workflows on a managed platform without setting up servers, GPU drivers, CUDA dependencies, or custom nodes locally. The shared executor includes more than 95 extensions, 4,000+ nodes, and 2,000+ models.

ComfyICU is a managed cloud platform for running, sharing, and deploying ComfyUI workflows. It supports visual workflow development, serverless GPU execution, team workspaces, and REST API deployment without requiring users to manage GPU infrastructure.
ComfyICU is a managed cloud platform for running ComfyUI workflows without maintaining servers, CUDA drivers, or local GPU infrastructure. It combines a visual workflow interface with serverless GPU execution, so users can build and test workflows, share them, and run them on cloud GPU tiers.
The platform is designed to cover both experimentation and application deployment. Workflows refined in the UI can be deployed as REST API endpoints, allowing development teams to use the same workflow configuration in production. Team plans add project workspaces, permissions, usage analytics, and shared billing.
ComfyICU's shared executor includes more than 95 extensions, 4,000+ nodes, and 2,000+ models. Credits are charged per second of GPU execution, while editing and idle time are not charged. Custom node installation is not supported on the fully managed platform.
Run ComfyUI workflows on a managed platform without setting up servers, GPU drivers, CUDA dependencies, or custom nodes locally. The shared executor includes more than 95 extensions, 4,000+ nodes, and 2,000+ models.
Choose among available L4, L40S, and H100 GPU tiers according to plan and workload. Credits are consumed per second while a workflow is executing, rather than for editing or idle time.
Develop and refine a workflow in the visual interface, then deploy it as a REST API using the same workflow environment. The platform provides auto-generated API code and documentation examples.
Developer integrations can use polling or webhooks for run status updates. The API documentation includes examples for Python, JavaScript, and curl, with JSON-based requests and responses.
Eligible plans provide organization features such as project-based workspaces, role-based access control, usage analytics, and shared billing for collaborative workflow development.
ComfyICU supports parallel workflow execution and describes automatic scaling for API workloads, helping teams run multiple jobs without provisioning GPU instances themselves.
New users can work with starter templates and a managed environment instead of first installing local GPU dependencies. The platform supports browsing, editing, and running workflows while charging only for execution time.
Professional creators can use the visual workflow editor to refine complex generation processes and run them on cloud GPUs when local hardware is insufficient or inconvenient.
Developers can take a workflow completed by a creative team and call it through a REST API, avoiding a separate workflow translation or infrastructure setup step.
API-based workflows can support scenarios such as generating product variations after a catalog upload, applying consistent styling, or processing batches of creative assets.
Teams can organize workflows in project workspaces, assign access through roles, and review usage through analytics while creatives and developers work in the same platform.
ComfyICU is used to create, run, share, and deploy ComfyUI workflows in the cloud. It supports both interactive workflow development and REST API execution.
Credits are spent per second of GPU execution. The platform states that users are not charged for idle time, editing, or browsing. New accounts include 5,000 free credits without requiring a credit card; paid monthly plans add larger credit allowances.
The pricing page lists L4 with 24 GB VRAM, L40S with 48 GB, and H100 with 80 GB. Availability, queue priority, and concurrency depend on the selected plan.
No. The pricing information states that custom node installation is not supported on the fully managed platform. The shared executor provides more than 95 extensions, 4,000+ nodes, and 2,000+ models instead.
A workflow can be exposed through ComfyICU's REST API. The developer documentation provides examples using Python, JavaScript, and curl, and describes polling or webhooks for status updates. File inputs can be supplied through public URLs and supported services listed in the API documentation.
Os dados de tráfego são apenas para referência.

baseten.co
Baseten is an inference platform for deploying, serving, and scaling open-source, custom, and fine-tuned AI models. It supports managed cloud, self-hosted, hybrid, and dedicated deployments for teams running production AI workloads.

www.coreweave.com
CoreWeave is an AI-focused cloud platform that combines GPU infrastructure, storage, networking, orchestration, and operational tooling for training and serving AI workloads. It supports teams moving from model experiments to production systems, including reinforcement-learning and agent-development workflows.

www.hyperstack.cloud
Hyperstack is a cloud GPU platform for running AI and machine learning workloads, including training, inference, data analytics, and model development. It also provides AI Studio, virtual machines, and managed Kubernetes for deploying and operating GPU-backed workloads.

hyperbolic.xyz
Hyperbolic is an open-access GPU and AI cloud for deploying on-demand H100, H200, B200, and other GPU capacity. It supports experimentation, training, fine-tuning, inference, and production workloads through on-demand instances, reserved clusters, and Private Cloud infrastructure.
inference.net
Inference.net is infrastructure for running, monitoring, evaluating, training, and deploying production AI workloads. It helps AI-native teams observe model behavior, route traffic across providers, and improve cost, latency, reliability, and quality through connected workflows.

runpod.io
Cloud GPU infrastructure for AI development, training, inference, and batch workloads.