
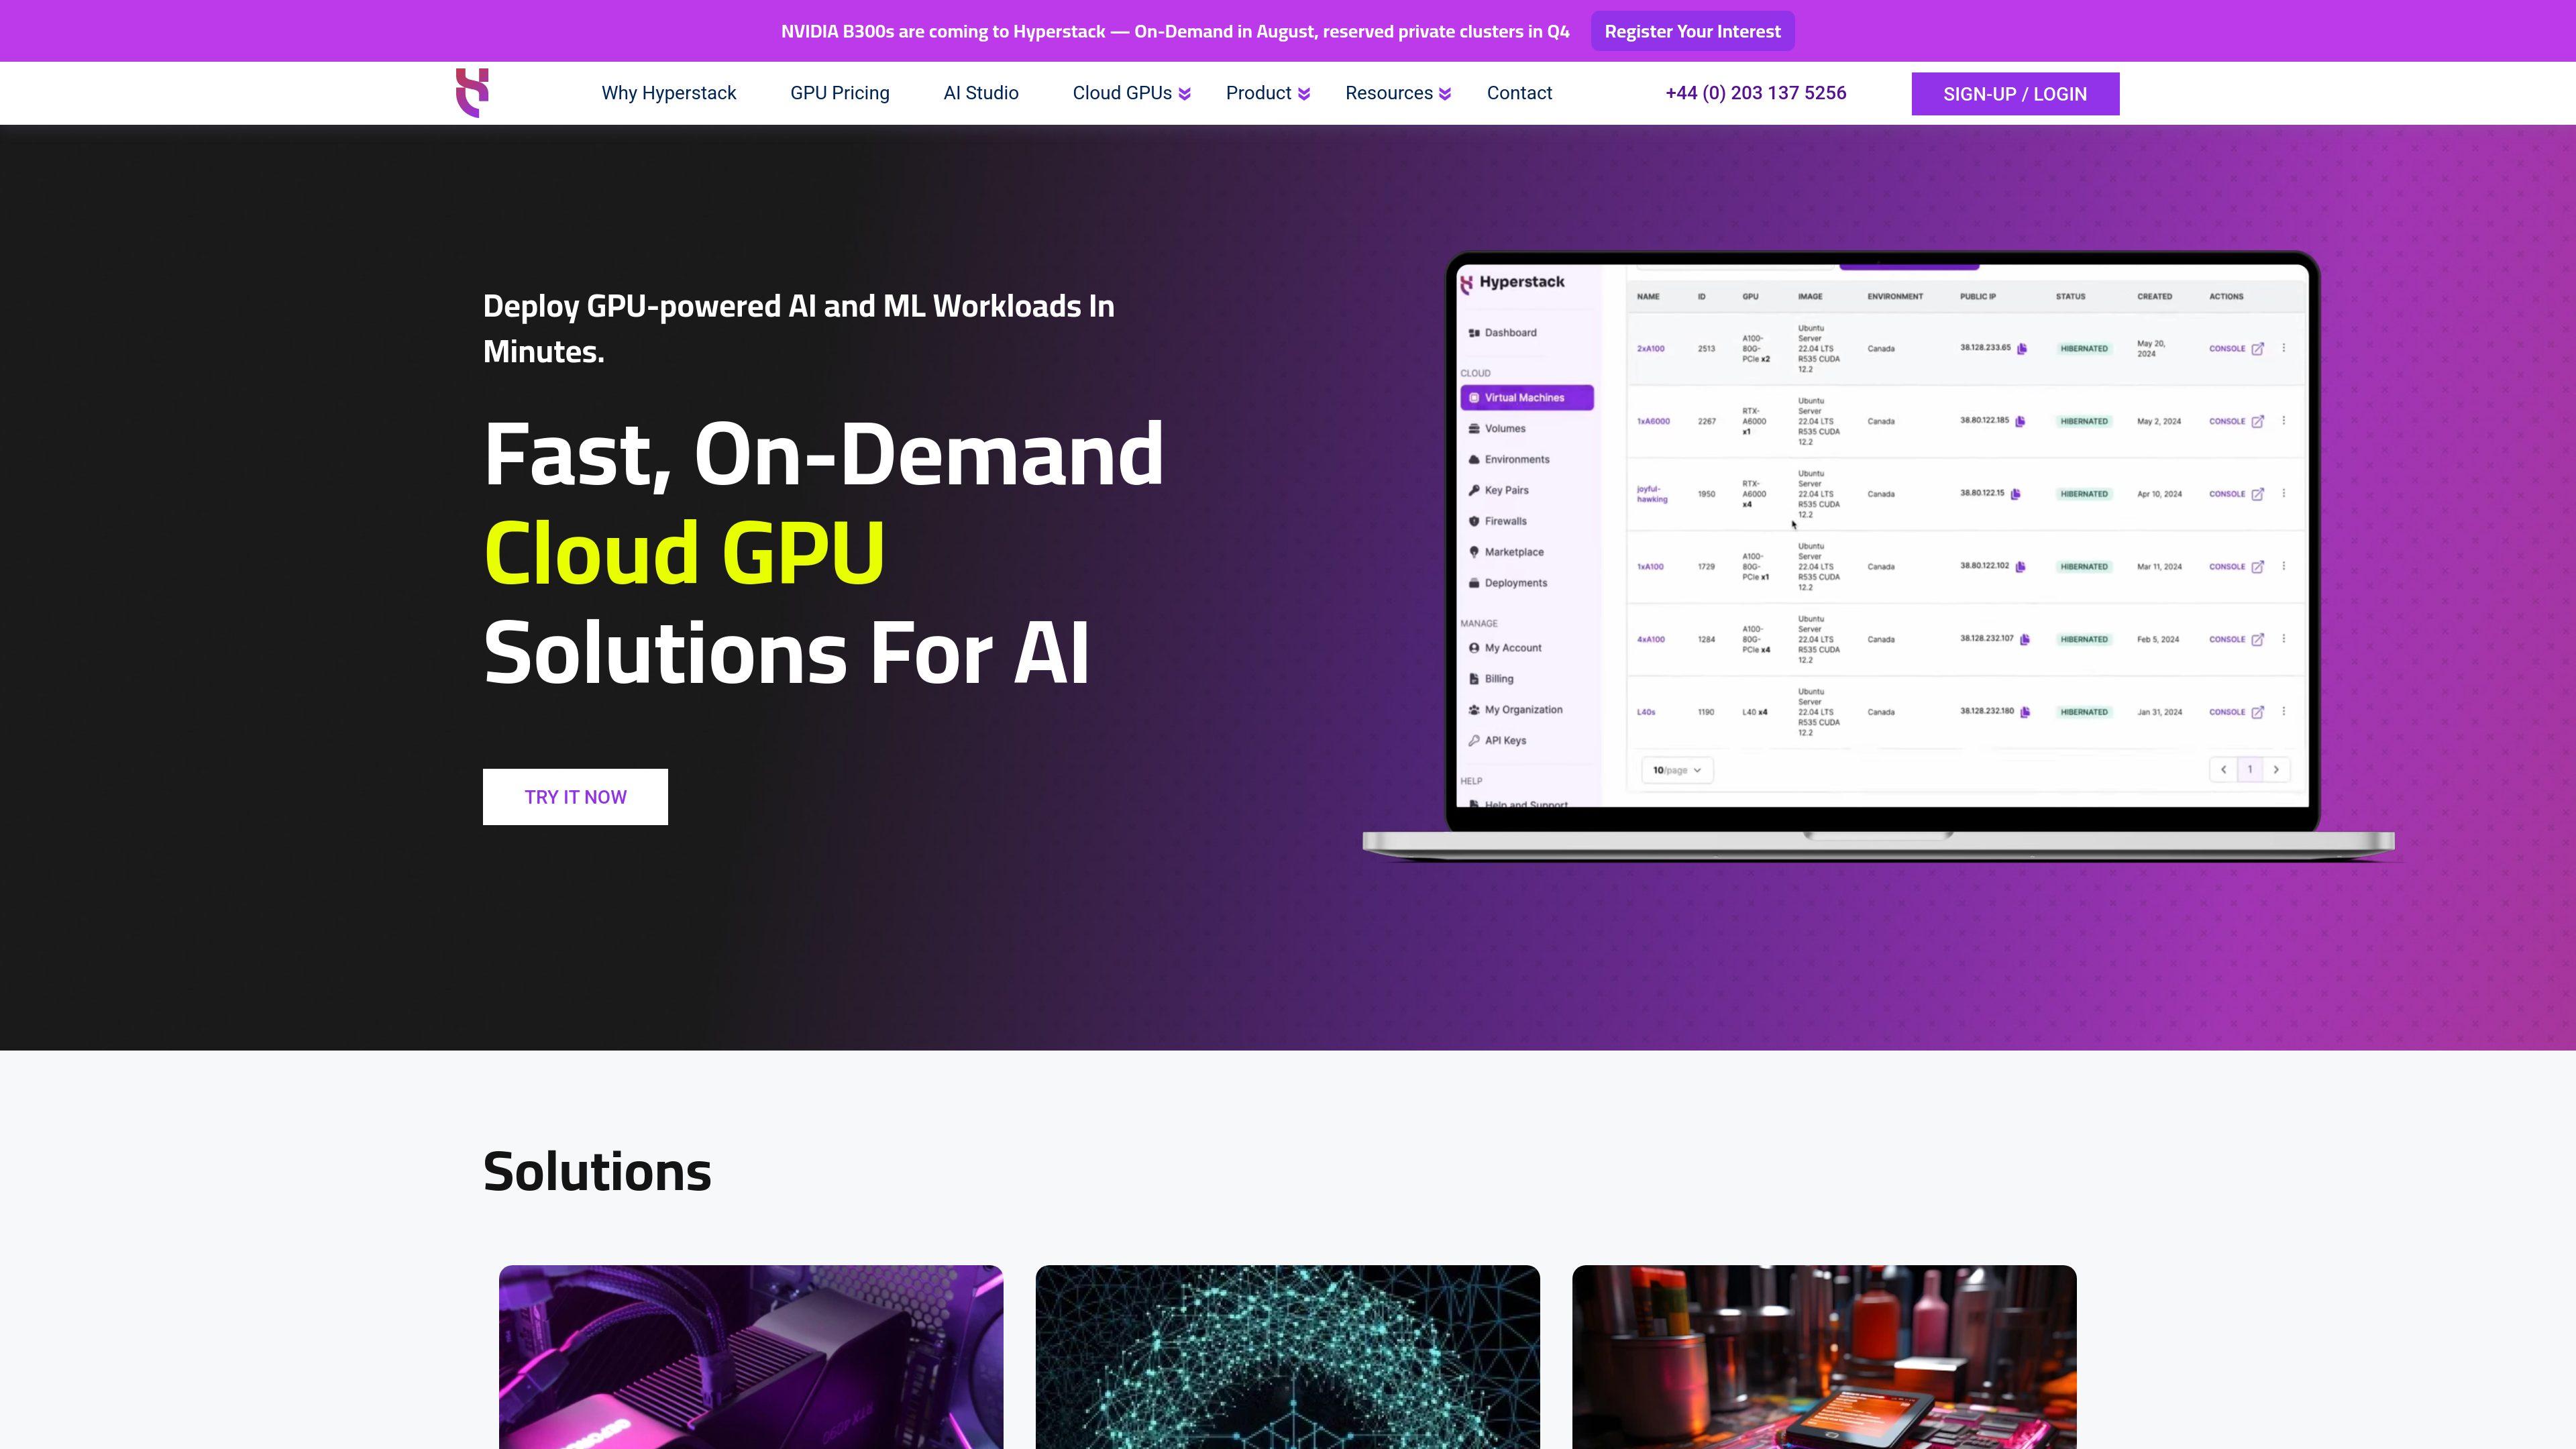
On-demand GPU virtual machines
Choose from listed NVIDIA GPU configurations, including H200, H100, RTX Pro 6000 SE, A100, L40, A6000, A4000, B200, and B300 options. GPU specifications vary by model and include published VRAM, CPU, and RAM limits.

Hyperstack is a cloud GPU platform for running AI and machine learning workloads, including training, inference, data analytics, and model development. It also provides AI Studio, virtual machines, and managed Kubernetes for deploying and operating GPU-backed workloads.
Hyperstack is a cloud GPU platform for AI, machine learning, deep learning, high-performance computing, rendering, simulations, data analytics, and virtual workstations. Users can provision GPU-backed virtual machines and configure environments for training, inference, model analysis, and other compute-intensive workloads.
The platform includes AI Studio, a full-stack environment for building and launching custom AI applications without managing the underlying infrastructure. AI Studio brings training, deployment, monitoring, and fine-tuning into one workflow, with token-based pricing for listed models and separate per-minute fine-tuning pricing.
Hyperstack also offers managed Kubernetes for virtual machine clusters, along with configurable GPU and CPU resources, storage, snapshots, role-based access control, APIs, and environment organization. Its cloud GPU pricing supports on-demand, reservation, and spot VM options, with usage billed by the minute for on-demand services. Infrastructure is listed in data centres in Europe and North America and is described as powered by renewable energy.
Choose from listed NVIDIA GPU configurations, including H200, H100, RTX Pro 6000 SE, A100, L40, A6000, A4000, B200, and B300 options. GPU specifications vary by model and include published VRAM, CPU, and RAM limits.
Build and launch custom AI applications in a managed environment that combines training, deployment, monitoring, and fine-tuning without requiring users to manage all infrastructure directly.
Use on-demand GPU VMs, reserve capacity at starting rates, or select listed spot VM options. On-demand usage is billed per minute, while longer-term reservations are invoiced monthly.
Deploy virtual machine clusters and automate software deployment, scaling, and management through an on-demand Kubernetes service with a free master node listed on the pricing page.
The platform lists one-click deployment, pre-configured SKUs, custom-build flavours, role-based access control, resource callbacks, environment organization, a first-class API, and human support.
Run neural-network and generative-AI training workloads on multi-GPU infrastructure, then use AI Studio’s fine-tuning workflow where appropriate. The platform lists dedicated fine-tuning pricing per minute.
Configure GPU environments for scalable inference, including generative AI, conversational AI, natural-language processing, image recognition, and speech-related workloads.
Process extensive datasets, support anomaly detection, and accelerate deep video analytics with GPU virtual machines or VM clusters.
Use GPU and HPC resources for scientific or medical research, engineering simulations, architecture, design visualization, and other compute-intensive analysis.
Use NVIDIA RTX-based SKUs for 3D visuals, game development, photorealistic rendering, and film production, or create high-performance virtual workspaces accessible remotely.
On-demand platform usage is billed per minute. The pricing page also lists hourly GPU rates, reservation starting rates, spot VM prices, CPU, storage, and other service charges. Longer-term reservations are invoiced monthly.
The pricing page states that bandwidth and data transfer have no additional charges. Other listed services, such as public IP addresses and storage, may have separate charges.
Hyperstack sends email notifications at 50%, 70%, 80%, 90%, and 100% balance depletion. After the balance is exhausted, resources may be scheduled for termination following a grace period; if the account is not recharged within one week, resources may be permanently deleted.
Yes. The site lists on-demand GPU VMs, reserved capacity with starting rates, and spot VM pricing for selected GPU models. Available models and prices vary by option.

www.coreweave.com
CoreWeave is an AI-focused cloud platform that combines GPU infrastructure, storage, networking, orchestration, and operational tooling for training and serving AI workloads. It supports teams moving from model experiments to production systems, including reinforcement-learning and agent-development workflows.
www.bentoml.com
Bento is an inference platform for packaging, deploying, optimizing, and operating AI and machine-learning models at scale. It supports open and custom models across cloud, on-premises, Kubernetes, and bring-your-own-cloud environments.

nebius.com
Nebius AI Cloud is a purpose-built cloud platform for developing, training, and serving AI workloads. It combines GPU and CPU compute, managed Kubernetes, MLOps tooling, and managed or serverless inference for teams scaling from experiments to production.

deepinfra.com
DeepInfra provides hosted machine-learning model inference and on-demand GPU instances for developers and teams. Its catalog covers text, image, audio, video, embedding, reranking, and other model workloads with pay-as-you-go pricing.

baseten.co
Baseten is an inference platform for deploying, serving, and scaling open-source, custom, and fine-tuned AI models. It supports managed cloud, self-hosted, hybrid, and dedicated deployments for teams running production AI workloads.
inference.net
Inference.net is infrastructure for running, monitoring, evaluating, training, and deploying production AI workloads. It helps AI-native teams observe model behavior, route traffic across providers, and improve cost, latency, reliability, and quality through connected workflows.