
Distributed Python execution
Ray Core provides tasks, actors, and objects for scaling Python applications, including simulations and backtesting.

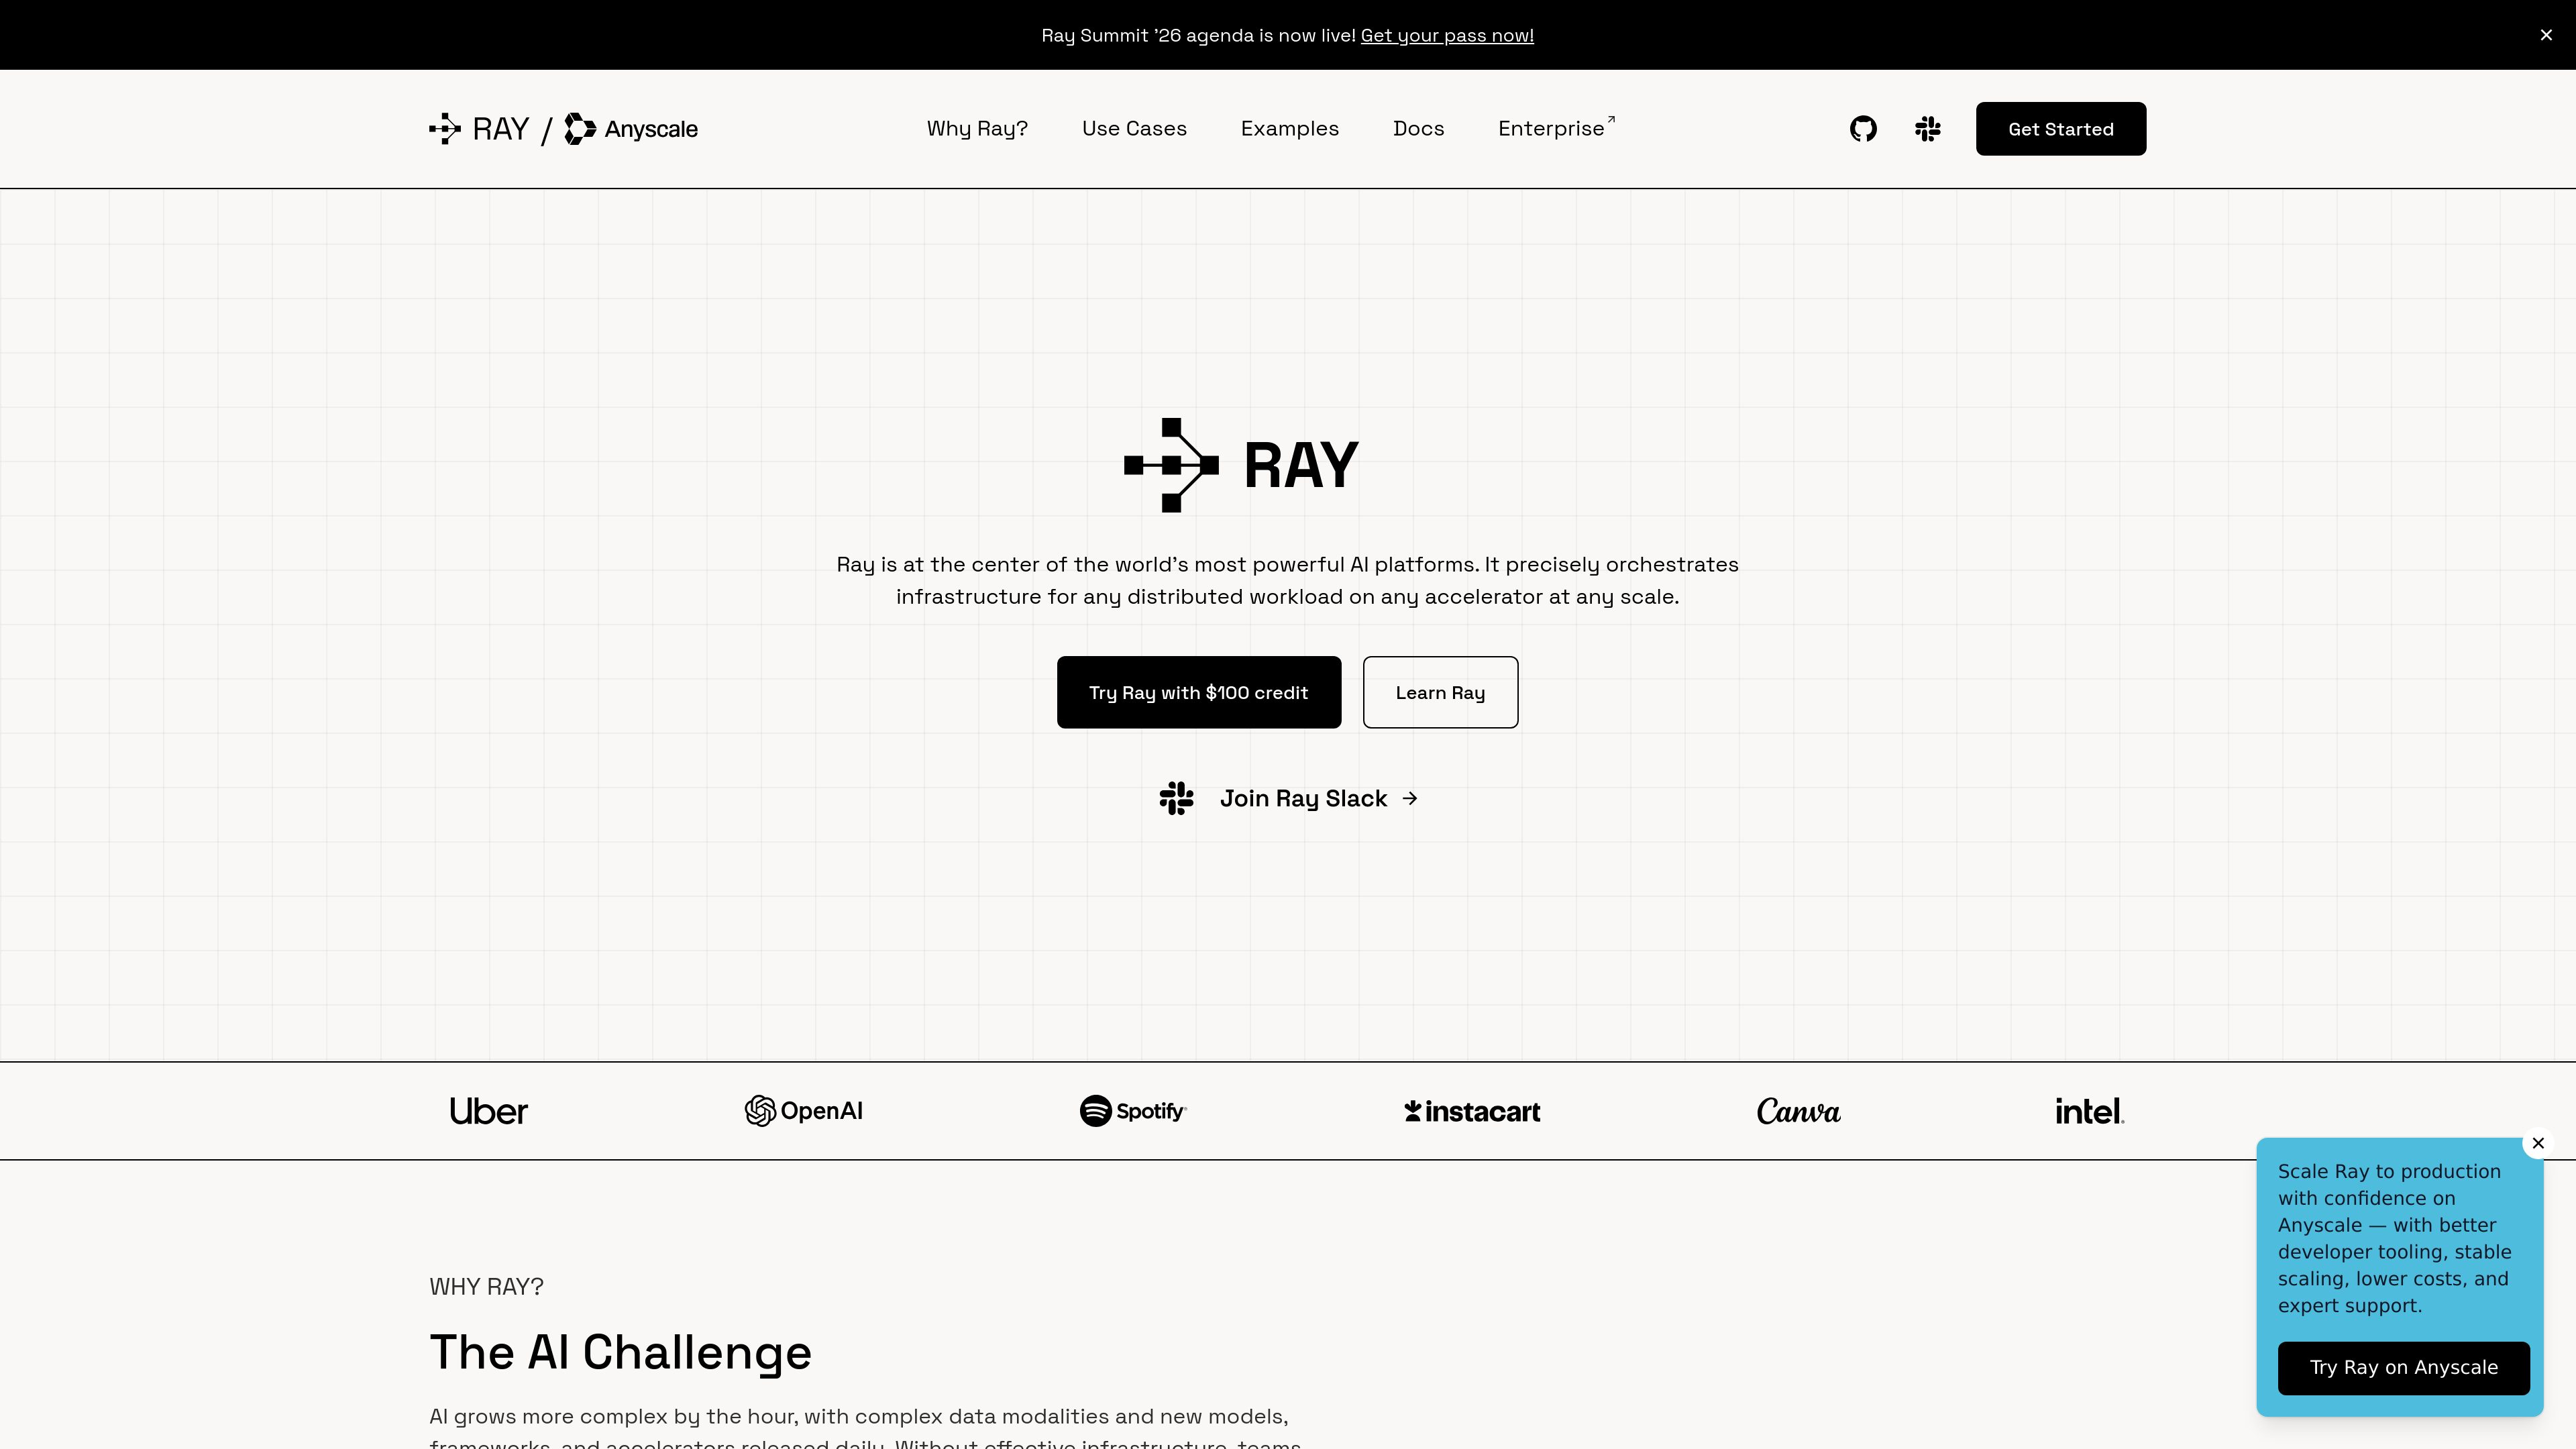
Ray is an open-source, Python-native framework for distributing and scaling AI, machine learning, and other compute-intensive workloads. It helps developers run workloads from a laptop to clusters with thousands of GPUs and supports data processing, training, serving, inference, and reinforcement learning.
Ray is an open-source, Python-native framework for managing, executing, and optimizing distributed compute. Its core primitives—tasks, actors, and objects—help developers distribute Python applications, while higher-level libraries support end-to-end AI workflows.
The platform is designed for varied workloads and infrastructure. It supports structured and unstructured data, including images, video, and audio; heterogeneous CPU and GPU resources; and model architectures ranging from traditional machine learning to multimodal and large language models. Ray can scale from local development environments to clusters with thousands of GPUs.
Ray’s workload coverage includes distributed model training, model serving, batch inference, reinforcement learning, generative AI, LLM inference, and LLM fine-tuning. Anyscale provides a fully managed option with governance, developer tooling, and expert support.
Ray Core provides tasks, actors, and objects for scaling Python applications, including simulations and backtesting.
Process structured and unstructured data such as images, video, and audio as part of distributed workflows.
Run training for foundation models, time-series models, XGBoost, and other AI/ML workloads with a stated one-line scaling path and framework compatibility.
Deploy models and business logic with independent scaling and fractional resource allocation, including LLMs, stable diffusion models, and object detection models.
Combine CPU and GPU resources in offline inference pipelines to improve accelerator utilization and manage compute costs.
Support production-oriented reinforcement learning through RLlib, as well as generative AI, RAG, LLM inference, and LLM fine-tuning workflows.
Developers can parallelize simulations, backtesting, and other Python programs that need more execution capacity than a single process or machine provides.
AI teams can distribute foundation-model, time-series, XGBoost, and other model-training workloads across available compute.
Teams can deploy models alongside business logic and scale components independently, with support for different model types and fractional resources.
Data and ML teams can build pipelines that use CPUs and GPUs together for high-volume inference jobs.
Teams can assemble workflows for multimodal models, RAG applications, LLM inference or fine-tuning, and distributed reinforcement learning.
Ray is an open-source framework for managing and distributing Python and AI workloads across compute resources. It includes core primitives for distributed applications and libraries for AI workflows.
The source describes support for distributed Python code, multimodal data processing, model training, model serving, batch inference, reinforcement learning, generative AI, LLM inference, and LLM fine-tuning.
Yes. Ray is described as supporting heterogeneous GPUs and CPUs, including pipelines that use both resource types for batch inference and independent resource scaling for serving.
Anyscale is described as a fully managed platform for running Ray. It adds enterprise governance, advanced developer tooling, and expert support to the open-source framework.
No pricing details are available from the supplied pricing URL, which returns a 404 page. The site does advertise a free Anyscale trial and a $100 credit offer, but it does not provide plan prices or limits in the collected content.
baseten.co
Baseten is an inference platform for deploying, serving, and scaling open-source, custom, and fine-tuned AI models. It supports managed cloud, self-hosted, hybrid, and dedicated deployments for teams running production AI workloads.

hyperbolic.xyz
Hyperbolic is an open-access GPU and AI cloud for deploying on-demand H100, H200, B200, and other GPU capacity. It supports experimentation, training, fine-tuning, inference, and production workloads through on-demand instances, reserved clusters, and Private Cloud infrastructure.
chutes.ai
Chutes is a decentralized, serverless AI inference platform for deploying, running, and scaling open-source models. Developers can access hosted models through an API or deploy private custom workloads on confidential GPU capacity.

vllm.ai
vLLM is an inference and serving engine for large language models, designed for high-throughput, memory-efficient deployment. It helps developers and infrastructure teams run open-source models through an OpenAI-compatible API across supported compute platforms.

nebius.com
Nebius AI Cloud is a purpose-built cloud platform for developing, training, and serving AI workloads. It combines GPU and CPU compute, managed Kubernetes, MLOps tooling, and managed or serverless inference for teams scaling from experiments to production.

www.coreweave.com
CoreWeave is an AI-focused cloud platform that combines GPU infrastructure, storage, networking, orchestration, and operational tooling for training and serving AI workloads. It supports teams moving from model experiments to production systems, including reinforcement-learning and agent-development workflows.