
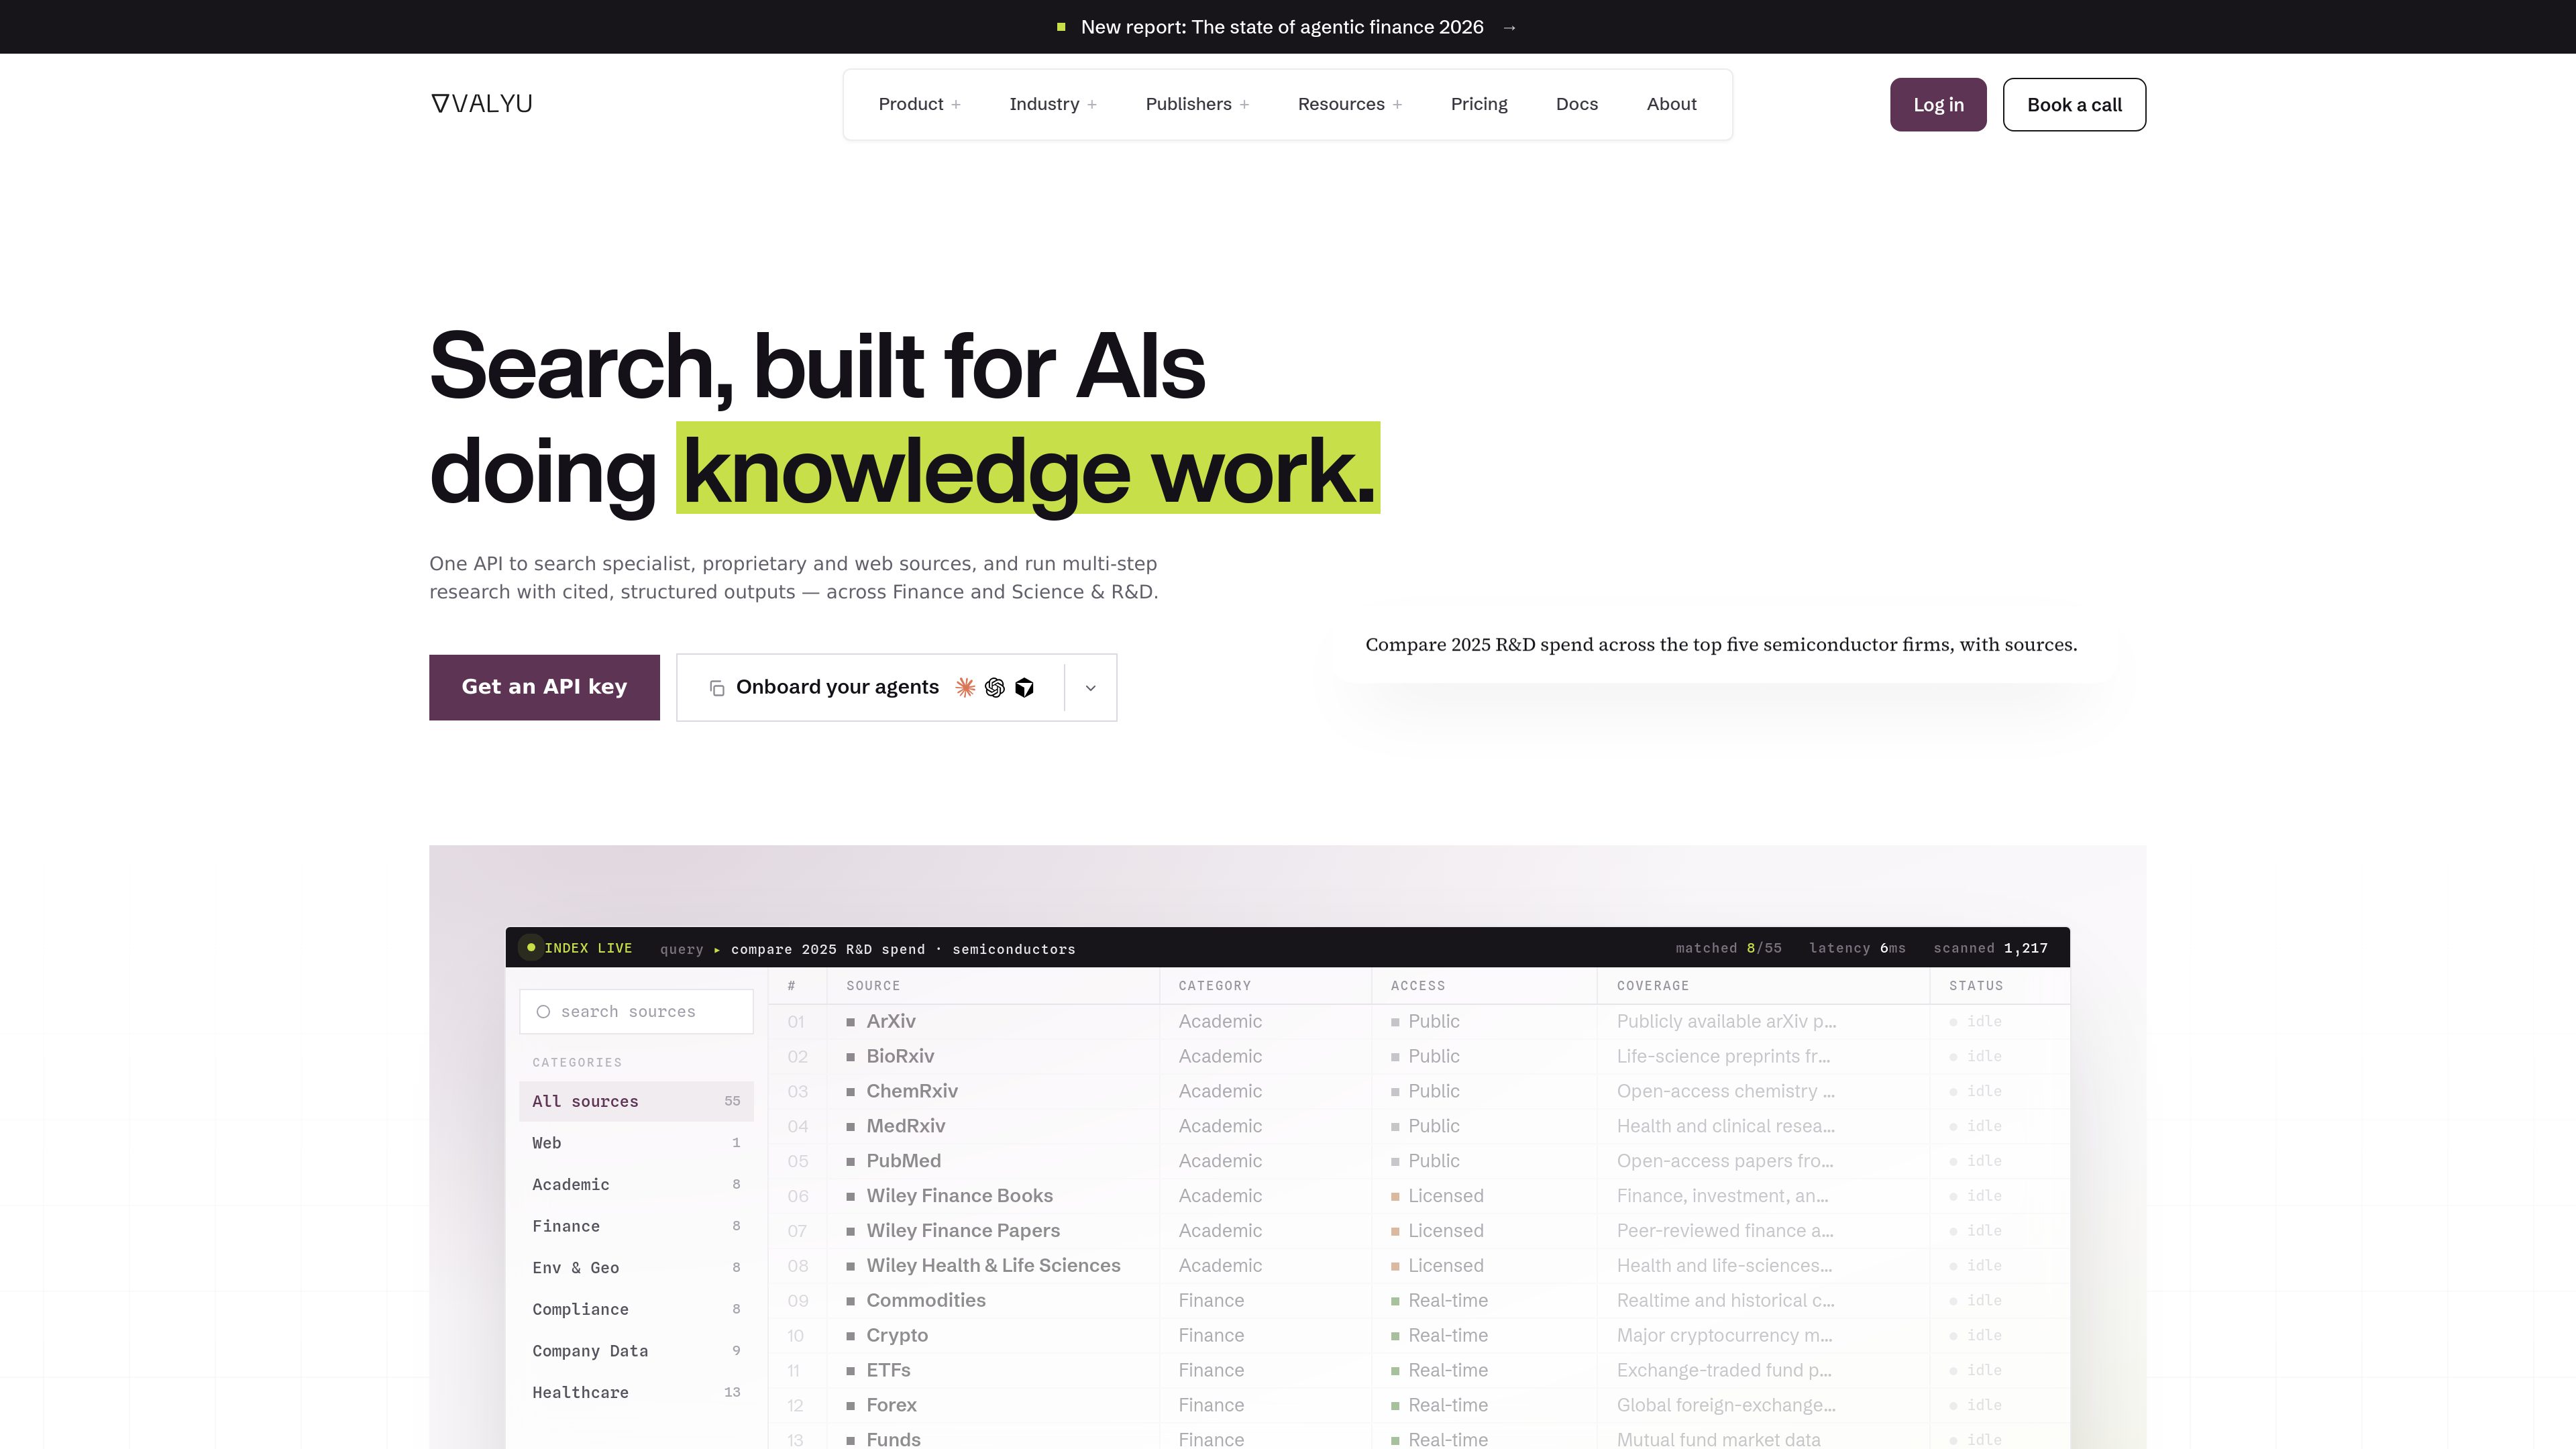
Unified search across specialist sources
Query the open web and datasets covering finance, science, healthcare, company information, compliance, economics, and other domains through one API.

Valyu provides search, content extraction, answer, and DeepResearch APIs for AI agents and knowledge-work applications. It combines open-web results with financial, scientific, biomedical, legal, economic, and other specialist sources, returning cited content and research outputs.
Valyu is an API platform for AI-powered search and research. Its Search API lets agents query the open web alongside specialist and licensed sources such as academic papers, SEC filings, market data, clinical trials, patents, and economic indicators. Results can include ranked URLs, full-text excerpts, content, source metadata, and relevance scores.
The platform also provides Contents, Answer, and DeepResearch APIs. Contents extracts clean material from URLs, while Answer combines search with AI synthesis. DeepResearch performs multi-step investigation and returns a cited report, with research depth configurable for workflows that may run from several minutes to several hours. Valyu is positioned for AI products, research workflows, and research desks that need traceable information rather than a standalone web-search box.
Query the open web and datasets covering finance, science, healthcare, company information, compliance, economics, and other domains through one API.
Submit questions such as searches for clinical trials or research topics without needing ticker symbols or database identifiers.
Receive ranked results with full-text excerpts, source metadata, relevance scores, and structured data suitable for agent context windows and RAG pipelines.
Convert pages into clean Markdown, JSON, summaries, or screenshots; structured extraction can follow a defined JSON schema.
DeepResearch follows leads across multiple searches and produces reports with citations, while Answer provides search plus AI synthesis for question-answering workflows.
Combine filings, earnings, market data, company financials, and relevant web reporting for due diligence, monitoring, financial modelling, and thesis work.
Search papers, preprints, compounds, clinical trials, patents, regulatory information, and related sources for literature reviews or drug and target research.
Build screening, event-triggered research, thesis monitoring, bear-case preparation, and supply-chain exposure analysis into a desk’s existing chats, agents, or internal tools.
Supply AI applications with retrieved excerpts, clean page content, and source metadata for agent tool calls, ingestion, and question-answering interfaces.
Search can return ranked URLs, full-text excerpts, content, structured data, and source metadata. Contents can return extracted Markdown, JSON, summaries, or screenshots; Answer returns synthesized responses; DeepResearch returns cited research reports.
Search retrieves relevant sources in real time. DeepResearch plans and performs a multi-step investigation, following leads and synthesizing the evidence into a report. Its research modes range from fast investigations to runs lasting up to several hours.
The site lists open-web, academic, financial, biomedical, company, compliance, economic, environmental, healthcare, legal, prediction-market, and transportation sources. Availability can vary by plan; the pricing page describes broader access on higher paid tiers.
Developers can use the API in their own tools, while the site also documents connectors for Claude and ChatGPT. Enterprise offerings include private indexes, SSO with SAML or OIDC, scoped tenant isolation, zero-data-retention options, and US, EU, or UK deployment options.

context.dev
Context.dev Answers researches the web and returns sourced results in a JSON structure you define. It supports fast responses for shorter tasks and ultra mode for deeper research.

www.nimbleway.com
Nimble Web Search Agents are self-learning research agents that search and crawl the live web for domain-specific answers, enrichment, and structured datasets. They are designed for teams building repeatable research workflows where the schema, search scope, and output format need to be controlled.

www.diffbot.com
Diffbot transforms unstructured public web content into structured data for AI applications. Its APIs and agent skills support web search, page extraction, crawling, entity resolution, natural-language processing, and Knowledge Graph research.

you.com
ウェブ、ニュース、金融業務向けの検索・コンテンツ抽出・引用付き調査API。

vespa.ai
Vespa is an AI search platform for building search, retrieval-augmented generation, recommendation, personalization, and agent applications over text, vectors, tensors, and structured data. It is designed for developer teams that need configurable ranking and distributed operation at production scale.

rayyan.ai
系統的レビューと文献レビューのためのAIプラットフォーム