AIデータ抽出

AIデータ抽出ツールで、文書・Webページ・画像・PDFから情報を構造化。調査や業務の自動化、データ分析を効率化できます。

データと分析

このコレクションを探索

製品

JPG to Excel preview
JPG to Excel logo

JPG to Excel

AI OCR

JPG to Excelは画像やスキャンした表を編集可能なExcelまたはCSVに変換します。

You.com preview
You.com logo

You.com

AI検索API

ウェブ、ニュース、金融業務向けの検索・コンテンツ抽出・引用付き調査API。

AI Data Platform (ADAP) preview
AI Data Platform (ADAP) logo

AI Data Platform (ADAP)

AIデータ抽出

AppenのAI Data Platform (ADAP)は、マルチモーダルAIデータのアノテーション、微調整、アライメント、評価に対応。

Thunderbit preview
Thunderbit logo

Thunderbit

AIウェブスクレイパー

Chrome拡張機能とAPIでWebページを構造化データに変換するAIスクレイピング

Upstage AI preview
Upstage AI logo

Upstage AI

AIドキュメント抽出

Upstage AIは、複雑なファイルの変換、構造化データの抽出、文書ワークフローの構築を支援する文書処理ツールと大規模言語モデルを提供します。API、Studio、AWS Marketplace、オンプレミスに対応。

Image to Text preview
Image to Text logo

Image to Text

AIデータ抽出

画像やPDFを編集可能なテキストに変換する無料Web OCR

fileAI preview
fileAI logo

fileAI

AIドキュメント抽出

fileAIは非構造化ファイルを構造化・検証済みデータに変換し、企業のワークフローを自動化します。

Evolution AI preview
Evolution AI logo

Evolution AI

AIデータ抽出

請求書・銀行取引明細・財務諸表向けAIデータ抽出プラットフォーム

Jiva.ai preview
Jiva.ai logo

Jiva.ai

AIモデルデプロイメント

自社データでカスタムAIモデルを学習できるノーコード基盤

Page to Markdown preview
Page to Markdown logo

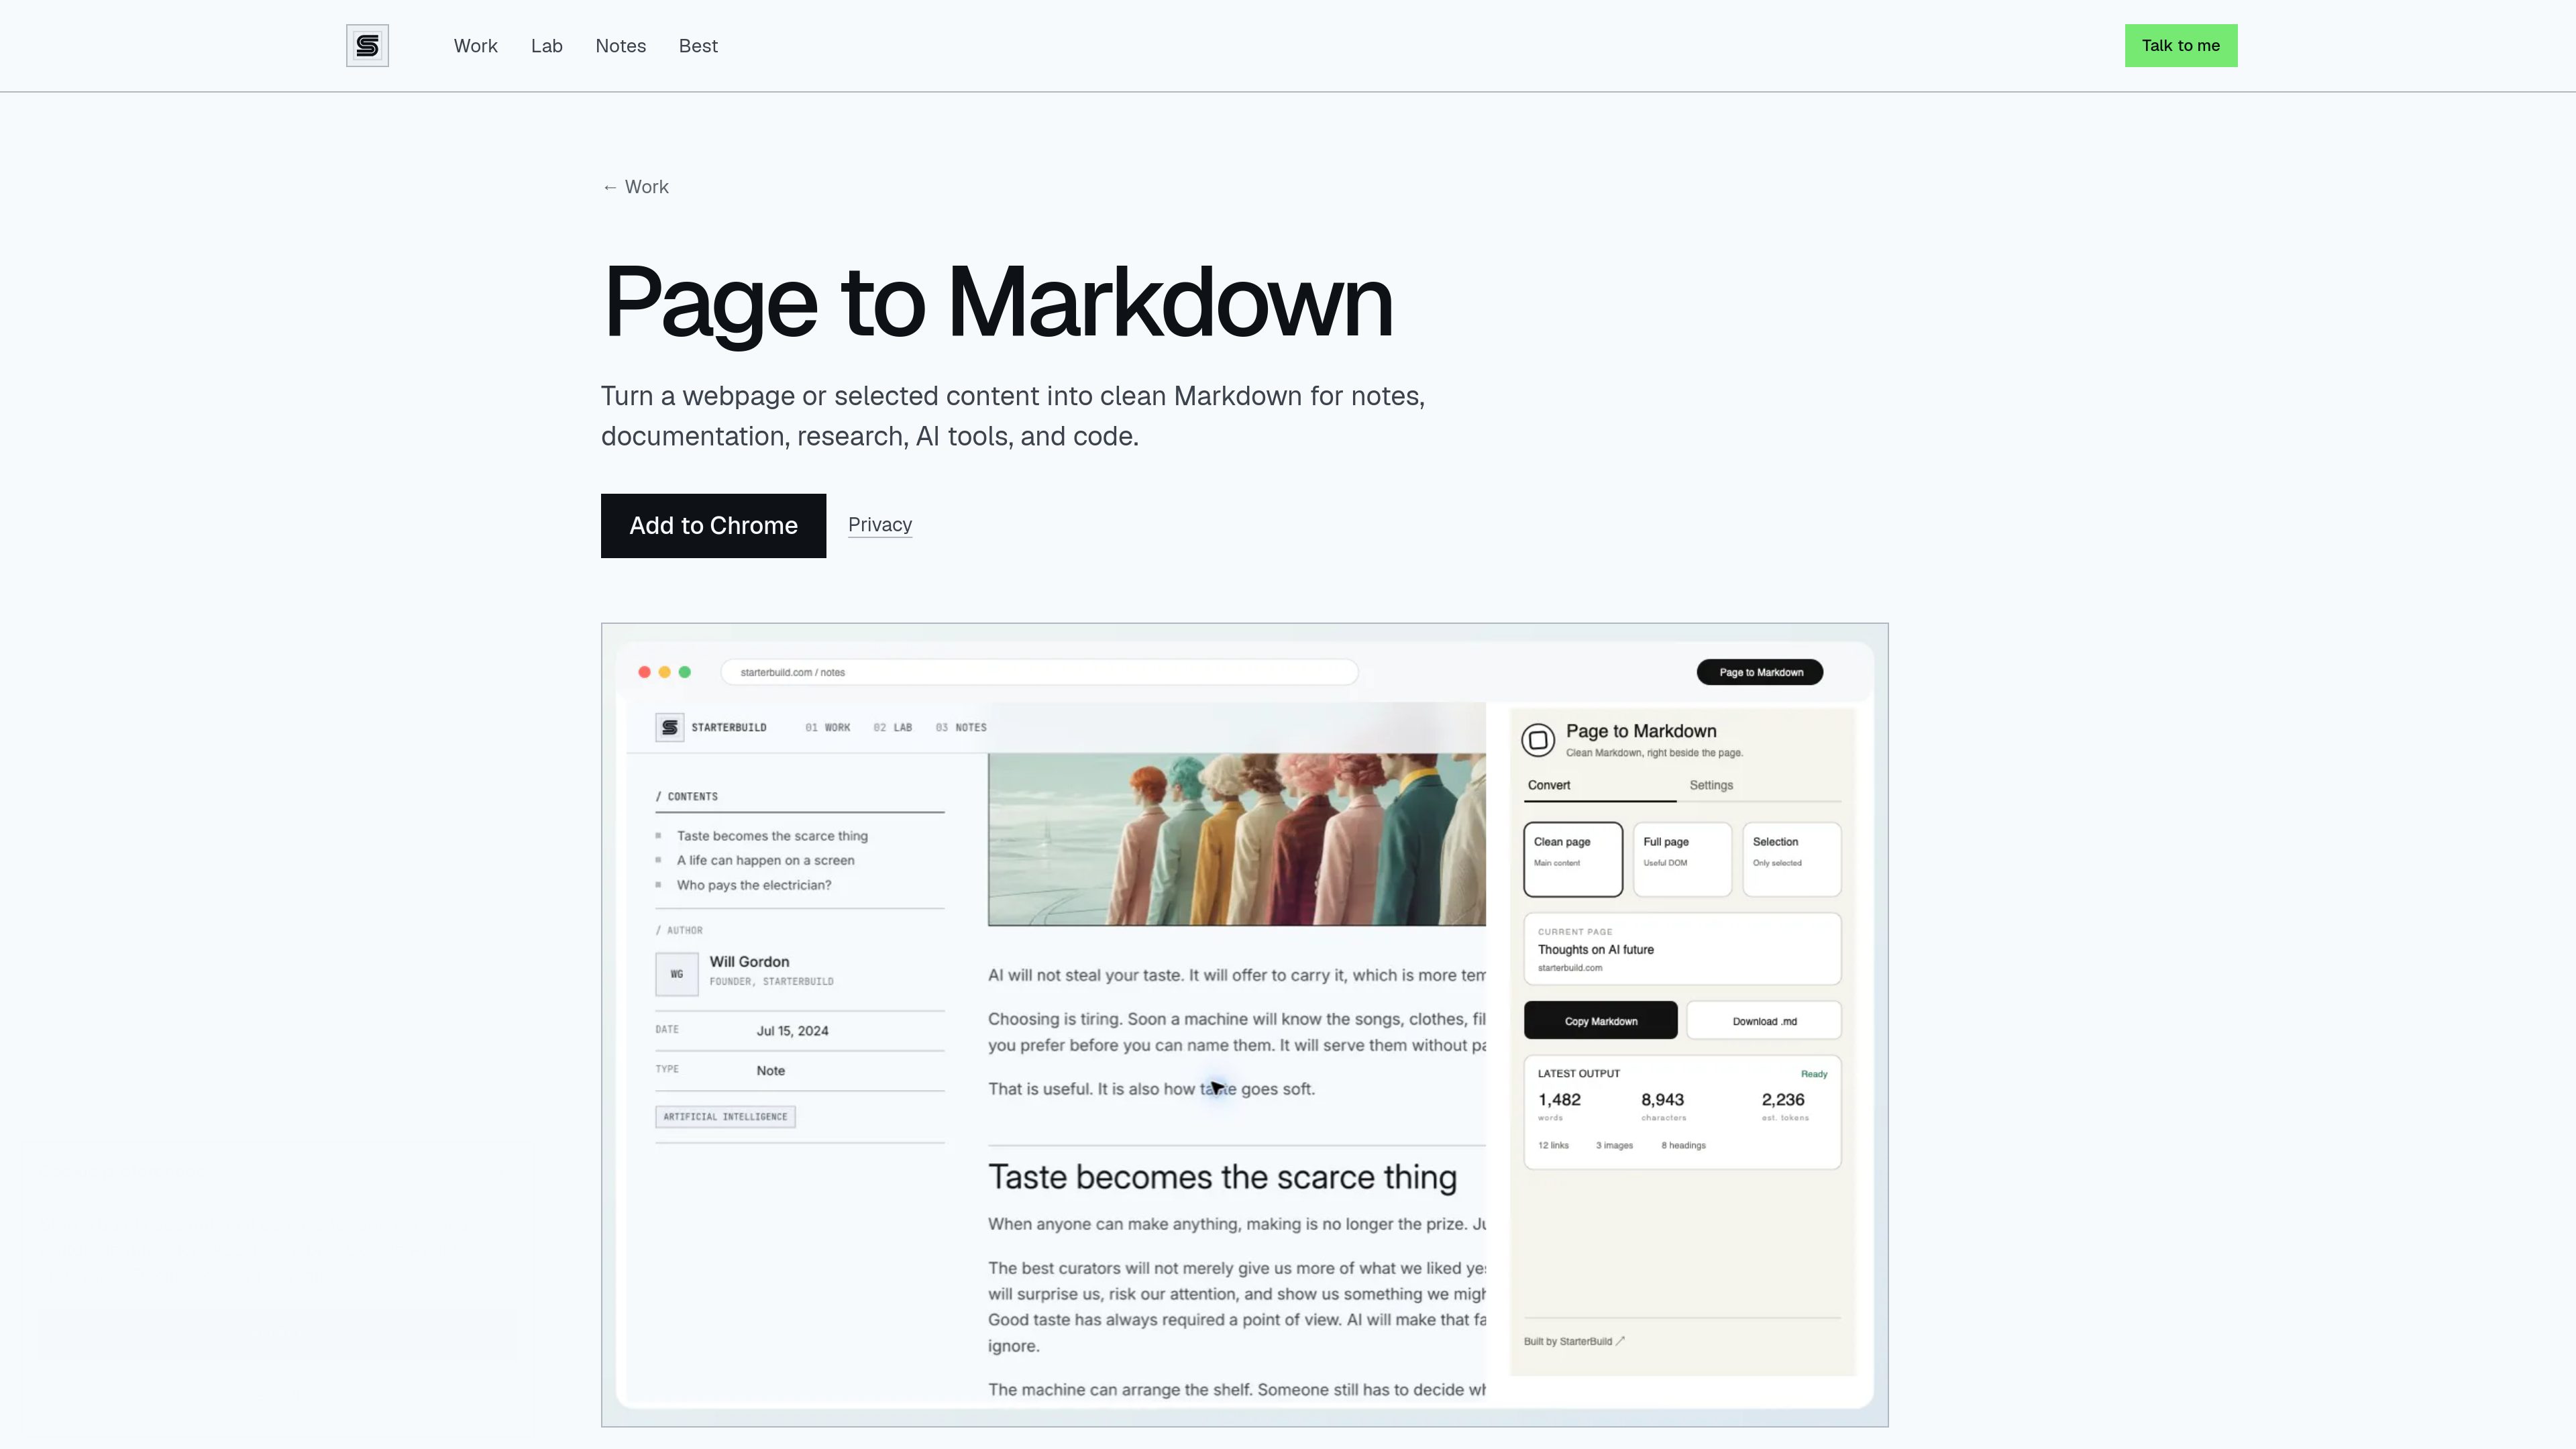
Page to Markdown

AIデータ抽出

Page to Markdown is a free Chrome extension that converts webpages or selected content into clean, usable Markdown. It is designed for notes, documentation, research, AI tools, and coding workflows.

BrowserAct preview
BrowserAct logo

BrowserAct

AIブラウザ自動化

BrowserAct is a no-code AI web scraping and browser automation platform that builds reusable Bots from plain-language data requests. It helps teams collect structured, refreshed web data in the cloud or give local AI agents a browser layer for web tasks.

Valyu preview
Valyu logo

Valyu

AIデータ抽出

Valyu provides search, content extraction, answer, and DeepResearch APIs for AI agents and knowledge-work applications. It combines open-web results with financial, scientific, biomedical, legal, economic, and other specialist sources, returning cited content and research outputs.

LlamaParse preview
LlamaParse logo

LlamaParse

AIデータ抽出

LlamaParse is an AI document parsing platform that converts complex PDFs, office files, spreadsheets, images, and other documents into structured, AI-ready data. It is designed for developers and enterprise teams building retrieval, extraction, and document automation workflows.

Amazon Textract preview
Amazon Textract logo

Amazon Textract

AIデータ抽出

Amazon Textract is an AWS machine learning service that uses optical character recognition to extract printed text, handwriting, layout elements, and data from scanned documents. It helps teams automate document processing for PDFs, images, forms, tables, invoices, receipts, and similar business records.
GraphRAG preview
GraphRAG logo

GraphRAG

AIデータ抽出

GraphRAG is a research project and data pipeline for extracting structured information from unstructured text with language models, then using graph-based context to support question answering over private data.

Instructor preview
Instructor logo

Instructor

AIデータ抽出

Instructor is a developer library for extracting structured, validated data from large language models. It uses Pydantic schemas, automatic retries, streaming, and a consistent interface across cloud, local, and routed LLM providers.

Diffbot preview
Diffbot logo

Diffbot

AIデータ抽出

Diffbot transforms unstructured public web content into structured data for AI applications. Its APIs and agent skills support web search, page extraction, crawling, entity resolution, natural-language processing, and Knowledge Graph research.