Prime Intellect logo

Prime Intellect

Freemium
訪問

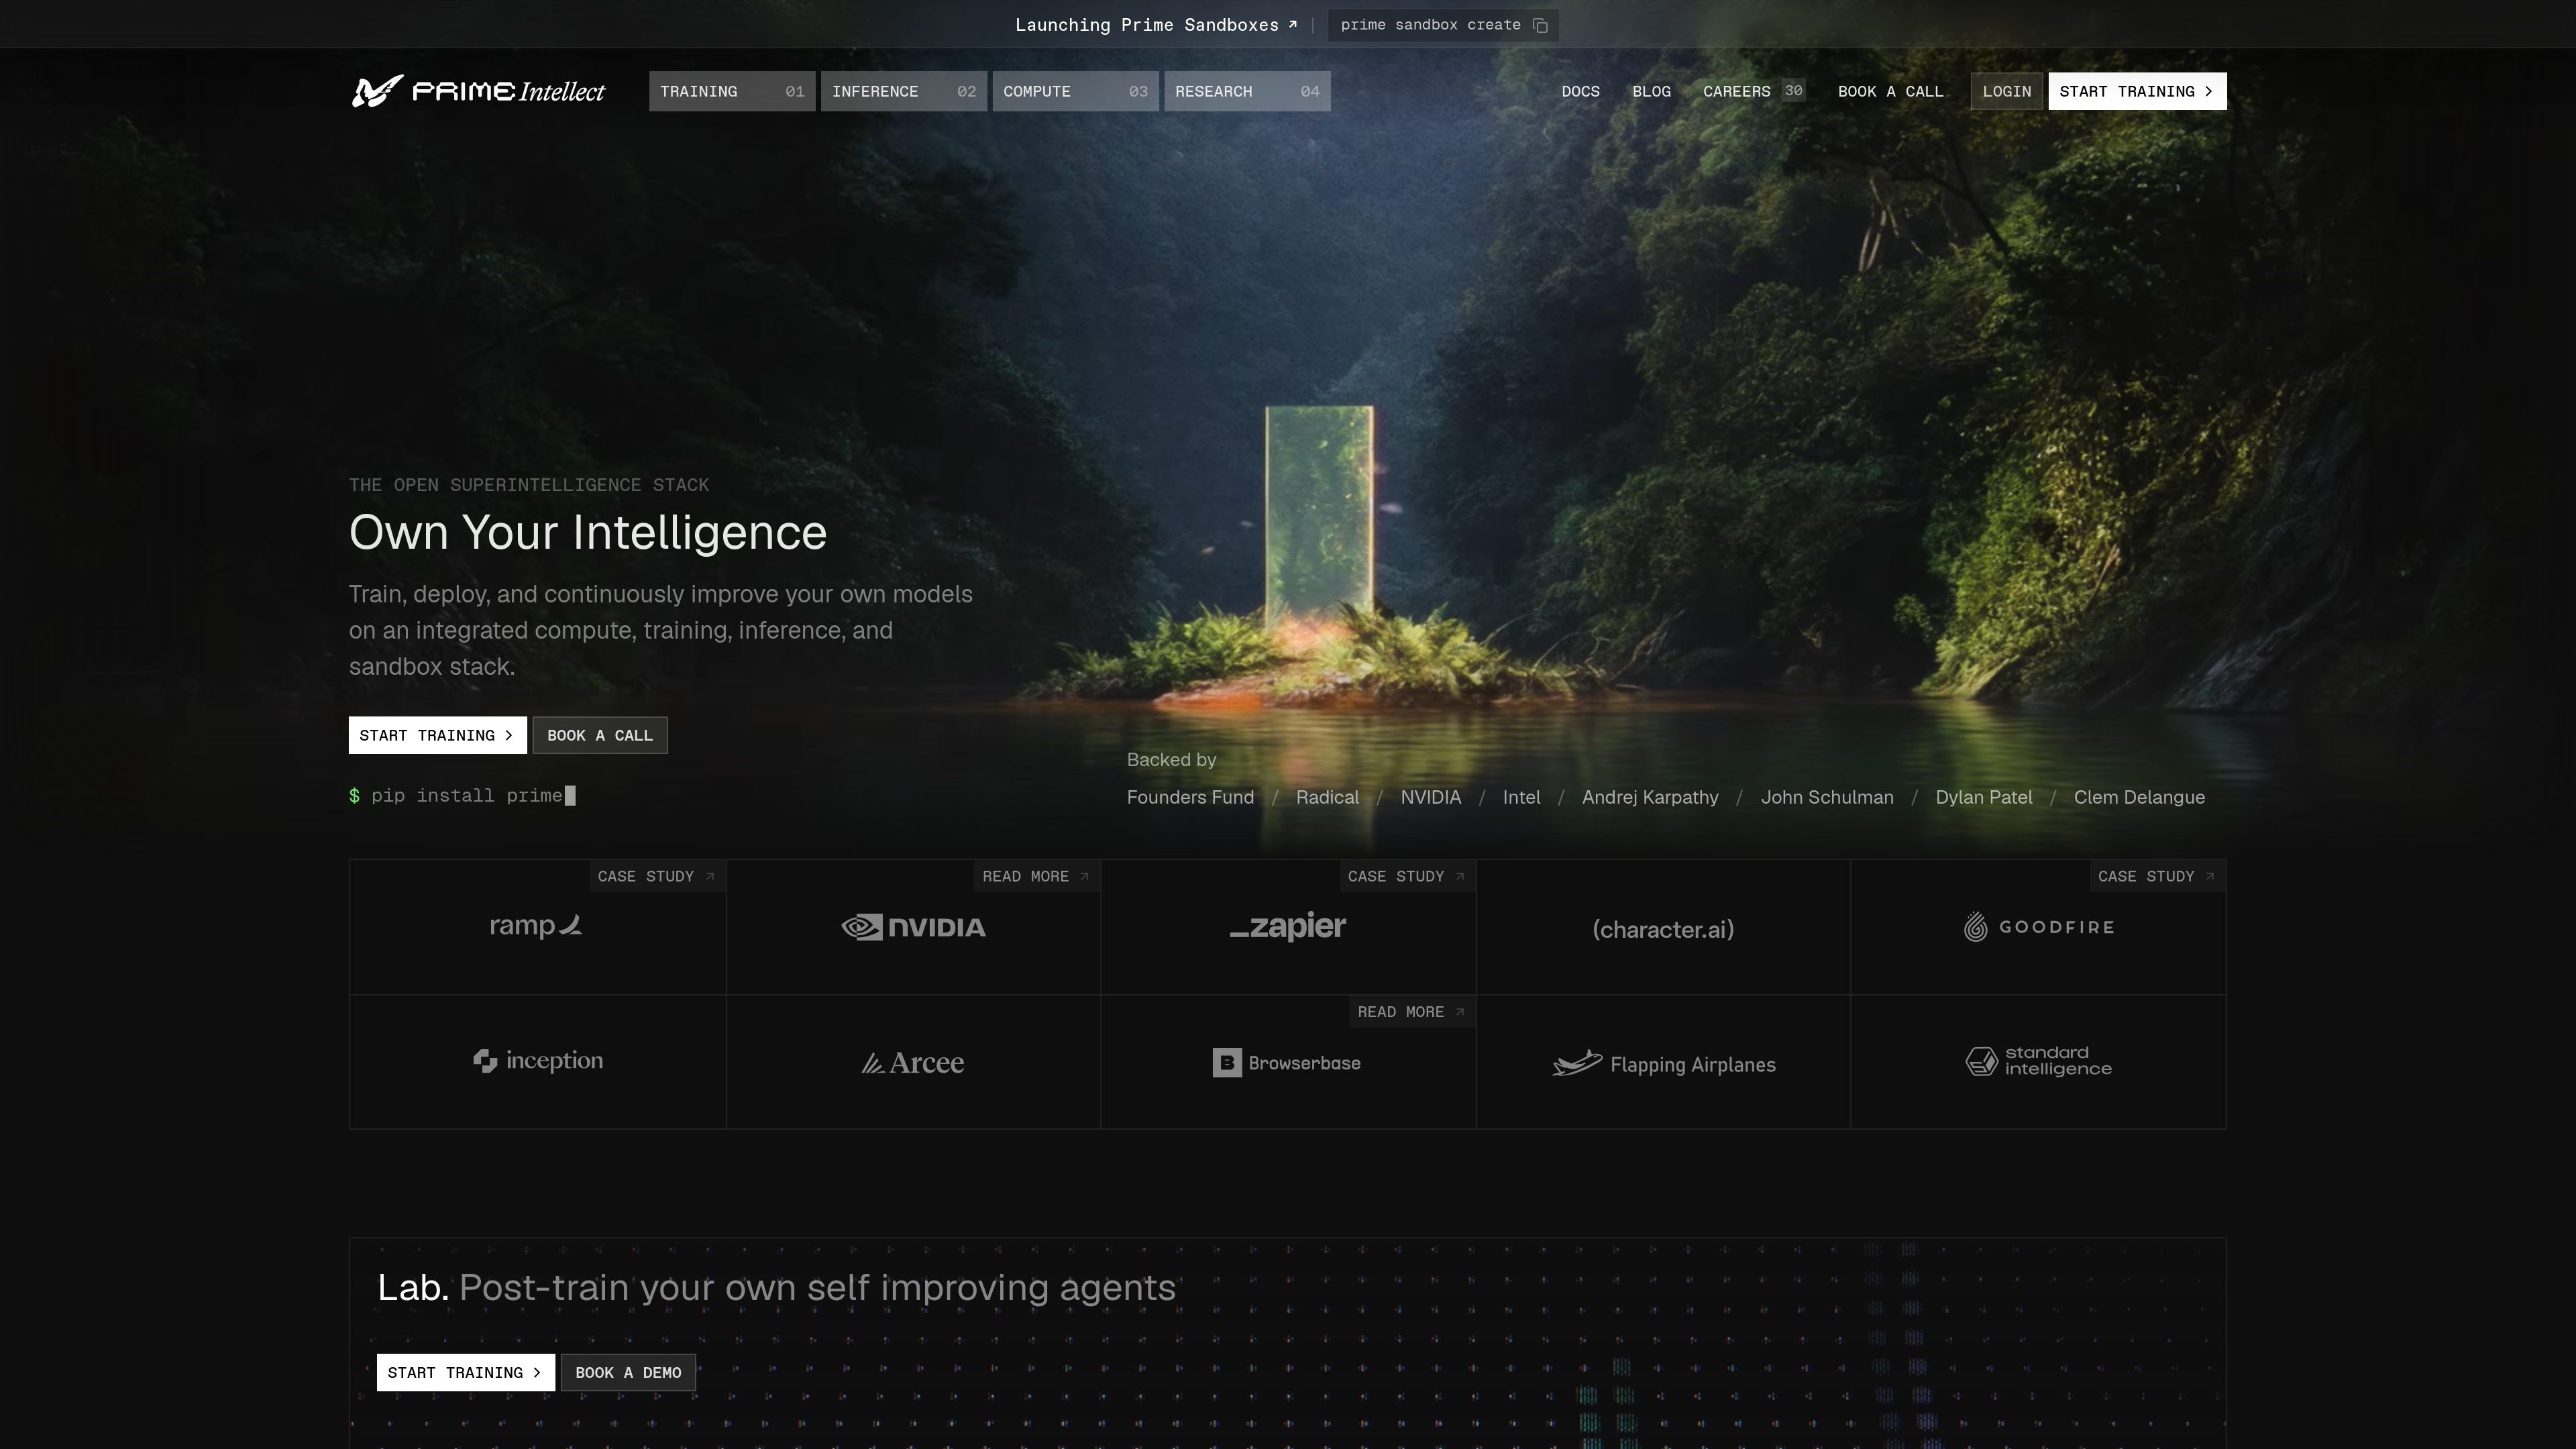
Prime Intellect is an open stack for training, evaluating, deploying, and improving AI models and agents. It combines RL environments, hosted evaluations and training, model inference, GPU compute, and isolated sandboxes for research and production workflows.

Prime Intellectとは?

Prime Intellect is an AI infrastructure and research platform for teams building, evaluating, and improving models and agents. Its stack combines reinforcement-learning environments, hosted evaluations, managed training, inference, GPU compute, and isolated microVM sandboxes.

The core workflow connects environment development, evaluation, training, and deployment. Users can create and manage RL environments through the Prime CLI, benchmark models on hosted infrastructure, train models in managed workflows, and serve models through Prime-hosted infrastructure or a common inference gateway. The platform also provides access to community environments and compute resources for experimentation and larger-scale workloads.

Prime Intellectでできること

RL environment development

The Prime CLI supports an init, develop, eval, and push workflow for turning tasks into RL environments. Prime Intellect’s open-source Verifiers library provides modular components for creating environments and training language-model agents.

Hosted evaluations

Run model evaluations without managing the evaluation infrastructure. The service supports benchmarking across open-source models and provides public leaderboard functionality for comparing results.

Managed RL training

Train large-scale models on RL environments through managed workflows with visibility and control over experiments. Prime Intellect also describes hands-on support from its applied research team.

Model inference

Run Prime-hosted models, including GLM-5.3, on Prime infrastructure or access models from third-party providers through the Prime Inference Gateway. Both routes use one OpenAI-compatible API.

GPU compute and cluster access

Use on-demand GPU capacity from 1 to 256 GPUs across clouds, with SLURM and Kubernetes orchestration, InfiniBand networking, and Grafana monitoring. Larger reserved clusters can be requested through quotes from more than 50 providers.

Isolated agent sandboxes

Run workloads in Linux microVMs with Docker Compose, background jobs, kernel-dependent workloads, and bring-your-own Docker images. Sandboxes support parallel rollouts and integrate with Verifiers and Prime-RL.

利用シーン

“Build and validate agent environments”

Research and engineering teams can encode tools, tasks, datasets, and reward logic as RL environments, run baseline evaluations, inspect results, and push revisions through the Prime CLI.

“Turn benchmarks into improvement loops”

Teams can use the same environment for evaluation and RL training. Zapier used this workflow for AutomationBench, examining rollout traces and live metrics to detect reward hacking before continuing training.

“Train specialist subagents”

Product teams can train focused agents for narrow workflows instead of relying only on general-purpose models. Ramp used a custom spreadsheet environment to train FastAsk for financial workbook retrieval.

“Run large-scale agent experiments”

Researchers can combine managed training, GPU capacity, and isolated microVM sandboxes for parallel rollouts and workloads that require Docker, background processes, or full Linux environments.

“Serve and compare models”

Teams can evaluate models on their own tasks, access Prime-hosted or third-party models through the OpenAI-compatible gateway, and request dedicated serving capacity when their latency, reliability, or custom-model requirements call for it.

よくある質問

What types of work does Prime Intellect support?

The platform supports RL environment development, hosted model evaluations, managed training, model inference, GPU compute, and sandboxed agent workloads. The documented workflows focus on training and improving models and agents.

Can the same environment be used for evaluation and training?

Yes. Prime Intellect’s case study materials describe using the same environment for baseline evaluation, reward debugging, and RL training. This was the workflow used by Zapier for AutomationBench.

What are Prime Sandboxes?

Prime Sandboxes are isolated Linux microVM environments for agentic training. They support Docker Compose, background jobs, kernel-dependent workloads, parallel rollouts, and Docker images supplied by the user.

How is inference accessed?

Prime-hosted models run on Prime infrastructure, while the Prime Inference Gateway provides access to models served by third-party providers. The site describes one OpenAI-compatible API for both routes.

What sandbox usage rates are listed?

The Sandboxes page lists usage-based rates of $0.02 per vCPU-hour, $0.0125 per GiB of memory-hour, and $0.0002 per GiB of disk-hour. The page states that these prices are valid through December 22; broader platform pricing was not available on the supplied pricing page.

クイック情報

Category
AI infrastructure and machine-learning research platform
Primary workflows
RL environment development, evaluation, training, inference, and agent sandboxing
Environment Hub
More than 2,500 open-source RL environments listed on the site
Inference interface
One OpenAI-compatible API for Prime-hosted and third-party models
Compute access
On-demand access to 1–256 GPUs, plus quoted larger reserved clusters
Sandbox pricing
Usage-based rates are listed for vCPU, memory, and disk; prices are stated as valid through December 22 on the source page

Prime Intellectの代替品

Sequel logo

Sequel

sequel.sh

Sequel is an AI data analyst and secure data layer for agents. It connects databases, warehouses, analytics platforms, spreadsheets, and SaaS tools so Claude, Cursor, ChatGPT, and other MCP-capable agents can answer questions using shared data connections and definitions.

Salad logo

Salad

salad.com

AIワークロード向けの分散型GPUクラウド、従量課金制

EdgeOne Makers logo

EdgeOne Makers

pages.edgeone.ai

Tencent EdgeOne基盤でWebアプリとAIエージェントをデプロイし、ホスティング、関数、ストレージ、内蔵ツールを統合。

Hyperstack logo

Hyperstack

www.hyperstack.cloud

Hyperstack is a cloud GPU platform for running AI and machine learning workloads, including training, inference, data analytics, and model development. It also provides AI Studio, virtual machines, and managed Kubernetes for deploying and operating GPU-backed workloads.

Simular logo

Simular

www.simular.ai

Simular is an autonomous computer platform that uses AI agents to operate real computers and automate digital workflows. It serves individuals, builders, operators, and businesses that need to automate tasks across desktop applications and websites, including workflows that do not expose traditional APIs.

OpenController logo

OpenController

www.lyzr.ai

OpenController is Lyzr’s control plane for discovering, evaluating, governing, and monitoring AI agents, models, tools, data, and workflows across an enterprise AI estate. It is intended for teams managing agents across clouds, frameworks, runtimes, and environments.