
Natural-language behavior definition
Describe the decisions an agent should make in natural language before testing the workflow.

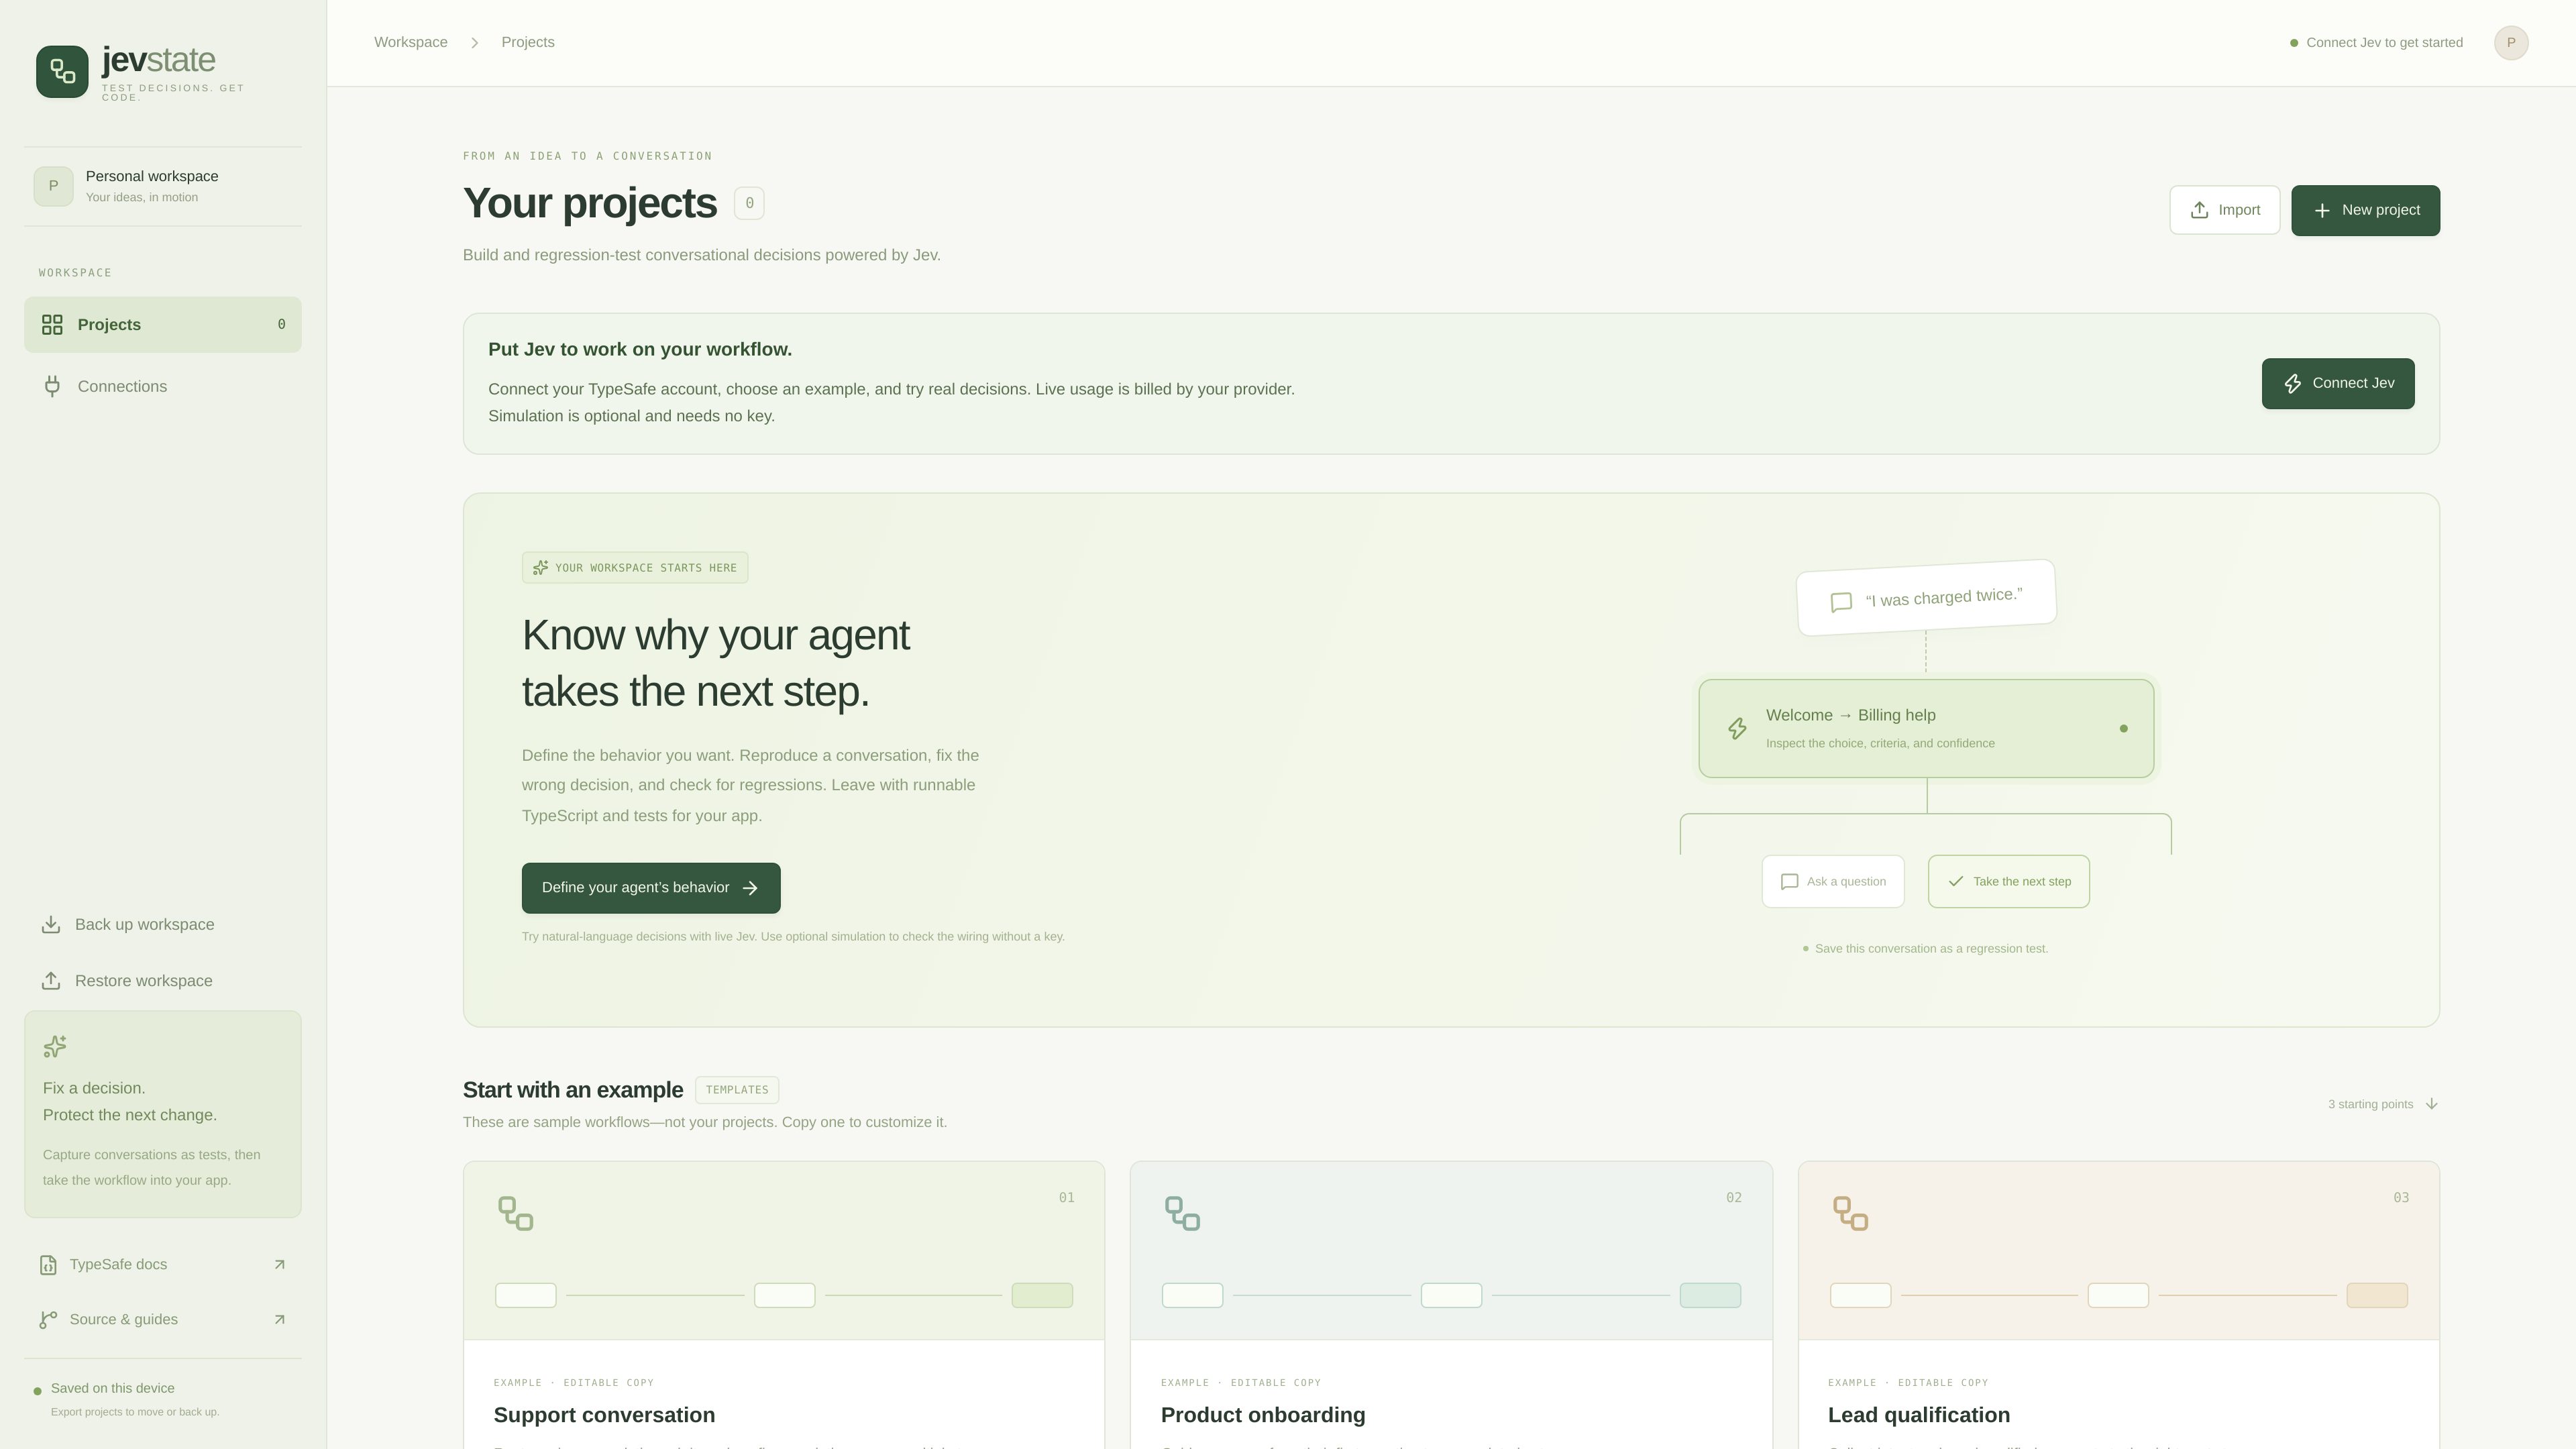
Jev State is a workspace for defining, testing, and regression-checking conversational decisions powered by Jev. It helps teams inspect why an agent takes a step and export runnable TypeScript and tests for an application.
Jev State is a workspace for defining and regression-testing conversational decisions powered by Jev. It lets users describe intended agent behavior, reproduce conversations, inspect the choice and criteria behind a next step, and save conversations as tests.
The workflow runs from definition to implementation: create or copy a project, try decisions, check changes against saved conversations, and leave with runnable TypeScript and tests for an application. The workspace is saved on the device and can be exported for backup or transfer.
Live usage requires a connected TypeSafe account and is billed by the provider. Optional simulation is available for checking wiring without a key. The site does not provide evidence of specific pricing rates, plan limits, integrations beyond the TypeSafe connection, team workspaces, or generated-code runtime assumptions.
Describe the decisions an agent should make in natural language before testing the workflow.
Reproduce a conversation and inspect the selected next step, the criteria used, and the reported confidence.
Save a conversation as a regression test so a later change can be checked against an existing decision path.
Take a completed workflow out of the workspace as runnable TypeScript and tests for use in an app.
Start from sample projects for support conversations, product onboarding, or lead qualification, then customize the selected example.
Keep projects saved on the device and export the workspace to move or back up project data.
Model a support conversation that routes an issue, works through multiple turns, and confirms resolution.
Design an onboarding flow that guides a user from an initial question through a completed setup.
Capture a prospect’s intent in conversation and send a qualified lead to the appropriate next step.
Reproduce a conversation after changing agent behavior, compare the resulting decision with the expected path, and preserve the interaction as a test.
It helps test conversational decisions: users define desired agent behavior, run or reproduce conversations, inspect the next-step choice and criteria, and check changes against saved regression tests.
The site says completed workflows can produce runnable TypeScript and tests for an app. It also provides workspace export for moving or backing up projects.
Live Jev usage requires connecting a TypeSafe account, and live usage is billed by the provider. The site also describes optional simulation that does not need a key.
Yes. Jev State provides editable sample workflows for support conversations, product onboarding, and lead qualification. These are starting templates, not the user’s projects.
The site describes the workspace as saved on the device and provides export and restore actions for backup or moving projects. It does not specify broader team or cloud-collaboration behavior.

context.ai
Context は、顧客インフラ上で AI エージェントを構築・デプロイ・改善できる企業向けプラットフォームです。ワークスペース、ランタイム、コンテキスト、評価ツール、コネクタ、IdP ベースのアクセス制御を備えています。

cognition.ai
CognitionはDevinを中心に、自律的に計画・実装・テスト・デプロイを行うソフトウェア開発エージェントを提供します。

deepeval.com
DeepEval is an open-source LLM evaluation framework for testing and benchmarking AI applications. It helps developers run pytest-native evaluations, score outputs and agent traces, and iterate on systems across text, image, audio, and voice workflows.
www.galileo.ai
Galileo is an AI observability and evaluation platform for testing, debugging, and governing LLM and agent systems across development and production. It helps teams turn evaluation results into production guardrails and monitor AI behavior at scale.
www.giskard.ai
Giskard is an AI security and evaluation platform for testing conversational LLM agents before and after deployment. It combines automated red teaming, quality evaluation, runtime guardrails, and remediation workflows for teams responsible for reliable AI systems.

www.promptfoo.dev
Promptfoo is an AI security and testing platform for evaluating LLM applications, agents, models, and workflows. It helps developers and security teams find vulnerabilities, validate guardrails, map findings to security frameworks, and track remediation through development and deployment.