LLM評価

LLM評価ツールやベンチマーク、テスト基盤を探し、モデル品質の測定、出力比較、リスク検出、AIアプリの改善に役立てられます。

AIインフラ

このコレクションを探索

製品

Artificial Analysis preview
Artificial Analysis logo

Artificial Analysis

LLM評価

モデル、プロバイダー、ハードウェアを比較できるAIベンチマーク・分析プラットフォーム。Pro、Enterprise、無料APIに対応。

Weights & Biases preview
Weights & Biases logo

Weights & Biases

LLM評価

実験追跡、アーティファクト管理、GenAI トレーシング、評価に対応する機械学習・AIプラットフォーム。

Arena preview
Arena logo

Arena

AIチャットボット

Arenaは、モデルとのチャット、出力への投票、タスク別リーダーボードの閲覧ができる公開AIモデル比較・ランキングプラットフォームです。テキスト、ビジョン、コード、検索、動画、エージェントの各タスクで最先端モデルを評価できます。

Pydantic preview
Pydantic logo

Pydantic

AIオブザーバビリティ

型安全アプリの構築、AIシステムの可観測性、出力評価、モデルルーティングを支援するAIエンジニアリングスタック

Scale AI preview
Scale AI logo

Scale AI

LLM評価

本番で信頼できるAIを構築するためのデータ・評価・企業向けAIツール

Langfuse preview
Langfuse logo

Langfuse

AIオブザーバビリティ

LLMアプリケーションとエージェントの追跡・評価・改善を行うオープンソースAIエンジニアリング基盤。

SuperAnnotate preview
SuperAnnotate logo

SuperAnnotate

LLM評価

画像・動画・テキスト・音声のアノテーションと評価パイプラインを構築するAIデータ基盤。

Horizon preview
Horizon logo

Horizon

LLM評価

LabelboxのRL環境製品。長期タスク向けのポストトレーニングと評価に対応。

Outlier AI preview
Outlier AI logo

Outlier AI

LLM評価

専門家を柔軟な案件とつなぎ、週払いに対応するリモートAIトレーニングプラットフォーム

Context logo
Context logo

Context

AIエージェントビルダー

Context は、顧客インフラ上で AI エージェントを構築・デプロイ・改善できる企業向けプラットフォームです。ワークスペース、ランタイム、コンテキスト、評価ツール、コネクタ、IdP ベースのアクセス制御を備えています。

Klavis AI logo
Klavis AI logo

Klavis AI

AIエージェント基盤

Klavis AIは、コーディングデータとツール利用データに対応したAIエージェントの学習・評価環境を提供します。

Agnost AI preview
Agnost AI logo

Agnost AI

AIオブザーバビリティ

Agnost AI monitors AI agents in production by analyzing conversations, traces, user corrections, and frustration. It helps teams identify recurring failures, review suggested prompt fixes, and apply approved changes with replay-based regression coverage.

OpenTrain AI preview
OpenTrain AI logo

OpenTrain AI

LLM評価

OpenTrain AIは、事前審査済みのAIトレーナー、データラベラー、ドメイン専門家を採用できるマーケットプレイス兼マネージドサービスです。RLHF、評価、レッドチーム、アノテーション、エージェントワークフローに対応します。

QAgent preview
QAgent logo

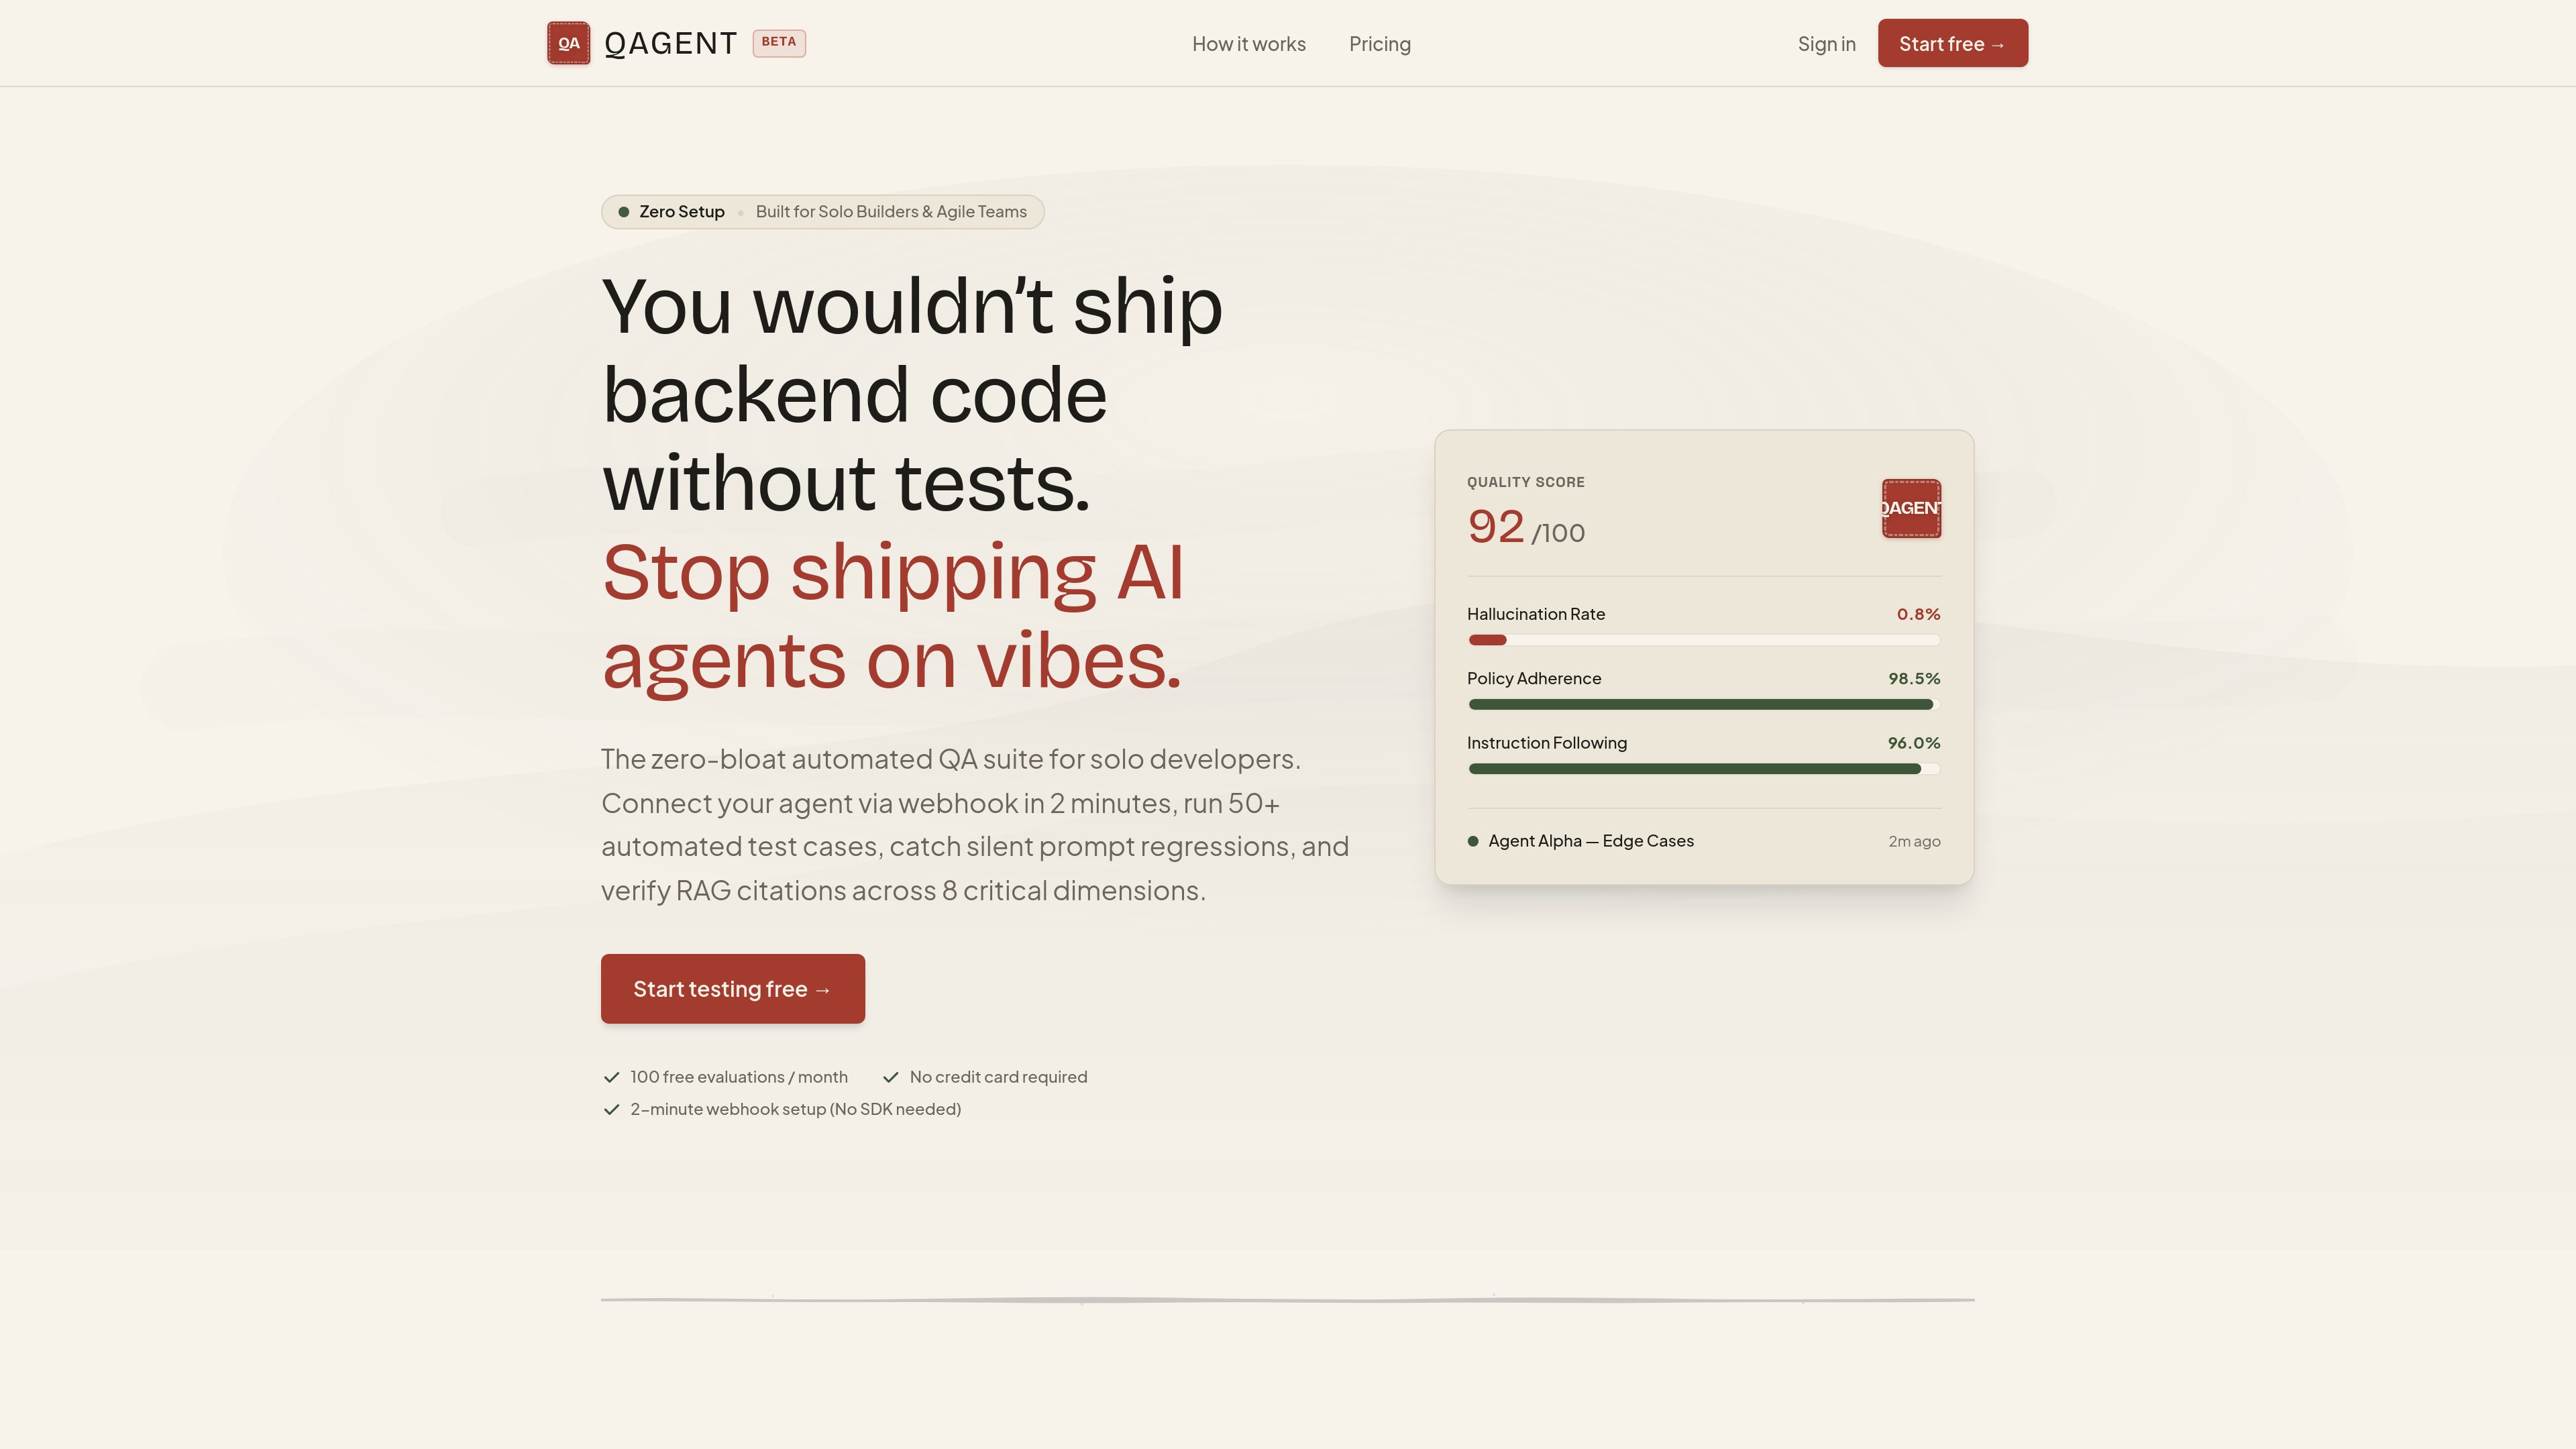
QAgent

AIテストアシスタント

QAgent is an AI agent testing and quality assurance platform for developers and agile teams. It connects to an agent through a webhook or endpoint, runs automated test cases, and evaluates responses for groundedness, policy adherence, prompt compliance, and related quality dimensions.
inferock-bench preview
inferock-bench logo

inferock-bench

AIゲートウェイとルーティング

inferock-bench is a local diagnostic proxy for tracking LLM API usage, provider-reported costs, failures, and billing-integrity signals. It helps developers inspect calls to OpenAI, Anthropic, Gemini Developer API, and pinned OpenRouter endpoints using locally stored receipts.
NovaSynth preview
NovaSynth logo

NovaSynth

AIテストアシスタント

NovaSynth is a pre-production testing platform for AI agents that uses synthetic users across real SIP phone calls, LiveKit audio, and chat. It helps teams rehearse multi-turn interactions, surface failures, and validate fixes before releasing agents to customers.

MCPJam preview
MCPJam logo

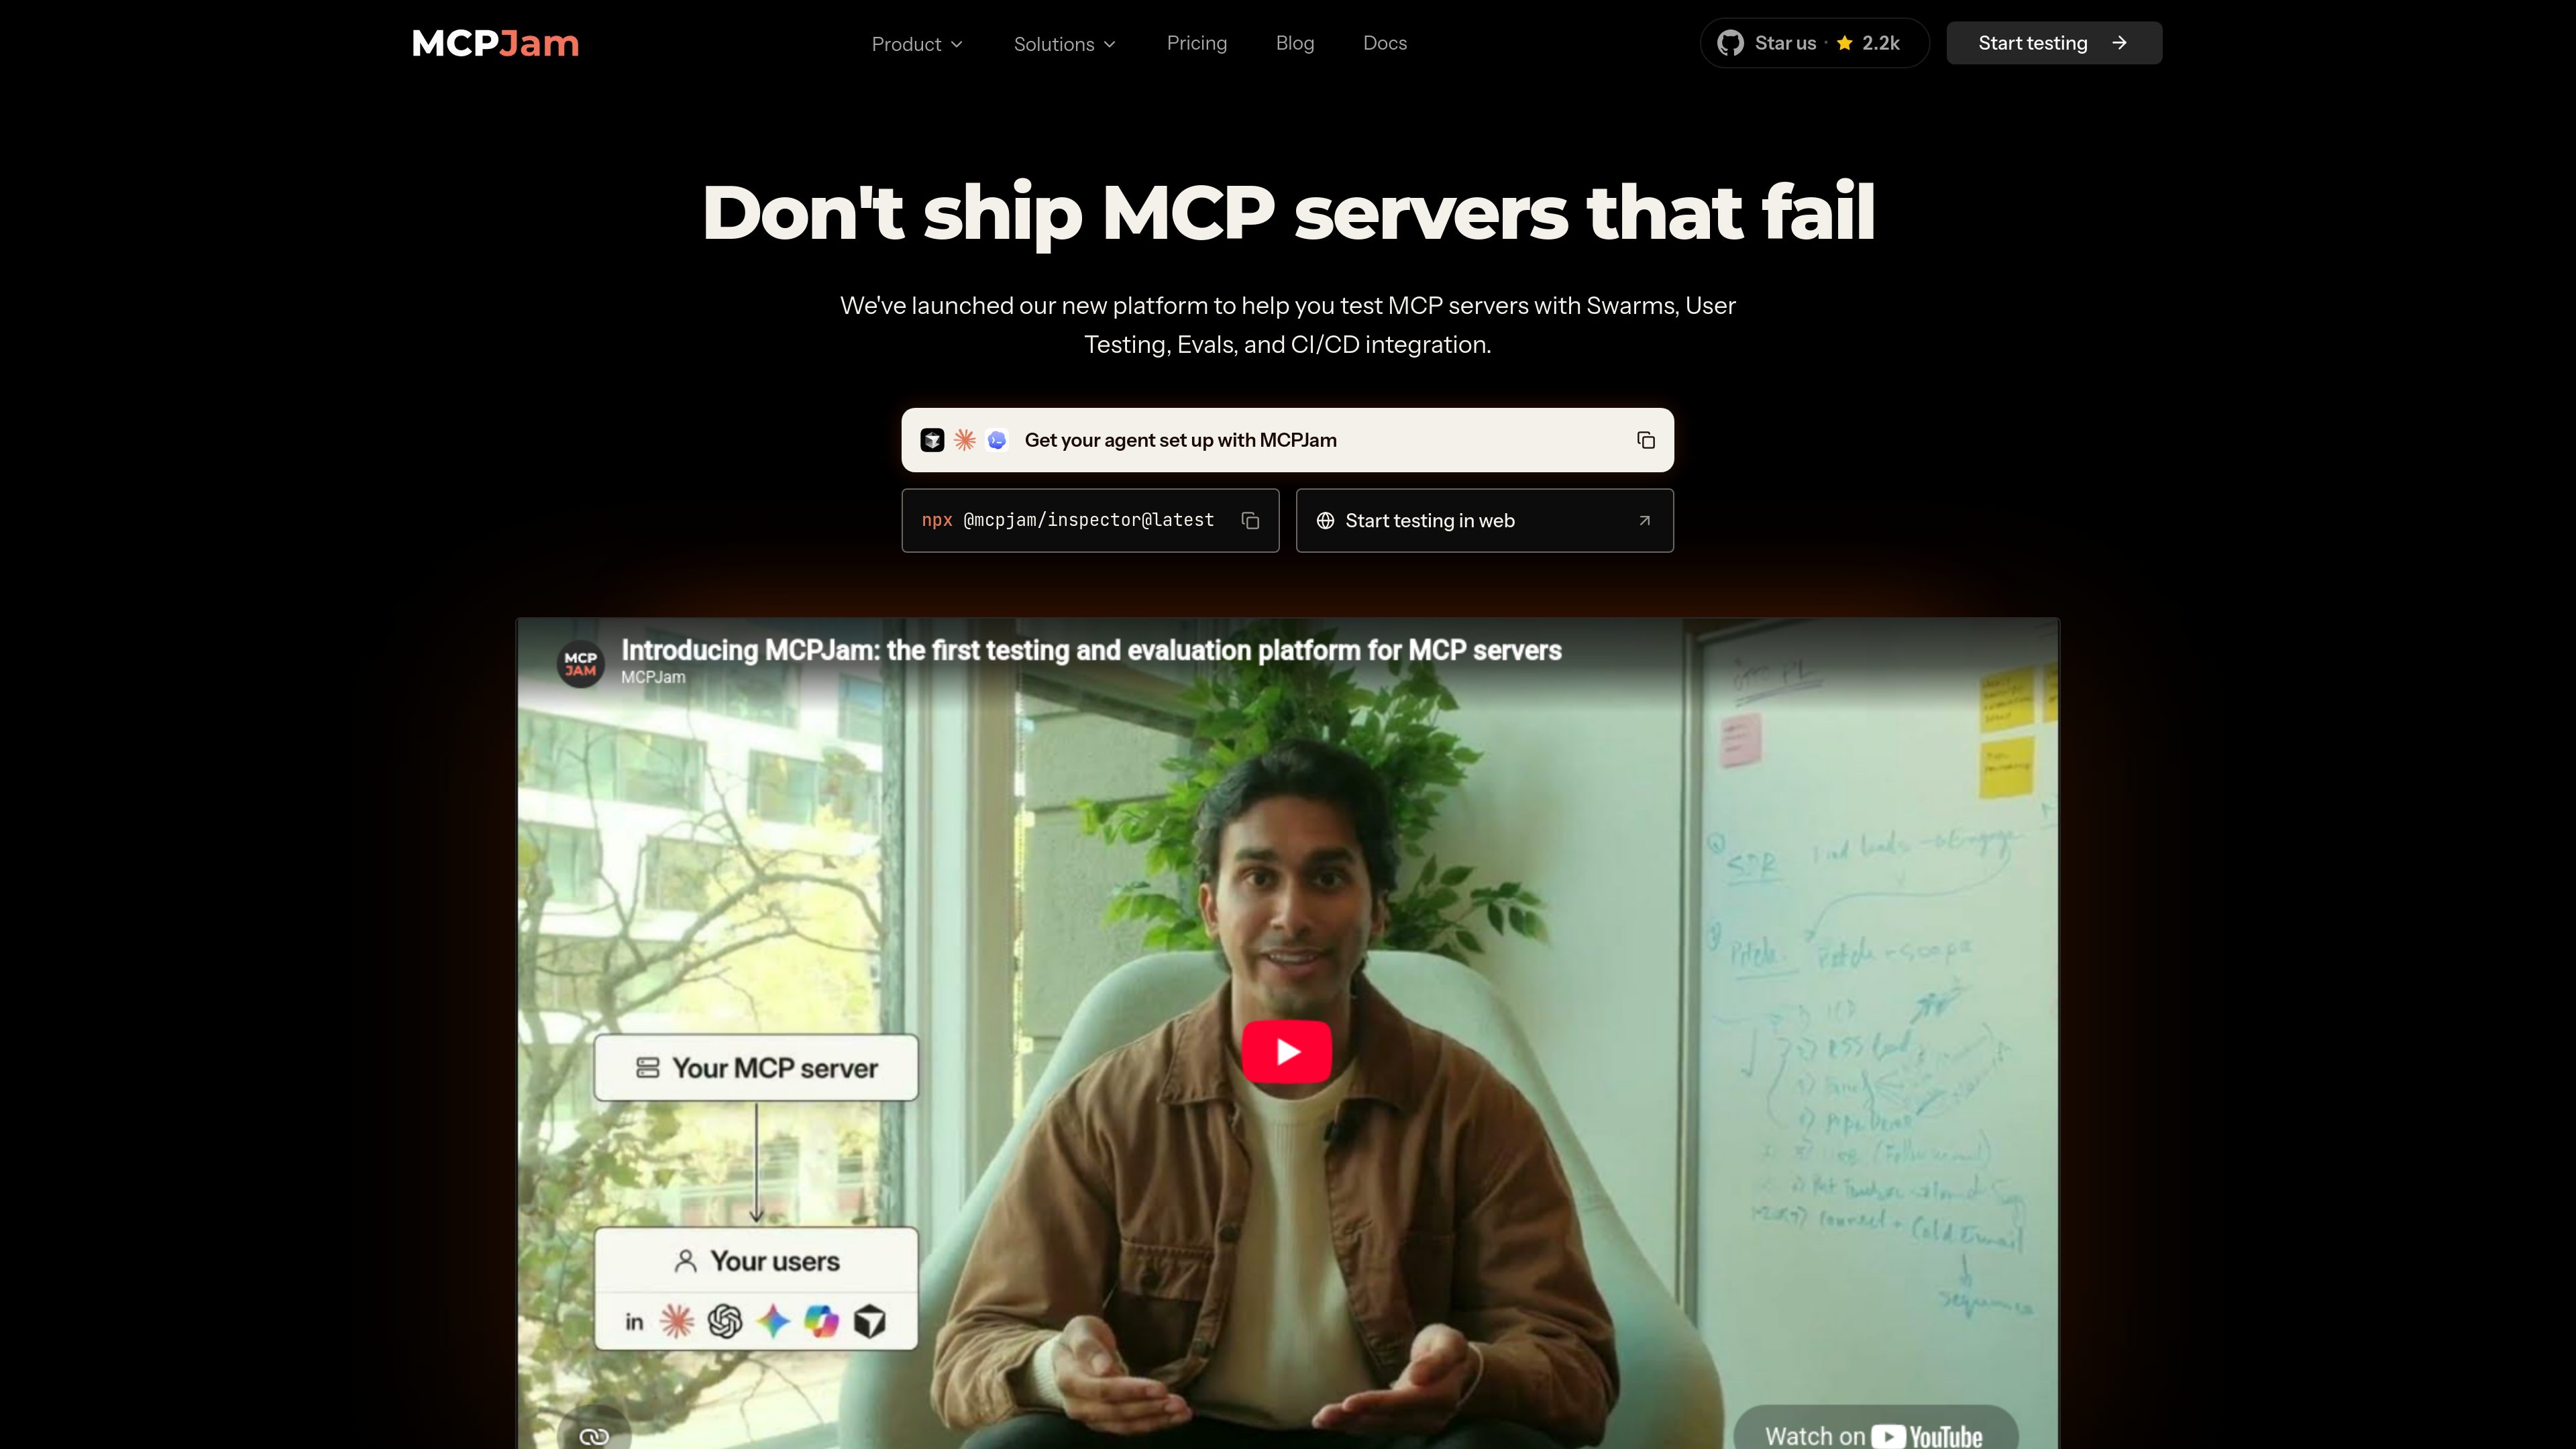
MCPJam

AIテストアシスタント

MCPJam is a testing and evaluation platform for MCP servers. It helps developers inspect servers locally, run user and model-based tests, and add behavior checks to CI/CD workflows.

Oqoqo preview
Oqoqo logo

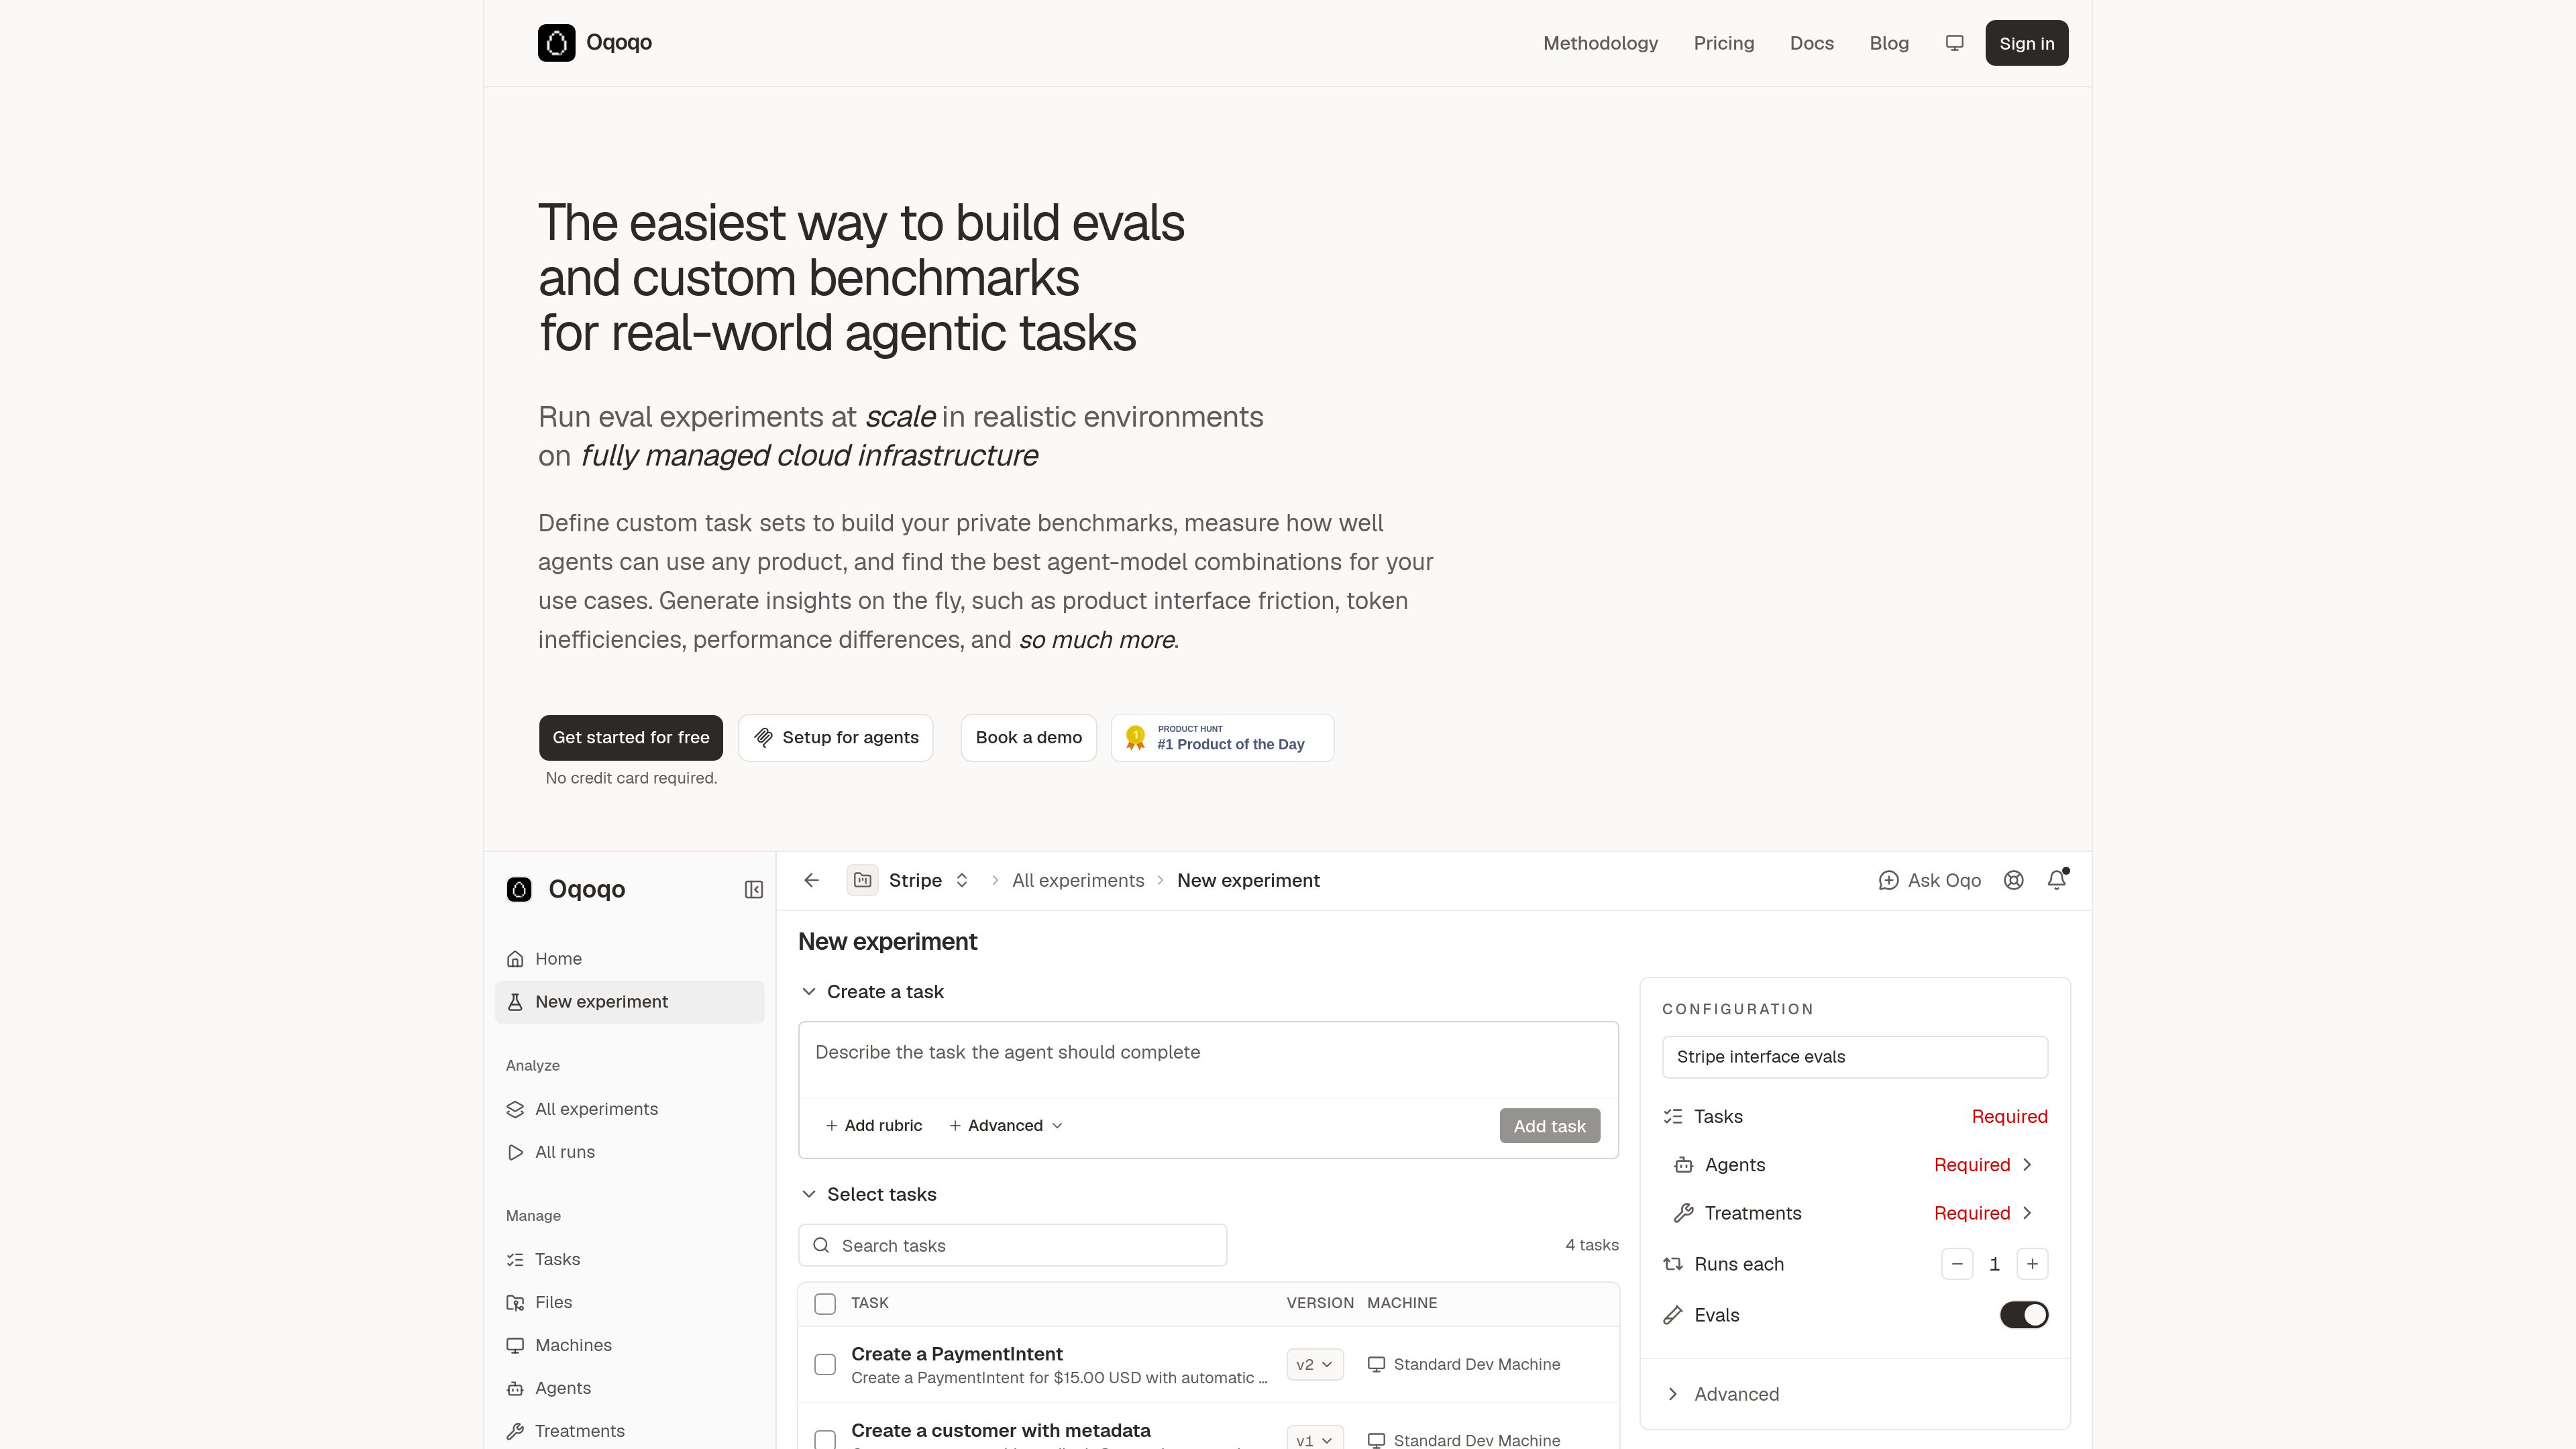
Oqoqo

LLM評価

Oqoqo is an evaluation platform for running repeatable agent experiments in realistic, isolated environments. Teams use it to build private benchmarks, compare agents and models, and investigate why agent workflows succeed or fail.

ComputeArena preview
ComputeArena logo

ComputeArena

LLM評価

ComputeArena is a community benchmark directory for measuring local AI model throughput across chips, quantisations, and runtimes. It helps developers run offline benchmarks, inspect signed reports, and compare decode and prefill performance on compatible workloads.

Jev State preview
Jev State logo

Jev State

AIエージェントビルダー

Jev State is a workspace for defining, testing, and regression-checking conversational decisions powered by Jev. It helps teams inspect why an agent takes a step and export runnable TypeScript and tests for an application.