
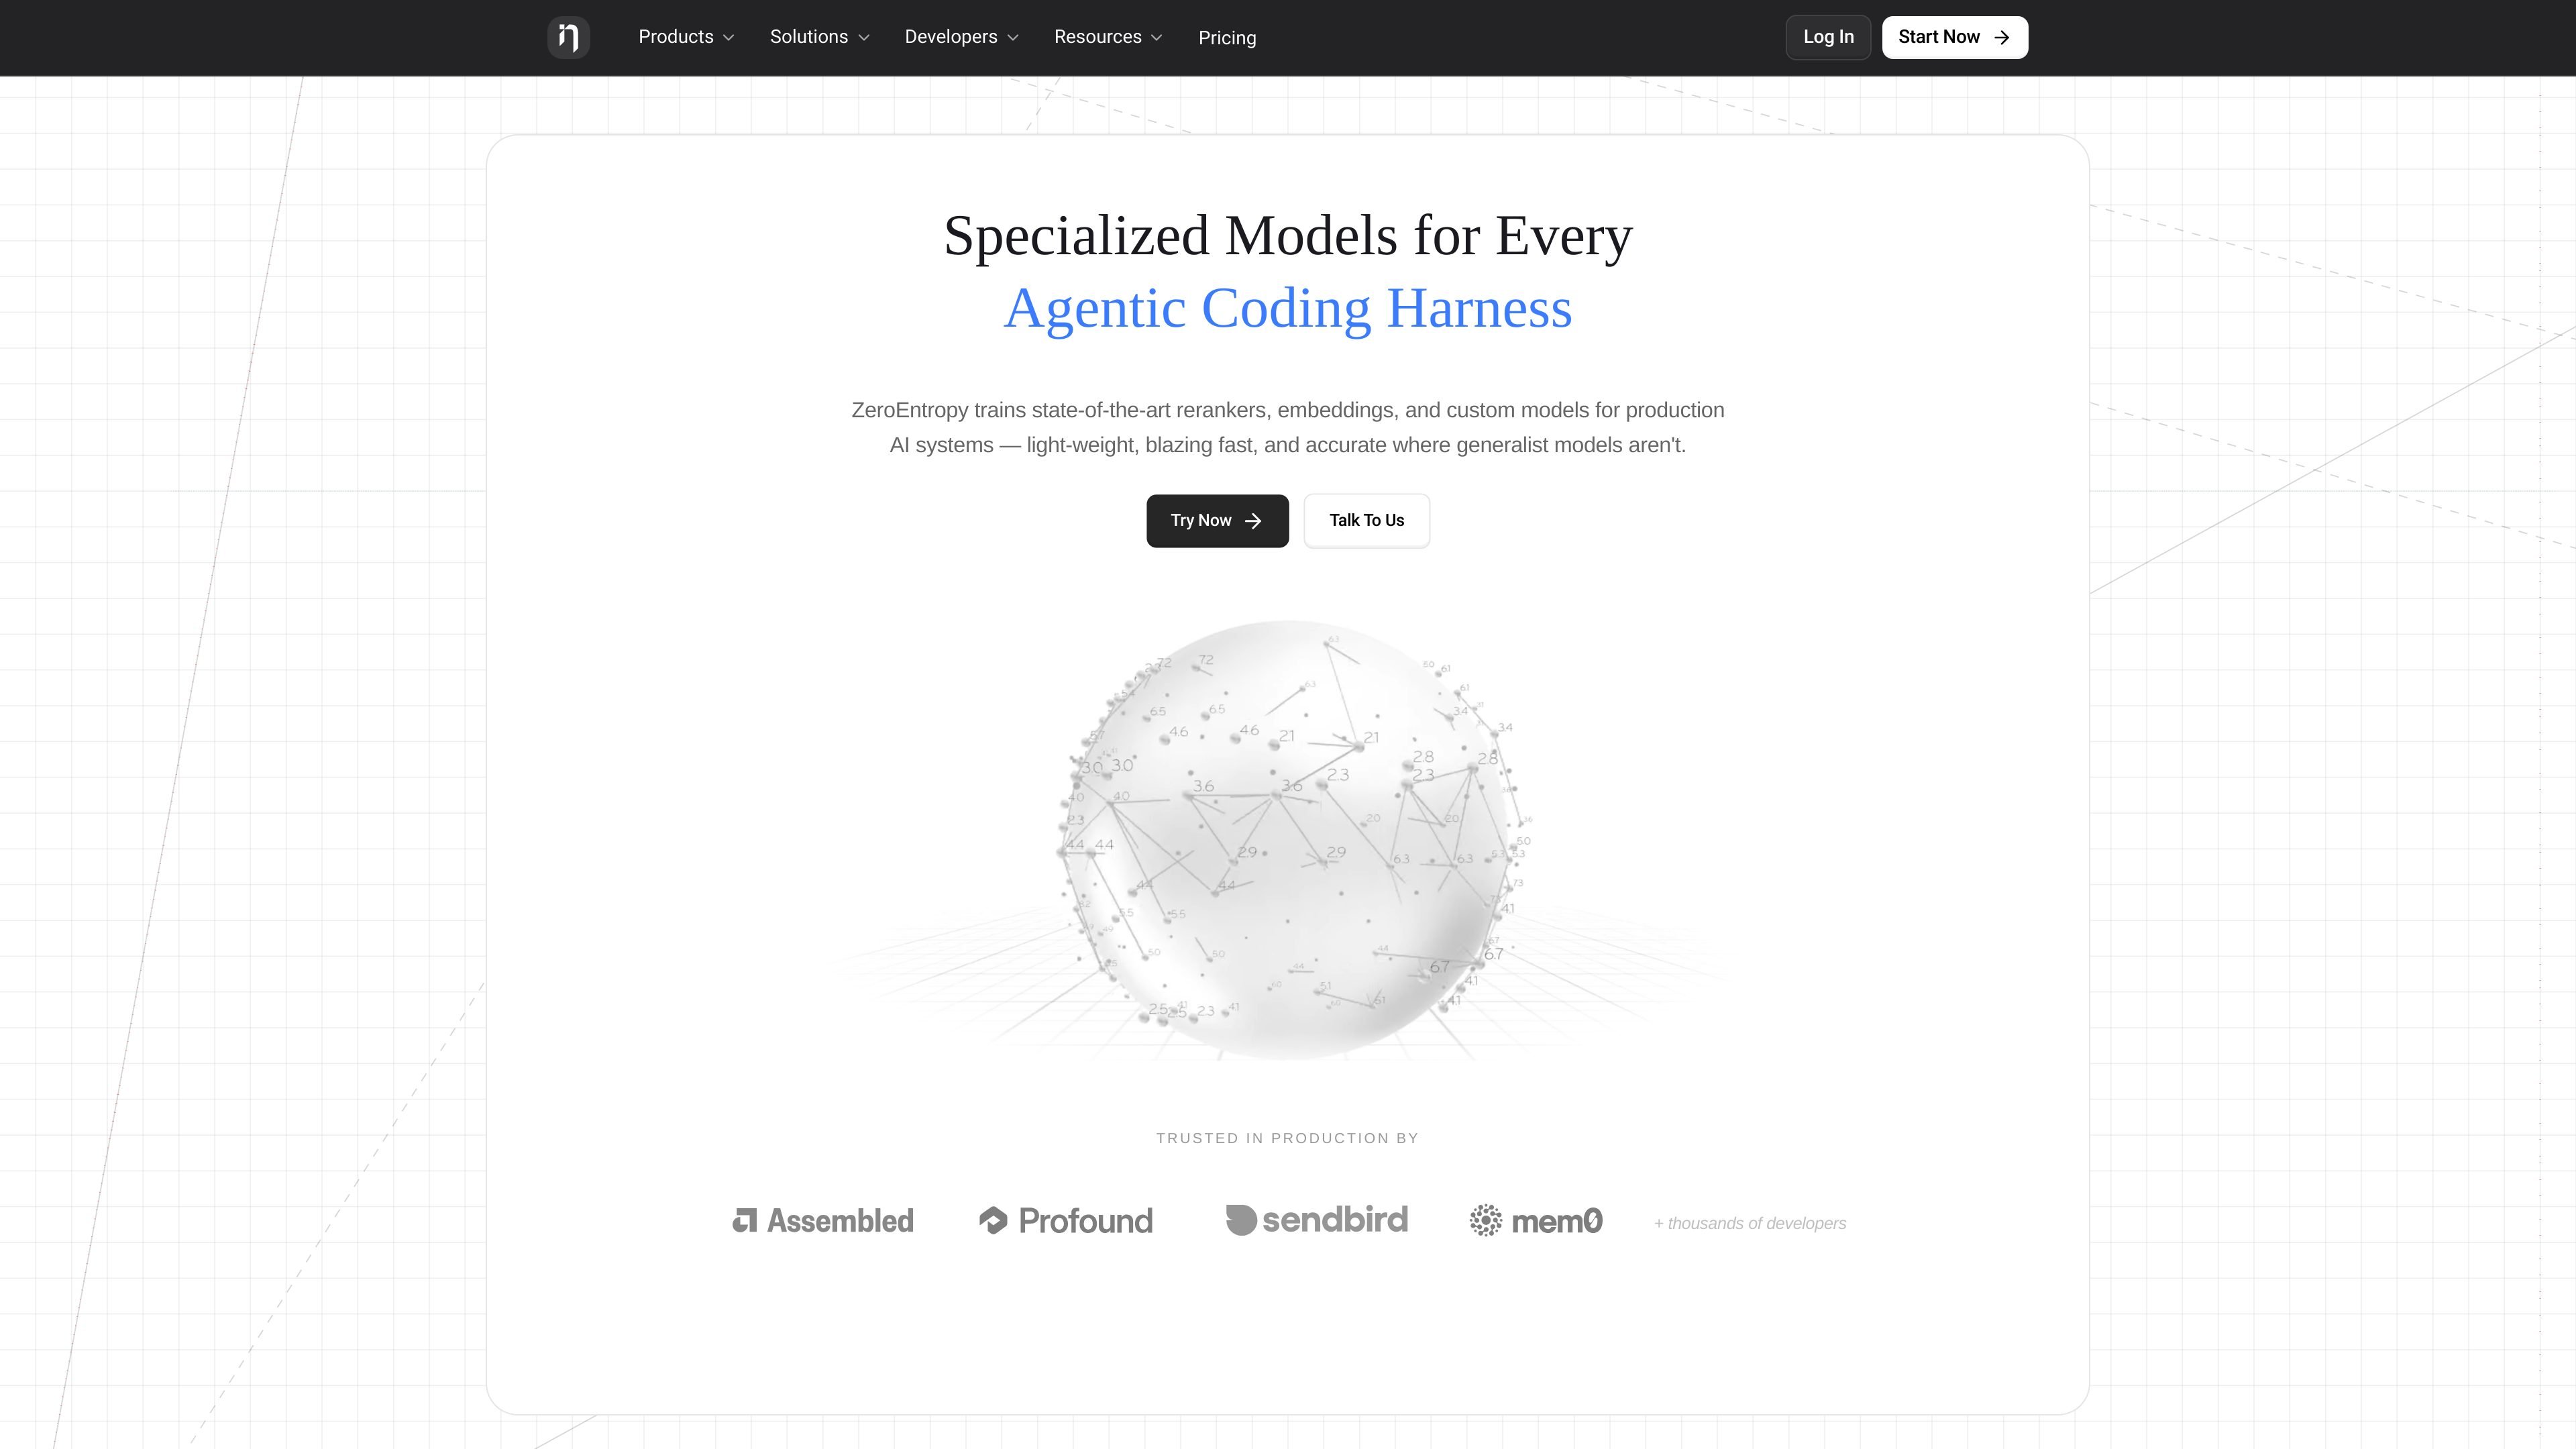
Reranking with `zerank-2`
Use `zerank-2` for reranking retrieval candidates so the best matches reach the model. The homepage describes it as the flagship reranker and says it can improve retrieval with a single line of code.

Modèles d’IA spécialisés pour les systèmes de recherche, avec rerankers, embeddings, modèles personnalisés, API, licences d’entreprise et déploiement VPC.
ZeroEntropy is a retrieval-focused AI product that trains specialized models for search and RAG pipelines. Its core line includes rerankers, embeddings, and custom models designed for production systems where accuracy, latency, and cost all matter.
The homepage positions the stack as a faster and more accurate alternative to generalist models, while the pricing and trust pages show how teams can adopt it through self-serve APIs, enterprise plans, VPC deployment, and compliance documentation.
Use `zerank-2` for reranking retrieval candidates so the best matches reach the model. The homepage describes it as the flagship reranker and says it can improve retrieval with a single line of code.
Use `zembed-1` for embeddings when your system needs retrieval vectors rather than only reranking. The site positions it as the flagship embedding model and says it can outperform leading embedding models even at lower dimensionality.
Train specialized models for query rewriting, context compression, and bespoke production-agent workflows. The homepage frames custom models as a way to adapt the stack to a specific application rather than using a general-purpose model unchanged.
Access the models through a single API, partner providers, or dedicated VPC deployment. The pricing page also mentions AWS Marketplace and Azure as deployment channels for ZeroEntropy VPC.
Use the search API for retrieval workflows that include OCR, indexing, storage, queries, reranking, and embeddings. The pricing page breaks these into usage-based components for teams that want retrieval infrastructure rather than one isolated model.
Evaluate models against public benchmarks and internal datasets. The evaluations page shows rankings across 28 datasets and multiple verticals, which gives teams a way to compare retrieval quality before production rollout.
Improve the ordering of retrieval candidates before they reach an LLM, especially when keyword and vector search both contribute documents and ranking quality determines answer quality.
Power support systems where wrong retrieval creates bad responses. The Assembled story shows production reranking across chat, email, and phone support workflows.
Support medical or other research-heavy search systems that must retrieve from large document collections and maintain accuracy under domain-specific queries. The site cites Vera Health using ZeroEntropy for retrieval across millions of medical research papers.
Reduce latency in interactive AI products and agents by replacing slower generalist alternatives with specialized models optimized for serving performance.
Run evaluation-driven model selection before production rollout. The evaluations page and Assembled case study both emphasize benchmark review, regression sets, and live traffic validation.
ZeroEntropy provides specialized AI models for retrieval-heavy workflows, including rerankers, embeddings, and custom models. The pricing page and homepage show both self-serve API usage and enterprise options, including VPC deployment and model licensing.
The site shows a ZeroEntropy API with Python and TypeScript SDKs, plus deployment through partner providers and ZeroEntropy VPC. It also notes availability on AWS Marketplace and Azure for VPC deployment.
Yes. The trust center lists SOC 2 Type II and HIPAA compliance, and the site also references GDPR and CCPA compliance statements. The trust page includes controls for access, data protection, disaster recovery, and network security.
The pricing page lists self-serve pricing for the API, an enterprise plan with contact sales flow, and an on-prem offering called "ze on-prem." It also says enterprise customers can get volume discounts, white-glove onboarding, and custom integrations.
Les données de trafic sont fournies à titre indicatif uniquement.
valpere.github.io
session-indexer est un outil pour développeurs hébergé sur GitHub qui indexe les transcriptions de sessions Claude Code dans SQLite et permet de les rechercher par sens. Il est conçu pour retrouver l’historique JSONL par projet, avec FTS5 en solution de repli lorsque la recherche basée sur des embeddings n’est pas disponible.
zilliz.com
Base de données vectorielle et plateforme Vector Lakebase entièrement gérées pour les charges IA d’entreprise, avec recherche en temps réel, récupération hybride, SaaS et BYOC.
kensho.com
Kensho est le moteur d’IA d’entreprise de S&P Global pour la recherche et la transformation de données adaptées à l’IA, reliant des données fiables aux LLM, agents et applications personnalisées.

trychroma.com
Infrastructure de recherche open source pour l’IA avec recherche vectorielle, plein texte, regex et métadonnées.

trytako.com
Tako est une API de moteur de réponses qui ancre l’IA dans des données fiables sous licence et sur le Web, avec des résultats structurés et cités pour les équipes IA, data et recherche.

skillsmp.com
SkillsMP est une marketplace gratuite pour découvrir des compétences d’agents open source dans des dépôts GitHub publics, avec recherche, navigation, API REST et accès MCP pour Claude Code, Codex CLI et ChatGPT.