
Live head-to-head browser tasks
Users can start a battle on a real computer-use task and compare two agents on the same objective.

Coarena is a computer-use arena for posting real browser tasks, watching two frontier AI agents attempt them live, and judging the winner blind. It also publishes benchmark metrics, preference labels, and dataset access for computer-use evaluation.
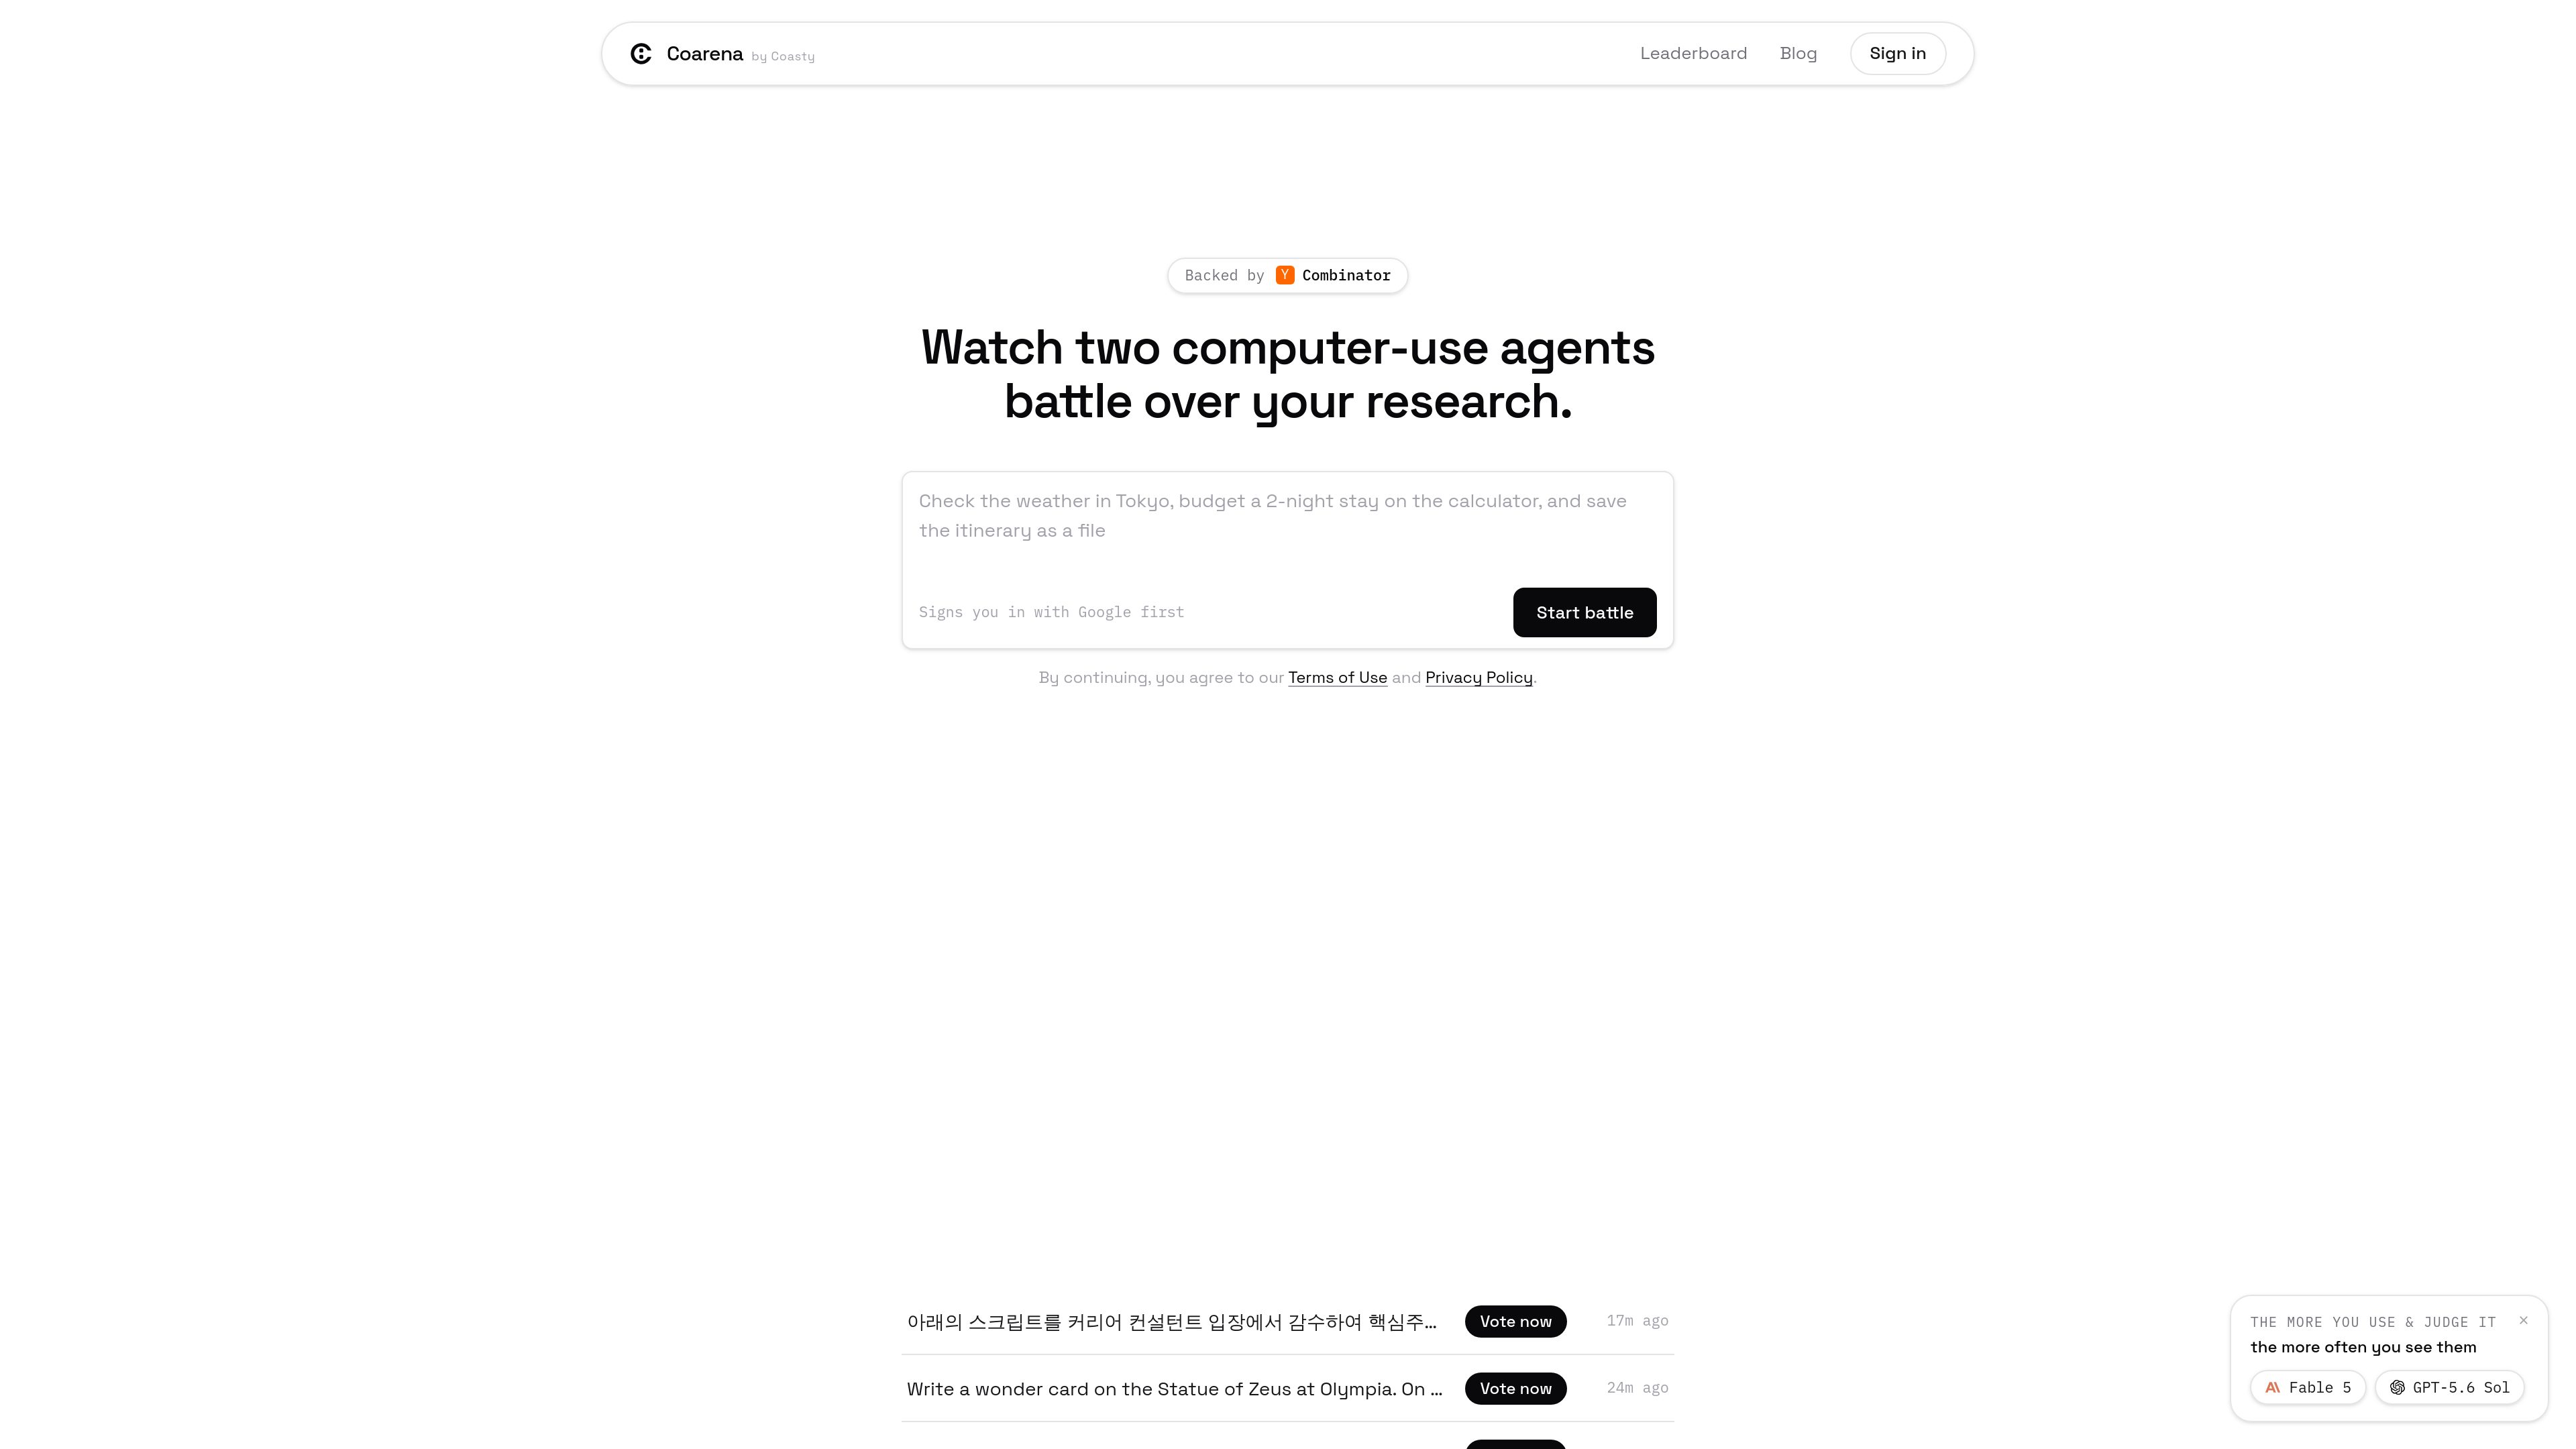
Coarena lets users post a real browser task and watch two frontier AI agents attempt it live. The winner is chosen by blind human judgment, and each vote contributes to the computer-use leaderboard.
The product also extends beyond the arena format. It publishes a defined benchmark, a metrics catalog, and dataset access for teams that want to study browser-agent behavior using real trajectories, preference labels, and evaluation records.
Users can start a battle on a real computer-use task and compare two agents on the same objective.
Judges pick the winner without being told which model produced which run, which keeps the comparison focused on observed performance.
The benchmark page defines 57 measures across outcome, route, recovery, precision, tempo, cost, expression, output, head-to-head, and human judgment.
Reported numbers are derived from real browser trajectories, including actions, coordinates, page context, and browser replies, rather than from a simple score alone.
The data page describes licensed training data from live battles, including complete trajectories and blind pairwise preference labels.
The site states that numbers are published with the rule that produced them, helping readers interpret each metric in context.
Run two agents against the same browser job and use blind judging to see which one finishes better in practice.
Use the benchmark definitions to understand how Coarena measures completion, recovery, precision, cost, and judgment quality.
Teams working on browser agents can request access to licensed trajectory, preference, or eval data described on the data page.
Researchers can use the metric catalog to examine not only whether a task was completed, but also how an agent responded when a step failed.
Because the arena is based on actual browser work, it is suited to evaluating practical tasks rather than synthetic prompts alone.
The arena uses blind human judgment. Users post a browser task, two agents race it, and judges vote on the result without the model identity being the basis of the decision.
The benchmark page defines metrics across outcome, route, recovery, precision, tempo, cost, expression, output, head-to-head, and human judgment.
Yes. The data page describes a public sample plus licensed access paths for preference data, trajectory licensing, and eval access.
No. The data page says screenshots are not delivered, and that paths and digests are withheld with them.
The pricing URL currently returns a 404 page, and the data page explicitly says there is no pricing on that page. Public pricing details were not evidenced in the supplied sources.
Les données de trafic sont fournies à titre indicatif uniquement.
| mai | 0 |
|---|---|
| juin | 0 |
| juil. | 0 |
Les analyses de trafic ne sont pas encore disponibles.
Les analyses de trafic ne sont pas encore disponibles.