
Scraping Browser
Cloud browser infrastructure for automation, data extraction, and AI agent browser operations, with anti-detection and fingerprint isolation.
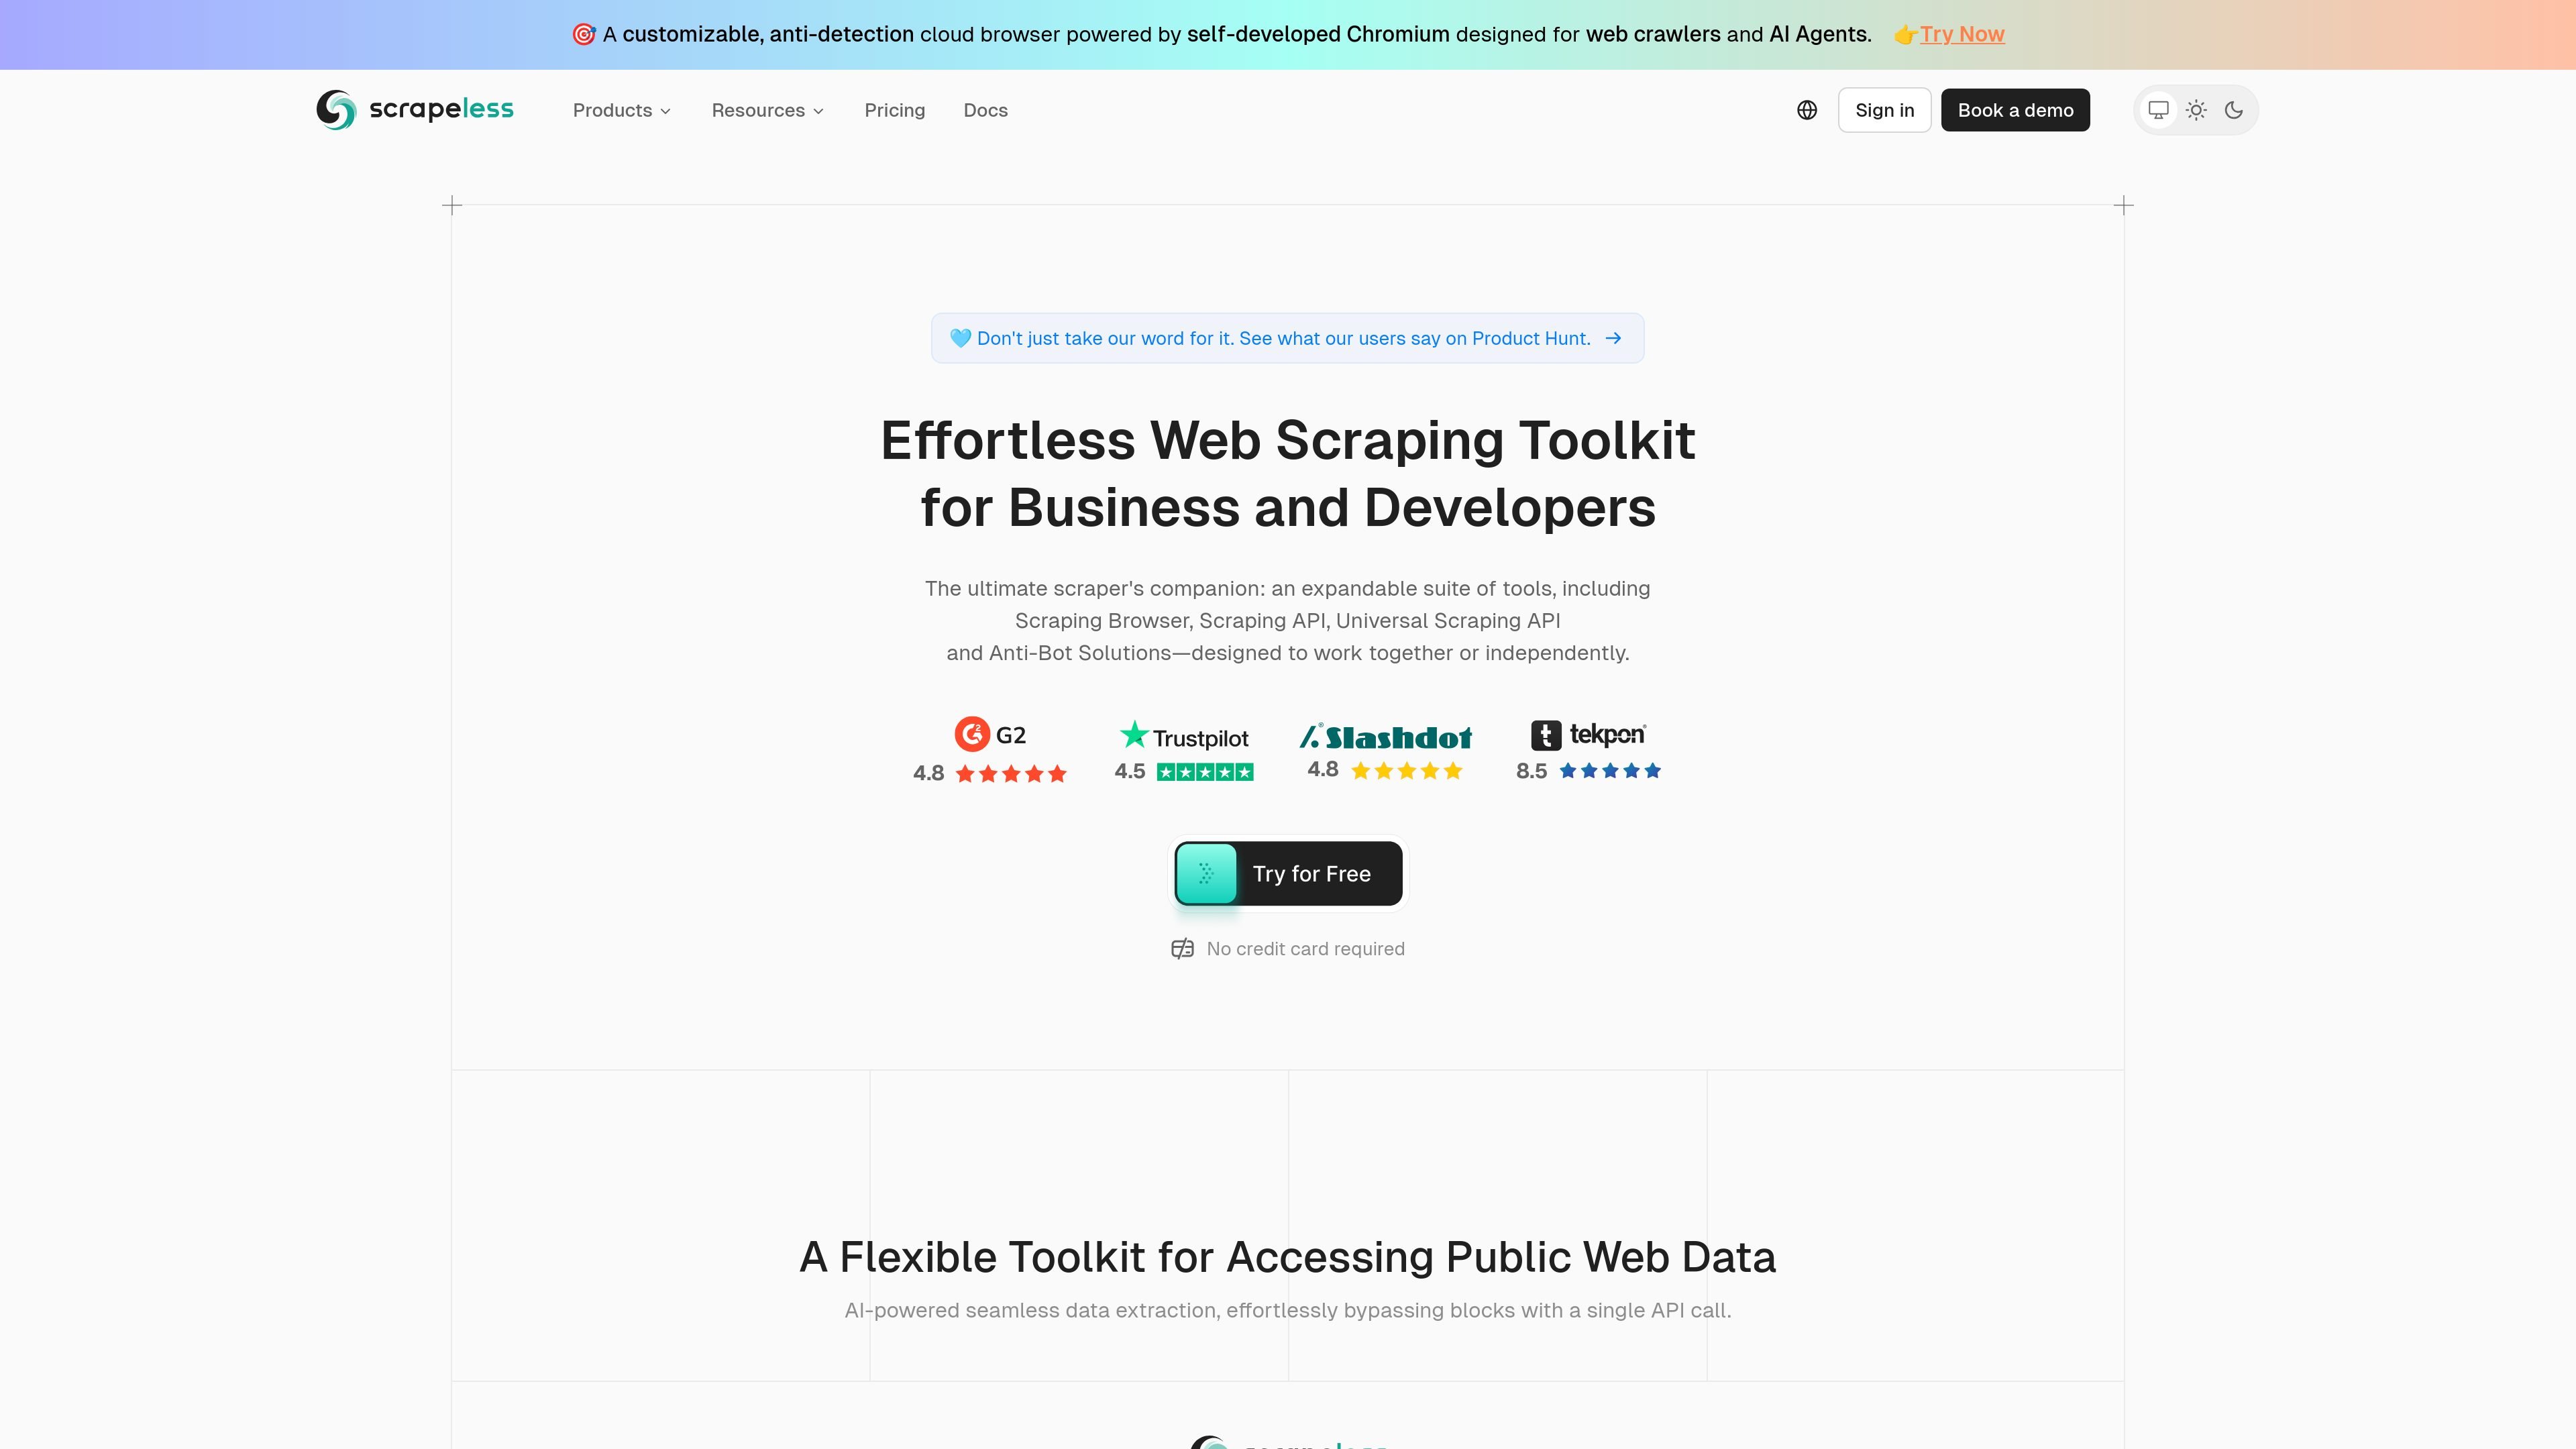
Scrapeless is a web scraping toolkit built for businesses and developers that need to collect public web data, automate browser tasks, and work around common blocking mechanisms. The site positions the product as a set of tools that can be used together or independently, rather than a single standalone API.
Its main offerings include Scraping Browser, Universal Scraping API, Proxy Solutions, and Crawl, with supporting mentions of CAPTCHA solving, anti-bot handling, and enterprise services such as custom solutions, data transformation, and real-time data push. The pricing page also shows trial and sales motions, including a free trial, book-a-demo flow, and contact-sales option.
Cloud browser infrastructure for automation, data extraction, and AI agent browser operations, with anti-detection and fingerprint isolation.
An enterprise web-unlock option that handles IP rotation, anti-blocking, CAPTCHA, JavaScript rendering, and dynamic content loading.
Residential, ISP, datacenter, IPv6, and high-bandwidth proxies with geo-location targeting and dedicated IP support.
Single-page and recursive crawl modes, flexible multi-format delivery, built-in CAPTCHA solving, and global proxy rotation.
Compatibility notes for Puppeteer and Playwright, plus a dashboard that provides example code after login.
Custom solutions, data cleaning and transformation, real-time data push/API integration, and enterprise SLA coverage are offered for larger projects.
Collect articles, blog posts, and research papers from public web pages for downstream analysis or aggregation.
Track product prices, discounts, and market trends with scraping flows that avoid browser maintenance overhead.
Gather product reviews, user feedback, or social media review content for sentiment or reputation workflows.
Run browser-based automation or AI agent workflows in cloud browsers with anti-detection and fingerprint isolation.
Use enterprise services when a project needs custom scraping, data transformation, real-time API delivery, or service-level support.
Scrapeless is presented as a full-stack web scraping toolkit that includes Scraping Browser, Scraping API, Universal Scraping API, Proxy Solutions, and a CAPTCHA Solver/anti-bot layer.
The site says the toolkit is designed for business and developers and supports automation, data extraction, AI agent browser operations, and public web data collection.
The homepage says the toolkit can work together or independently, and the product pages highlight browser automation, web-unlock scraping, and proxy infrastructure as separate offerings.
The site says users can register for a free trial, and the pricing page indicates a demo flow and contact-sales option for enterprise needs.
The site emphasizes collection of publicly available data and warns against unauthorized or unapproved sensitive information.
流量數據僅供參考。