
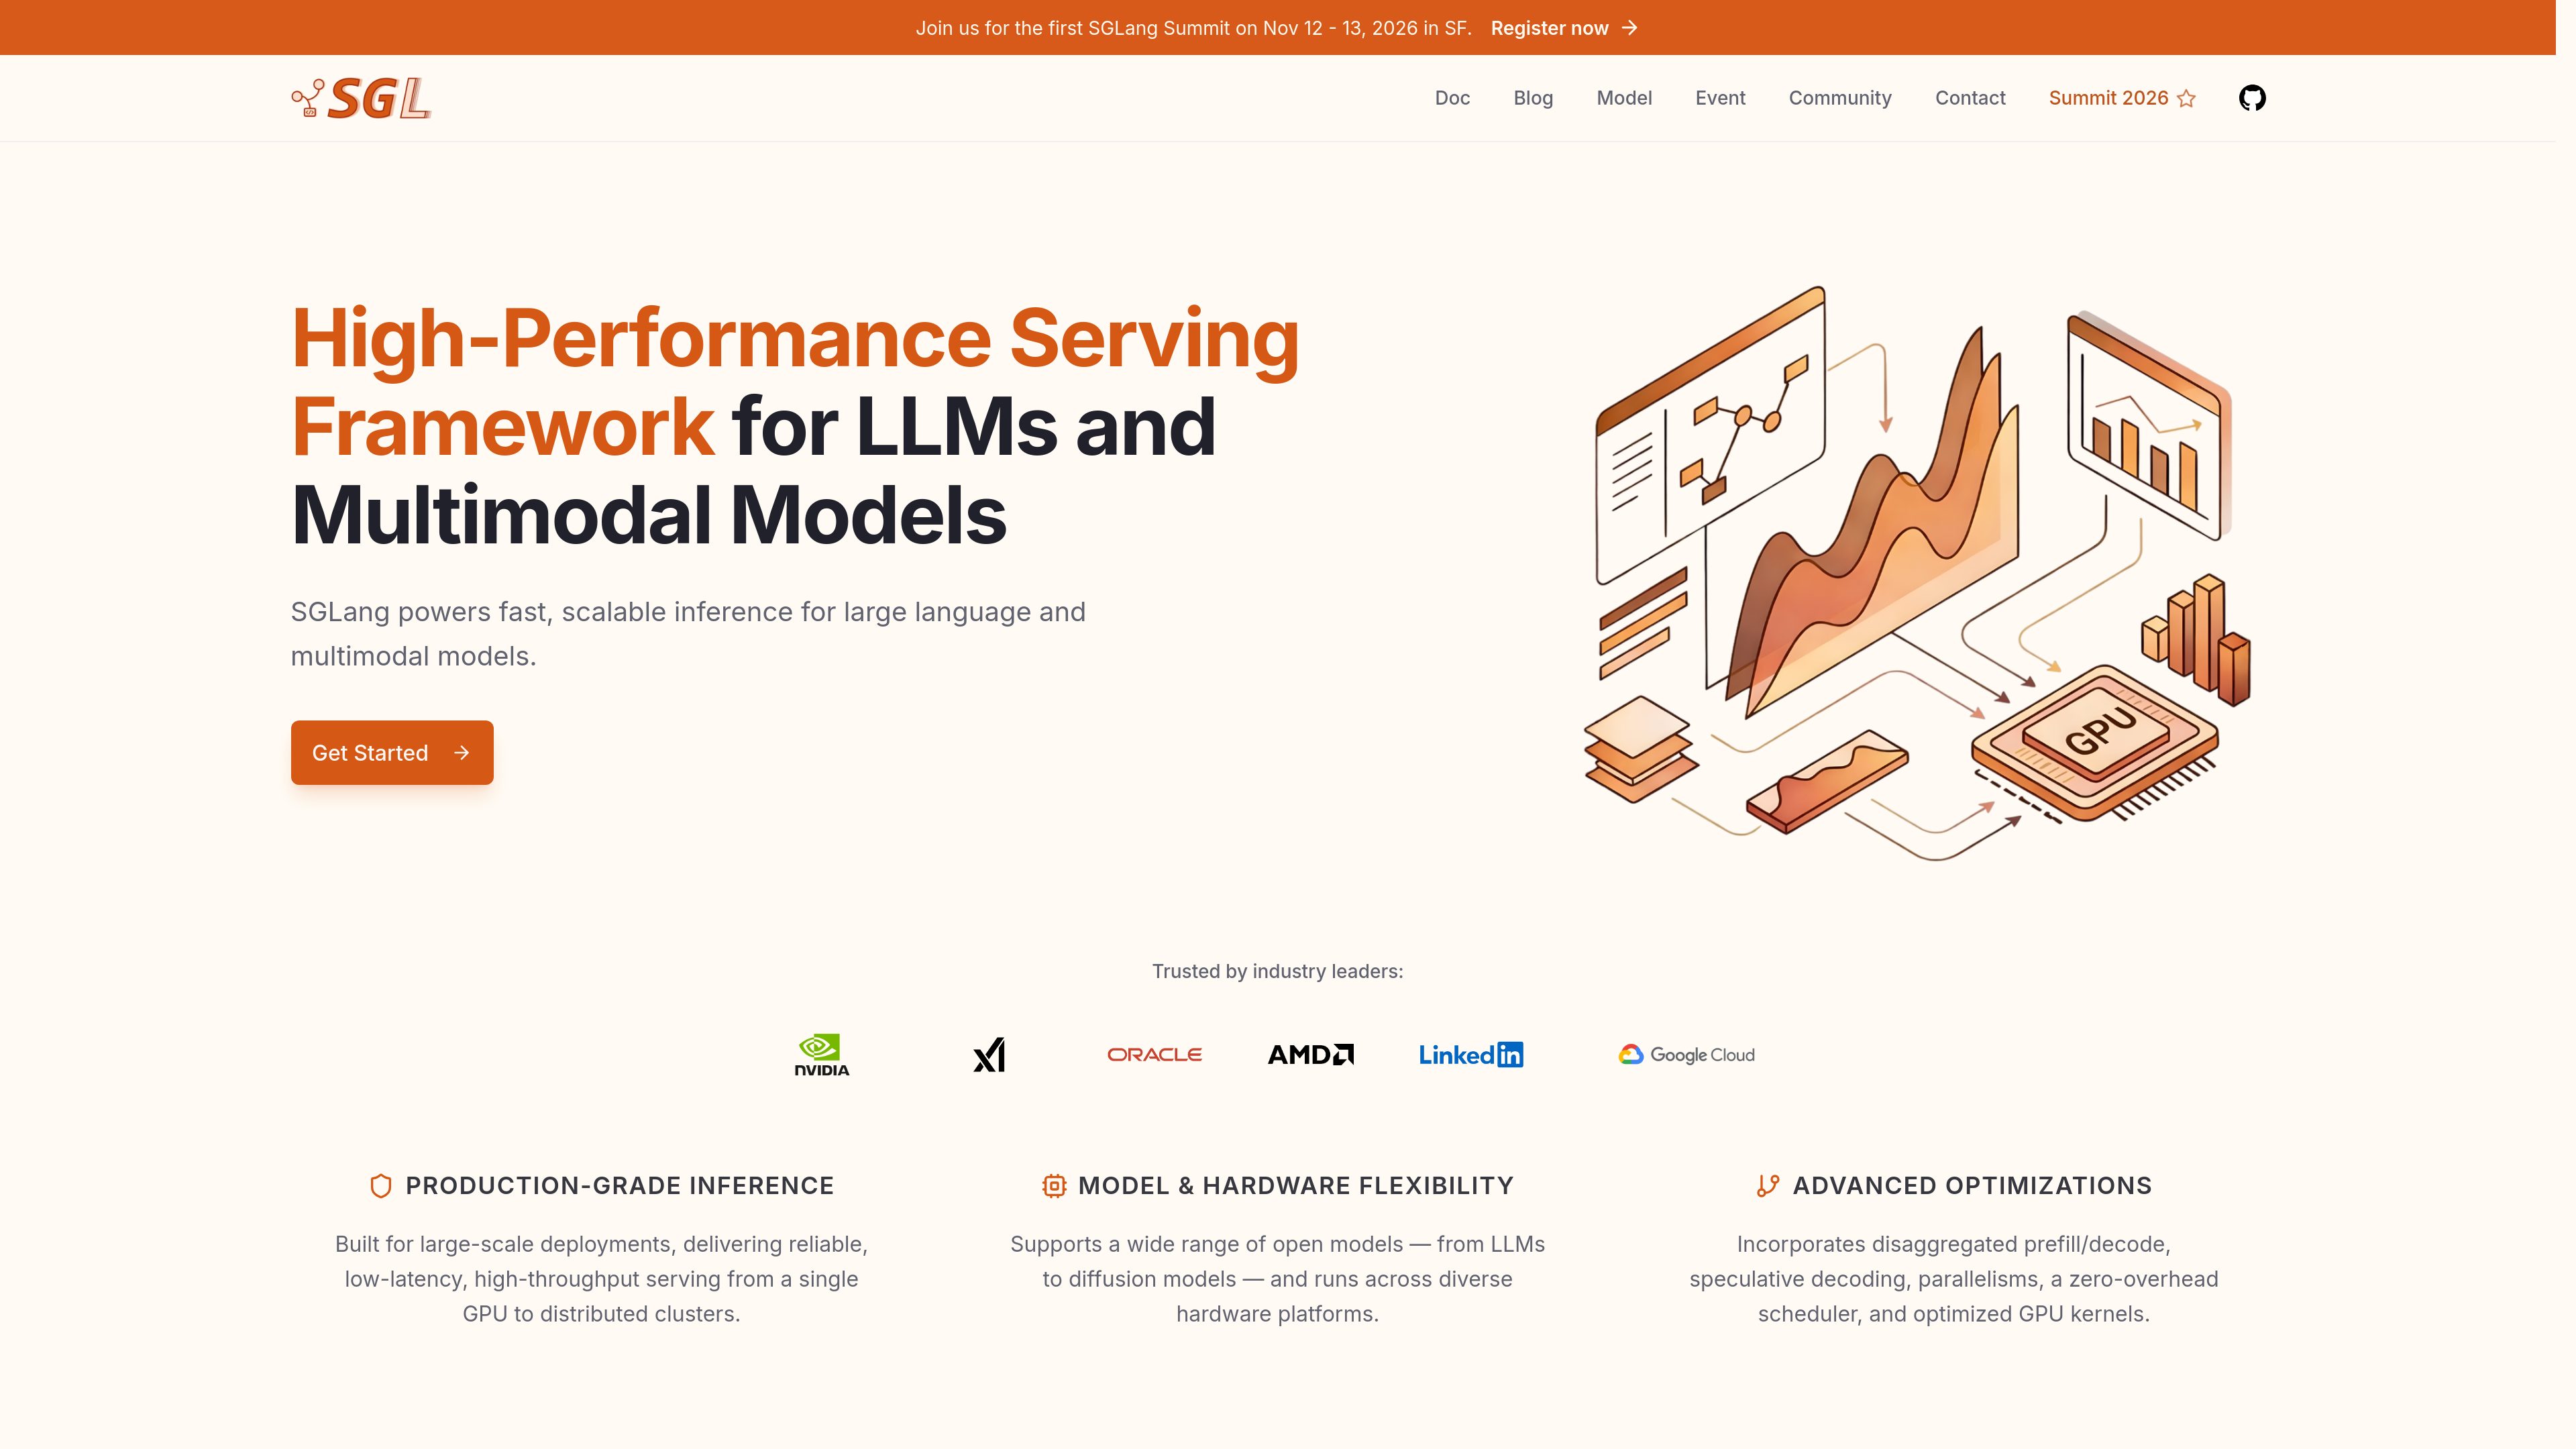
Production-oriented model serving
Runs inference workloads from a single GPU to distributed clusters, with the site positioning the framework for low-latency and high-throughput deployments.

SGLang is an open-source serving framework for large language and multimodal models. It helps developers deploy model servers and query them through OpenAI-compatible endpoints across supported GPU, CPU, TPU, NPU, and XPU platforms.
SGLang is an open-source inference and serving framework for large language and multimodal models. Its core purpose is to run model servers for production workloads, with support for deployments ranging from a single GPU to distributed clusters.
The framework combines model and hardware flexibility with serving optimizations intended to improve latency and throughput. It supports language, vision-language, diffusion, and other multimodal model workloads on platforms including NVIDIA and AMD GPUs, CPU servers, TPUs, Ascend NPUs, and XPUs.
A typical workflow is to install SGLang through pip or Docker, start a server for a selected model, and query it through OpenAI-compatible endpoints.
Runs inference workloads from a single GPU to distributed clusters, with the site positioning the framework for low-latency and high-throughput deployments.
Supports open model families including DeepSeek, Qwen, Llama, Mistral, and GLM, as well as vision-language, diffusion, OCR, speech, and other multimodal models listed in the model catalog.
The supported hardware list includes NVIDIA GPUs, AMD GPUs, CPU servers, Google TPUs, Ascend NPUs, and XPUs.
Includes disaggregated prefill and decode, speculative decoding, multiple parallelism strategies, a zero-overhead scheduler, and optimized GPU kernels.
After a server is launched, applications can interact with the selected model through standard OpenAI-compatible endpoints.
The project includes radix-tree caching capabilities and related ecosystem projects such as a Kubernetes operator for serving, GPU scheduling, and model lifecycle management.
Developers can install the framework, launch a server against a supported language or multimodal model, and connect an application through OpenAI-compatible API endpoints.
Teams evaluating supported reasoning, coding, and agent-oriented models can use the serving engine and its parallelism, caching, and decoding optimizations as part of a model-serving stack.
The model catalog covers vision-language, OCR, image, video, audio, and diffusion models, making the framework applicable to supported non-text inference workloads as well as standard LLM serving.
Organizations running model services across clusters can use the framework's distributed serving capabilities and explore the surrounding ecosystem, including OME, a Kubernetes operator for LLM serving, GPU scheduling, and model lifecycle management.
Related projects in the ecosystem support speculative-decoding draft-model training, reinforcement-learning data generation, and large-scale MoE post-training workflows built around SGLang.
The site describes a three-step workflow: install SGLang with pip or Docker, launch the server with a selected model, and query it through an OpenAI-compatible API. Platform-specific package commands depend on the chosen runtime and hardware.
The catalog includes LLMs, mixture-of-experts models, vision-language and other multimodal models, diffusion models, OCR models, and speech-related models. Examples of listed model families include DeepSeek, Qwen, Llama, Mistral, and GLM.
The site lists NVIDIA GPUs, AMD GPUs, CPU servers, TPUs, Ascend NPUs, and XPUs. Actual compatibility depends on the model, backend, and platform-specific support.
Yes. The documented basic workflow uses standard OpenAI-compatible endpoints after the SGLang server is launched.
Yes. The site presents SGLang as an open-source serving framework and links to its codebase and community resources.

vllm.ai
面向大语言模型的高吞吐、内存高效推理与服务引擎,支持通过 OpenAI 兼容 API 部署开源模型。

cloud.sambanova.ai
面向开发者的 AI 推理平台,通过 API 提供对开源语言和视觉模型的访问,支持使用 OpenAI 兼容 API、在线体验场和模型目录构建及测试 AI 应用。
chutes.ai
Chutes is a decentralized, serverless AI inference platform for deploying, running, and scaling open-source models. Developers can access hosted models through an API or deploy private custom workloads on confidential GPU capacity.
sambanova.ai
面向开发者、企业和基础设施运营者的 AI 推理平台,支持运行大型开源模型和智能体工作负载,并适用于云端、本地、混合及隔离环境。
parasail.io
面向 AI 原生初创团队的推理云,通过兼容 OpenAI 的 API 提供开放模型与前沿模型,并支持无服务器、弹性、专用和批量部署,按令牌或 GPU 计费。

friendli.ai
面向生产环境部署前沿开放权重模型和自定义 AI 模型的推理云,提供无服务器模型 API、专用 GPU 端点及 BYOG 选项,支持智能体、多模态和高吞吐工作负载。