
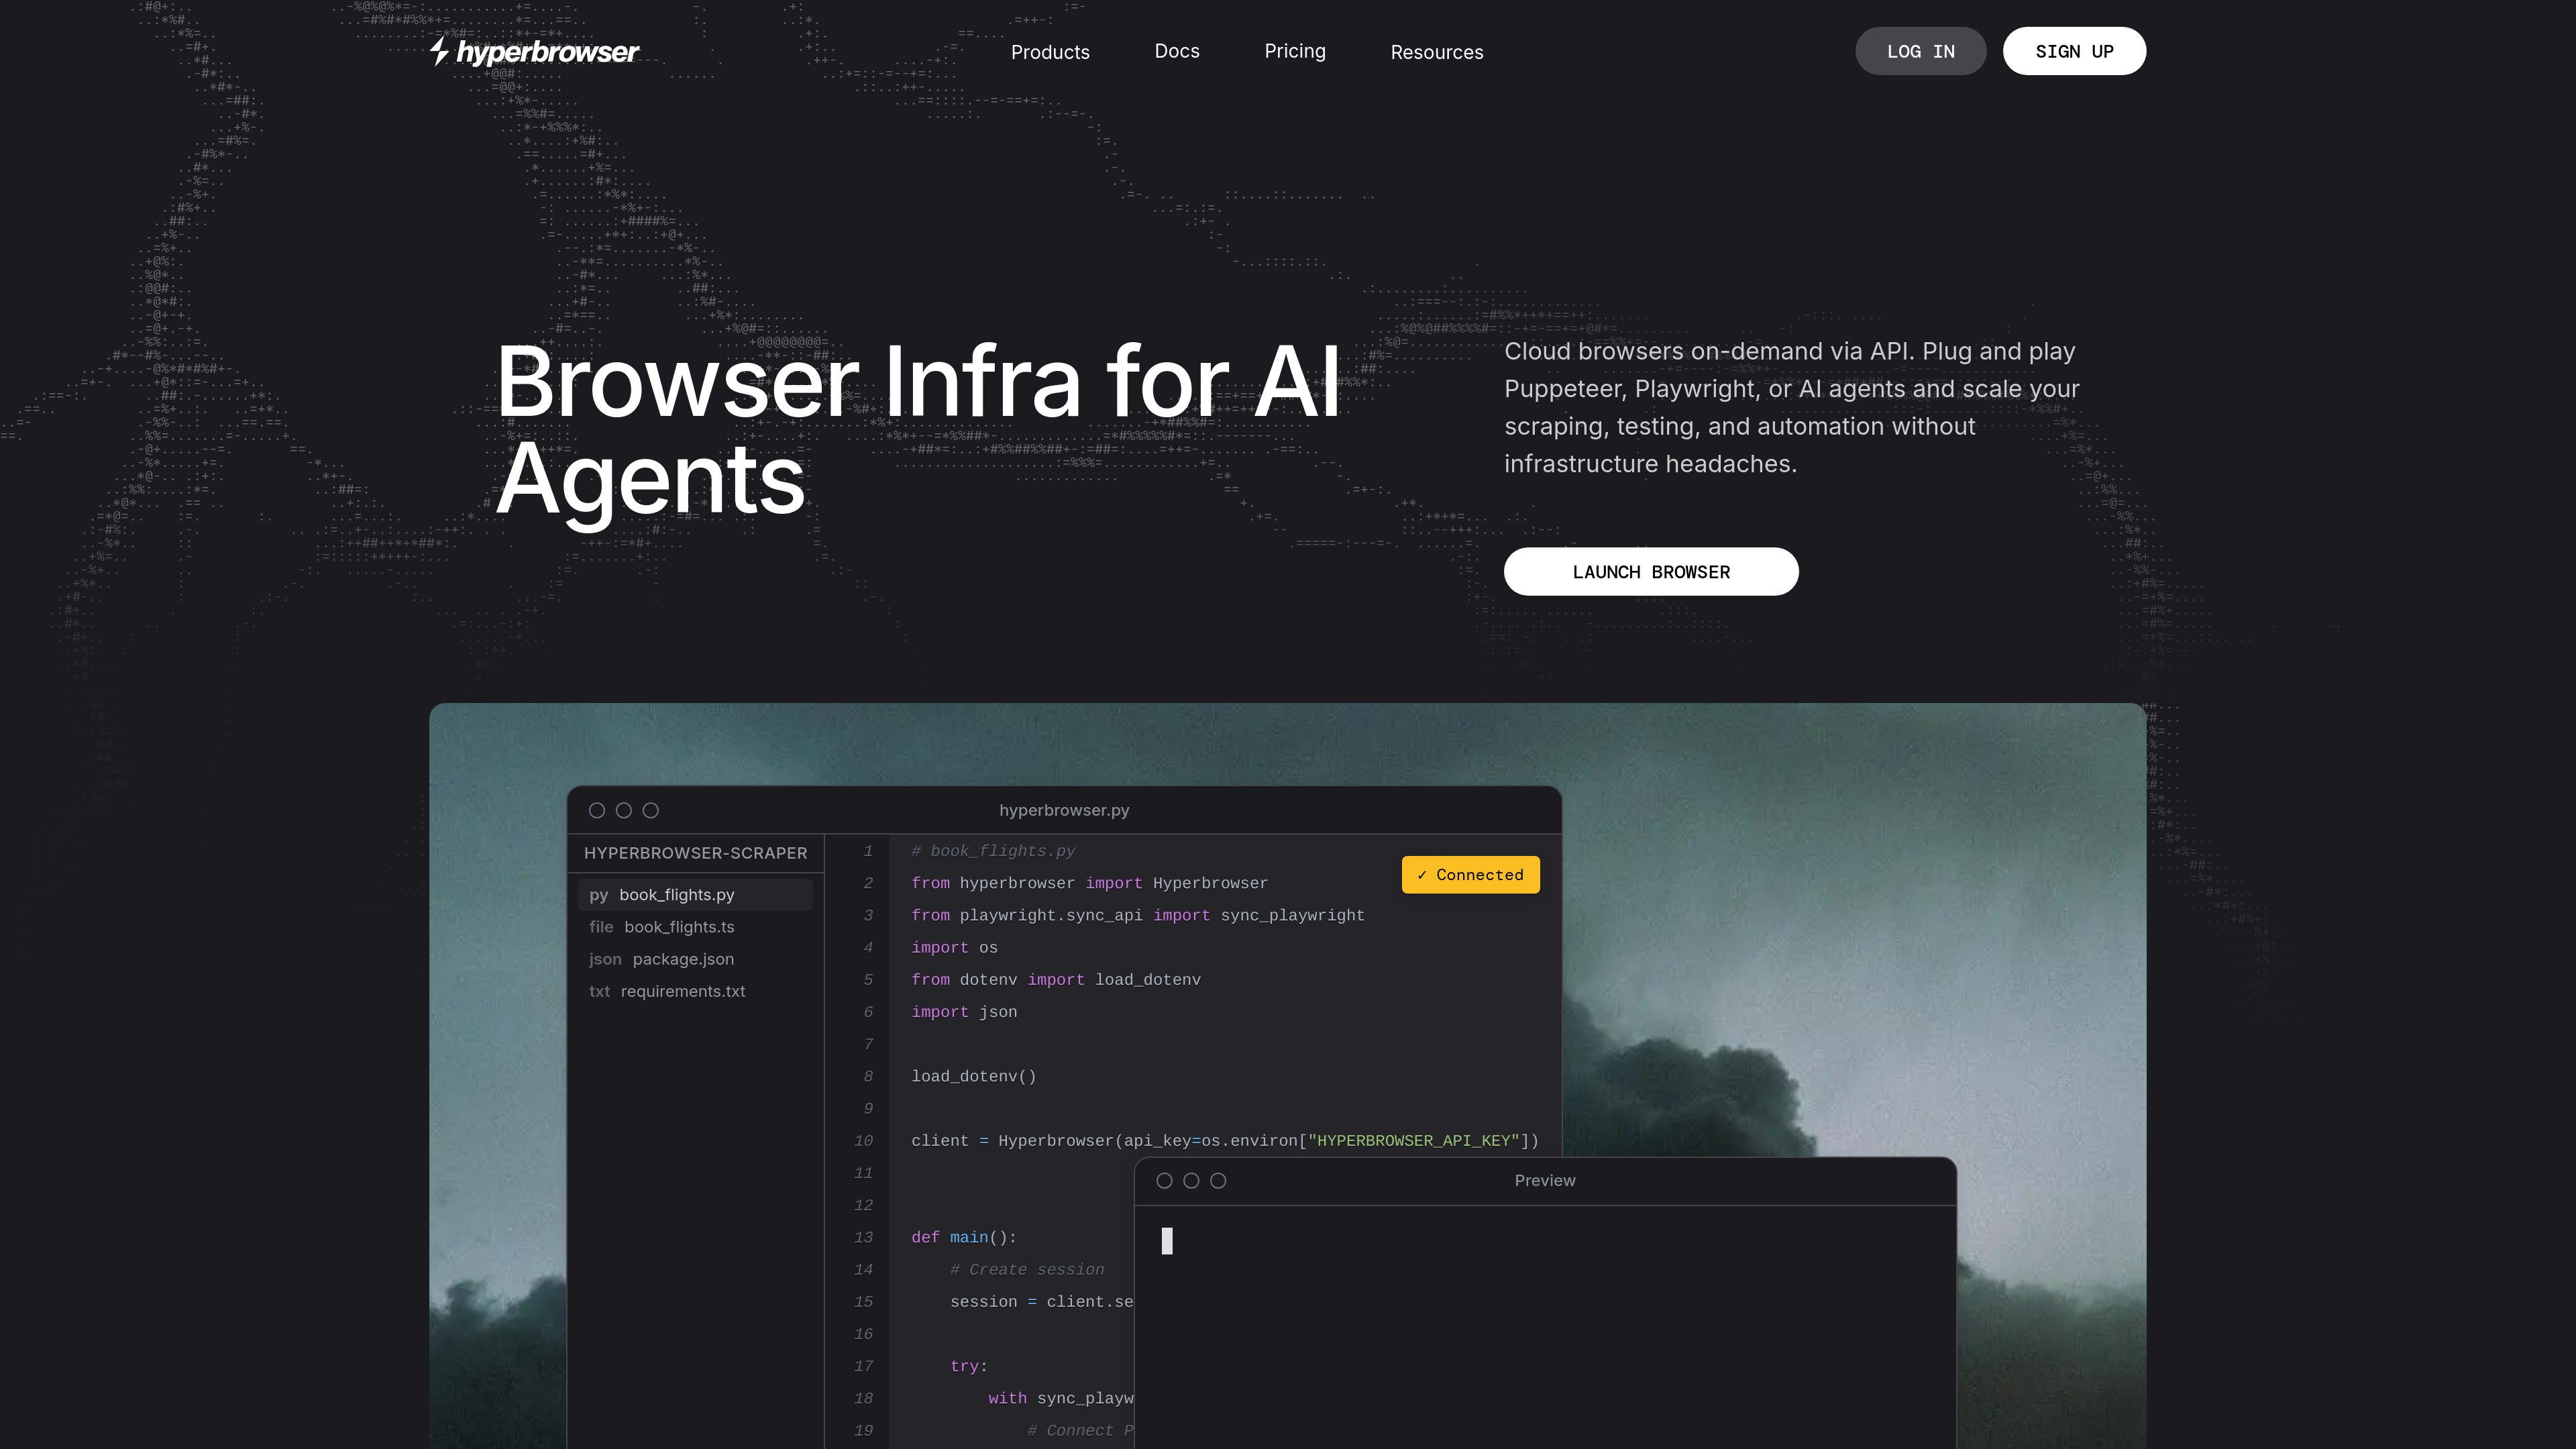
On-demand cloud browser sessions
Create and manage browser sessions through the platform instead of running browser infrastructure locally.

Hyperbrowser provides on-demand cloud browsers and sandboxes for AI agents, web automation, scraping, testing, and agentic code execution. It connects browser workflows through an API, Playwright, Puppeteer, Python, or Node.js.
Hyperbrowser is browser infrastructure for AI agents and automation. It provisions cloud browser sessions on demand and lets existing Playwright or Puppeteer scripts connect through a browser session, so teams can run web workflows without managing browser infrastructure directly. The documentation also presents sandboxes for agentic code execution and large-scale web scraping.
The platform supports browser session management, Web API access, AI-powered browser automation, stealth and proxy configuration, and SDK-based integration. Its home-page example shows a Python workflow that creates a session, connects Playwright over CDP, navigates to a flight-search site, fills form fields, and interacts with the page.
Hyperbrowser uses credit-based billing. The pricing page lists a free plan with 5,000 credits, one concurrent browser, and seven days of data retention; paid plans add higher concurrency and features such as captcha solving, stealth modes, and residential proxies. Enterprise availability includes higher concurrency, longer retention, premium support, and compliance offerings stated on the pricing page.
Create and manage browser sessions through the platform instead of running browser infrastructure locally.
Connect existing automation scripts to cloud browsers, including a documented Playwright-over-CDP workflow.
Use the Web API or the documented Python and Node SDKs to integrate browser sessions into applications.
Support AI-powered browser automation and sandbox-based agentic code execution alongside scraping and automation tasks.
Documentation covers anti-detection features and proxy configuration; paid plans list basic or ultra stealth modes and residential proxy access at applicable tiers.
Credit-based billing measures active browser time and proxy data, while paid plans provide higher concurrent-browser limits.
Run cloud browser sessions for web scraping workflows that need to navigate pages and interact with sites rather than only issue basic requests.
Give an AI-powered automation agent a managed browser session for tasks such as navigating websites, completing forms, and extracting results.
Connect Playwright or Puppeteer test scripts to remote cloud browsers so browser execution is handled as an external service.
Use the documented sandbox capability for workflows in which an agent needs an execution environment in addition to browser access.
Automate multi-step processes such as the documented flight-search example, including navigation, field entry, and button interaction.
Use a Hyperbrowser session and connect an existing Playwright or Puppeteer workflow to the cloud browser. The home-page example uses Playwright's `connect_over_cdp` with a session WebSocket endpoint.
The documentation includes Python and Node SDK resources, as well as a Web API and API reference.
The pricing page uses credits: active browser sessions are billed at 100 credits per hour per browser instance, proxy usage at 10,000 credits per gigabyte, and API calls are listed as free. Plans and included credits vary by tier.
Yes. The pricing page lists a free plan with 5,000 included credits, one concurrent browser, and seven days of data retention.
The documentation includes stealth and proxy configuration resources. The pricing page lists basic or ultra stealth modes and residential proxy access on specified paid tiers.

steel.dev
Steel is open-source browser infrastructure for AI agents and web automation. It provides cloud browser sessions through an API, with support for common browser automation tools and workflows such as scraping, research, RPA, and agent-driven web tasks.

www.notte.cc
Notte is browser infrastructure for AI agents and production web automation. It provides managed cloud browsers, AI-driven workflows, developer interfaces, and operational tools for authenticated or recurring web tasks.
www.simular.ai
Simular is an autonomous computer platform that uses AI agents to operate real computers and automate digital workflows. It serves individuals, builders, operators, and businesses that need to automate tasks across desktop applications and websites, including workflows that do not expose traditional APIs.

www.browseract.com
BrowserAct is a no-code AI web scraping and browser automation platform that builds reusable Bots from plain-language data requests. It helps teams collect structured, refreshed web data in the cloud or give local AI agents a browser layer for web tasks.

apify.com
Apify is a marketplace and platform for running web-scraping and browser-automation tools, called Actors. It helps developers and teams collect live web data, feed AI and data workflows, automate browser tasks, and connect runs to external tools.

www.stagehand.dev
Stagehand is an SDK for building browser agents with Playwright-style APIs, natural-language actions, structured extraction, and self-healing behavior. It supports TypeScript, Python, and Go for agents that need to operate web pages with browser-level control.