
Vector and hybrid search
Run approximate nearest-neighbor vector searches with documented recall above 90%, and combine dense or sparse vector search with full-text strategies.

turbopuffer is an object-storage-native search engine for vector, full-text, hybrid, and regex search. It helps AI, search, and data teams retrieve content from large document collections with filtering, ranking, and scalable namespace-based storage.
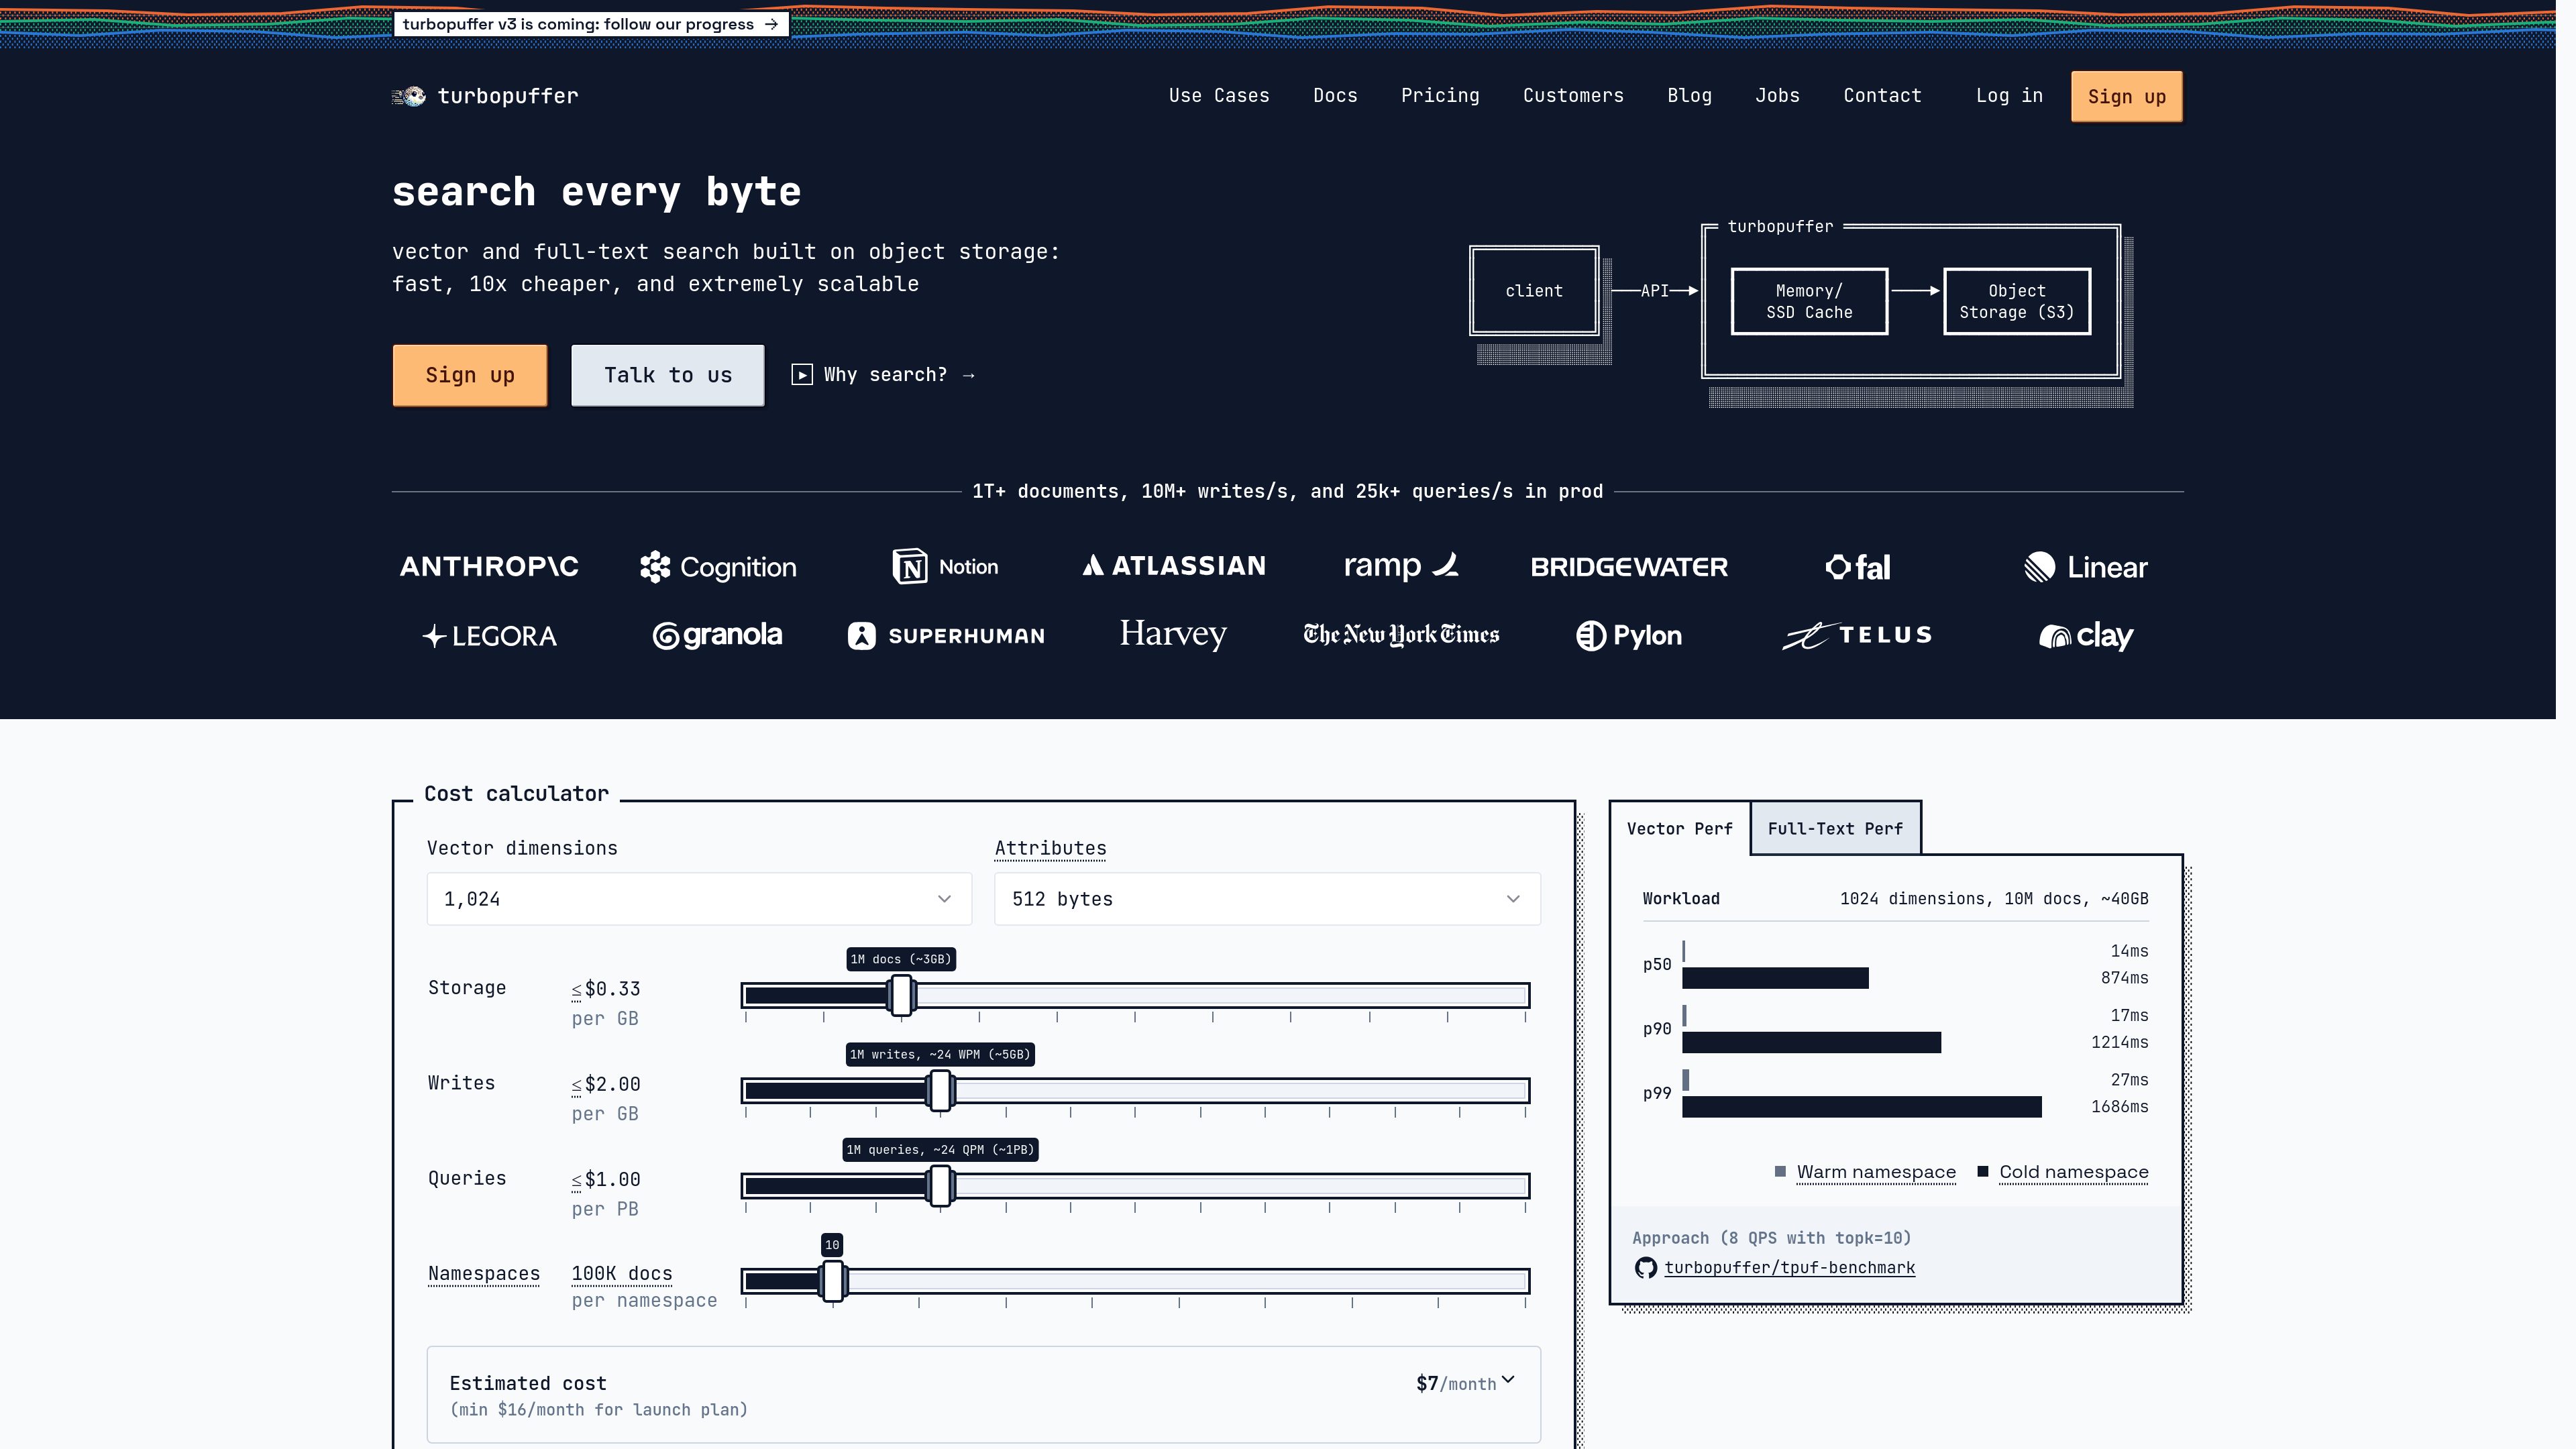
turbopuffer is a hosted, object-storage-native search engine for vector, full-text, hybrid, and regex search. It uses object storage as the durable source of state, with memory and NVMe SSD caches for query execution, so applications can search large collections without keeping the entire index in memory.
The service supports metadata filtering, ranking, boosting, document lookup, and namespace-based organization. It is intended for search across text, images, videos, web pages, agent memories, and other indexed data. The documented API includes operations to create, update, and delete documents, plus queries with filters and ranking.
Its architecture is designed for large-scale workloads: the site reports production systems handling more than 1 trillion documents, 10 million writes per second, and 25,000 queries per second. The documented tradeoffs include higher write latency from writing directly to object storage and slower occasional queries for uncached or unpinned data.
Run approximate nearest-neighbor vector searches with documented recall above 90%, and combine dense or sparse vector search with full-text strategies.
Search text with an inverted index, BM25 ranking, and boosting. Fast trigram regex indexes support pattern-based retrieval in addition to keyword and semantic search.
Apply metadata filters while querying documents, then use ranking and boosting to control how matching results are ordered.
Use object storage for durable state and memory or NVMe SSD caches for compute. The architecture is intended to scale across very large document collections and high-throughput workloads.
Organize data in namespaces for multi-tenant or application-specific isolation. Copy-on-write branching creates a namespace clone in constant time while keeping later reads and writes independent.
The pricing tiers list multi-tenant deployment across plans, with single-tenant and BYOC options at Enterprise. Available higher-tier controls include SSO, audit logs, private networking, and per-namespace CMEK.
Give agents semantic and full-text tools for retrieving relevant documents, web content, memories, reasoning transcripts, tool calls, or evaluation data during a task.
Index and filter large collections of documents and multimedia files so applications can locate the small set of relevant records, files, or media assets for a user.
Build search tools backed by an index of news, papers, or broader web content, allowing agents and applications to retrieve from a maintained corpus.
Match articles, products, or other content to items a user has liked or engaged with using semantic similarity search.
Curate substantial datasets for pre-training or post-training models to search through reinforcement-learning workflows.
The documented product supports vector search, BM25 full-text search, hybrid search combining vector and full-text strategies, metadata filtering, and regex search using trigram indexes.
Object storage is the durable source of state, while memory and NVMe SSD caches provide compute for queries. Cached data can deliver low latency; uncached or unpinned namespaces can produce slower cold queries.
Writing directly to object storage increases write latency; the documentation gives a p90 of 248 ms for 512 KB upserts. Uncached or unpinned data can also have occasional cold-query latency, with a documented p90 of 1,214 ms for a 1-million-document example.
Applications can separate data into namespaces. The product supports multi-tenant deployment by default on listed plans, while Enterprise also offers single-tenant and BYOC deployment options. Copy-on-write branching can create independent namespace copies.
The pricing page lists Launch, Scale, and Enterprise plans. Launch has a $16-per-month minimum, Scale has a $256-per-month minimum, and Enterprise starts at $4,096 per month. Enterprise adds deployment and support options such as single-tenant, BYOC, private networking, and service-level commitments.

vespa.ai
Vespa is an AI search platform for building search, retrieval-augmented generation, recommendation, personalization, and agent applications over text, vectors, tensors, and structured data. It is designed for developer teams that need configurable ranking and distributed operation at production scale.

oriane.xyz
AI-powered video search and data tools for finding, analyzing, and using TikTok and Instagram content.

brave.com
Brave Search API gives developers programmatic access to Brave’s independent Web index for search results, AI-ready context, and grounded answers. It is designed for agents, chatbots, search applications, research tools, and other software that needs current Web data.