Autoscaling inference
Deploy containerized language, image, video, speech, or custom models as endpoints with configurable authentication, readiness checks, and replica limits, including scaling to zero.

Deploy, scale, and fine-tune AI workloads on GPU infrastructure in your own AWS account.
Tensorfuse manages AI workloads inside your AWS environment, from online inference to queued jobs and fine-tuning. It provisions a dedicated EKS cluster through a cross-account IAM role, with model-serving workloads running in your VPC. Teams can configure GPUs, endpoint settings, secrets, persistent storage, and deployment automation while using their own models and cloud resources.
Deploy containerized language, image, video, speech, or custom models as endpoints with configurable authentication, readiness checks, and replica limits, including scaling to zero.
Deploy jobs, submit parameterized runs, and poll their status for batch inference, data processing, or evaluation.
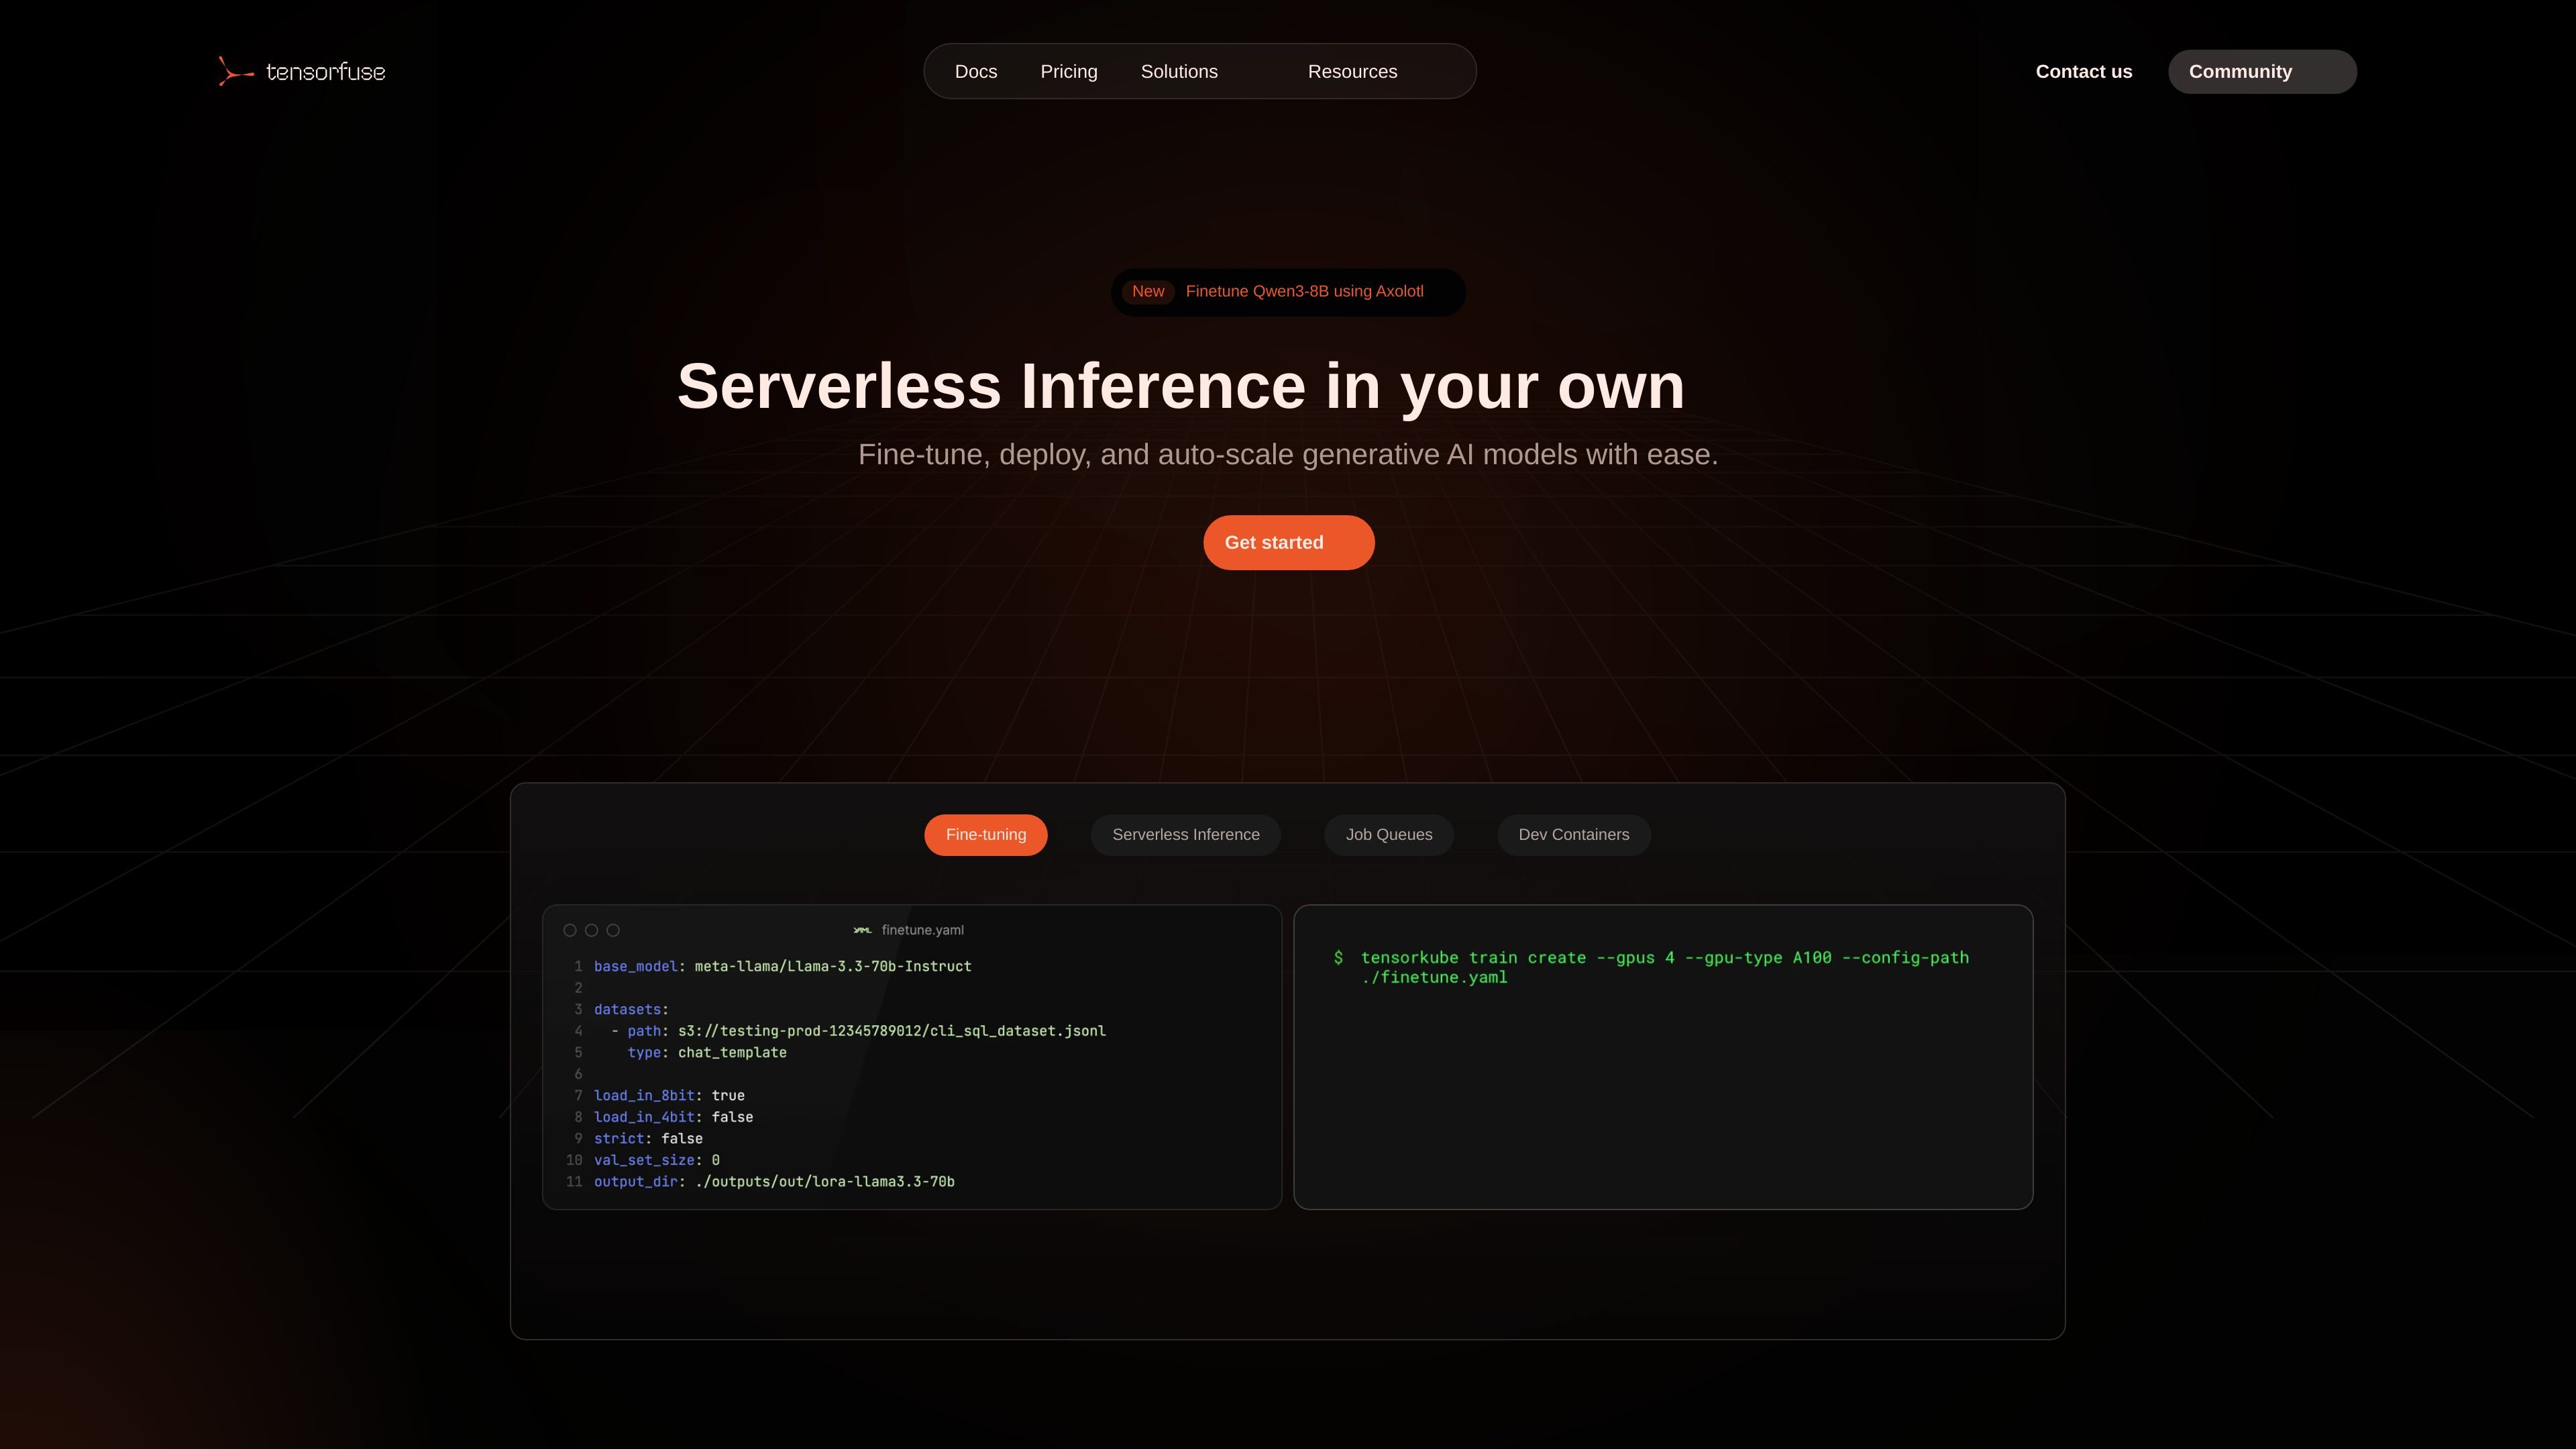
Run Axolotl, Unsloth, Hugging Face, or custom training workflows. The Axolotl guide supports several dataset formats, hyperparameter sweeps, model comparisons, and Weights & Biases monitoring.
Synchronize local code with GPU development containers for interactive experiments without manually using SSH.
Use private S3 storage, project secrets, persistent volumes, and GitHub Actions to support repeatable deployments.
Serve a chosen model to applications with changing request traffic.
Queue separate inference or data-processing runs with their own payloads.
Compare fine-tuning configurations on your dataset and evaluate resulting adapters or models.
Model serving runs in your VPC, but you must configure network access, storage permissions, and external integrations. For example, the Axolotl workflow can upload models to Hugging Face Hub and send experiment information to Weights & Biases.
The Axolotl workflow supports JSONL, CSV, Parquet, and Hugging Face datasets, including instruction and conversation formats.
The Hacker plan includes 100 managed GPU hours for serverless inference and development containers. Infrastructure runs in your AWS account; startup offers depend on eligibility and existing cloud credits.
Os dados de tráfego são apenas para referência.