
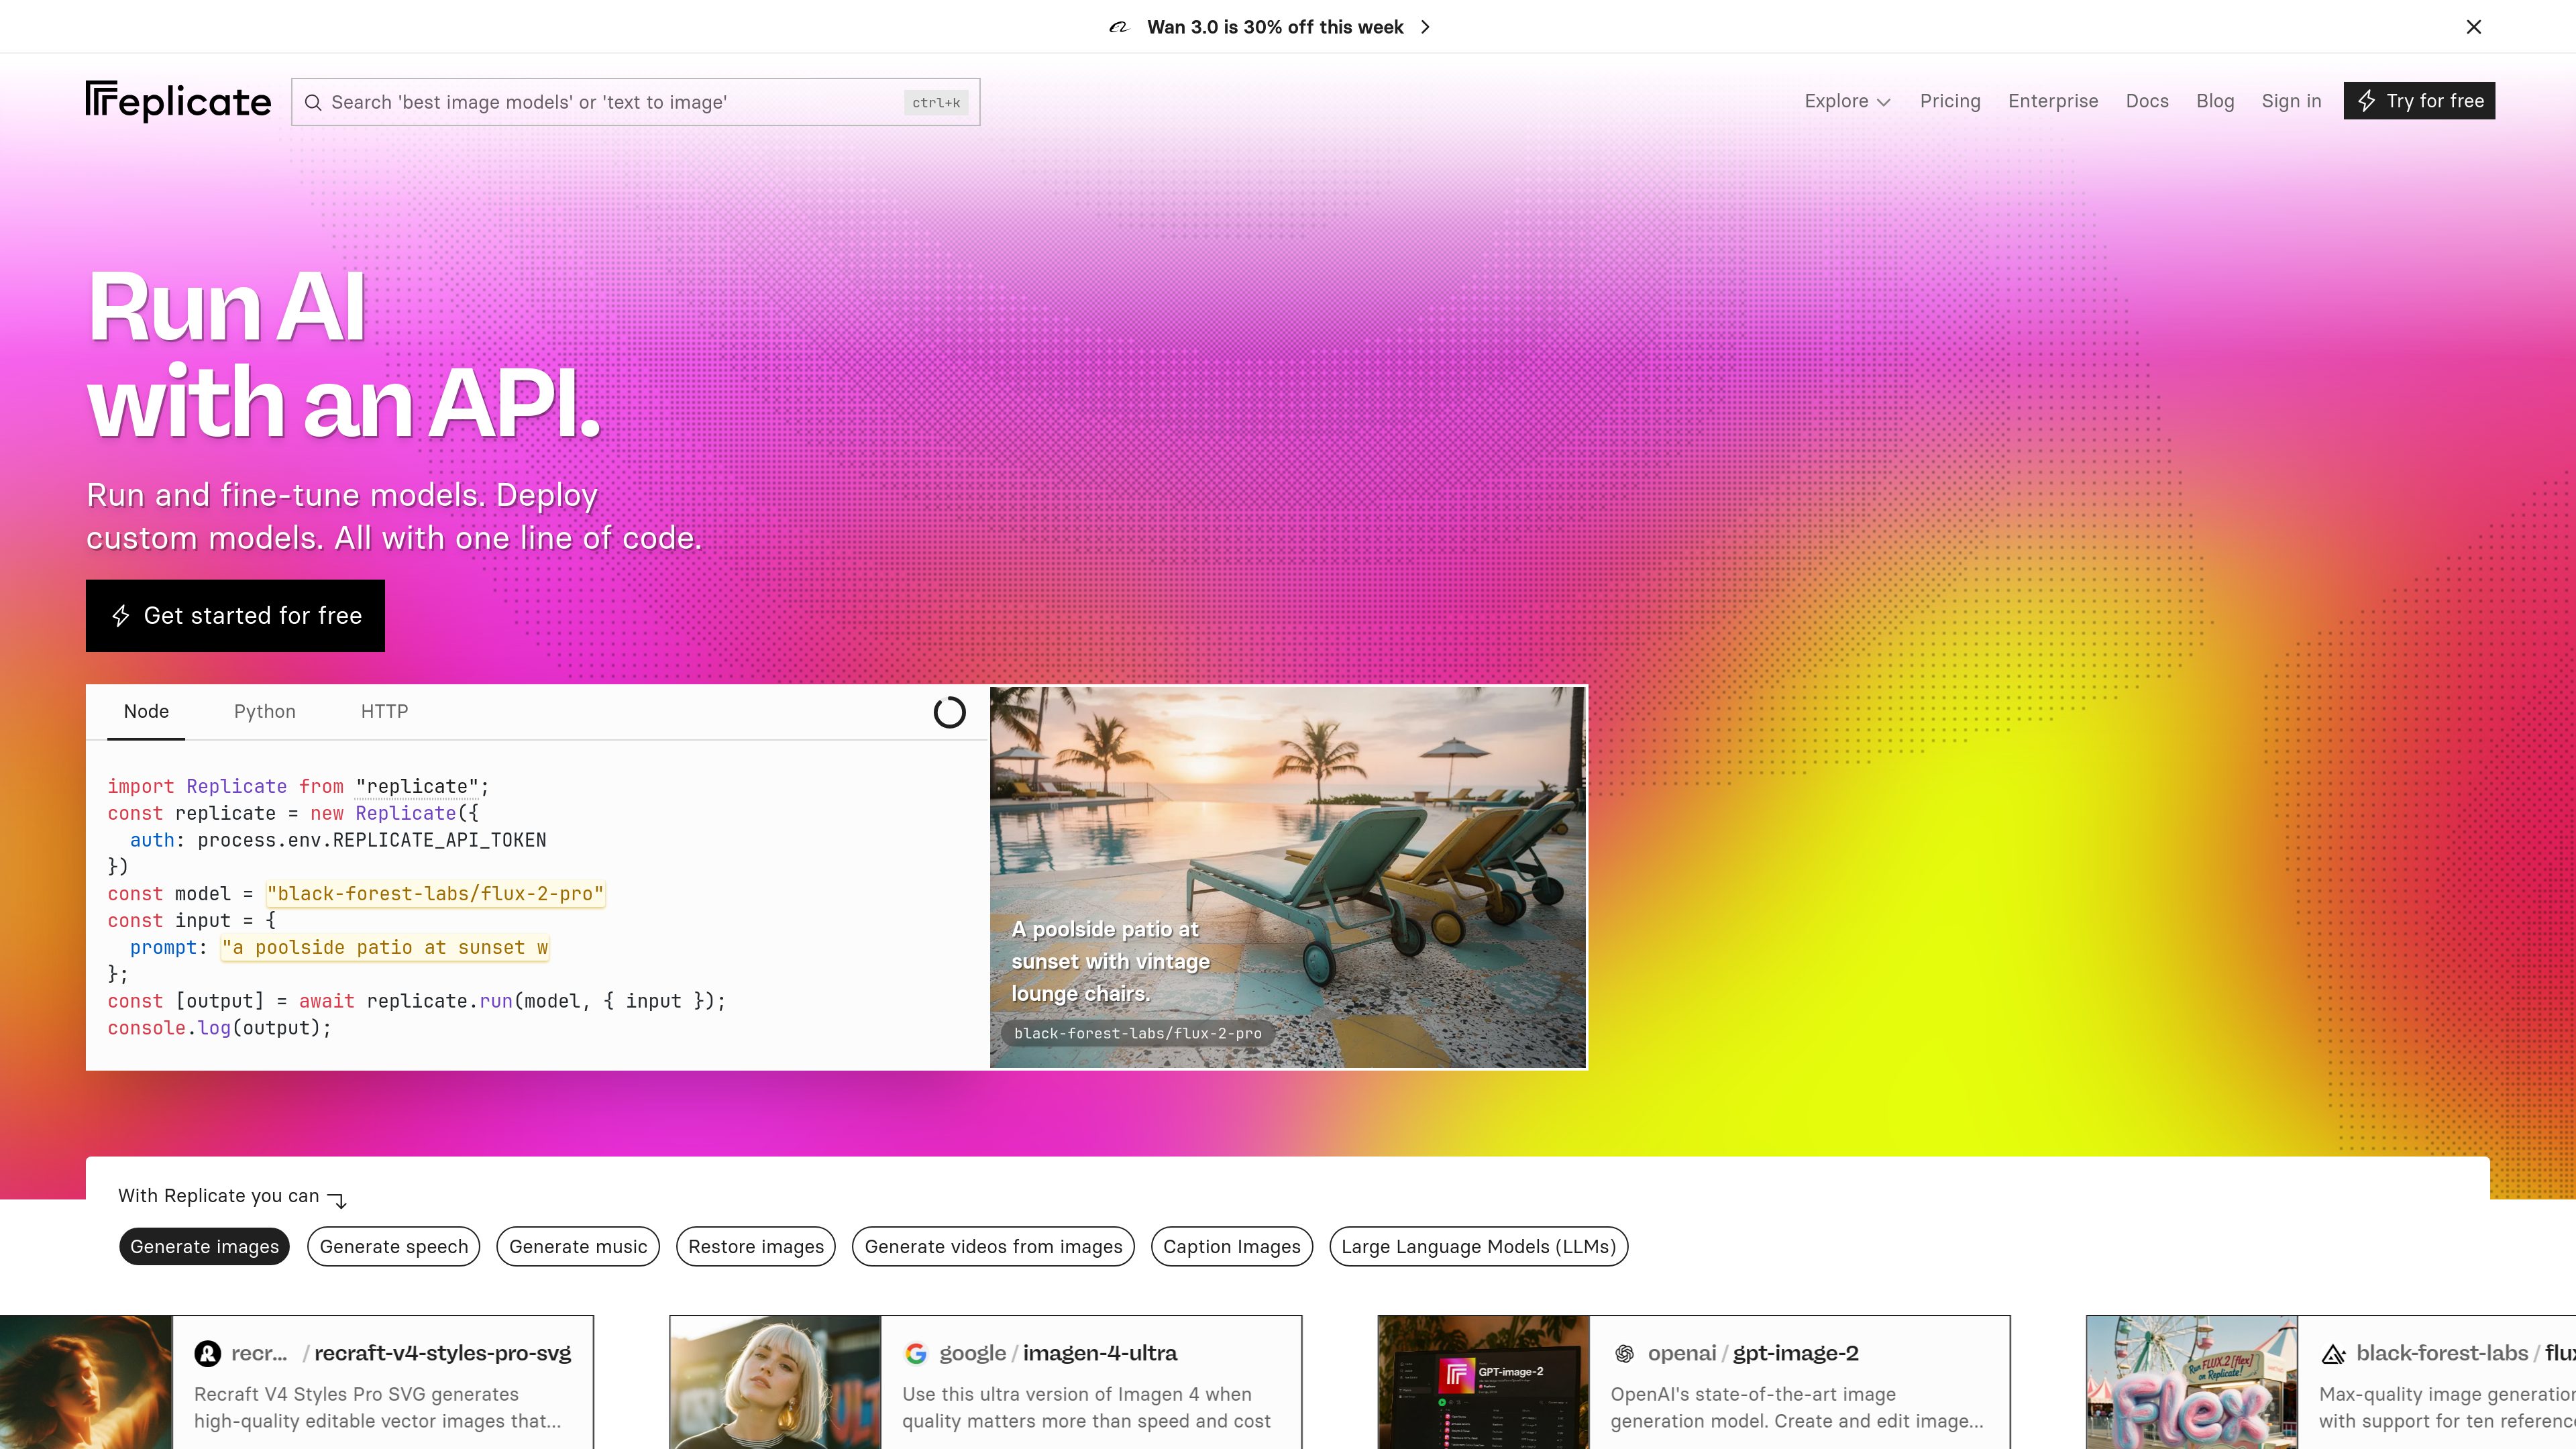
Hosted model catalog
Run community-contributed open models and proprietary models from Replicate’s catalog. The site lists tasks such as image, video, speech, music, and language generation, as well as image restoration and captioning.
Run, fine-tune, and deploy machine-learning models through a cloud API.
Replicate is a cloud platform for running machine-learning models through an API. It brings together community-contributed open models and proprietary models, with catalog tasks including image and video generation, speech and music generation, image restoration, captioning, and large language models. Developers can call models from code, fine-tune them, or package and deploy custom models.
The platform makes model execution available through an API workflow, without requiring users to host every model themselves. Public model pages provide model information and cost estimates. Pricing varies by model: some usage is billed according to hardware and runtime, while other models charge by input or output units. Custom deployments have a different cost profile, since most private models are billed for the time their hardware instances remain online.
Run community-contributed open models and proprietary models from Replicate’s catalog. The site lists tasks such as image, video, speech, music, and language generation, as well as image restoration and captioning.
Call a model from application code using a cloud API. Documentation provides getting-started guides for Node.js and Python, along with an HTTP API reference.
Fine-tune supported models through Replicate; the documentation includes a guide to fine-tuning an image model.
Deploy custom models using Cog, Replicate’s open-source tool for packaging machine-learning models, then serve them as private models.
Public model charges depend on the model: many are billed for processing time on the hardware used, while others charge by input or output. Model pages show cost estimates.
Replicate says private model instances can scale up and down with demand. Most private models use dedicated hardware and incur charges while online, including setup and idle time.
Use API calls to connect an application to catalog models for generating images, videos, speech, or music, selecting a model suited to the requested output.
Compare available model pages and their cost estimates, then make repeatable API calls while assessing model behavior for a project.
Use image restoration, captioning, or image-generation models as steps in a software workflow without setting up each model’s serving infrastructure directly.
Model builders can use Cog to package a model and deploy it privately on Replicate, where the service manages its online instances and demand-based scaling.
Replicate’s basic workflow is to choose a model and call it through the cloud API. Documentation includes getting-started guides for Node.js, Python, and Google Colab, as well as an HTTP API reference.
It depends on the model. Many public models are billed for the time they take to run, at a rate associated with the hardware; others charge by input or output units. Model pages provide cost estimates.
Yes. Use Cog to package and deploy a custom model on Replicate. Models can be public or private: a private model is accessible only to the user or organization that owns it and can later be made public. A Deployment provides a private, dedicated API endpoint for a model.
Most private models run on dedicated hardware and are billed for the time their instances are online, including setup and idle time. Replicate says fast-booting fine-tunes are billed only while actively processing requests.
Os dados de tráfego são apenas para referência.
| mai. | 1255416 |
|---|---|
| jun. | 1218701 |
| jul. | 1079703 |
As análises de tráfego ainda não estão disponíveis.
www.bentoml.com
Bento is an inference platform for packaging, deploying, optimizing, and operating AI and machine-learning models at scale. It supports open and custom models across cloud, on-premises, Kubernetes, and bring-your-own-cloud environments.

baseten.co
Baseten is an inference platform for deploying, serving, and scaling open-source, custom, and fine-tuned AI models. It supports managed cloud, self-hosted, hybrid, and dedicated deployments for teams running production AI workloads.
parasail.io
Parasail is an inference cloud for AI-native startups that provides access to open and frontier models through an OpenAI-compatible API. It offers serverless, elastic, dedicated, and batch deployment options with per-token or GPU-based pricing.

chutes.ai
Chutes is a decentralized, serverless AI inference platform for deploying, running, and scaling open-source models. Developers can access hosted models through an API or deploy private custom workloads on confidential GPU capacity.

www.sglang.io
SGLang is an open-source serving framework for large language and multimodal models. It helps developers deploy model servers and query them through OpenAI-compatible endpoints across supported GPU, CPU, TPU, NPU, and XPU platforms.

huddle01.com
Manage cloud workloads and access multiple AI models through one platform.