
Multiple NVIDIA GPU families
HyperAI offers A100, L4, RTX 6000 Pro and H200 GPU configurations so teams can choose hardware aligned to training, inference or larger context windows.
Infraestrutura empresarial com GPUs NVIDIA para treino, fine-tuning e inferência de IA.
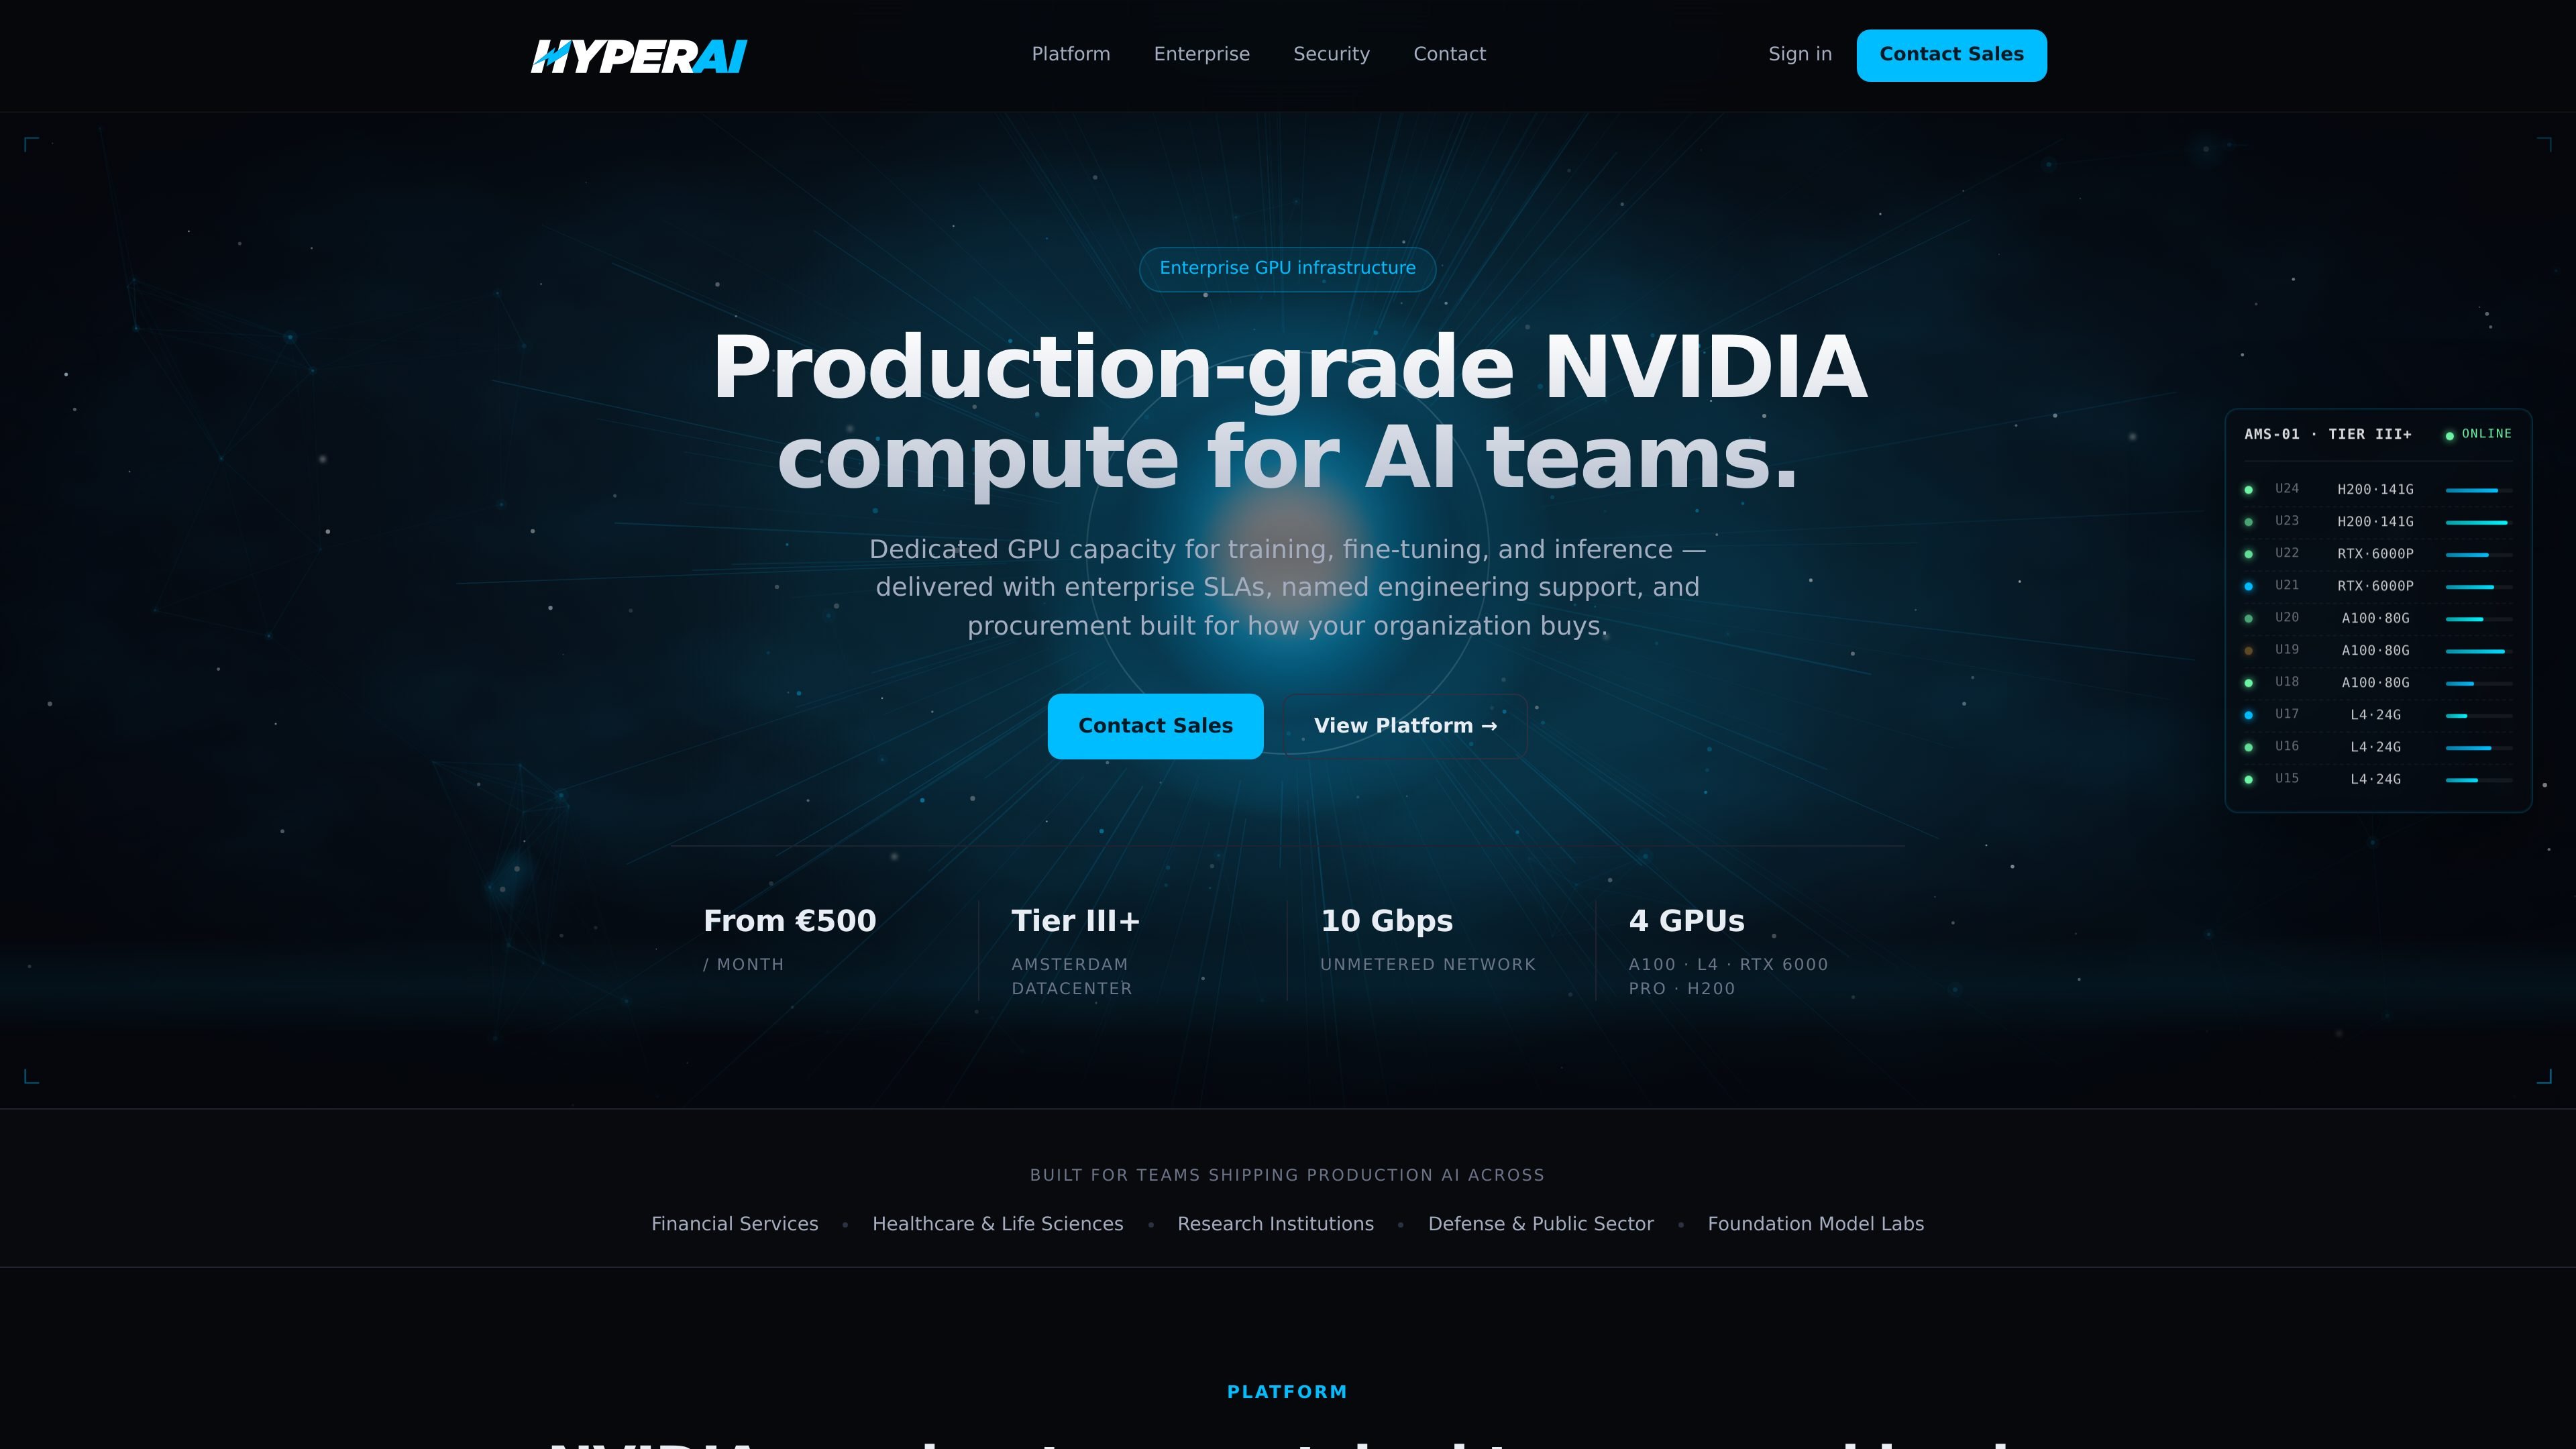
HyperAI is an enterprise GPU infrastructure service for AI teams that need dedicated NVIDIA compute rather than shared cloud instances. The site presents it as production-grade infrastructure for training, fine-tuning, and inference, with hardware options spanning A100, L4, RTX 6000 Pro, and H200.
Its public pages emphasize procurement-friendly deployment options: single-tenant nodes or isolated clusters, SLA-backed uptime, named engineering support, and reserved capacity contracts. Every tier includes a managed infrastructure baseline in an Amsterdam Tier III+ datacenter with 10 Gbps networking and local NVMe storage.
HyperAI offers A100, L4, RTX 6000 Pro and H200 GPU configurations so teams can choose hardware aligned to training, inference or larger context windows.
The homepage describes single-tenant nodes and isolated clusters, which is aimed at environments that need dedicated compute without sharing nodes with other customers.
Each deployment includes a Tier III+ Amsterdam datacenter, 10 Gbps vPort, and unmetered traffic with fair-use terms, giving the service a fixed infrastructure baseline.
Configurations pair the GPU with AMD EPYC processors, NVMe storage, and defined RAM and vCPU tiers, allowing deployments to be sized to workload requirements.
The site states that reserved capacity is available through annual and multi-year contracts with guaranteed allocation and fixed pricing on request.
HyperAI includes named technical support, with a dedicated technical account manager and 24/7 on-call engineers rather than a generic ticket queue.
Use the A100 and H200 configurations for memory-hungry training, fine-tuning, and frontier LLM work where NVLink or HBM capacity matters.
Use L4 for production inference workloads such as chatbots, embeddings, and video pipelines when energy efficiency and right-sized GPU capacity matter.
Use RTX 6000 Pro for large-context inference or dense single-node training when you want a Blackwell-class GPU with 96 GB of memory.
Use the dedicated tenancy and isolated cluster model for organizations that want reserved GPU capacity, fixed pricing on request, and procurement-friendly contracts.
Use the Amsterdam-based infrastructure and named support model for teams that need a managed deployment with clear operational ownership.
HyperAI is a managed enterprise GPU infrastructure service for AI workloads. The homepage positions it for training, fine-tuning and inference on NVIDIA GPUs, with workloads split across A100, L4, RTX 6000 Pro and H200 configurations.
The site shows dedicated single-tenant nodes and isolated clusters, but it does not document self-service setup steps. The public pages present a sales-led procurement flow with platform and spec-sheet links rather than a documented onboarding wizard.
HyperAI lists baseline infrastructure such as a Tier III+ Amsterdam datacenter, 10 Gbps unmetered network, NVMe storage and AMD EPYC CPUs matched to each GPU. Specific software integrations or orchestration tools are not described on the public pages provided.
The homepage says each deployment includes named engineering support, including a dedicated technical account manager and 24/7 on-call engineers. It also mentions SLA-backed uptime with a 99.9% availability commitment and service credits.
The public site does not show a verified pricing page. The homepage lists monthly starting prices for each GPU configuration and notes that annual and multi-year discounts are available on request, with VAT excluded.
Os dados de tráfego são apenas para referência.

crusoe.ai
Crusoe oferece infraestrutura de nuvem para IA, inferência gerenciada e capacidade de data center para treinar e servir cargas de trabalho de IA em escala.
fx.sh
fx é um agente de programação nativo, pequeno e aberto, com CLI para trabalhar com código pelo terminal. Foi desenvolvido para pesquisa, incorporação e uso como parte de sistemas maiores, com suporte à inferência local ou na nuvem.

decart.ai
Decart AI Lab desenvolve modelos do mundo em tempo real e infraestrutura para Physical AI, incluindo Oasis 3 e DOS.
fluidstack.io
Fluidstack constrói e opera infraestrutura de IA em grande escala para entregar capacidade computacional mais rapidamente.
my-legacy.ai
Plataforma web de planejamento de vida e herança para organizar ativos digitais, informações de emergência, credenciais e mensagens póstumas.

onsecurity.io
Testes de penetração aprovados pela CREST, varredura e inteligência contra ameaças para empresas do Reino Unido