
Multi-source ingestion
Ingests files, text, URLs, feeds, and connected accounts, including PDFs, audio, video, web pages, Slack messages, email, and knowledge base sources.

Camada de contexto para agentes de IA com conteúdo pesquisável e fundamentado
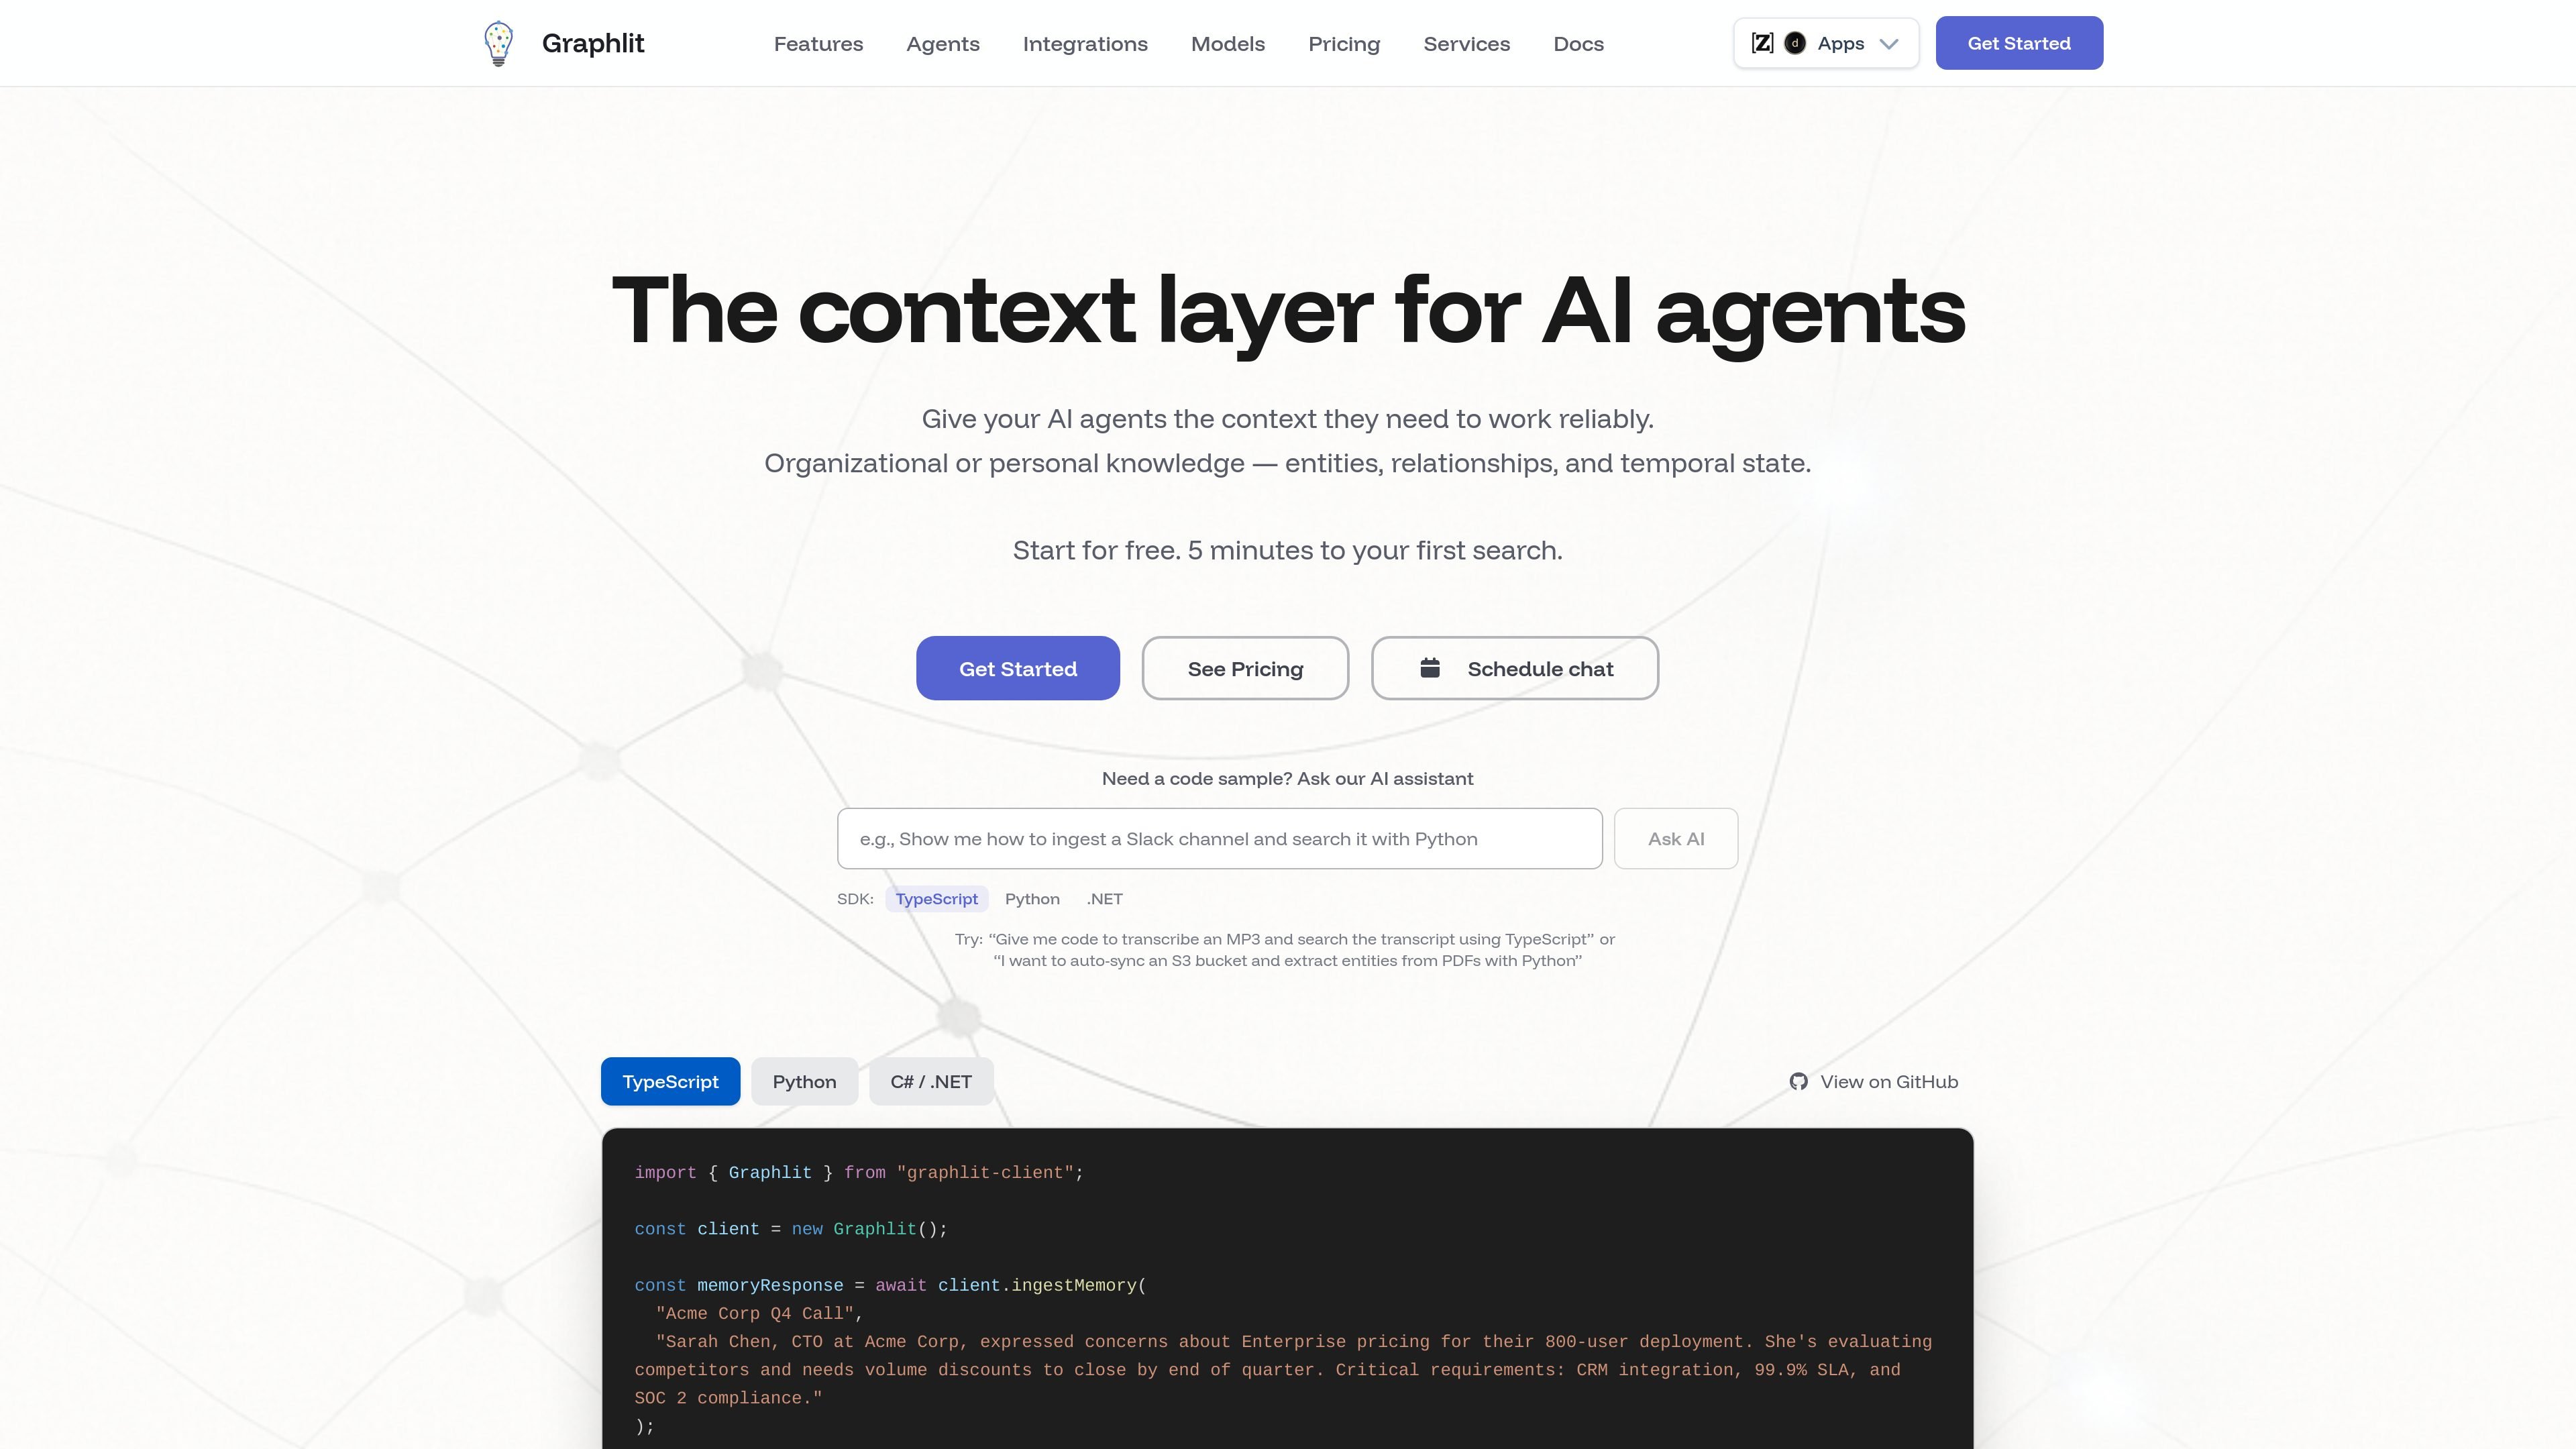
Graphlit is a context layer for AI agents and applications that need to work with organizational knowledge instead of isolated chat memory. It combines ingestion, extraction, search, chat, and knowledge graph workflows behind a single API.
The product is designed to bring content from files, web pages, messages, storage systems, and business tools into a searchable context layer. The site emphasizes real-time or continuous sync, provenance, and grounded answers so agents can use source-backed information rather than static prompts or ad hoc glue code.
Ingests files, text, URLs, feeds, and connected accounts, including PDFs, audio, video, web pages, Slack messages, email, and knowledge base sources.
Supports preparation, extraction, and enrichment workflows, with built-in transcription, OCR, embeddings, and completions.
Provides semantic search, keyword search, and hybrid search, plus source-grounded conversations with citations for retrieval-augmented use cases.
Extracts entities, observables, relationships, and temporal state to build organizational knowledge graphs rather than simple document indexes.
Connects to tools such as Slack, GitHub, Jira, Notion, Google Drive, S3, Gmail, Dropbox, and more, with continuous sync mentioned in the product messaging.
Offers SDKs and an MCP server for developer workflows, including TypeScript, Python, and .NET support and access from tools such as Claude, Cursor, and ChatGPT on higher plans.
Build assistants that answer from company knowledge with source citations, multi-turn memory, and retrieval over documents, messages, and connected apps.
Sync and search operational content from tools like Slack, GitHub, Jira, Notion, and email so teams can find context without manual ETL.
Extract people, companies, relationships, events, and ownership from content to support graph queries and relationship-aware applications.
Process PDFs, web pages, audio, video, and office files through ingestion, transcription, OCR, and enrichment pipelines for downstream AI use.
Connect external data sources to AI agents through MCP and SDKs so apps can retrieve context and trigger actions from familiar developer tools.
Graphlit is used to ingest content, extract structure, and make it searchable for AI applications that need grounded context. The site positions it as a context layer for AI agents, with support for search, RAG, chat, and knowledge graphs.
The pricing page shows a Free tier with limited usage and paid plans for Hobby, Starter, and Growth, plus a Custom option for larger integration and agent work. The site also says there is a free project to get started and that no credit card is required for the free tier.
Yes. The site references SDKs for TypeScript, Python, and .NET, and the home page shows example code in TypeScript.
Graphlit’s integrations page describes ingestion, preparation, and delivery across connected tools. The site highlights sources such as Slack, GitHub, Jira, Notion, Gmail, Google Drive, S3, Dropbox, and similar systems.
The pricing page says Graphlit includes ingestion and extraction, search and RAG, knowledge graphs, and agent context in one platform price. It also calls out citations, configurable workflows, and content feeds.
Os dados de tráfego são apenas para referência.

airweave.ai
Airweave é uma camada open source de recuperação de contexto para agentes de IA e sistemas RAG. Conecta apps e bancos de dados, sincroniza dados em tempo real e oferece recuperação fundamentada por meio de uma busca unificada.
memmy.bot
Memmy é um agente de IA local-first e uma camada de memória para quem usa várias ferramentas de IA. Mantém o contexto autorizado no dispositivo e pode levar memórias relevantes entre apps para desktop, fluxos de trabalho CLI e agentes externos.
www.getnoan.com
NOAN é uma camada de fatos e uma API para empresas que desejam que sites, aplicativos e agentes de IA utilizem as mesmas informações verificadas sobre a empresa. Organiza fatos empresariais aprovados e versionados em um espaço de trabalho conectado, acessível via REST e MCP.
skynetlab-cortex.com
Cortex é uma infraestrutura de memória semântica para assistentes e agentes de IA. Ajuda as equipes a manter disponíveis o contexto compartilhado, as decisões, as fontes e as contradições entre conversas e mudanças de modelo.

kolosal.ai
Kolosal Planout é uma camada de tradução de dados com AI que transforma o contexto multimodal do produto em entradas estruturadas para a AI, ajudando as equipes a definir a intenção de aplicações a partir de documentos, reuniões, designs e conhecimento da equipe.

recall.it
Base de conhecimento pessoal com IA para salvar, resumir, organizar e conversar com conteúdos