
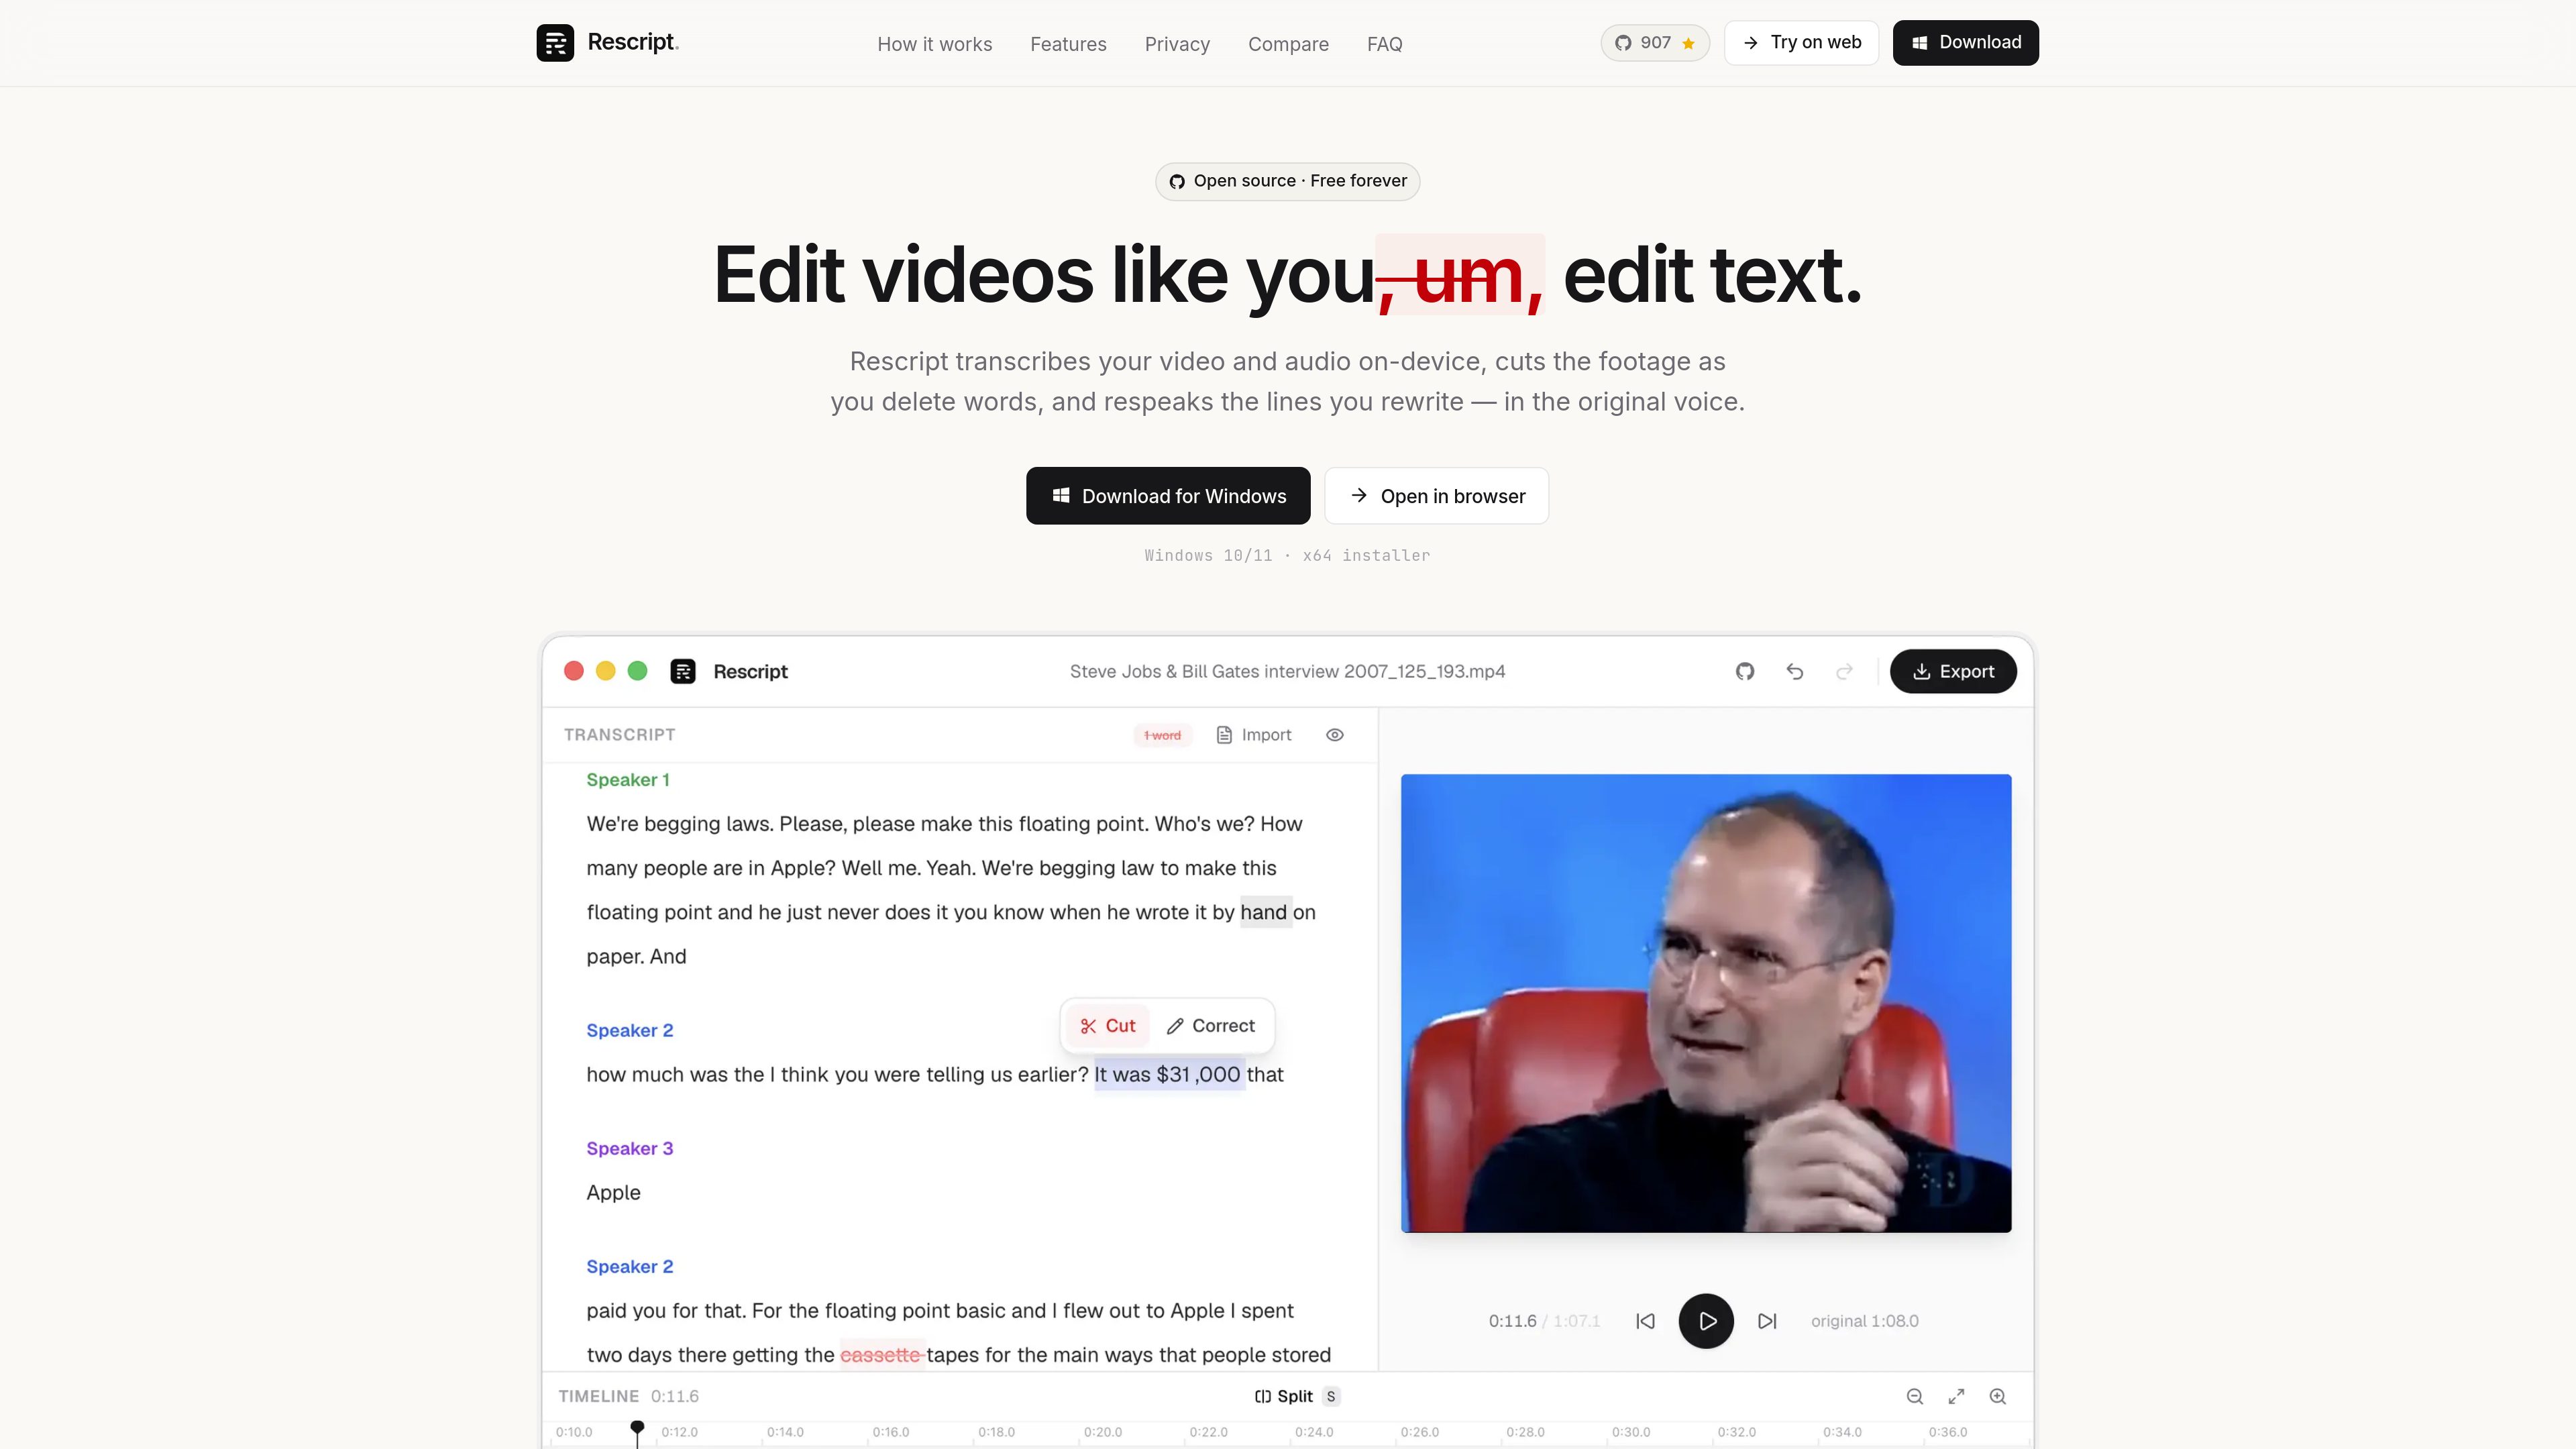
Word-level transcript editing
Delete a word or phrase to cut the matching span of video or audio. Playback previews the edited result and word timings can be corrected.
Rescript는 음성 중심 미디어를 위한 무료 오픈소스 트랜스크립트 기반 동영상·오디오 편집기입니다. 브라우저나 데스크톱 앱에서 로컬로 생성한 트랜스크립트를 수정해 영상을 편집하고, 기기에서 동영상, 오디오, 트랜스크립트 또는 자막을 내보낼 수 있습니다.
Rescript is a free, open-source editor for speech-driven video and audio. It transcribes media locally with Whisper, then treats the transcript as an editing surface: deleting words or phrases removes the corresponding portions of the recording.
The product runs in a browser or as a desktop app for macOS, Windows, and Linux. Its local workflow includes transcription, speaker labeling, editing, optional voice regeneration, and export, so media files do not need to be uploaded.
Delete a word or phrase to cut the matching span of video or audio. Playback previews the edited result and word timings can be corrected.
Remove detected filler words such as “um” and “uh” across a file, or cut pauses of 0.3 seconds or longer in one operation.
Whisper transcription is paired with local speaker detection that groups transcript blocks by speaker. Speaker labels can be renamed for clearer interviews and conversations.
A timeline with waveform, word bars, split and cut regions, draggable handles, zoom, pan, and timing nudges provides manual control when transcript editing is not enough.
Rewrite a selected line and generate replacement speech in the original speaker’s voice. Rescript uses clean audio from the recording, checks the available slot, and fits the new audio to the replaced span.
Export video as MP4 or WebM up to 4K, audio as M4A, MP3, or WAV, transcripts as TXT or Markdown, and subtitles as SRT, VTT, or JSON.
Review a speaker-labeled transcript to remove tangents, repeated takes, filler words, and long pauses without searching through a waveform for every edit.
When deleting a sentence is not enough, rewrite a misspoken name, figure, or phrase and generate a replacement in the relevant speaker’s voice.
Edit interviews, therapy sessions, legal recordings, or unreleased footage locally when sending source media to a cloud editor is undesirable.
Import an existing SRT, VTT, or JSON transcript, edit the associated media, and export cleaned transcripts or subtitle files in several formats.
Create a tightened single-clip spoken-word edit, then move the exported result to a more general editor when the project needs multitrack work, titles, transitions, or effects.
No. Transcription, editing, voice generation, and export run on the user’s device. The Whisper model and language voice bundles make one-time downloads and are then cached; the media itself is not uploaded.
No. The full editor runs in a browser. Desktop builds are available for macOS, Windows, and Linux for users who prefer an installed, offline-first app.
Yes. Rescript can import SRT, VTT, or JSON caption files, allowing users to skip local transcription and edit the media against the imported text.
It exports video as MP4 or WebM up to 4K, audio as M4A, MP3, or WAV, transcripts as TXT or Markdown, and subtitles as SRT, VTT, or JSON.
It is intended for transcript-based editing of speech-driven media and single-clip cuts. It does not replace a general editor for recording, multitrack timelines, layers, titles, transitions, color, effects, or noise removal.
트래픽 데이터는 참고용으로만 확인하세요.