
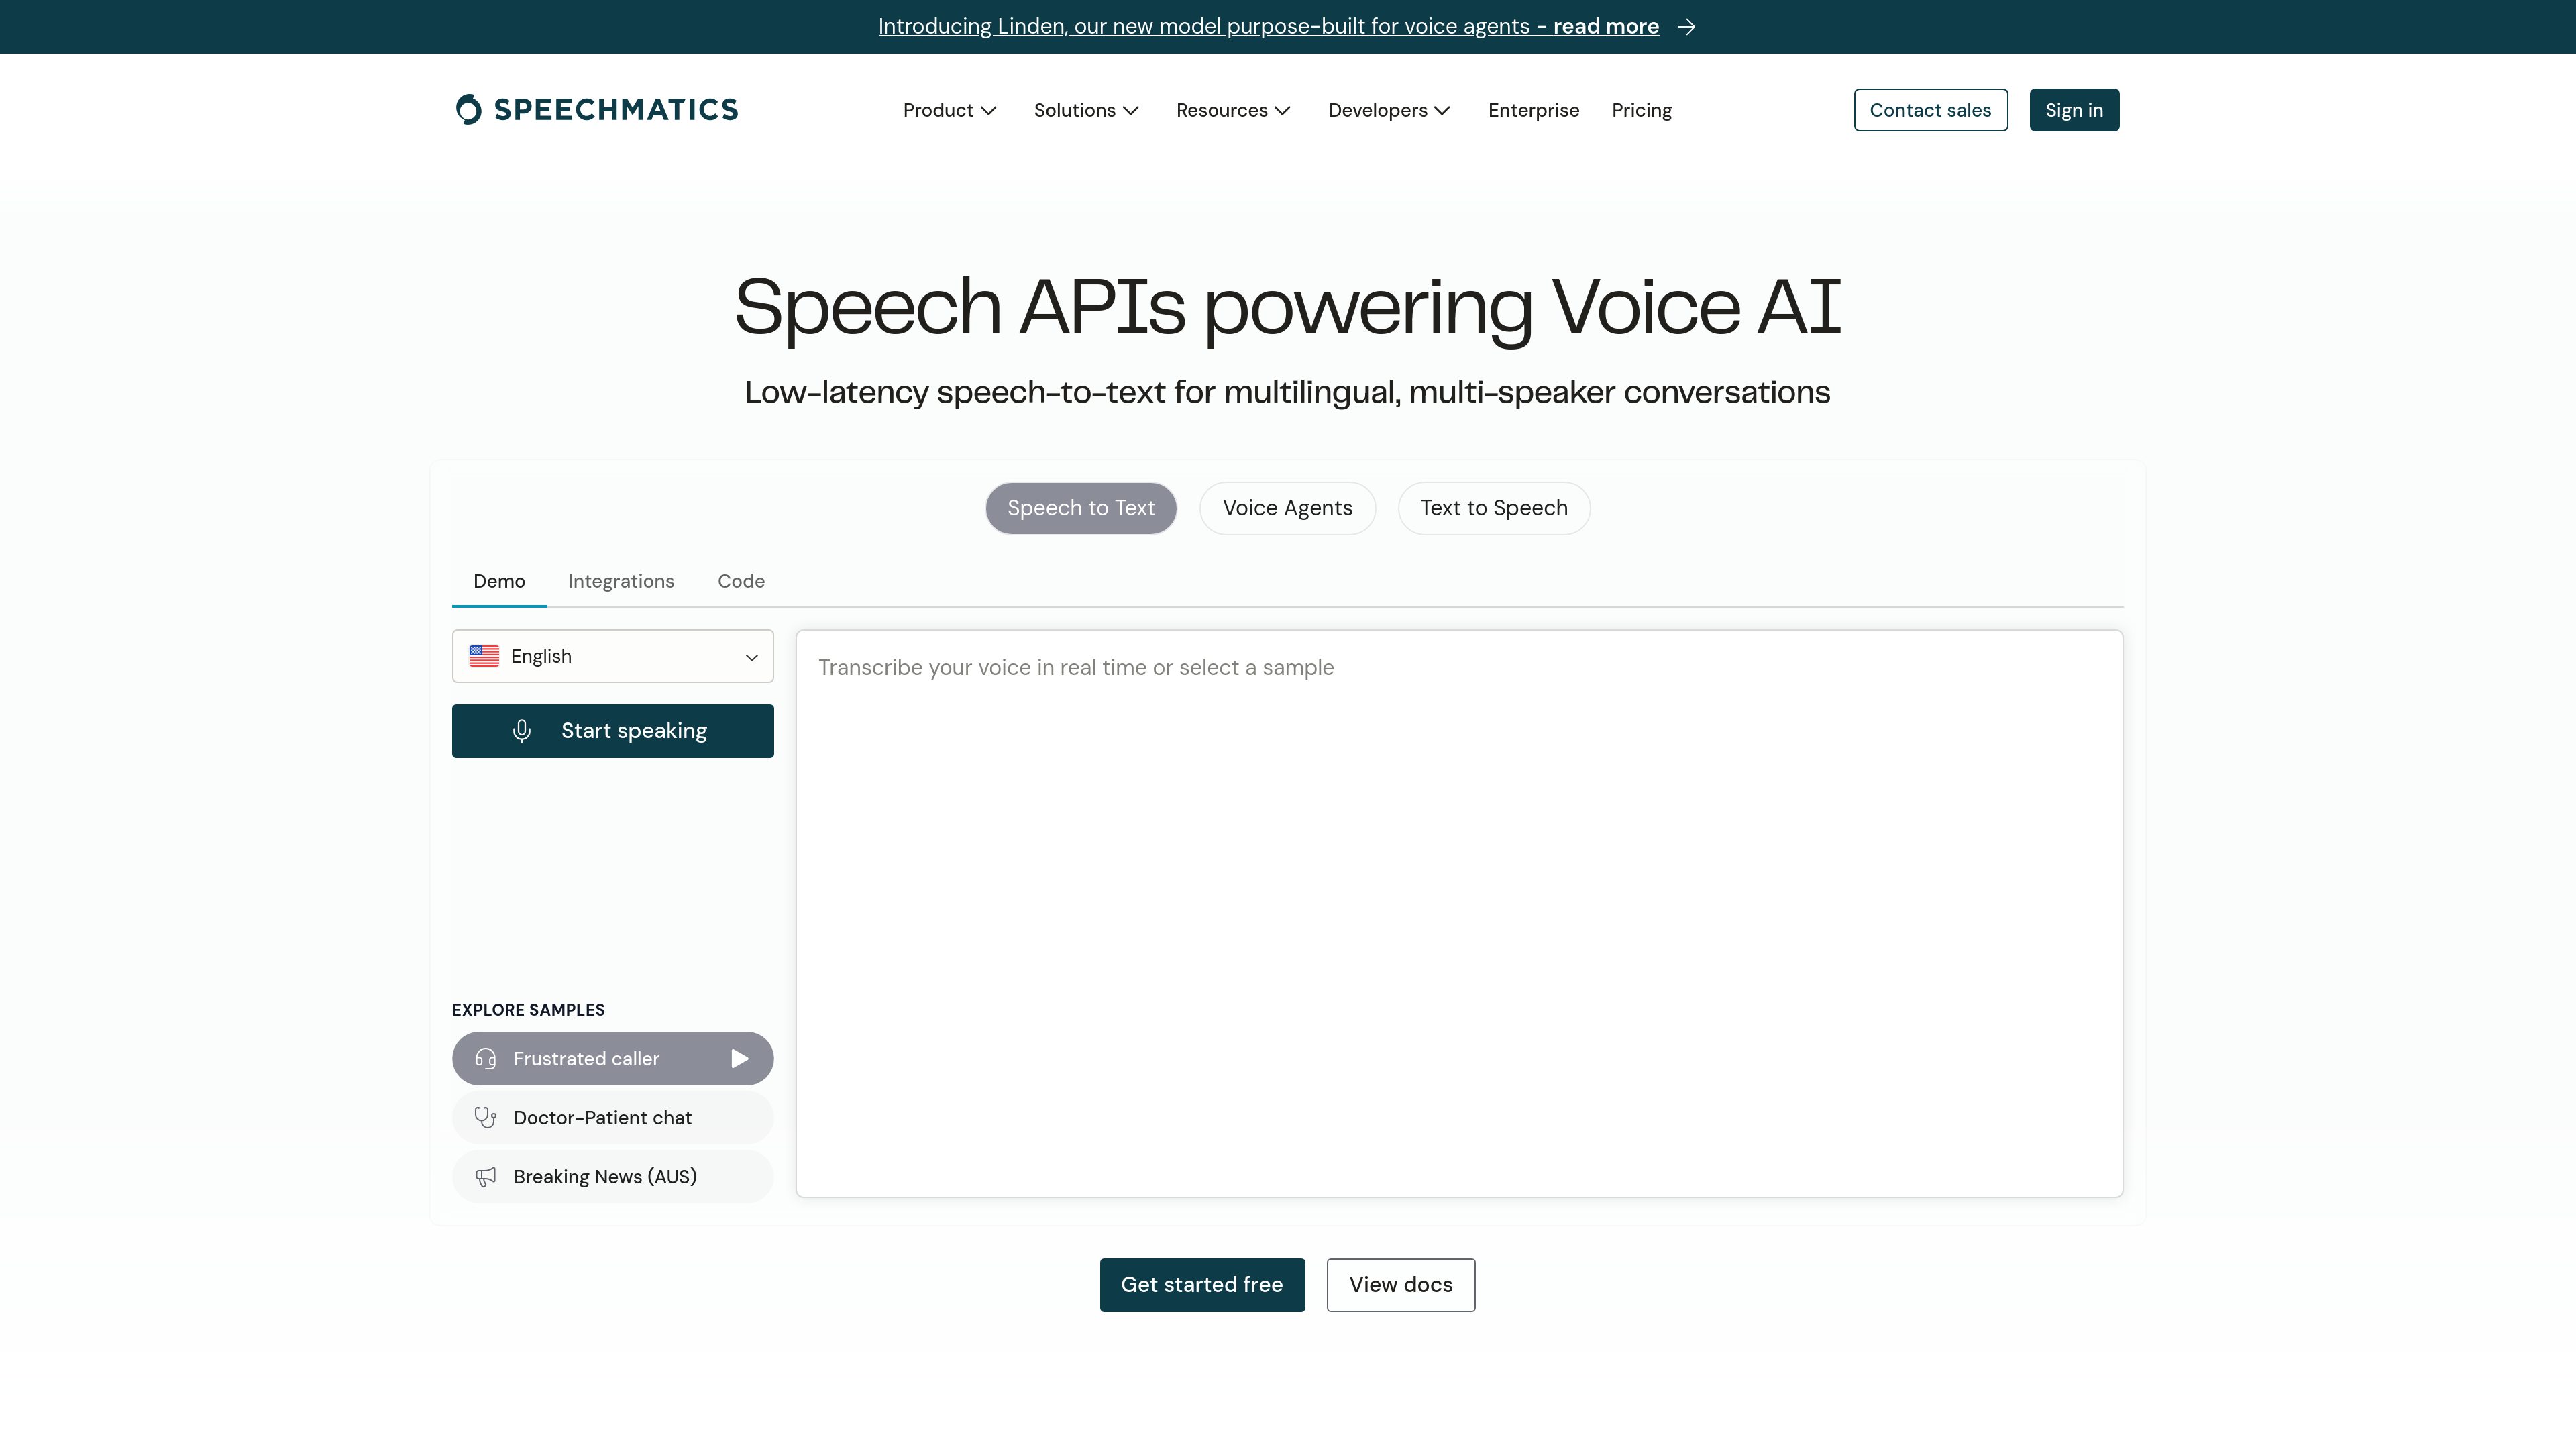
Pre-recorded and real-time transcription
Transcribe audio or video files in batch workflows, or process live audio and video for applications that need streaming speech recognition.

Speechmatics provides speech-to-text APIs for pre-recorded and real-time audio, with support for multilingual speech, multiple speakers, and voice-agent workflows. It is designed for teams building transcription and Voice AI applications.
Speechmatics is a speech-to-text API platform for transcribing live or pre-recorded audio and video. Its models are designed for conversational audio, including accents, multiple speakers, multilingual speech, and language switching within a sentence. The platform offers general-purpose, enhanced, medical, and voice-agent-oriented models for different transcription requirements.
Core capabilities include batch transcription from audio or video files and real-time transcription from live audio or video. Depending on the model, outputs and processing options include speaker diarization, language hints and labeling, smart formatting, word-level timings, custom dictionaries, healthcare vocabulary handling, mixed-language transcription, and code-switching support.
Transcribe audio or video files in batch workflows, or process live audio and video for applications that need streaming speech recognition.
The Melia 1 model supports 56 languages without requiring a language choice up front and can switch languages mid-sentence. The platform site describes support for more than 55 languages overall.
Speaker diarization separates contributions in multi-speaker recordings, while language hints and labeling help identify or guide the languages present in a transcription.
Available model choices include Melia 1 for multilingual audio, Enhanced for higher-accuracy single-language transcription, Oak 1 for clinical language, and Linden 1 for real-time voice-agent use cases.
Optional processing includes translation, chapters, topics, summaries, sentiment, PII redaction, and audio alignment. Availability and rates vary by model and processing mode.
The Linden 1 real-time model includes turn detection for conversational voice-agent workflows, helping an application identify when a speaker's turn has changed.
Use Melia 1 to transcribe meetings, interviews, calls, or other recordings where speakers use multiple languages or switch languages during a conversation.
Use the Oak 1 medical model for clinical language, including drug names, dosages, abbreviations, and procedure terms, with multilingual support.
Use the Linden 1 real-time model as the speech-recognition layer for conversational agents that need built-in turn detection.
Process audio or video files in batch and add outputs such as chapters, topics, summaries, translation, or sentiment analysis where the selected model and workflow support them.
Yes. The pricing information distinguishes pre-recorded transcription from real-time transcription. Pre-recorded workflows accept audio or video files, while real-time workflows process live audio or video.
The site describes support for more than 55 languages. The Melia 1 model is listed as transcribing 56 languages without choosing one language up front and can switch languages mid-sentence.
Speaker diarization is listed as an available transcription feature. Exact feature availability can differ by model, product package, and deployment.
Oak 1 is the medical model. It is intended for clinical language, including drug names, dosages, abbreviations, and procedure terms.
The pricing page says users can start free with $100 in credits and no card required. Usage rates after the included credits vary by model and processing mode.
トラフィックデータは参考情報としてご利用ください。

speechify.ai
SpeechifyAI is a developer API for expressive text-to-speech and voice cloning. It provides streaming Simba models, catalog and cloned voices, SSML support, and a free starting tier for building speech into applications.

lemonfox.ai
Speech-to-text and text-to-speech APIs for developers building audio workflows.

deepgram.com
Speech-to-text, text-to-speech, and voice agent APIs for developers and enterprises.
4allapi.com
4ALL API is an API aggregation gateway for enterprises and developers that provides one access layer for text, image, video, and audio models from multiple providers. It supports OpenAI-compatible access, usage-based billing, model routing, and failover workflows.

modelslab.com
ModelsLab is a developer platform that provides APIs for image, video, audio, 3D, and LLM generation through a unified service. It supports teams building generative media features without integrating each model provider separately.
inworld.ai
Realtime voice, speech, and language-model infrastructure for consumer applications.