
Generative and predictive inference
The platform is positioned for both generative AI and predictive AI inference workloads, covering more than one broad model-serving pattern.
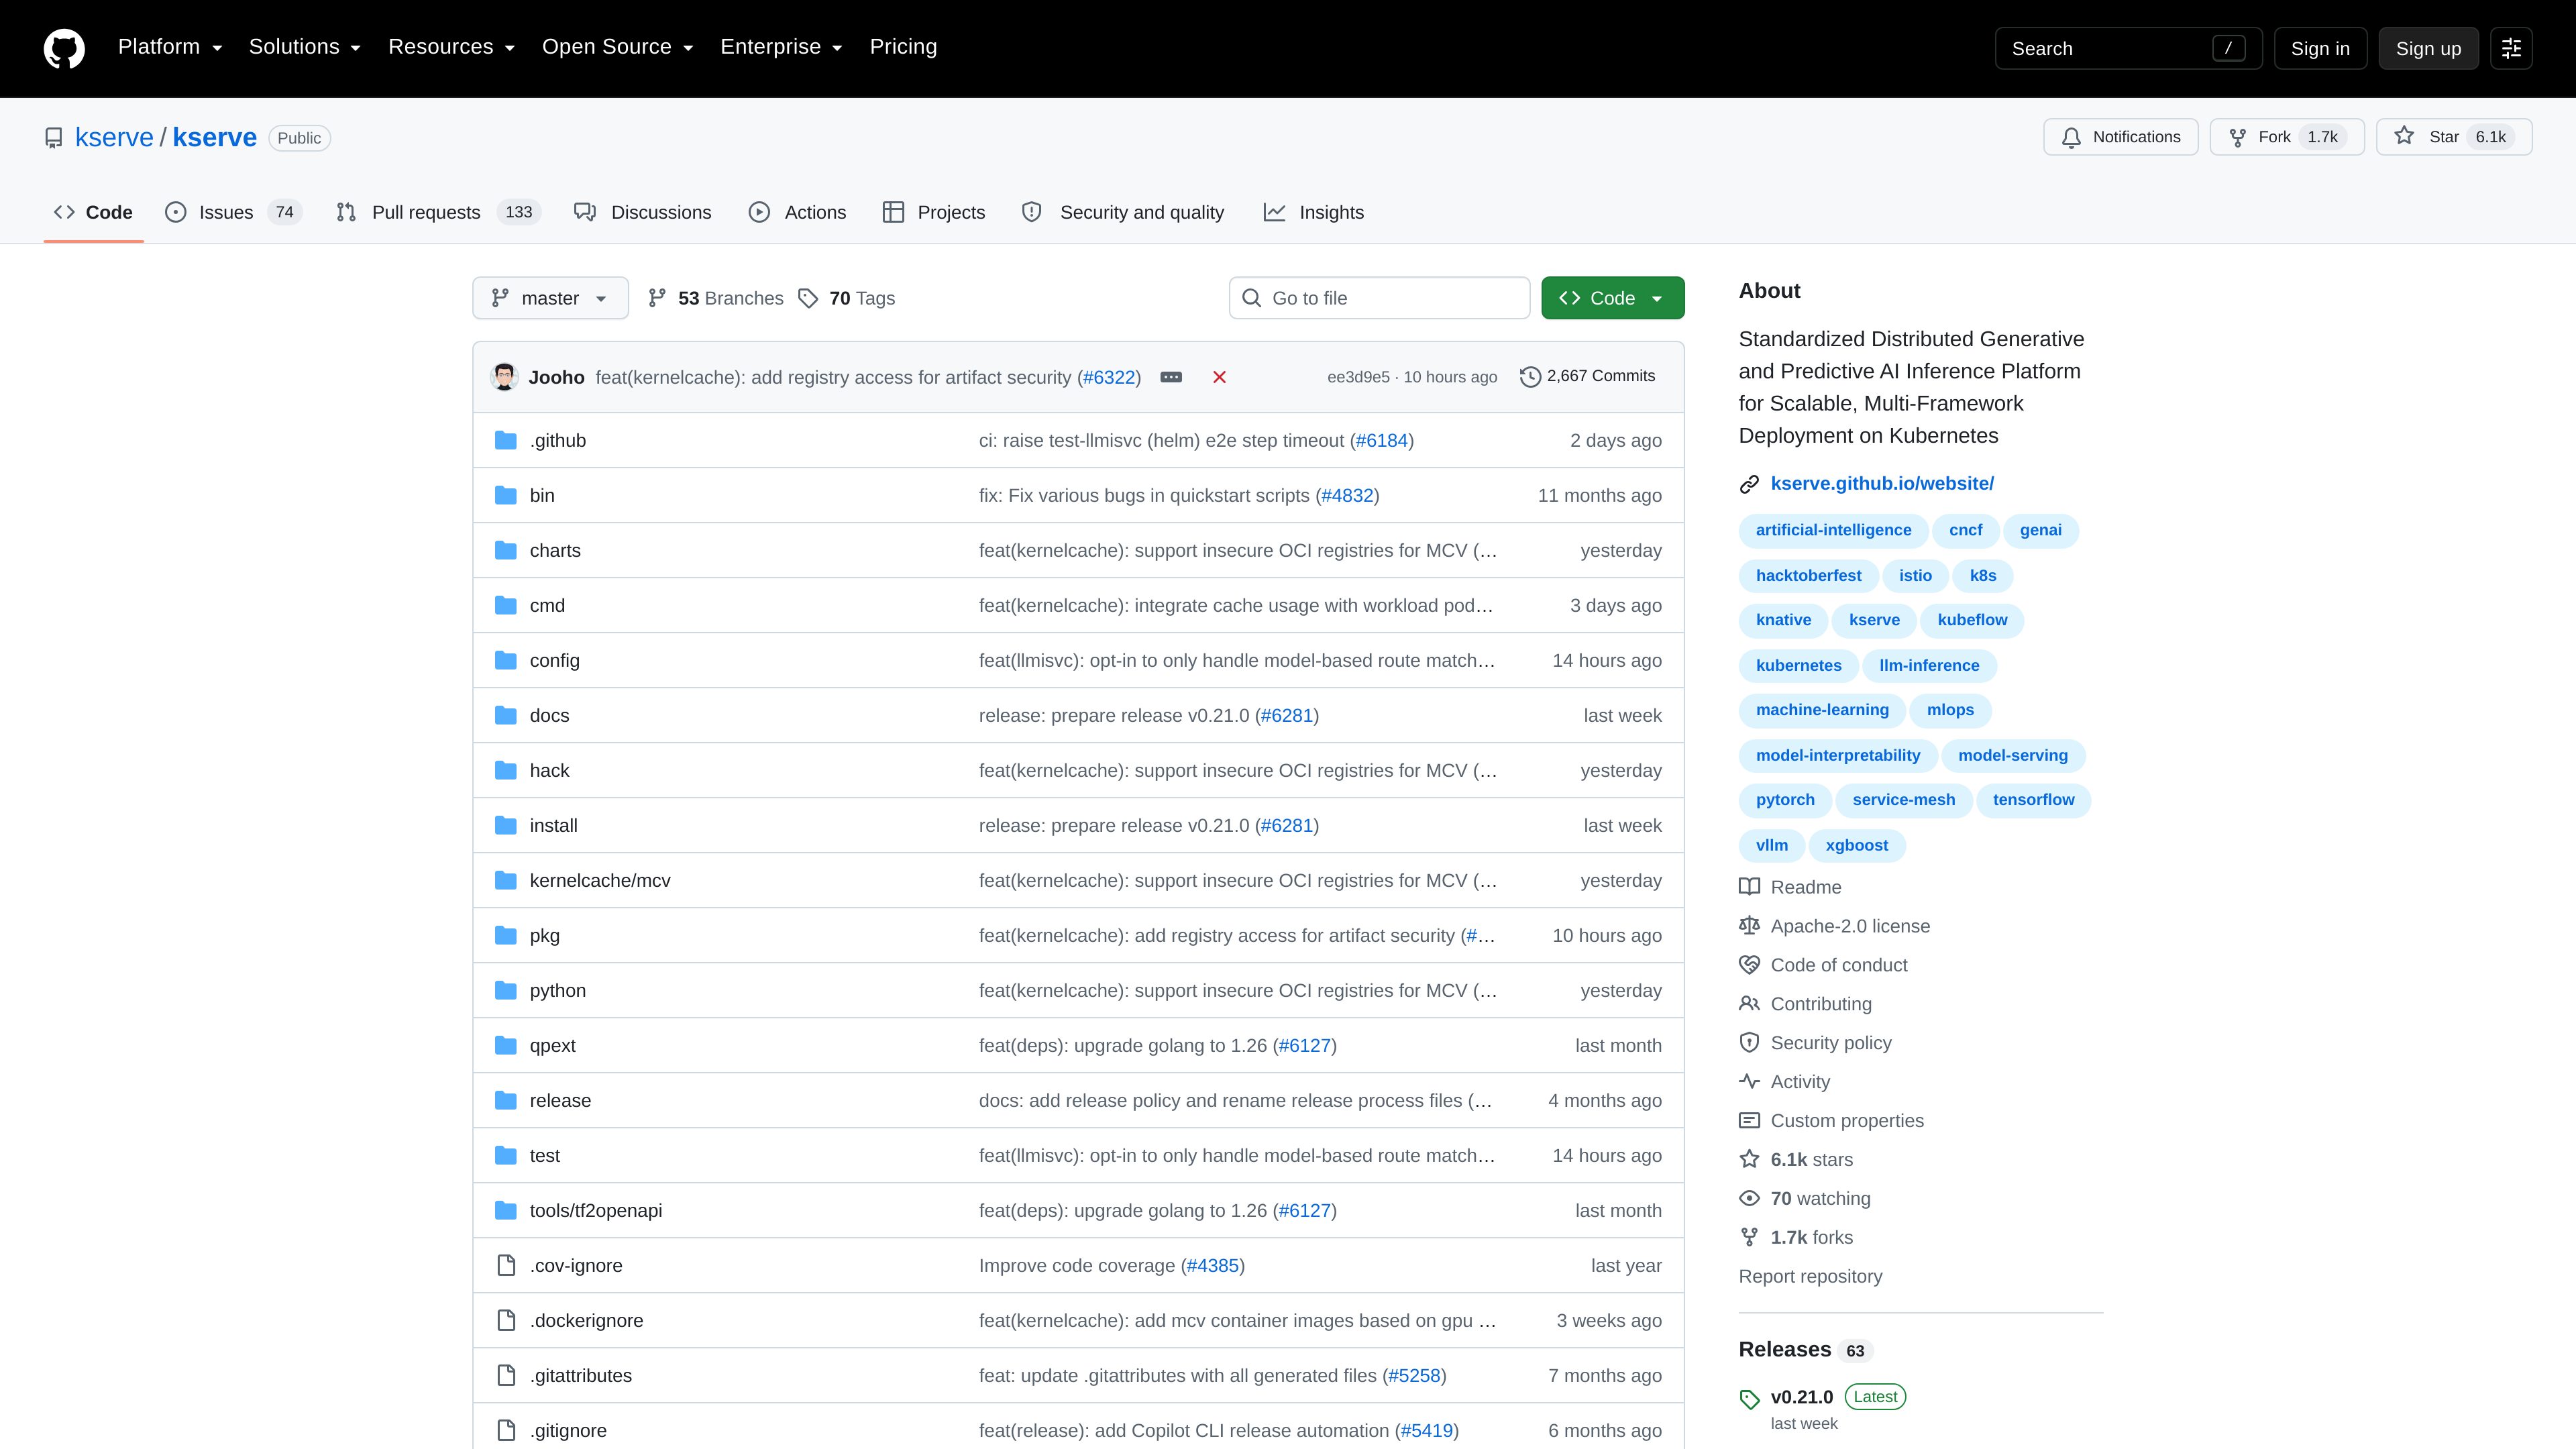
KServe is a Kubernetes-based inference platform for deploying distributed generative and predictive AI workloads across multiple model frameworks. It is intended for teams that need a standardized way to run inference services in Kubernetes.
KServe is a Kubernetes-based platform for standardized distributed inference. It is designed to deploy and operate both generative and predictive AI workloads while accommodating multiple model frameworks.
The project’s core purpose is to give teams a common inference-serving layer for Kubernetes instead of requiring each model service to use a separate deployment approach. Its repository includes documentation, installation resources, charts, APIs, samples, and operational guides, indicating a platform intended for engineering teams managing model-serving infrastructure.
The platform is positioned for both generative AI and predictive AI inference workloads, covering more than one broad model-serving pattern.
KServe is designed to support inference services built with multiple model frameworks rather than prescribing a single framework for every workload.
Kubernetes is the platform foundation, making KServe relevant to teams that manage model-serving workloads through Kubernetes resources and deployment practices.
The project provides a common platform approach for deploying inference services, helping teams apply a consistent operational model across different workloads.
The repository contains dedicated documentation and installation areas, along with guides covering subjects such as multi-model serving, manifests, debugging, and OpenShift.
The codebase exposes APIs and includes charts, configuration, samples, and multiple implementation directories, giving platform teams project materials to inspect and adapt.
A machine-learning team can use the platform as a standardized Kubernetes foundation for exposing predictive inference workloads.
Teams deploying generative AI services can evaluate KServe as a Kubernetes-oriented serving layer for distributed inference workloads.
Organizations with models built using different frameworks can use a common platform approach instead of creating an entirely separate serving workflow for each framework.
An internal infrastructure team can use the project’s installation materials, charts, APIs, and operational guides as a basis for providing model-serving capabilities to application teams.
Teams with a need to serve multiple models can consult the repository’s dedicated multi-model serving guidance when designing their Kubernetes deployment approach.
KServe is used to deploy distributed generative and predictive AI inference workloads on Kubernetes through a standardized, multi-framework platform approach.
It is primarily relevant to machine-learning, platform, and infrastructure teams that operate inference services in Kubernetes environments.
Yes. The project description explicitly covers both generative and predictive AI inference.
Kubernetes is the platform named in the project description, so KServe is intended for Kubernetes-based deployment rather than a standalone, platform-neutral installation.
The project repository includes dedicated docs and install directories, as well as charts and operational guides. The specific installation method and prerequisites should be checked in the current project documentation.
inference.net
Inference.net is infrastructure for running, monitoring, evaluating, training, and deploying production AI workloads. It helps AI-native teams observe model behavior, route traffic across providers, and improve cost, latency, reliability, and quality through connected workflows.

www.hyperstack.cloud
Hyperstack is a cloud GPU platform for running AI and machine learning workloads, including training, inference, data analytics, and model development. It also provides AI Studio, virtual machines, and managed Kubernetes for deploying and operating GPU-backed workloads.
ubiops.com
Model serving and orchestration for AI teams deploying workloads across cloud and private infrastructure.
www.bentoml.com
Bento is an inference platform for packaging, deploying, optimizing, and operating AI and machine-learning models at scale. It supports open and custom models across cloud, on-premises, Kubernetes, and bring-your-own-cloud environments.

friendli.ai
FriendliAI is an inference cloud for deploying frontier open-weight and custom AI models in production. It offers serverless Model APIs, dedicated GPU endpoints, and BYOG options for agent, multimodal, and other high-throughput workloads.

baseten.co
Baseten is an inference platform for deploying, serving, and scaling open-source, custom, and fine-tuned AI models. It supports managed cloud, self-hosted, hybrid, and dedicated deployments for teams running production AI workloads.