
Usage, cost, and latency monitoring
Track model usage, spending, and response latency to identify expensive workloads and performance bottlenecks.

An open-source AI gateway and LLM observability platform for developers building AI apps.
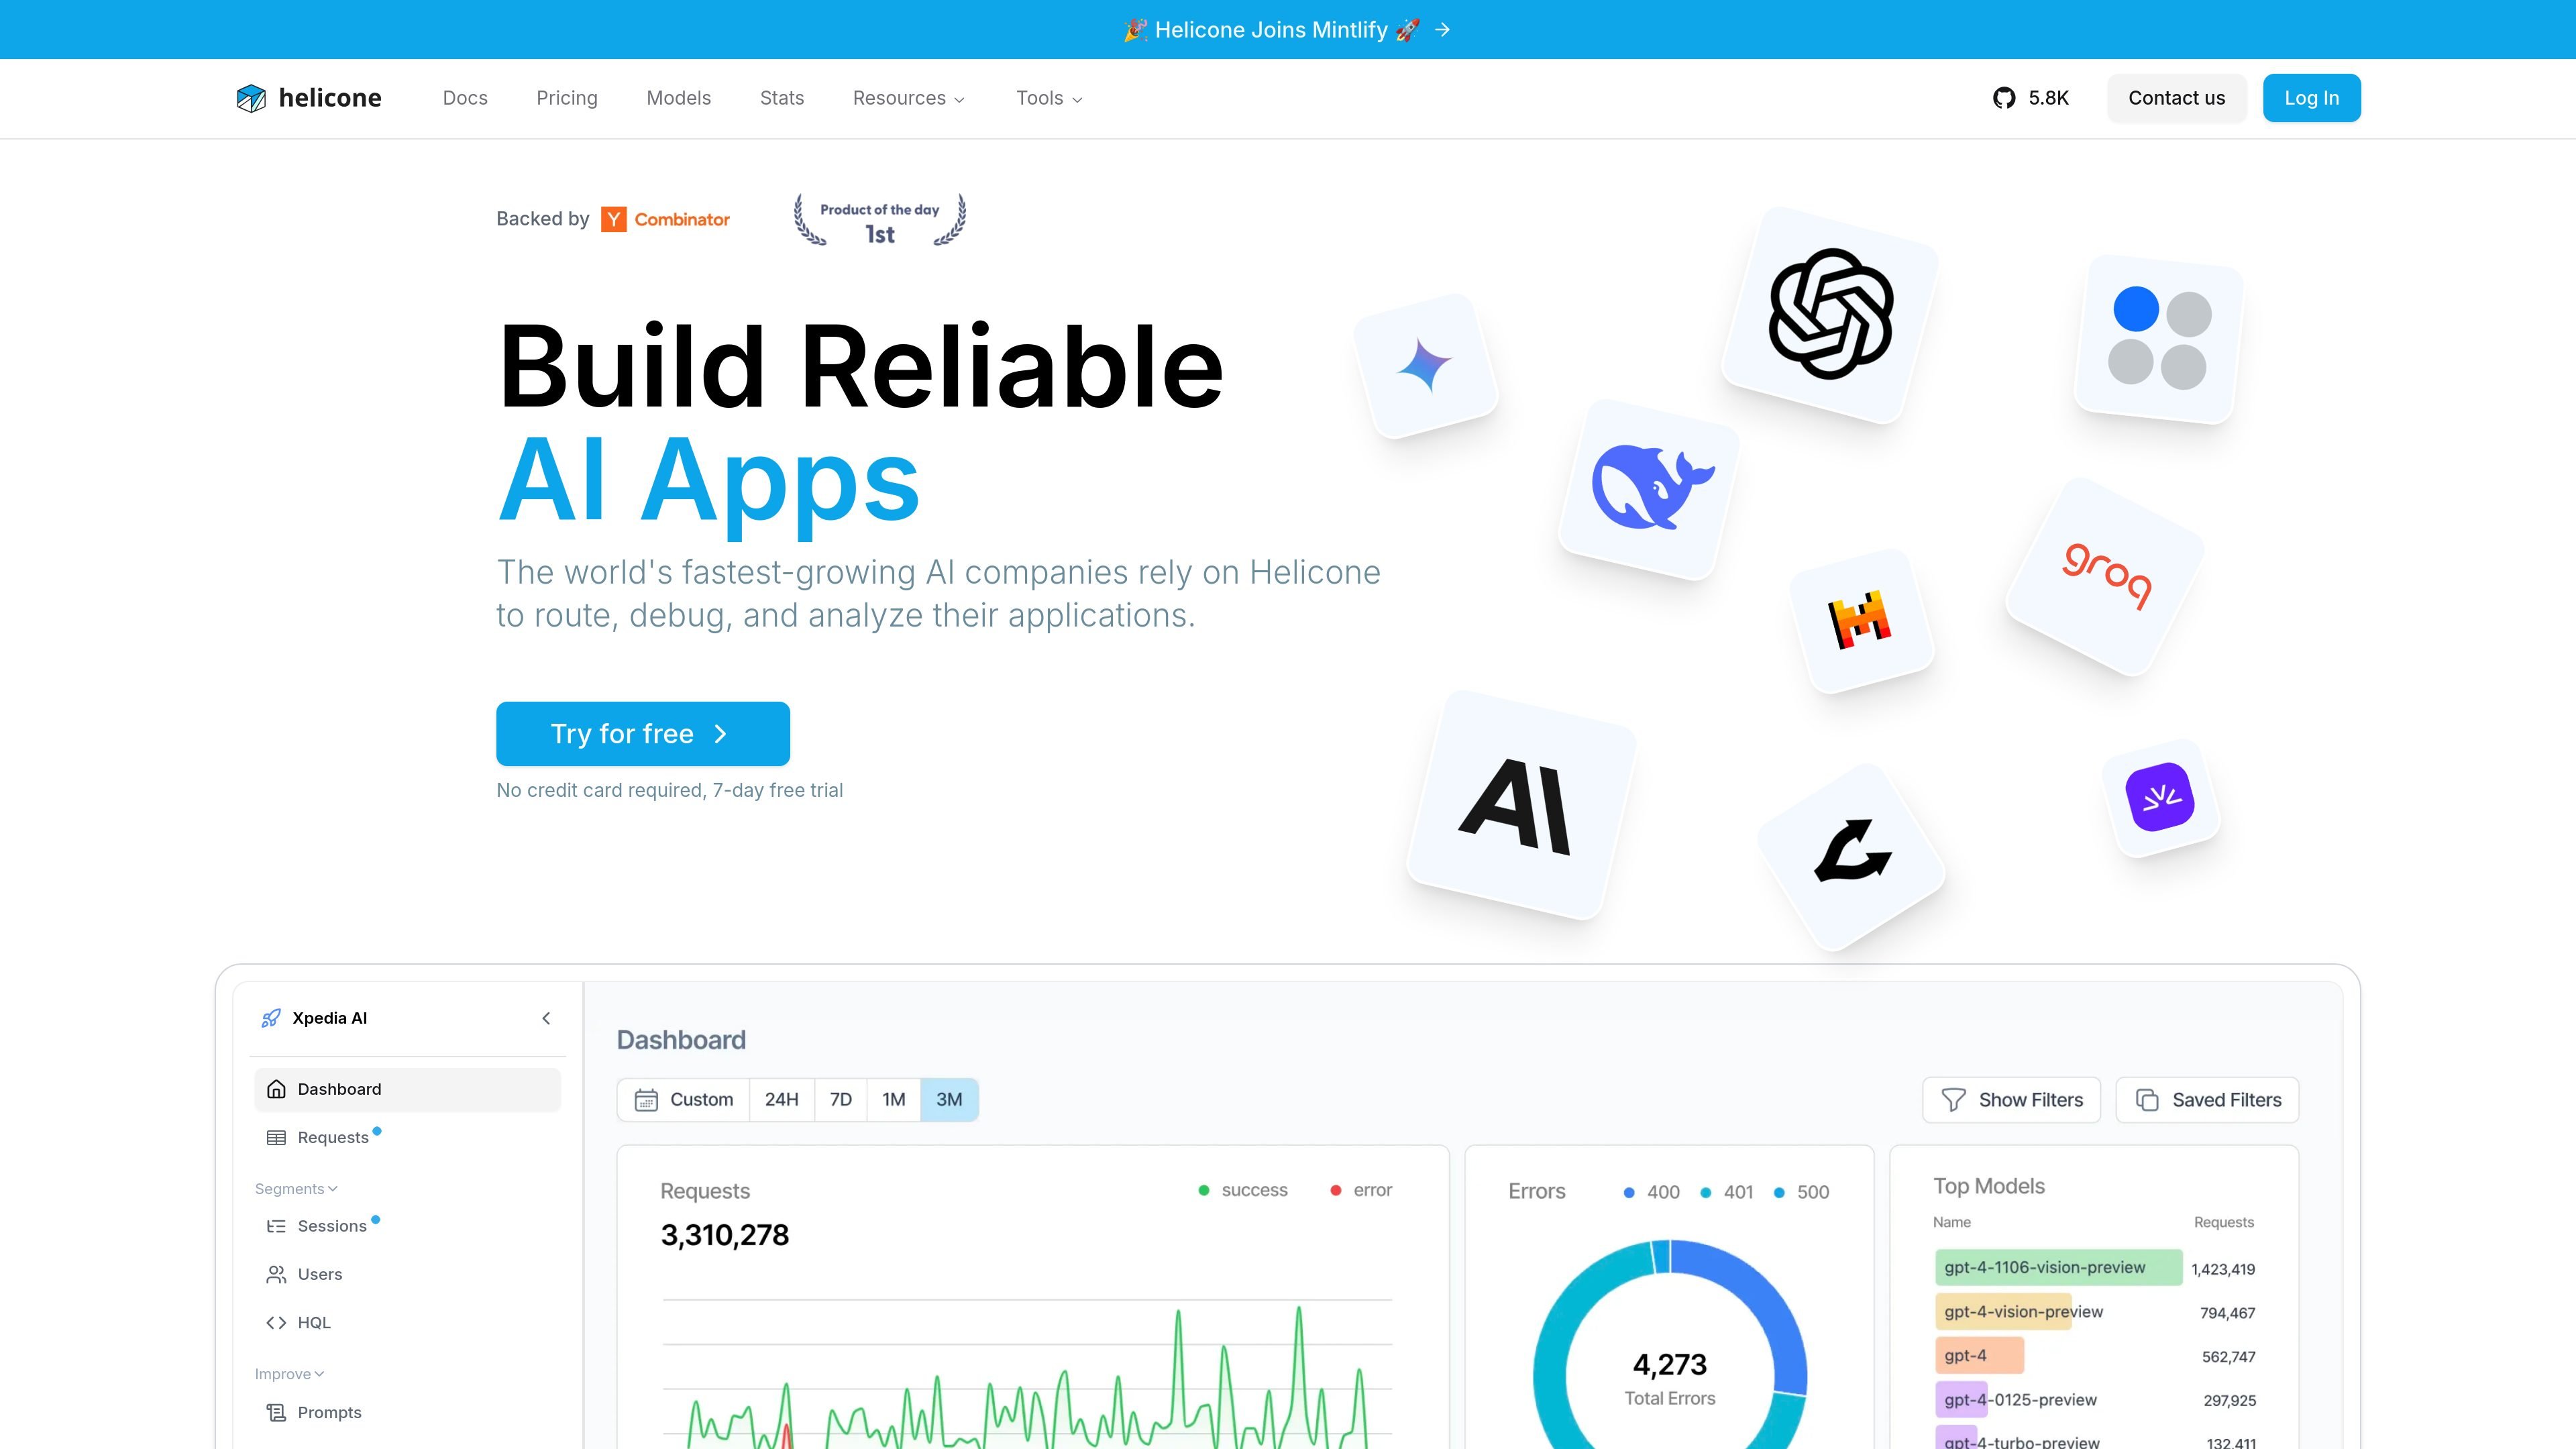
Helicone is an open-source AI gateway and observability platform for applications that use large language models. It helps developers route model requests, investigate application behavior, and understand usage, latency, and costs across multiple AI models.
Teams can integrate Helicone into existing AI workflows, including using it as a proxy for model requests. Its monitoring, request controls, and testing tools support ongoing analysis and optimization. Helicone offers cloud-based service and support for self-hosted deployment.
In its March 3, 2026 acquisition announcement, Helicone said its services would remain live for the foreseeable future in maintenance mode, with security updates, new models, and bug and performance fixes continuing. Consider that maintenance status when planning a long-term dependency.
Track model usage, spending, and response latency to identify expensive workloads and performance bottlenecks.
Route model requests through a gateway with caching, rate limits, and automatic fallbacks. Model-swapping capabilities support changes to the models used by an application.
Attach custom properties to requests for more detailed analysis of application activity. Sessions and user analytics provide additional ways to examine usage.
Pro includes Helicone Query Language (HQL), alerts, and reports for investigating recorded activity and monitoring ongoing operations.
Use the playground to test prompts, sessions, and traces, and work with prompts, scores, and datasets to inspect model behavior.
Plan-specific retention ranges from seven days on Hobby to indefinite retention on Enterprise. The pricing comparison also lists API access and data export.
When an application becomes slow, developers can examine latency alongside recorded requests and session activity to locate the workloads that need attention.
Use custom properties to distinguish workloads and examine their model usage and costs, helping teams decide where optimization efforts should focus.
Use gateway caching for repeated requests and configure rate limits and automatic fallbacks as part of an application's request-handling workflow.
Teams that need control over infrastructure can explore self-hosting. Enterprise packages include on-premises deployment, SAML SSO, and a custom MSA.
Hobby includes 10,000 requests per month, 1 GB of storage, one seat, and one organization. Its listed data retention is seven days. This is an observability allowance; model inference through the gateway requires credits and should be budgeted separately.
Pro costs $79 per month and Team costs $799 per month, with usage-based charges applying to both. Both offer a seven-day free trial. Enterprise pricing is available through sales.
Helicone supports integration into existing AI workflows, including a gateway proxy for AI model requests. Its documentation provides a quick-start guide, gateway integration instructions, custom property guidance, and authentication details.
Pro includes unlimited seats and one organization. Team adds five organizations and a dedicated Slack channel. Enterprise includes unlimited organizations, SAML SSO, on-premises deployment, and a custom MSA.
トラフィックデータは参考情報としてご利用ください。
www.tensorzero.com
TensorZero is an open-source LLMOps platform for building and operating production-grade LLM applications. Its stated scope combines an LLM gateway with observability, evaluation, optimization, and experimentation tools.

www.newapi.ai
New API is an open-source, self-hosted AI gateway for developers and teams. It provides a unified OpenAI-compatible endpoint for connecting multiple AI providers, selecting models, configuring channels, and monitoring usage on their own infrastructure.

aihubmix.com
A unified API gateway for developers building with models from multiple AI providers.
apisix.apache.org
Apache APISIX is an open-source API gateway and AI gateway for routing, securing, observing, and governing API, microservice, and LLM traffic. It helps teams manage dynamic gateway policies through a plugin-based architecture built on NGINX and etcd.

kie.ai
A unified API for developers building with video, image, music, and chat AI models.

eachlabs.ai
each::labs provides a single API for orchestrating more than 600 AI models, with routing, fallback handling, observability, and usage-based pricing. It is designed for teams building and operating production AI applications across video, image, audio, and text workflows.