
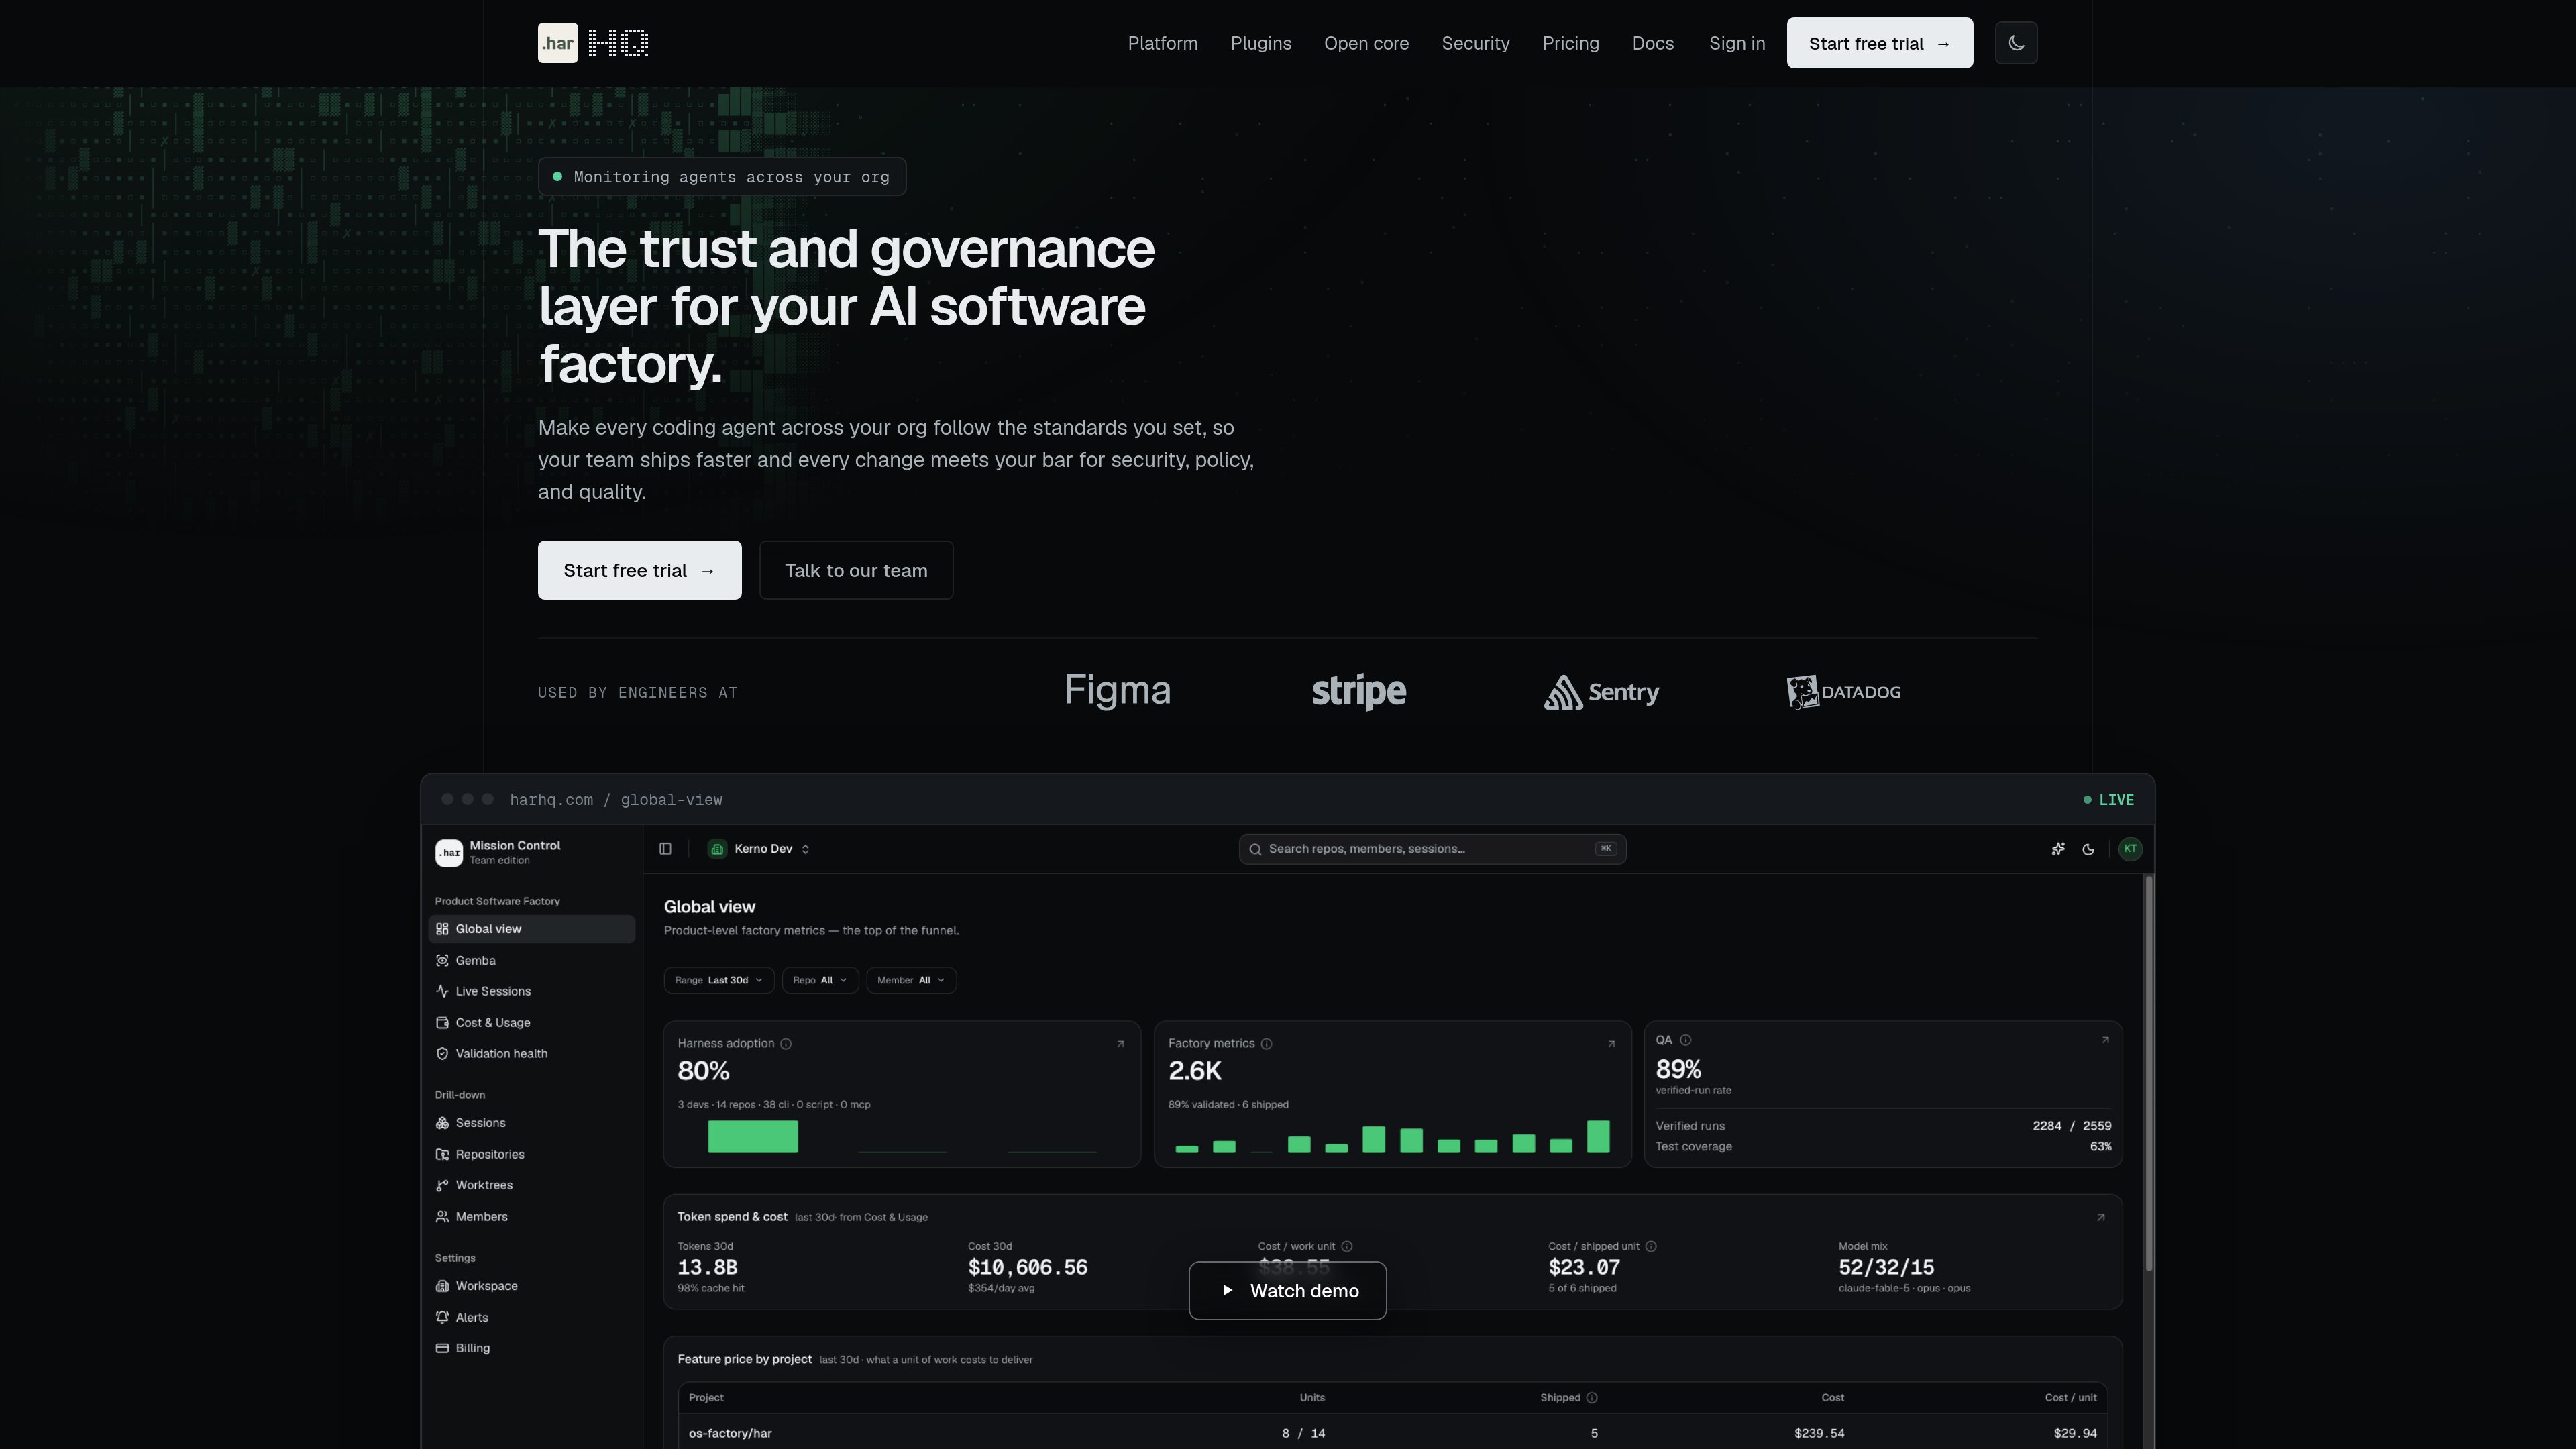
Organization-wide policies
Define required gates, budgets, roles, and alert thresholds once, then apply those standards across connected repositories and coding agents.
HAR HQ is a team governance and observability layer for organizations running coding agents with HAR. It standardizes verification, tracks AI-related work and spend, and helps engineering teams review and improve agent workflows.
HAR HQ is the team edition of HAR, an open-source, agent-agnostic harness for multi-agent coding workflows. It adds an organizational governance and observability layer for teams running coding agents across repositories.
Organizations can define shared verification standards, budgets, roles, and alert thresholds. Connected agent runs synchronize gates, proof, and cost to a workspace, and repositories and agents inherit the configured policies by default. The workflow is designed to verify changes before a pull request opens, giving reviewers a recorded validation context.
HAR HQ also links operational data to the work that produced it. Teams can inspect verification history, logs, replayable agent trajectories, pass rates, adoption, and AI spend by model, repository, teammate, ticket, or task. The product is intended for engineering organizations that need more consistent agent execution, pre-merge checks, and visibility into team usage.
Define required gates, budgets, roles, and alert thresholds once, then apply those standards across connected repositories and coding agents.
Run the project’s full verification pipeline on each agent change before a pull request opens. A per-session matrix records the gate and validated tree.
Retain verification history, logs, artifacts, and replayable agent trajectories in each worktree so teams can investigate why a run passed or failed.
Break down AI spend by model, repository, and teammate, export usage to CSV, set a weekly workspace limit, and trace cost and validation to tickets or tasks.
Review workspace adoption, pass rate, and cost, then drill into an engineer’s repositories and runs to support targeted coaching.
Ask plain-language questions about spend, coverage, failed gates, and team activity using live workspace data.
An engineering organization can encode its security, policy, and quality requirements as shared standards so agents in different repositories follow the same required gates.
Teams can require agents to run real project checks before opening pull requests, allowing reviewers to start with recorded gate results and supporting evidence instead of an unverified change.
A lead can inspect the session matrix, logs, validated tree, and replayable trajectory to understand a failed gate, while cost data shows whether retries or a particular task increased spend.
Engineering or operations teams can review spend by model, repository, and teammate, export the data, set a workspace limit, and connect usage to the ticket or task delivered.
Technical leaders can compare adoption and pass-rate data, examine how effective engineers use agents, and use those patterns to guide team-wide workflows.
HAR HQ is the team edition of HAR. It provides organization-level governance, verification visibility, AI spend tracking, and team enablement for coding-agent workflows.
The documented setup has three steps: install the HAR harness, connect it to an organization workspace with `har hq connect`, and apply a policy with `har hq policy apply ./policy.yaml`. The existing `.har/` contract and agent workflow remain in place.
A per-session matrix records the gate that ran and the tree it validated. Worktrees can also retain verification history, logs, artifacts, and a replayable agent trajectory.
Yes. Spend can be viewed by model, repository, and teammate, exported to CSV, limited with a weekly workspace cap, and traced to the ticket or task associated with a run. The supplied sources do not specify pricing for HAR HQ.
Listed profiles cover web apps, CLI or library projects, and iOS apps. Listed plugins include Playwright, RocketSim, Kerno, Gitleaks, Trivy, and Semgrep; plugins register verification stages in HAR and can be installed from bundled identifiers, a local path, an npm package, or a Git URL.
トラフィックデータは参考情報としてご利用ください。

www.agentops.ai
AgentOps is a developer platform for building, tracing, debugging, and deploying AI agents and LLM applications. It provides observability for agents built with OpenAI, CrewAI, AutoGen, and more than 400 LLMs and frameworks.
evlat.kalaomer.com
Evlat is a quiet macOS status strip for monitoring Claude Code, Codex, and Antigravity sessions, plus long-running commands. It highlights sessions that need your response and shows activity from local or SSH-connected machines.

www.lyzr.ai
OpenController is Lyzr’s control plane for discovering, evaluating, governing, and monitoring AI agents, models, tools, data, and workflows across an enterprise AI estate. It is intended for teams managing agents across clouds, frameworks, runtimes, and environments.
www.privent.ai
Priventは、特にn8nワークフロー向けのエージェント型AI用ランタイムセキュリティレイヤーです。外部モデルに届く前に機密データをマスキングし、リスク判断を監査記録として残し、ChatGPT、Claude、Geminiの組織全体での利用も監視します。

getorchestra.io
データとAIのワークフローを構築・実行・監視する宣言型オーケストレーション基盤
www.langchain.com
LangSmith is an observability and evaluation platform for AI agents and LLM applications. It helps development and production teams trace agent behavior, monitor quality and cost, investigate failures, and evaluate changes.