
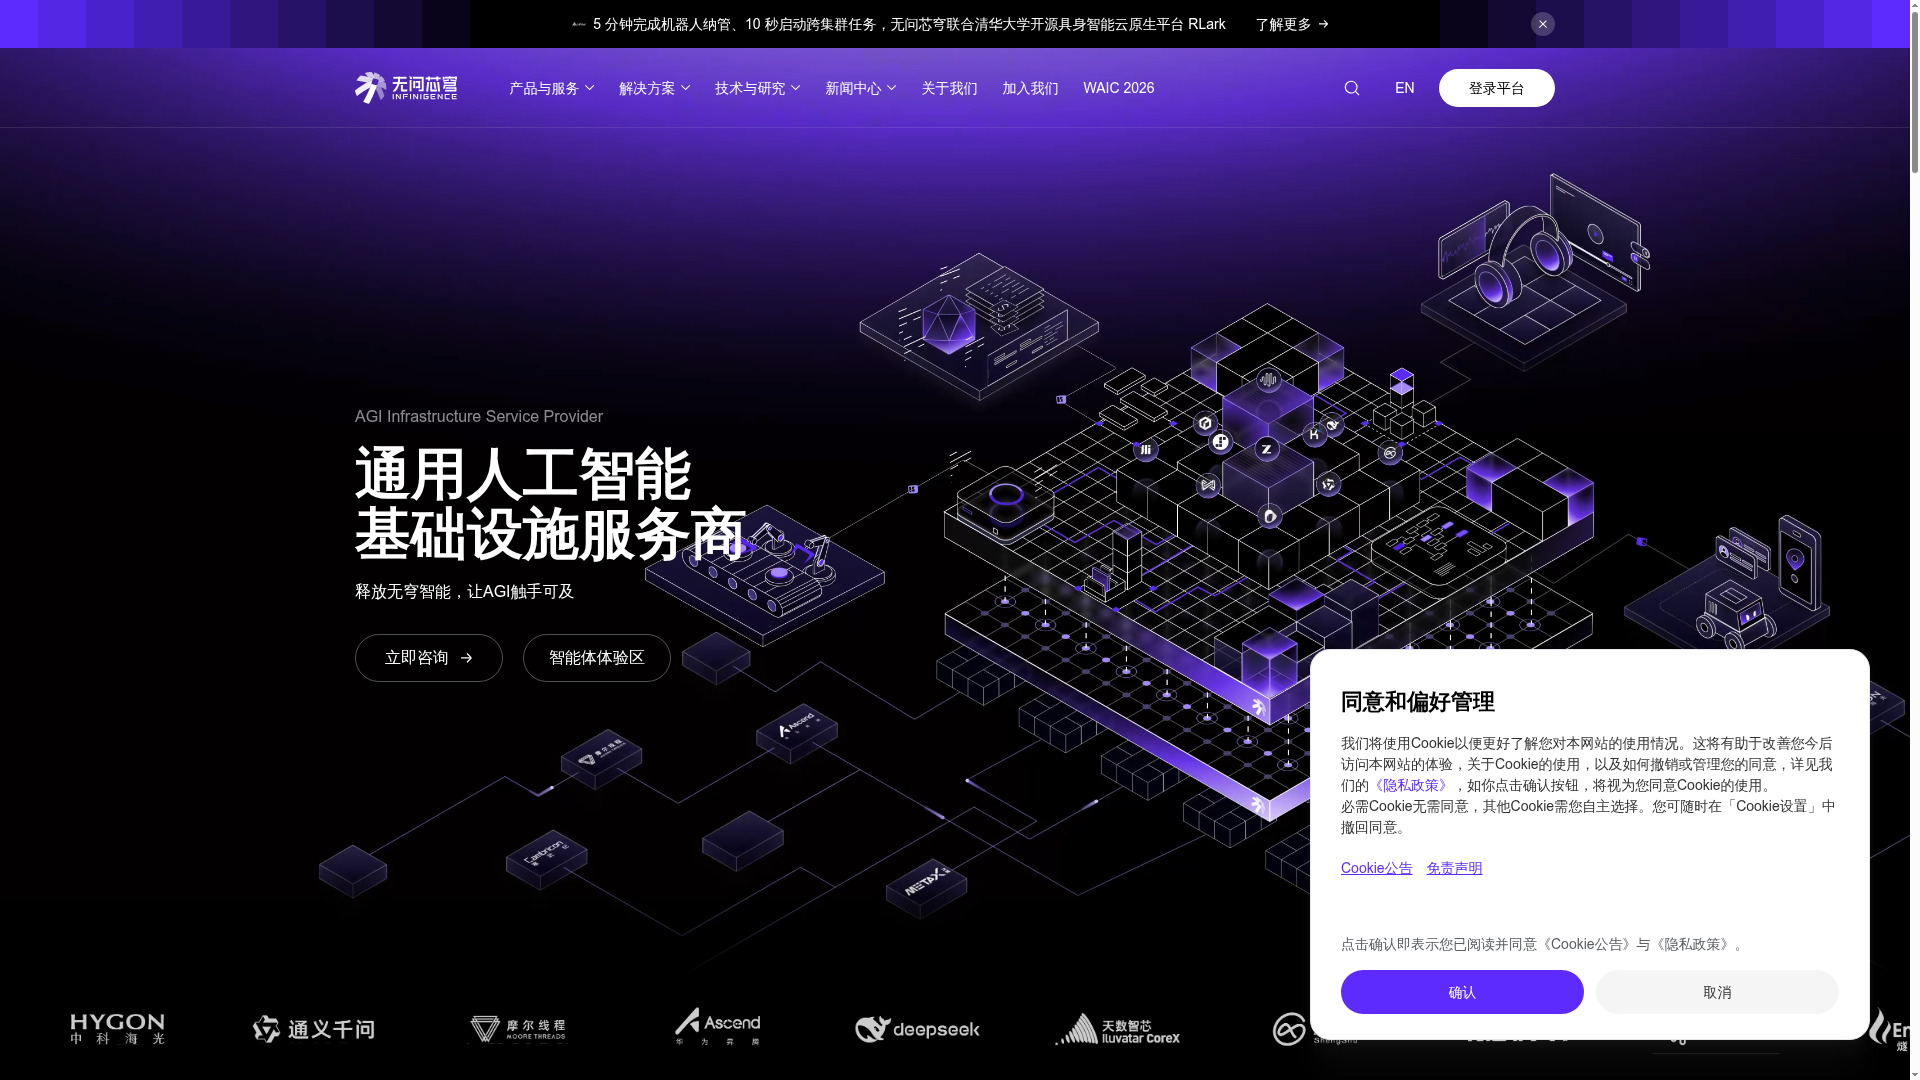
M×N Intermediate Layer Positioning
Built around an intermediate layer between “M models” and “N chips,” aiming to reduce adaptation complexity in multi-model, multi-chip environments.
Optimisation du calcul et infrastructure IA pour déployer des modèles sur plusieurs puces
无问芯穹(Infinigence AI,简称“无穹”)is an AI computing optimization and compute solution for LLM deployment. The site positions it as an “M×N” intermediate-layer product connecting “M models” and “N chips,” intended to support the efficient, unified deployment of multiple LLM algorithms across diverse chips.
From the public pages, its focus is not a single-model tool, but an intermediate-layer capability for model deployment and compute adaptation, helping upstream and downstream teams collaborate more smoothly and supporting LLM infrastructure in the AGI era.
Built around an intermediate layer between “M models” and “N chips,” aiming to reduce adaptation complexity in multi-model, multi-chip environments.
Supports efficient, unified deployment of multiple LLM algorithms across diverse chips, emphasizing a consistent cross-chip delivery approach.
Combines AI computing optimization with compute solutions to address computational efficiency and resource orchestration in LLM deployment.
Connects upstream and downstream workflows to help build LLM infrastructure and make the handoff between model deployment and compute supply smoother.
Clearly targeted at infrastructure development for the AGI era, suitable for teams that need to bring model capabilities into business scenarios.
Suitable for teams that need to deploy multiple LLMs across different chip environments, reducing repeated adaptation work through a unified approach.
Suitable for teams focused on inference or training deployment efficiency, seeking better coordination between compute resources and model deployment.
Suitable for organizations that want to manage models, chips, and infrastructure within one system to support a more stable delivery process.
Suitable for teams building AGI-related foundational capabilities, serving as an intermediate layer connecting upstream models and downstream compute resources.
无问芯穹(Infinigence AI, abbreviated as “无穹”)is an AI computing optimization and compute solution for LLM deployment, designed to enable unified deployment across multiple models and chips.
Based on the site information, it mainly helps teams that need to deploy LLM algorithms in multi-chip environments, reducing the integration cost of different model and chip combinations.
The site description emphasizes the “M×N” intermediate-layer capability between “M models” and “N chips,” so its core function is to deploy multiple LLM algorithms efficiently and uniformly across diverse chips.
A pricing page is available, but the currently visible information does not show specific prices, plan limits, or trial rules, so the pricing details cannot be confirmed.
Les données de trafic sont fournies à titre indicatif uniquement.
fluidstack.io
Fluidstack construit et exploite une infrastructure d’IA à grande échelle pour fournir plus vite des capacités de calcul.

crusoe.ai
Crusoe fournit une infrastructure cloud IA, de l’inférence gérée et une capacité de data center pour entraîner et servir des charges IA à grande échelle.

decart.ai
Decart AI Lab développe des modèles du monde en temps réel et une infrastructure pour Physical AI, dont Oasis 3 et DOS.

theaiplatform.app
The AI Platform est une superapp d’IA indépendante des fournisseurs, conçue pour les équipes qui travaillent avec des flux impliquant plusieurs agents et plusieurs personnes. Elle réunit des agents spécialisés, le routage des modèles, des espaces de travail partagés et la création de mini-applications pour les personnes et les organisations qui utilisent l’IA au quotidien.
prava.space
Infrastructure de paiement pour agents IA avec achats approuvés par l’utilisateur via API et portefeuille.
actx0.com
Actx0 est une infrastructure de mémoire gérée pour les agents d’IA et les applications. Elle aide les équipes à stocker les souvenirs de session et les connaissances de l’espace de travail, puis à récupérer le contexte pertinent en quelques millisecondes avant la prochaine réponse du modèle.